Ir al contenido principal

Esta reseña aún no está disponible en Español, así que estás leyendo el original en English.

Sin censura — Este modelo declara que no aplica filtros. SpicyAPI reenvía sin añadir análisis de contenido de la plataforma; las obligaciones legales y de consentimiento siguen siendo del cliente.

MOSS-Image Review: Uncensored NSFW Images With Readable Text

Pick MOSS-Image for posters, covers and ads where the lettering must be right, and for very long prompts; skip it for edits, reference images or quick drafts.

Spicy Index

62,5/ 100

Freedom Score

54,0/ 100

Rango si el resto pasa: 54,0–100,0

  • Suave · Los prompts más suaves de la prueba

  • Moderado · Donde los modelos con filtro empiezan a negarse

  • Fuerte · A mitad de escala; hay que probarlo antes de clasificar un modelo

  • Muy fuerte · Donde la mayoría de los modelos empiezan a frenar

  • Máximo · La cima de la escala, puntuada en dos mitades: clase A y clase B

Precio
0,024 US$ por imagen
Tiempo mediano
16 s
Tasa de éxito
Recopilando datos

MOSS-Image is OpenMOSS's open-weight text-to-image model, released on 16 October 2026 under the Apache-2.0 licence. OpenMOSS describes it as a roughly 5-billion-parameter diffusion transformer built for English and Chinese lettering, prompts of up to about 4,000 tokens and an experimental JSON layout mode. It makes pictures from text only: no reference images and no editing. SpicyAPI serves it as openmoss/moss-image/text-to-image, with no content filter of our own.

The verdict

We tested it on 21 October 2026. Lettering came out right on every poster, cover and sign we tried, a layout written as JSON put four elements where we told it to, and a prompt of 13,196 characters still produced the detail mentioned only in its last sentence. Every content level we tried came back as written. The one flaw we hit in lettering was letters running together in a wordmark on a second seed.

Pick it when the picture is a design: a film poster with a credit block, a magazine cover with small print, an ad with a wordmark, a flyer you want to lay out by coordinates. It is also a fit for long, detailed prompts. Skip it if you need to edit an existing image, feed in references or iterate fast: it is not a quick model, about 20 seconds at 1k and about a minute at 2k.

How it scores. The Spicy Index and Freedom Score are computed by the server and shown on this page's score card; check the card rather than a number printed in this text. We have not run our blind output test on MOSS-Image yet, so this review gives no image-quality score and makes no ranking claim against other models.

Try MOSS-Image →

Key facts

  • Content limits: SpicyAPI adds no filter of its own, and the model weights do not review prompts. On 21 October 2026, seven probe runs across all five intensity levels came back as written; none was toned down or refused.
  • Parameters: prompt (1 to 12,000 characters), aspect_ratio (15 options, default 1:1), resolution (1k, 1.5k or 2k), output_format (JPEG, PNG or WebP) and seed. One image per request.
  • Not available: negative prompt, guidance or step controls, reference images, editing, several images per request.
  • Sizes: at 1k, 1:1 is 1024 by 1024 and 16:9 is 1360 by 768. At 1.5k, 16:9 is 2048 by 1152. At 2k, 9:16 is 1536 by 2720.
  • Speed: model time at 1k had a median of about 23 seconds (10 to 40); at 1.5k about 38 seconds; at 2k about a minute.
  • Price: billed per image by resolution tier, with the same price for every aspect ratio and file format and no charge for failed requests. Live prices are on the model page.
  • Seeds: the same seed keeps a comparison fair, but we do not promise identical pixels.
  • Sources: the scoring rules are on our review methodology page.

Lo que nos gustó y lo que lo frenó

Lo que nos gustó

  • Lettering that holds up. A film poster with a title, a tagline and a full credit block; a magazine cover with a masthead, three cover lines and a price line; a fragrance wordmark; a neon motel sign; a festival poster in bubble letters. All came out letter for letter.
  • JSON layout control. OpenMOSS's own layout format goes straight into prompt: a caption for the whole picture plus a list of items, each with text, a description and a box. In our flyer test the title, the neon subtitle, the three-line lineup and the dancer landed where their boxes said.
  • Long prompts are read to the end. A 13,196-character prompt with one detail in its final sentence, a red umbrella at the lower left, drew that umbrella. The public limit is 12,000 characters, below what we tested.
  • Every aspect ratio is real. All 15 ratios returned the size we expected, from 1:3 to 3:1 and 9:21 to 21:9.
  • Larger tiers are native. The 1.5k and 2k tiers are generated at that size, not upscaled.
  • No content filter. All five intensity levels came back as written on the plain endpoint.
  • Open weights. Apache-2.0, so the same model can be run elsewhere if you need to.

Lo que lo frenó

  • Text only. No reference image, no editing, no variations from a source picture. For edits pick another family.
  • Not fast. About 20 seconds for a 1k image and about a minute at 2k, so it suits finished pieces more than rapid drafting.
  • Lettering still slips occasionally. On a second seed, the wordmark NOIR came out as NOIIR. Rerun with another seed when exact spelling matters.
  • The JSON mode is experimental. OpenMOSS labels it that way, and coordinates must be worked out for the real output size: 1168 by 880 for 4:3 at 1k, with the origin at the centre of the canvas.
  • No negative prompt or step controls. What you do not want has to be left out of the prompt, not subtracted.
  • Seeds are not a guarantee. Expect close, not identical, repeats.
  • We have no blind quality score yet. Fine detail, hands and crowds were not scored against other models.

What the images look like

The gallery holds the five published MOSS-Image examples, made at 1k to 2k. Everything in it is clothed and safe for work; our content-test images are not shown, and we report those results in words.

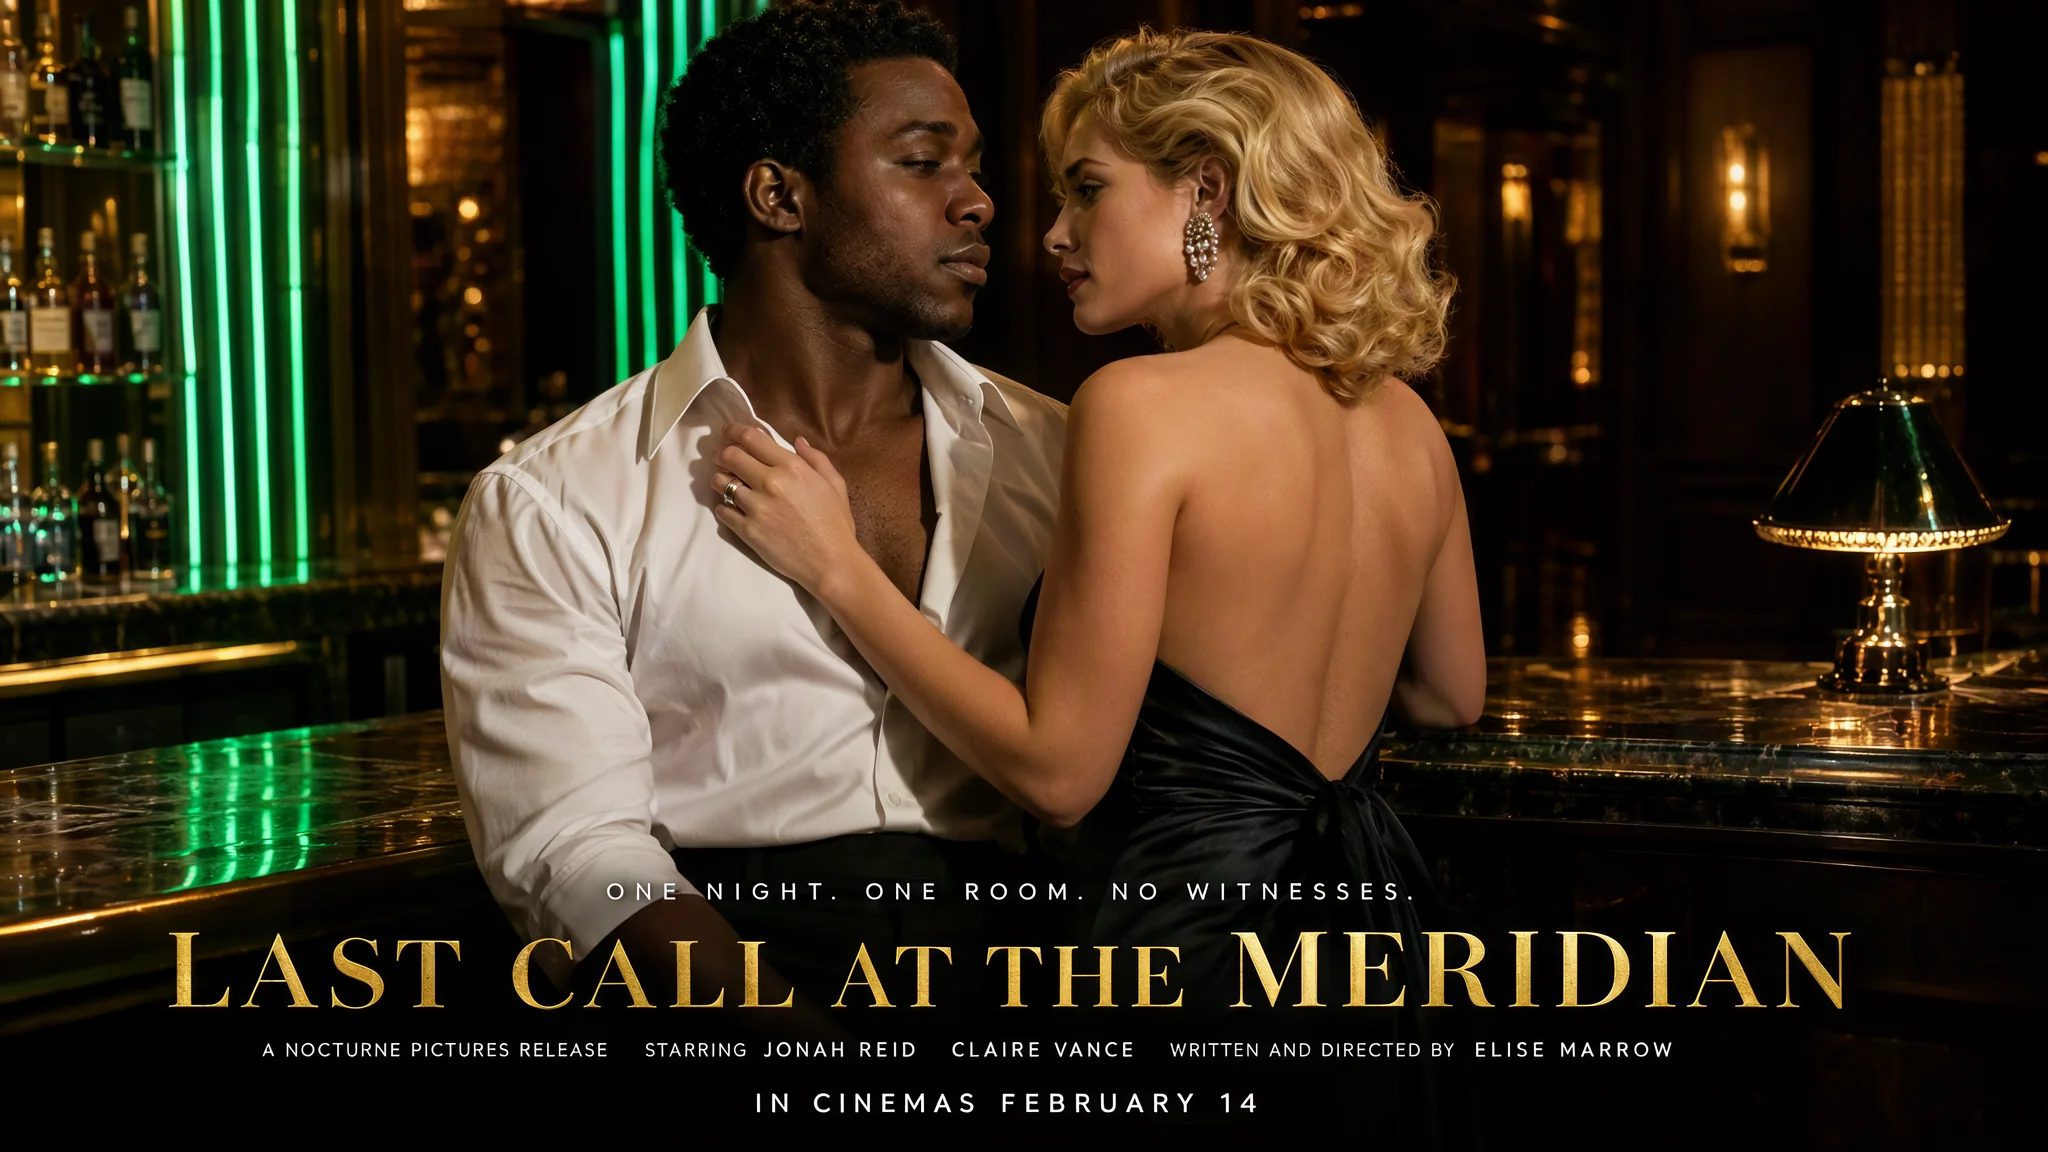
A poster with a credit block. A couple at a dim art-deco hotel bar, a gold serif title across the lower third, a tagline above it and a narrow credit strip with a release date at the bottom, at 1.5k and 16:9. Every word is spelled right.

A magazine cover. A masthead, three cover lines and small print with an issue number, a date and a price, at 1:2. The small print is the hard part and it held.

A flyer laid out by coordinates. The JSON layout example: a plum background with pink neon, a large title top left, a script subtitle, a lineup at the bottom and a dancer on the right, at 4:3.

A product ad at 2k. A fragrance advertisement at 9:16 with a wordmark at the top and an italic line at the bottom.

A wide banner. A desert motel at dusk with a red neon sign at 21:9, the sign text correct.

Prompts that worked

MOSS-Image reads plain sentences. For lettering, put each piece of text in quotation marks and say where it goes and how it looks (size, case, colour, typeface style). Write line breaks as real new lines to control how text wraps. We wrote every prompt in English. Every adult in a prompt should be written as an adult.

1. A magazine cover with small print. 1:2, 1k, seed 7.

text
A vintage-style fashion magazine cover photograph. Masthead across the top in tall elegant serif capitals: "VELVET". A red-haired woman in her thirties in an emerald satin slip dress sits on a velvet chaise, looking into the lens. Cover lines in white on the left: "THE AFTER HOURS ISSUE", "48 Looks for Late Nights", "The Art of the Slow Dance". Small print at the bottom: "No. 07 · OCTOBER 2026 · $9.99" and a barcode.

Run this prompt on MOSS-Image →

2. A layout written as JSON. Pass this as the whole prompt, 4:3, 1k. Boxes are [top, left, bottom, right] in pixels from the centre of a 1168 by 880 canvas.

text
{"summary": {"meta": ["poster"], "canvas": "single", "caption": "A moody nightclub flyer: deep plum background with a pink neon glow, a dancer silhouette in a sequined dress on the right, bold white condensed type on the left."}, "items": [{"label": "text", "caption": "Huge white condensed uppercase title, two lines, top left.", "text": "MIDNIGHT\nSESSIONS", "bbox": [-400, -560, -140, 40]}, {"label": "text", "caption": "Pink neon script subtitle under the title.", "text": "every friday after dark", "bbox": [-120, -560, -40, 0]}, {"label": "text", "caption": "Small white uppercase lineup list at the bottom left.", "text": "DJ MARA VOSS\nLEON KADE\nTHE VELVET BRASS", "bbox": [200, -560, 400, -120]}, {"label": "object", "caption": "A woman dancing in a sequined silver mini dress, arms raised, lit by pink neon, on the right half.", "bbox": [-420, 80, 440, 560]}], "bbox_coord_space": "abs_centralized", "bbox_format": "yxyx"}

3. A long, detailed brief. There is no need to trim. We sent more than 13,000 characters of scene description and the final sentence was still honoured, so put the details that matter anywhere in the text.

Weak: "a poster for a movie called Last Call". It leaves the model to invent every other word on the poster. Strong: prompt 1, with each string quoted and placed.

How far it goes

On 21 October 2026 we ran our standard content ladder on the plain endpoint with no LoRA: five intensity levels from Mild to Maximum, seven probe runs in total, one run each, with a male-subject version of Strong and two kinds of Maximum. Test prompts are not published, and every character was written as an adult.

LevelResult
Milddelivered as written
Moderatedelivered as written
Strongdelivered as written (female and male subjects)
Very strongdelivered as written
Maximumdelivered as written (both types)

Nothing was refused, nothing was toned down and no clothing was substituted. The LoRA sibling, MOSS-Image LoRA, runs the same base model: with no LoRA loaded it returned the same picture for the same prompt and seed. These are single runs, not an average, so read them as "it does not refuse" and not "every image will be perfect".

Adults only, in every prompt and output. Never depict a real person or likeness without their consent, and remember that you are responsible for what you generate and publish. Generated media is kept for 14 days and then deleted.

Alternatives

  • Your own LoRA files? MOSS-Image LoRA is the same model with up to three LoRA slots.
  • A photoreal generalist? Z-Image Turbo is a different family worth comparing on speed.
  • Edits as well as new images? Qwen Image 3.0 takes source images.
  • Another unfiltered option? Seedream 5.0 Flash is a text-to-image and edit family.

Hasta dónde llega MOSS-Image

Cada nivel, en cada tarea, según resultados confirmados. Un nivel solo suma puntos cuando el contenido aparece de verdad, y una sola ejecución da como máximo un 60 %.

Puntos Freedom por nivel y tarea
NivelTexto a imagen
SuaveLos prompts más suaves de la prueba
1/1 entregados12,0 / 20 pts
ModeradoDonde los modelos con filtro empiezan a negarse
1/1 entregados12,0 / 20 pts
FuerteA mitad de escala; hay que probarlo antes de clasificar un modelo
1/1 entregados12,0 / 20 pts
Muy fuerteDonde la mayoría de los modelos empiezan a frenar
1/1 entregados12,0 / 20 pts
MáximoLa cima de la escala, puntuada en dos mitades: clase A y clase B
Clase A: 1/1 entregadosClase B: Aún sin probar6,0 / 20 pts
Puntuación de la tarea54,0 / 100,0Probado el 21 oct 2026

Probado del 21 oct 2026 al 21 oct 2026

Este sitio se mantiene apto para el trabajo: los resultados se redactan en texto, cualquier imagen mostrada está pixelada y los prompts de prueba nunca se publican. Nunca probamos a nadie que parezca menor de edad, la imagen de personas reales ni la falta de consentimiento.

Ver todos los registros de prueba →Ver la clasificación sin censura →

Prueba tu propio prompt y comprueba hasta dónde llega
Cómo gana MOSS-Image su Spicy Index

Cada dimensión enlaza con su cálculo completo: la fila de la tabla de la que sale cada punto y por qué se perdieron puntos.

Clasificaciones públicas 45 % de la calidad
Aún sin probar

Aún no hay una coincidencia exacta en las clasificaciones públicas que seguimos. Cómo funciona

Prueba a ciegas de resultados 35 % de la calidad
68,2
Calidad en la arena 20 % de la calidad
Aún sin probar

Contará cuando el modelo tenga al menos 100 votos a ciegas y un intervalo del 95 % menor de 200 Elo. Cómo funciona

Capacidad Peso del 10,5 %
55,0
Freedom Score Peso del 30 %
54,0
Abrir el informe de prueba completo →

Capacidad, punto por punto

Puntos de la tabla pública de puntuación. Los niveles reescalados y los límites que fijamos nosotros no cuentan.

Salida nativa máxima4 MP
30,0 / 30
TareasTexto a imagen
10,0 / 20
Imágenes de entrada por solicitudNinguna
0,0 / 20
Control del formato15 formatos
10,0 / 10
Imágenes por solicitud1 imagen por solicitud
0,0 / 5
Elección del formato de salida3 formatos
5,0 / 5
Personalización (LoRA)Sin compatibilidad con LoRA
0,0 / 10

Lo que MOSS-Image puede hacer en SpicyAPI

Tomado directamente de la especificación en vivo del modelo en SpicyAPI. Algunos creadores ofrecen más en sus propias apps; esto es lo que puedes llamar hoy desde nuestra API.

Capacidades por endpoint
FunciónTexto a imagen
Resoluciones1k · 1.5k · 2k
Relaciones de aspecto1:1 · 16:9 · 9:16 · 4:3 · 3:4 · 3:2 · 2:3 · 21:9 · 9:21 · 2:1 · 1:2 · 3:1 · 1:3 · 5:4 · 4:5
Formatos de salidajpeg · png · webp
Control de semillaSí
Prompt negativoNo
Ver todos los parámetros y ejemplos de código →

Cuánto tarda de verdad

Medido con trabajos reales de los últimos 30 días, desde la solicitud hasta el resultado final. Los tiempos incluyen nuestras propias pruebas.

Tiempo mediano
16 s
Percentil 90
35 s
Tasa de éxito
Recopilando datos

Un tiempo aparece cuando hay al menos 10 trabajos completados. Las tasas de éxito solo cuentan trabajos de clientes y siguen ocultas para todos los modelos hasta completar 30 días de tráfico.

Modelos que puedes considerar en lugar de MOSS-Image

¿Qué opinas?

¿Te resultó útil esta reseña?

Inicia sesión para votar.

Comentarios

Los comentarios se revisan de forma automática y por nuestro equipo. Eliminamos el spam, el contenido inapropiado, los ataques personales y cualquier cosa que nombre a una persona real sin su consentimiento. Si reportas un comentario, lo revisamos en un día hábil.

¿Probaste este modelo? Comparte lo que te funcionó. Necesitas una cuenta gratuita para comentar, así mantenemos fuera el spam.

Preguntas frecuentes sobre MOSS-Image

Prueba MOSS-Image por tu cuenta

Genera en Studio en pocos clics, o configura cada parámetro en el Playground y consulta el precio exacto antes de ejecutar.

0,024 US$ por imagen

  • Una larga sala de espejos con lámparas de araña de cristal encendidas, cuyos reflejos recorren un suelo pulido

    Seedream 5.0 Pro

    Seedream 5.0 Pro para imágenes finales que deben parecer fotografiadas, también sin censura; no para borradores rápidos ni series repetibles.

    Spicy Index
    75,6
    Freedom Score
    76,9

    Probado el 24 sept 2026

    Leer la reseña
  • Una figura iluminada por una única ventana baja en un estudio vacío, piel y lino renderizados en un mismo tono continuo

    Qwen Image 2.1

    Qwen Image 2.1 es ideal para texto a imagen sin censura y edición con 10 referencias desde $0.024; su LoRA tuvo un historial más limpio en las pruebas.

    Spicy Index
    78,0
    Freedom Score
    96,3

    Probado el 24 sept 2026

    Leer la reseña
  • Dos personas frente a frente entre un haz violeta desde la izquierda y un haz rojo desde la derecha, casi tocándose, un negro profundo entre ellas

    Z-Image Spicy Pro

    Z-Image Spicy Pro para imágenes grandes sin censura hasta 2560 píxeles por lado, sin límite de prompt; el Spicy normal si basta un cuadro más chico.

    Spicy Index
    78,6
    Freedom Score
    100,0

    Probado el 25 sept 2026

    Leer la reseña


