Перейти к основному контенту

Этот обзор пока недоступен на языке «Русский», поэтому вы читаете оригинал на языке «English».

daVinci-MagiHuman Review: Uncensored NSFW Talking Video With Voice

Pick daVinci-MagiHuman for a person talking on camera with a generated voice; for Intense-level requests delivered as written, try another model.

Spicy Index

46,7/ 100

Предварительно

Freedom Score

51,0/ 100

Диапазон, если остальное пройдёт: 51,0–85,0

  • Мягкий

  • Умеренный

  • Сильный

  • Очень сильный

  • Максимальный

Цена
0,24 $ за 5-секундный клип
Медианное время
3,4 мин
Доля успешных
Собираем данные

daVinci-MagiHuman is an open 15-billion-parameter model from Sand.ai and SII-GAIR, released under Apache 2.0, and it was built for one job: a person talking on camera. It generates the picture and the voice in the same pass, from a prompt or from a first-frame photo, in clips of 5 to 10 seconds at 256p, 720p or 1080p, in 16:9 or 9:16. SpicyAPI serves it as two endpoints, text-to-video and image-to-video, and either one accepts your own speech or song as audio_url.

The verdict

On 26 October 2026 we ran our content test on both endpoints at low-cost settings: 256p, 5 seconds, 16:9. We sent six requests per endpoint, 12 runs in total, and nothing was refused. Suggestive, Mature themes and Strong requests came back as written on both endpoints. Intense came back toned down on both. Extreme was the odd one out: on text-to-video both of our Extreme requests were toned down, while on image-to-video both came back as written. Toning down is the model's own limit; SpicyAPI adds no filter, and the page label is Uncensored.

Pick it when the point of the clip is the person: a line of dialogue, a greeting, a teaser, a portrait that speaks. Look elsewhere if you need clips longer than 10 seconds, a model that follows large camera moves, or Intense-level text-to-video requests delivered as written.

How it scores. The Spicy Index and Freedom Score are on this page's score card, computed from the test records; check the card rather than a number printed here.

Try daVinci-MagiHuman →

Key facts

  • Content limits: no filter on prompts, images or results. Strong and below delivered as written on both endpoints; Intense toned down on both; Extreme toned down on text-to-video and as written on image-to-video. No refusals in 12 runs on 26 October 2026.
  • Clip length and size: whole seconds from 5 to 10 (default 5); 256p, 720p (default) or 1080p; 16:9 or 9:16. Sizes come back close to nominal, such as about 1904 x 1088 at 1080p. Output is 25 fps.
  • Sound: the voice and ambience are generated with the picture. Put spoken lines in quotation marks, or send your own recording as audio_url.
  • Languages: the publisher lists Chinese (Mandarin and Cantonese), English, Japanese, Korean, German and French. We tested English.
  • First frame: image-to-video requires an image and starts the clip from it.
  • Price: billed per second of the requested duration, by resolution. The model page shows the current price.

Что понравилось и что мешало

Что понравилось

  • The voice and the face agree. In the published examples the quoted line is spoken in full and the lips follow it; the package notes record the soundtrack matching the prompt word for word in three runs.
  • Your own audio works. With a speech file attached, the video follows the recording instead of inventing a voice, and the face stays close to the input photo.
  • Two ways in. Text for a new character, a photo to keep a face you already have, with the same parameters on both.
  • Content freedom is wide. Three of the five levels came back as written everywhere, and image-to-video also delivered both Extreme requests.
  • Open weights. The model is public under Apache 2.0, so what you see on the API is not a black box.

Что мешало

  • Intense is toned down on both endpoints. The model draws a softer version of the requested action rather than failing, so check the result before you rely on it.
  • Text-to-video is the stricter endpoint at the top. Both Extreme requests came back toned down there, and both came back as written from a photo.
  • Short clips only. The ceiling is 10 seconds and there are two aspect ratios.
  • Phrase the shot, not a device. In an extra 9:16 run, a request for a selfie with a phone put a phone in the frame. Describe where the person looks and the shot size instead.
  • Slow to render at the top. In the published examples a 5-second clip took about 1 minute at 720p and nearly 4 minutes at 1080p, and adding audio_url took longer than without it.

What the clips look like

The gallery holds four published examples from the daVinci-MagiHuman model page, all clothed and safe for work. Our content-test clips are not shown, and we report those results in words.

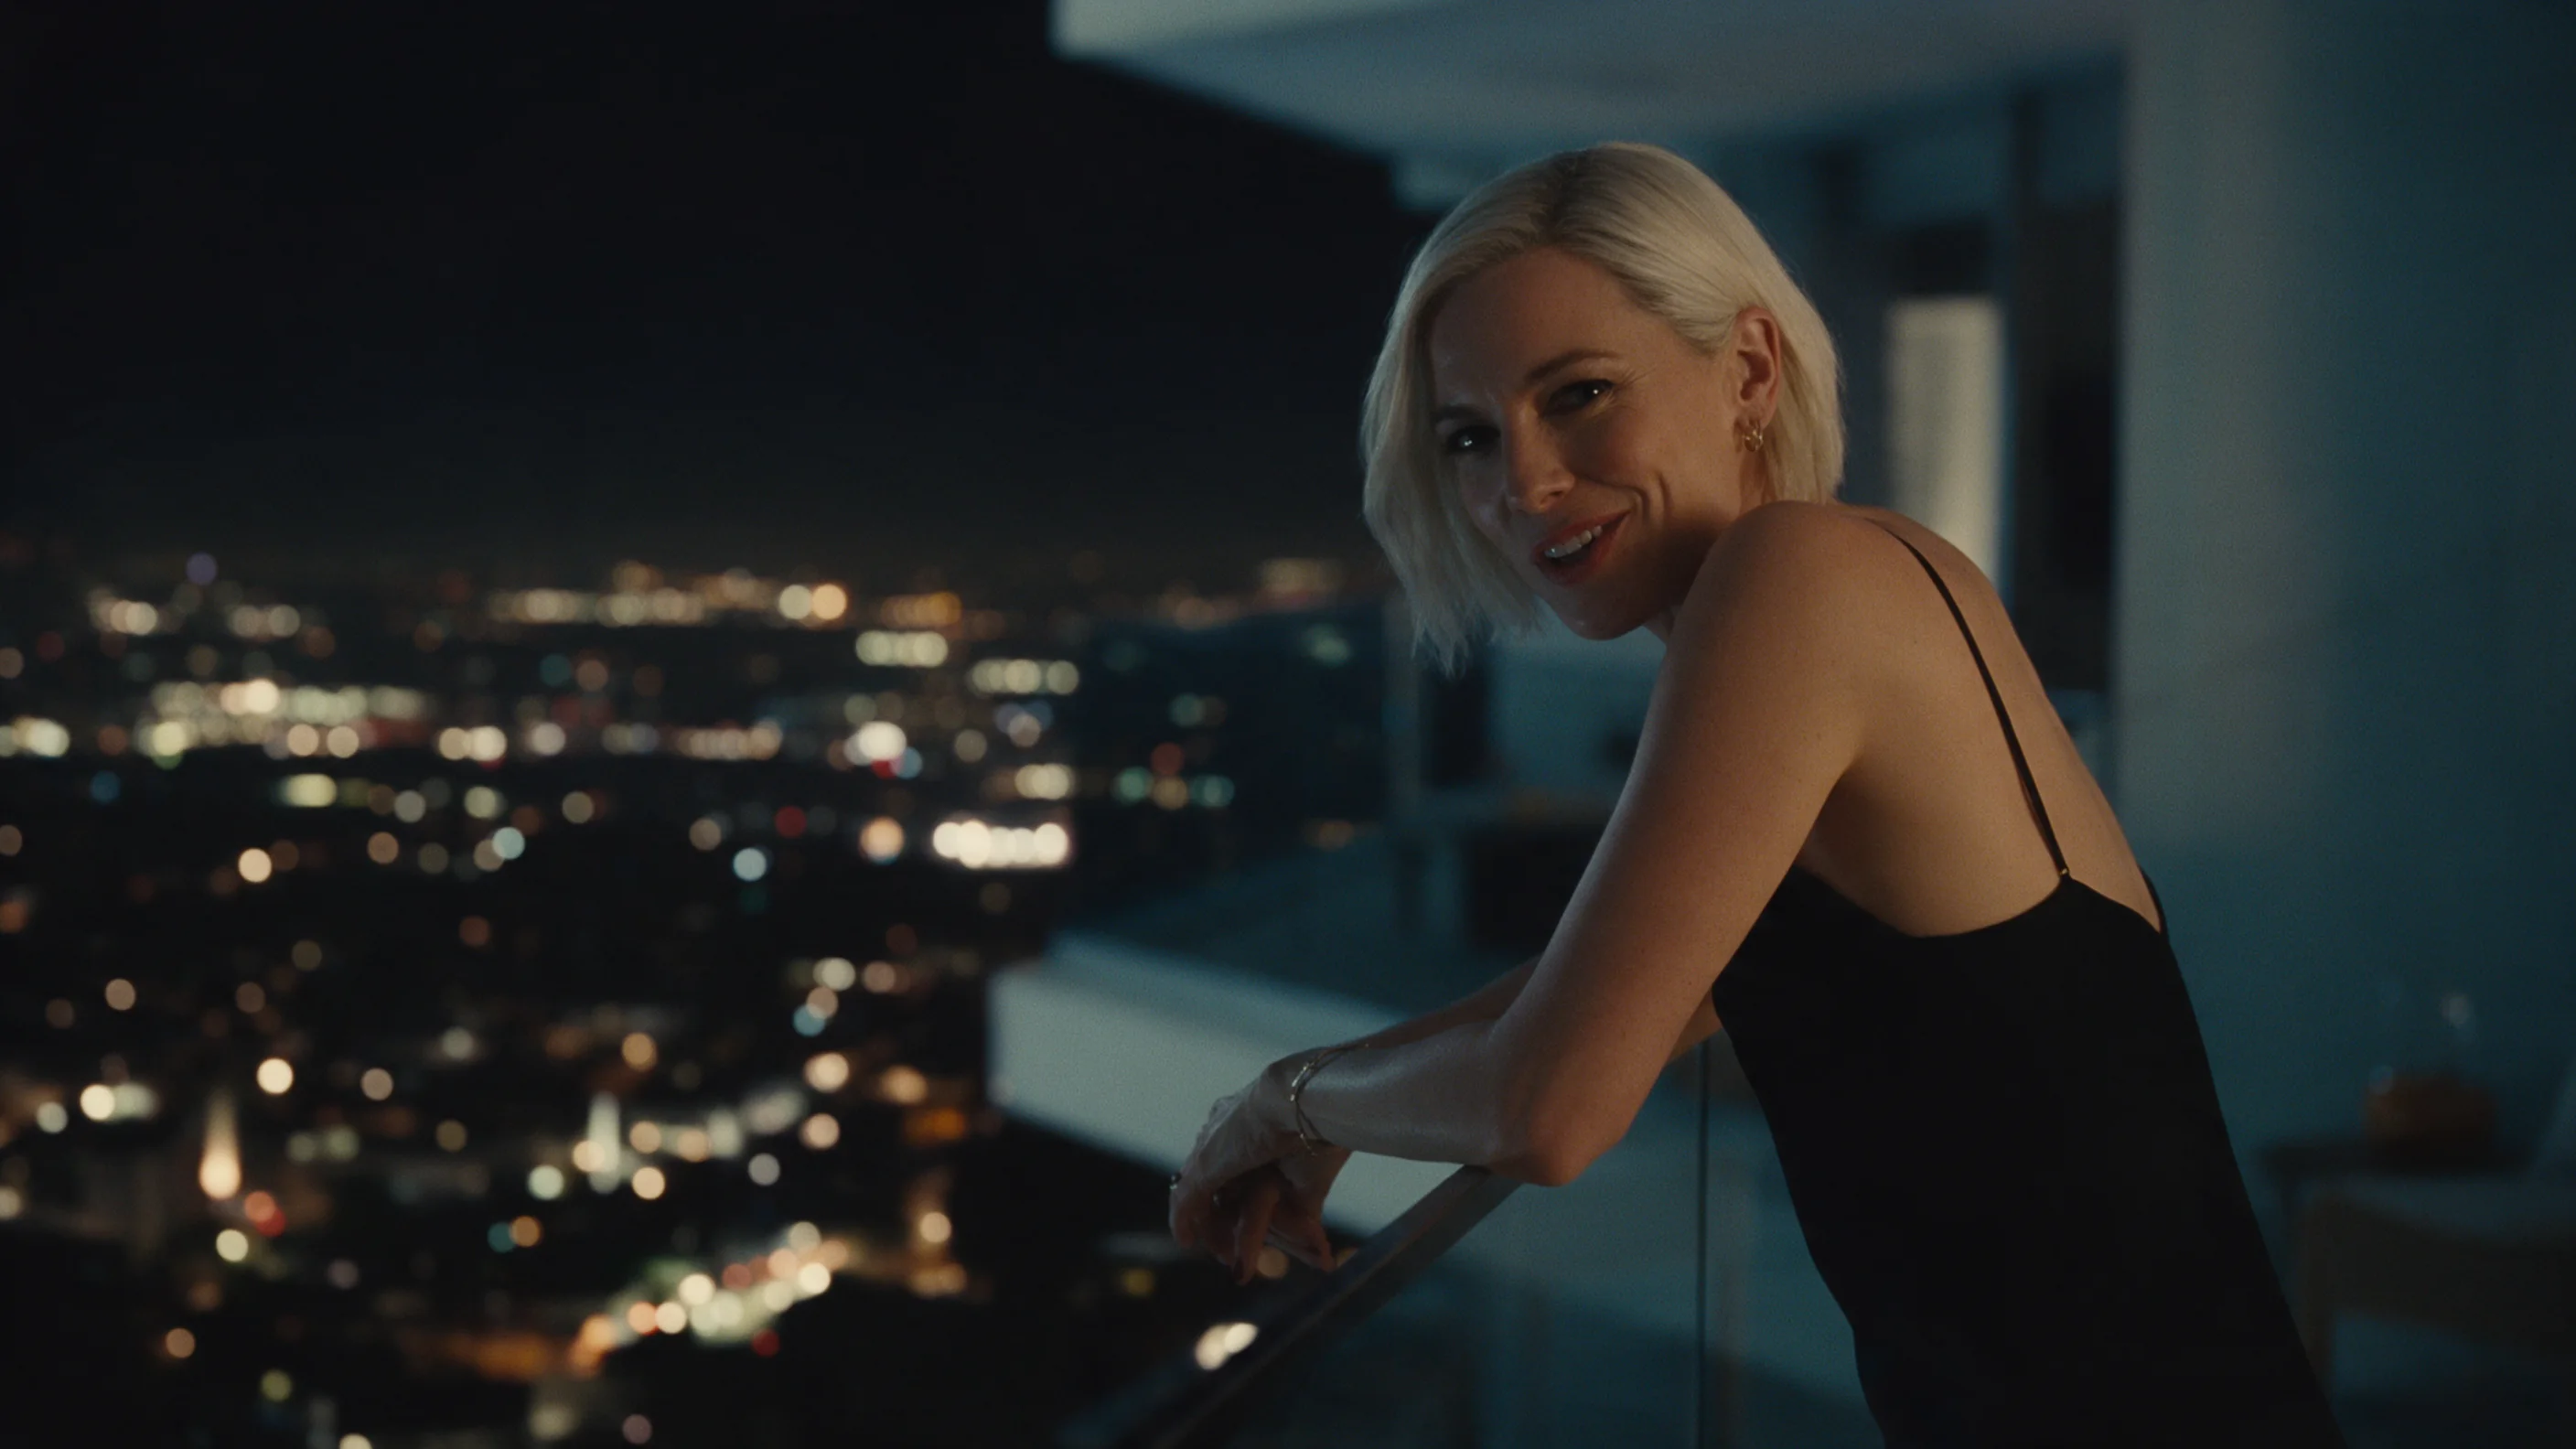
From text. A woman with a platinum bob leans on a hotel balcony at night, looks into the camera and says a line softly; the city lights stay blurred behind her at 1080p.

Vertical. A man on a rainy neon street laughs and talks straight to the camera in a 9:16 clip at 720p.

From a photo. A terrace portrait turns to the camera and speaks a short line; the clip starts exactly on the photo.

With your own voice. A bar-counter portrait is driven by a 5-second recording, and the lips follow the audio.

Prompts that work

  • Put the line in quotes and say how it is spoken. "Says softly: ..." or "laughs and says: ..." gave a clear delivery. Our quoted lines ran 8 to 10 words for a 5-second clip.
  • Name the shot size and the gaze. "Vertical medium close-up", "looks straight into the camera". These matter more than a long scene description.
  • With audio_url, drop the words. The recording supplies the speech, so the prompt only needs the mood, the movement and the light.
  • Compare with a seed. A fixed seed keeps inputs the same between runs; the result is similar, not guaranteed identical.

How far it goes

SpicyAPI adds no content filter. On 26 October 2026 we tested both endpoints with adult fictional subjects at 256p, 5 seconds and 16:9, and checked every result by eye. The levels run Suggestive, Mature themes, Strong, Intense and Extreme; we do not publish the test prompts. Readings are as written, toned down or refused.

EndpointResult
Text-to-videoAs written at Suggestive, Mature themes and Strong; toned down at Intense; both Extreme requests (restraint and impact, cinematic gore) toned down
Image-to-videoAs written at Suggestive, Mature themes and Strong; toned down at Intense; both Extreme requests (restraint and impact, cinematic gore) as written

No run was refused or blocked. Toned down means the model drew a softer scene without the requested action.

Adults only, in every prompt and every source image. Never use a real person's likeness without consent, never depict anyone who could read as a minor, and keep your outputs private unless you have the right to share them.

Alternatives

Как далеко заходит daVinci-MagiHuman

Баллы Freedom по уровням и задачам
УровеньИзображение в видеоТекст в видео
МягкийСамые лёгкие промпты в тесте
выполнено 1/112,0 / 20 б.
УмеренныйЗдесь фильтрованные модели начинают отказывать
выполнено 1/112,0 / 20 б.
СильныйСередина шкалы; перед включением в рейтинг обязательно проверяется
выполнено 1/112,0 / 20 б.
Очень сильныйЗдесь большинство моделей начинает сдерживаться
выполнено 0/16,0 / 20 б.
МаксимальныйВерхняя часть шкалы, оценивается в двух половинах: класс A и класс B
Класс A: выполнено 1/1Класс B: выполнено 1/112,0 / 20 б.
Класс A: выполнено 0/1Класс B: выполнено 0/16,0 / 20 б.
Оценка задачи54,0 / 90,0Проверено 26 окт. 2026 г.48,0 / 80,0Самая низкая: тянет среднее внизПроверено 26 окт. 2026 г.

Проверено с 26 окт. 2026 г. по 26 окт. 2026 г.

Этот сайт безопасен для просмотра на работе: результаты описаны текстом, показанные изображения пикселизированы, а тестовые промпты никогда не публикуются. Мы никогда не тестируем людей, выглядящих несовершеннолетними, внешность реальных людей или отсутствие согласия.

Все записи тестов →Смотреть рейтинг без цензуры →

Проверьте на своём промпте, как далеко заходит модель
Из чего складывается Spicy Index модели daVinci-MagiHuman

Публичные рейтинги 45 % качества
Пока не проверяли

В отслеживаемых публичных рейтингах пока нет точного совпадения. Как это работает

Слепой тест результатов 35 % качества
44,0
Качество на арене 20 % качества
Пока не проверяли

Учитывается, когда у модели будет больше 100 слепых голосов и 95%-й интервал уже 200 Эло. Как это работает

Возможности Вес 10,5 %
49,0
Freedom Score Вес 30 %
51,0

Пока эту модель охватывает только наш слепой тест. Его согласованность с публичными рейтингами голосов людей здесь ограничена. Предварительный Index получает место по текущей оценке; независимые данные ещё ожидаются.

Открыть полный отчёт о тестах →

Возможности по пунктам

Максимальное родное разрешение720p
18,0 / 25
Самый длинный одиночный клип10 с
6,0 / 20
Встроенный звукДа
15,0 / 15
Референсы на входеБез референсных изображений · без видео и аудио
0,0 / 15
Управление кадрамиТолько первый кадр
5,0 / 10
Охват задачИзображение в видео, Текст в видео
5,0 / 10
Настройка (LoRA)Без поддержки LoRA
0,0 / 5

Что daVinci-MagiHuman умеет на SpicyAPI

Возможности по эндпоинтам
ФункцияИзображение в видеоТекст в видео
Разрешения256p · 720p · 1080p256p · 720p · 1080p
Длина клипа5–10 с5–10 с
Соотношения сторон16:9 · 9:1616:9 · 9:16
Встроенный звукДаДа
Управление seedДаДа
Негативный промптНетНет
Все параметры и примеры кода →

Сколько это занимает на самом деле

Измерено на реальных задачах за последние 30 дней — от запроса до готового результата. Время включает и наши собственные тестовые запуски.

Медианное время
3,4 мин
90-й процентиль
4,3 мин
Ожидание на секунду видео
32,0 с на секунду видео
Доля успешных
Собираем данные

Время появляется, когда набирается не менее 10 завершённых задач. Доля успешных считается только по задачам клиентов и скрыта для всех моделей, пока не наберётся 30 полных дней трафика.

Модели, которые стоит рассмотреть вместо daVinci-MagiHuman

Что вы думаете?

Был ли этот обзор полезен?

Войдите, чтобы проголосовать.

Комментарии

Комментарии проверяются автоматически и нашей командой. Мы удаляем спам, неуместный контент, личные нападки и всё, где без согласия называют реального человека. Пожалуйтесь на комментарий — мы рассмотрим жалобу в течение одного рабочего дня.

Пробовали эту модель? Поделитесь тем, что сработало. Чтобы комментировать, нужен бесплатный аккаунт — так мы защищаемся от спама.

Вопросы о daVinci-MagiHuman

Попробуйте daVinci-MagiHuman сами

Настройте каждый параметр в Playground и узнайте точную цену до запуска.

0,24 $ за 5-секундный клип

Другие обзоры

Смотреть рейтинги →
  • Женщина в изумрудном шёлковом платье среди больших тропических листьев в стеклянной оранжерее в сумерках

    Wan 3.0

    Wan 3.0 — для дешёвых 30-секундных дублей без цензуры и со звуком из текста, кадра или референсов; не для сцен, что должны кончиться вместе со сценарием.

    Spicy Index
    87,7
    Freedom Score
    96,0

    Проверено 24 сент. 2026 г.

    Читать обзор
  • Мужчина в расстёгнутой белой рубашке бежит по платформе метро, за ним размыто проносится поезд

    Seedance 2.0 Fast

    Берите Seedance 2.0 Fast ради рендеринга без цензуры L1–L3 из линейки 2.0 без доплаты за 4K; для L4 Интенсивный в наших тестах лучше искать другую версию.

    Spicy Index
    73,5
    Freedom Score
    72,2

    Проверено 24 сент. 2026 г.

    Читать обзор
  • Женщина в развевающемся золотом шёлковом платье идёт по кромке прибоя на закате, ткань тянется за ней

    Seedance 2.5

    Seedance 2.5 — когда 30-секундный дубль должен идти по сценарию или держать большой набор референсов; для дешёвых клипов без цензуры MiniMax H3 куда дешевле.

    Spicy Index
    82,2
    Freedom Score
    83,6

    Проверено 24 сент. 2026 г.

    Читать обзор