Text-to-image on MOSS-Image, OpenMOSS's open 5-billion-parameter model, with up to three of your own LoRAs per request. Base and SFT LoRAs load, style LoRAs work at scale 1, 15 aspect ratios, three resolution tiers, and no content filter.
Workbench
These examples were written for this endpoint. Replace the prompt and sample media URLs with your own accessible inputs, then check the current quote and model availability before submitting.
 Output
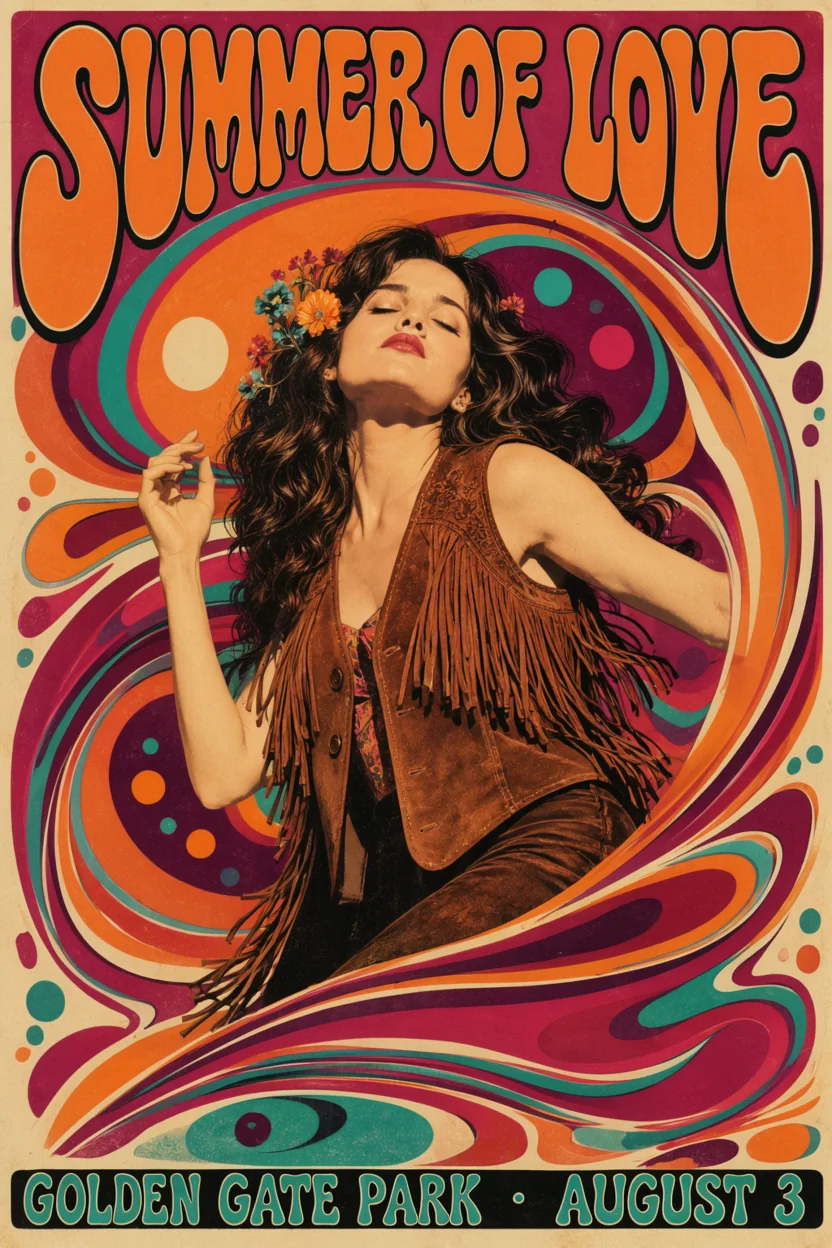
summer-of-love-poster A poster-style LoRA at 1, trigger word first. The title and the date line are still spelled correctly, and the swirling collage look comes from the LoRA.
- 7
- 1k
- 2:3
 Output
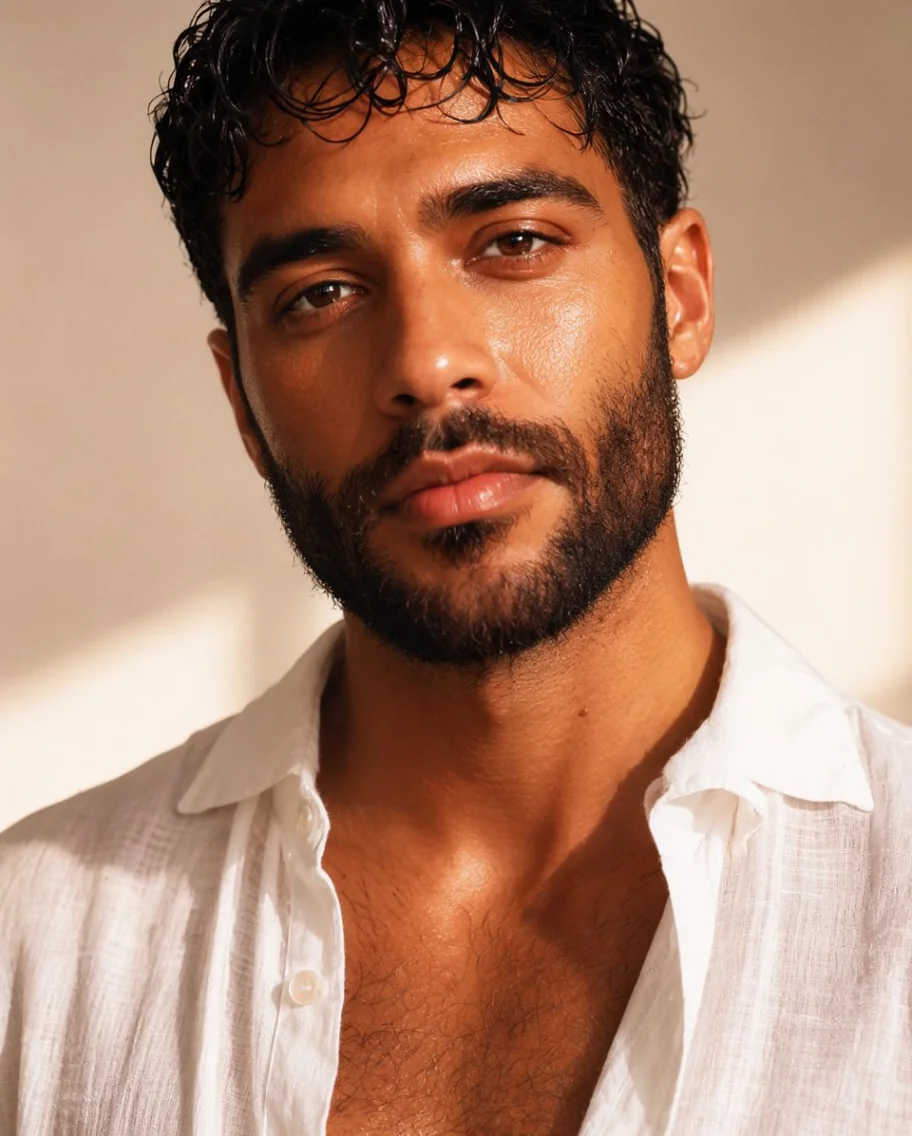
linen-shirt-portrait A portrait LoRA at 1 with its trigger word first. Window light, a calm gaze and a plain background keep the focus on the face.
- 21
- 1k
- 4:5
 Output
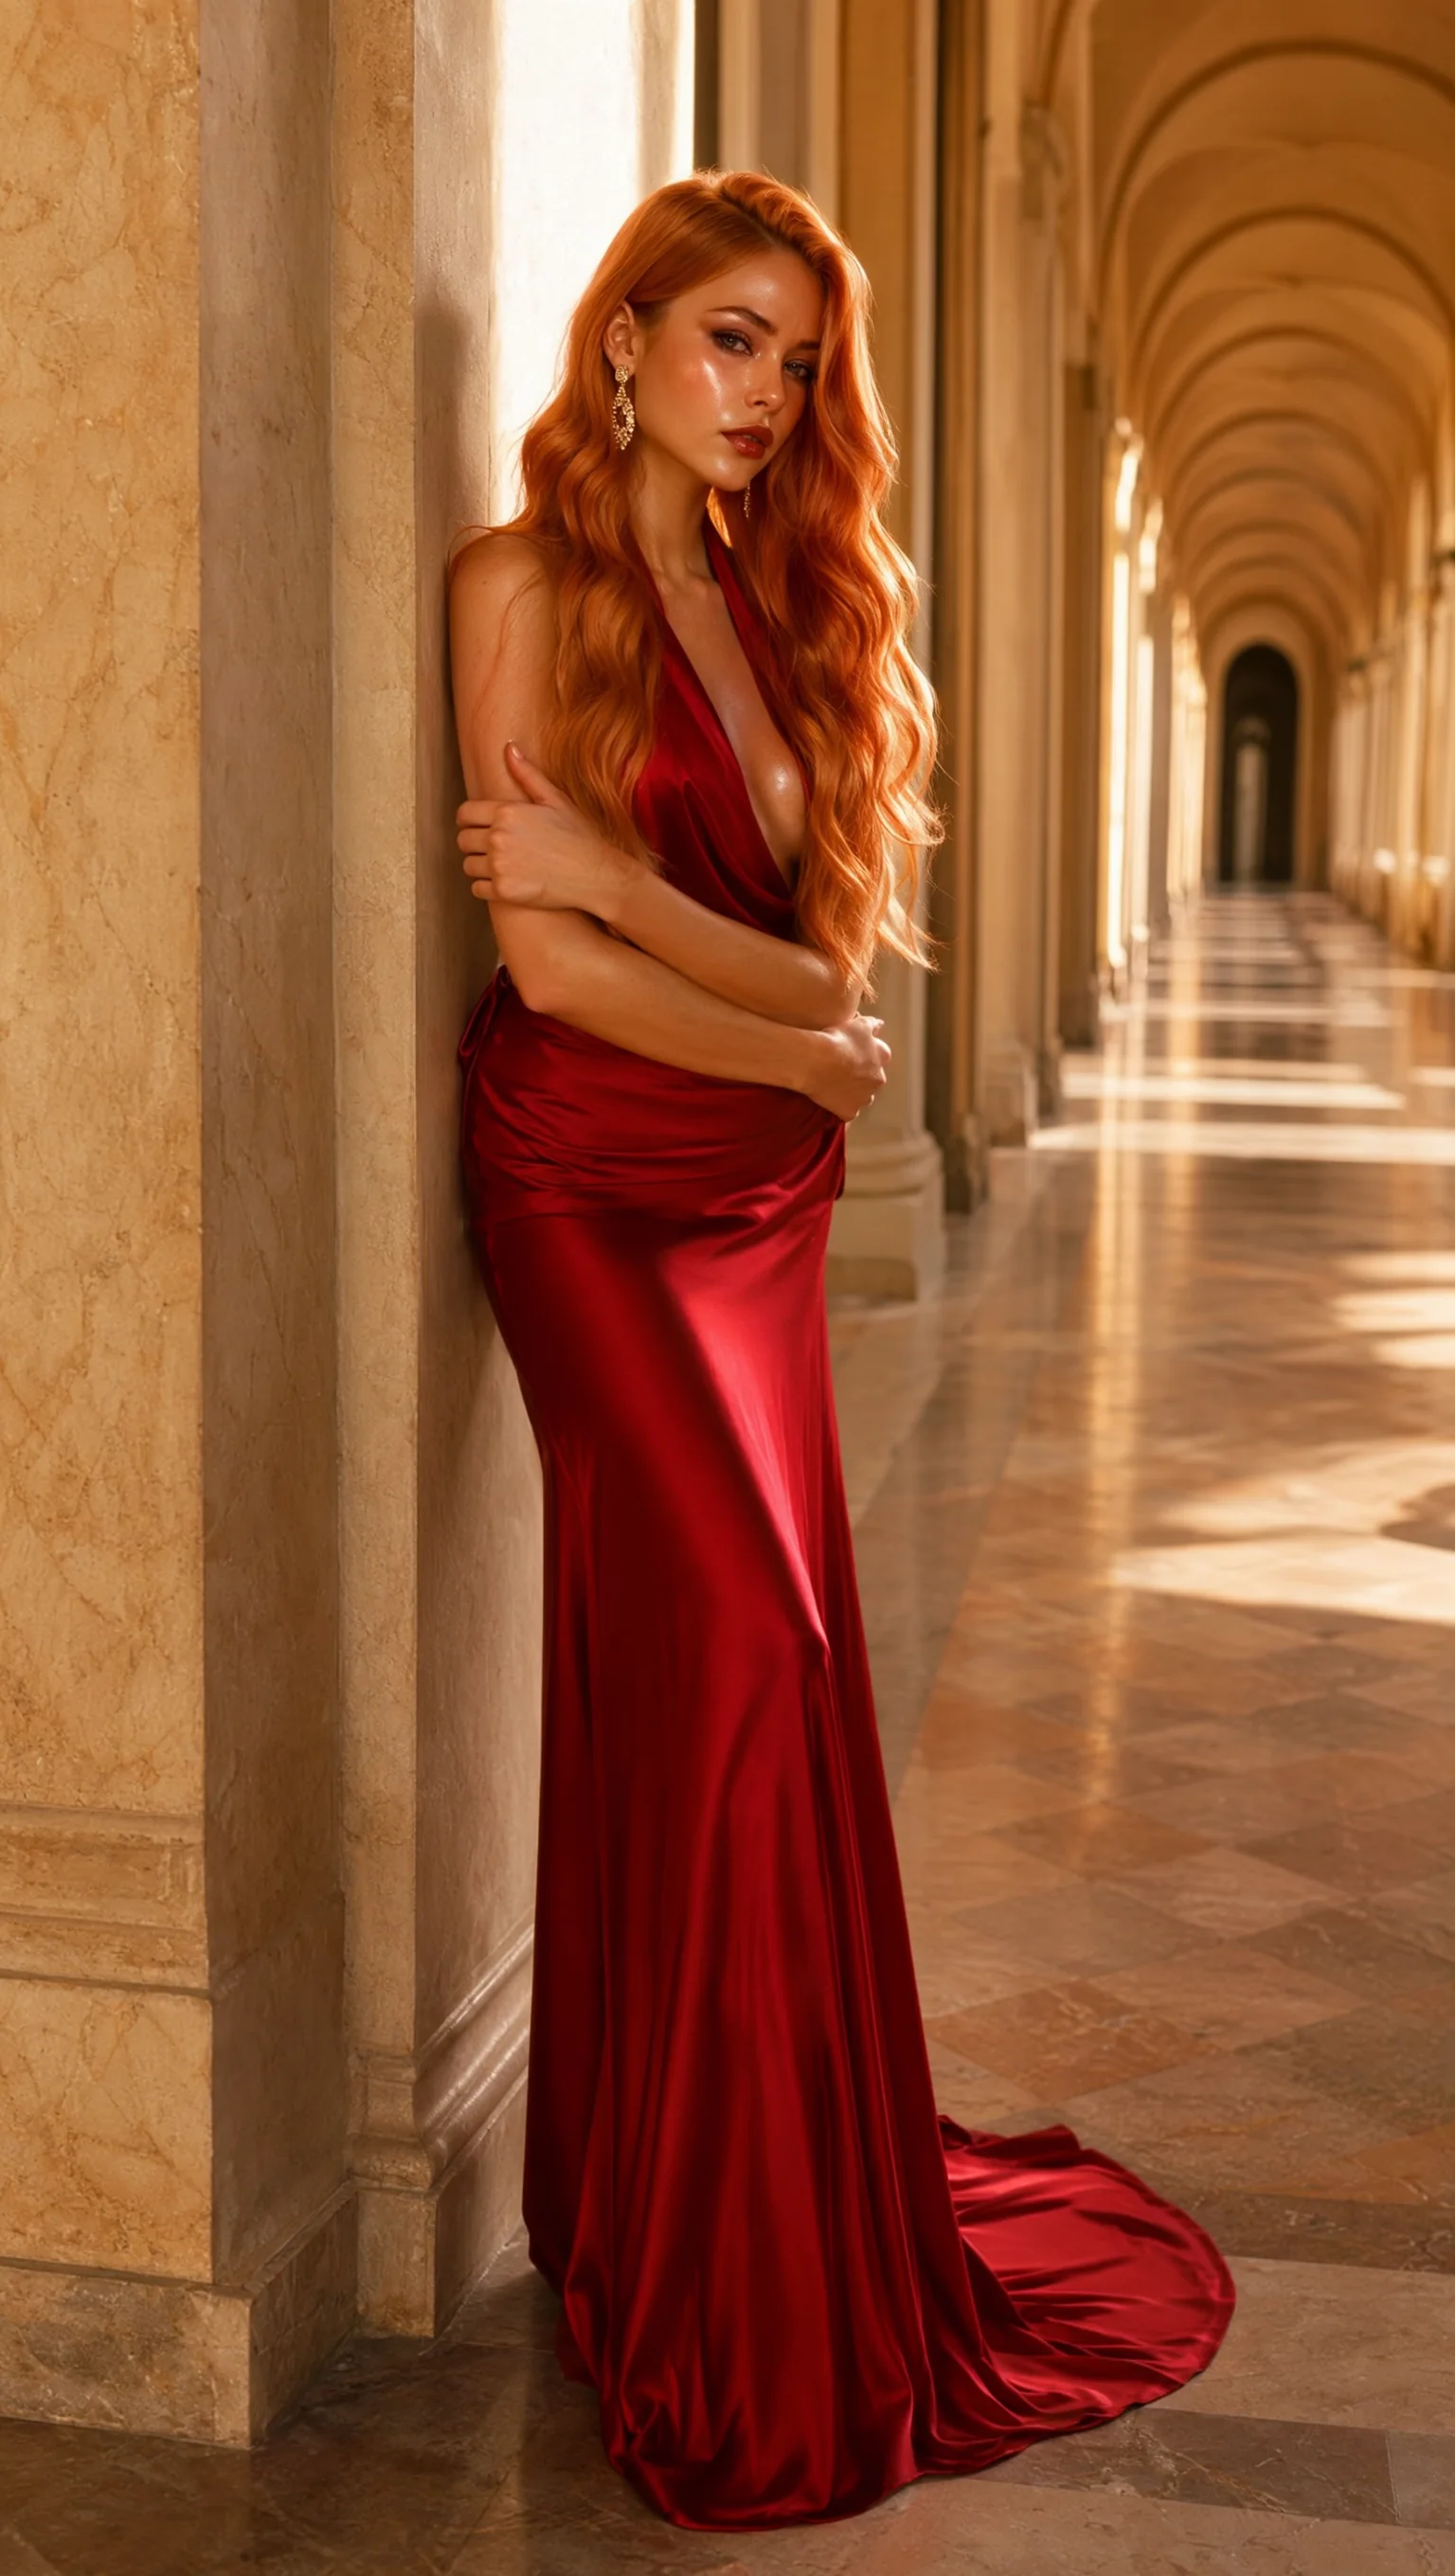
palazzo-red-satin The same portrait LoRA at 1 on the 2k tier in 9:16, which returns 1536 x 2720.
- 7
- 2k
- 9:16
 Output
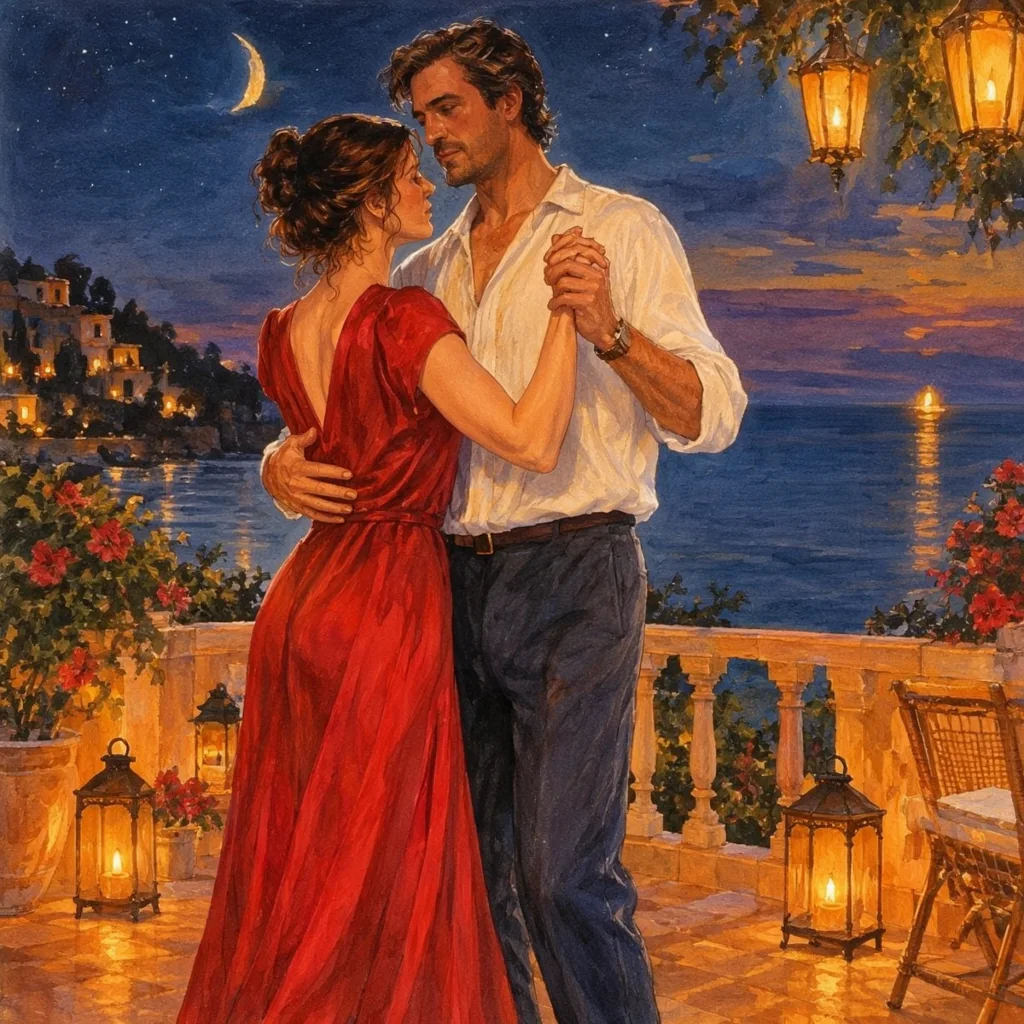
terrace-gouache-dance A gouache LoRA at 1. The file was trained on the Base checkpoint and loaded here without trouble.
- 42
- 1k
- 1:1
This example starts at $0.03 per image. The Playground updates the estimate when you change the settings.