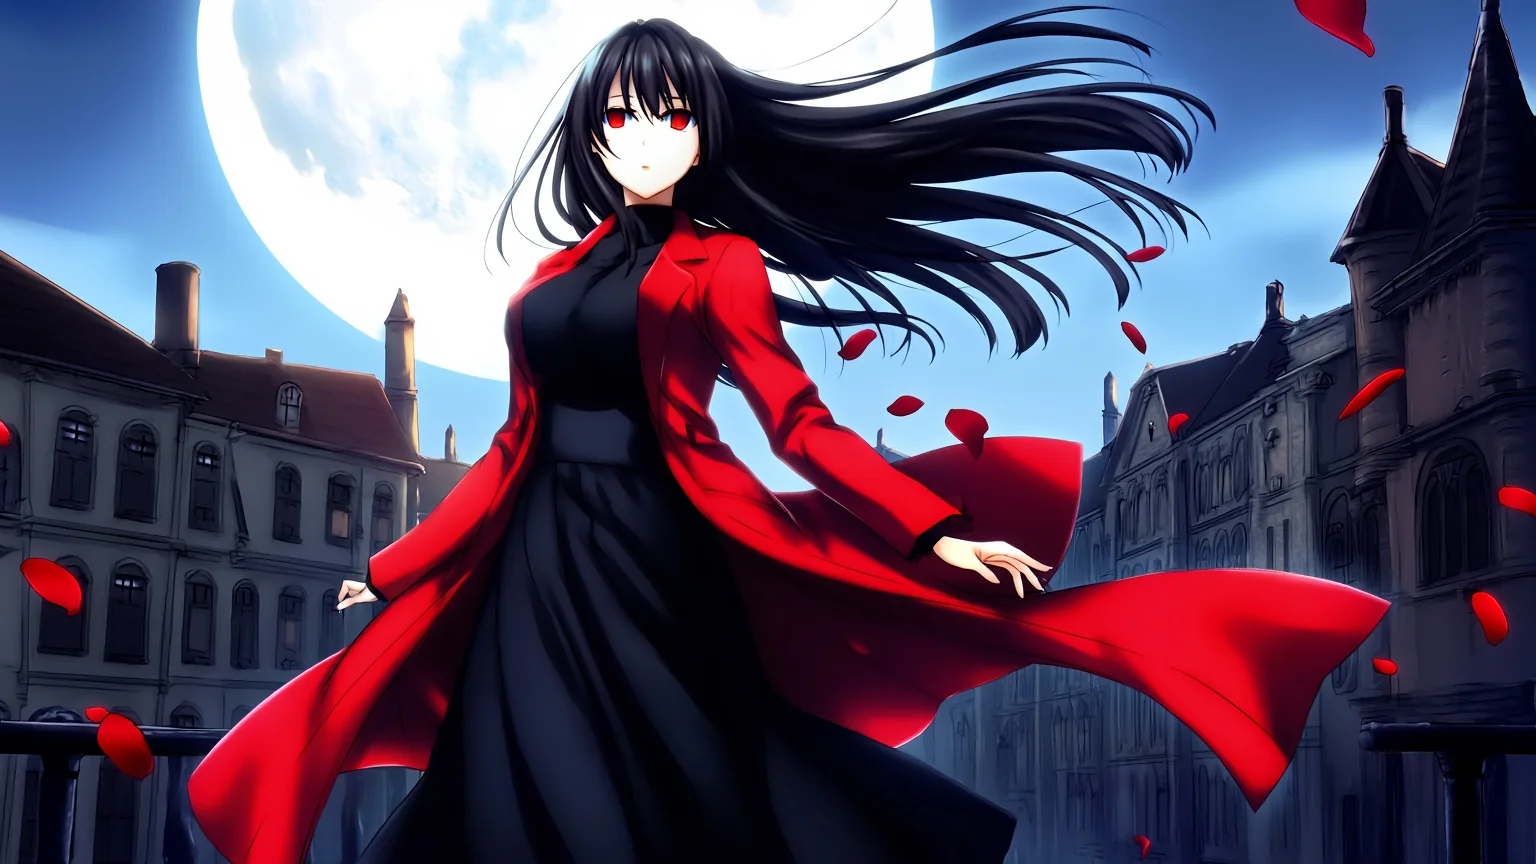
Neta Lumina text-to-image draws one anime illustration from Danbooru-style tags, plain sentences or both, on Neta.art Lab's fine-tune of Lumina-Image-2.0. Nine aspect ratios at about one megapixel, JPEG, PNG or WebP output, and no content filter.
Workbench
These examples were written for this endpoint. Replace the prompt and sample media URLs with your own accessible inputs, then check the current quote and model availability before submitting.
 Output
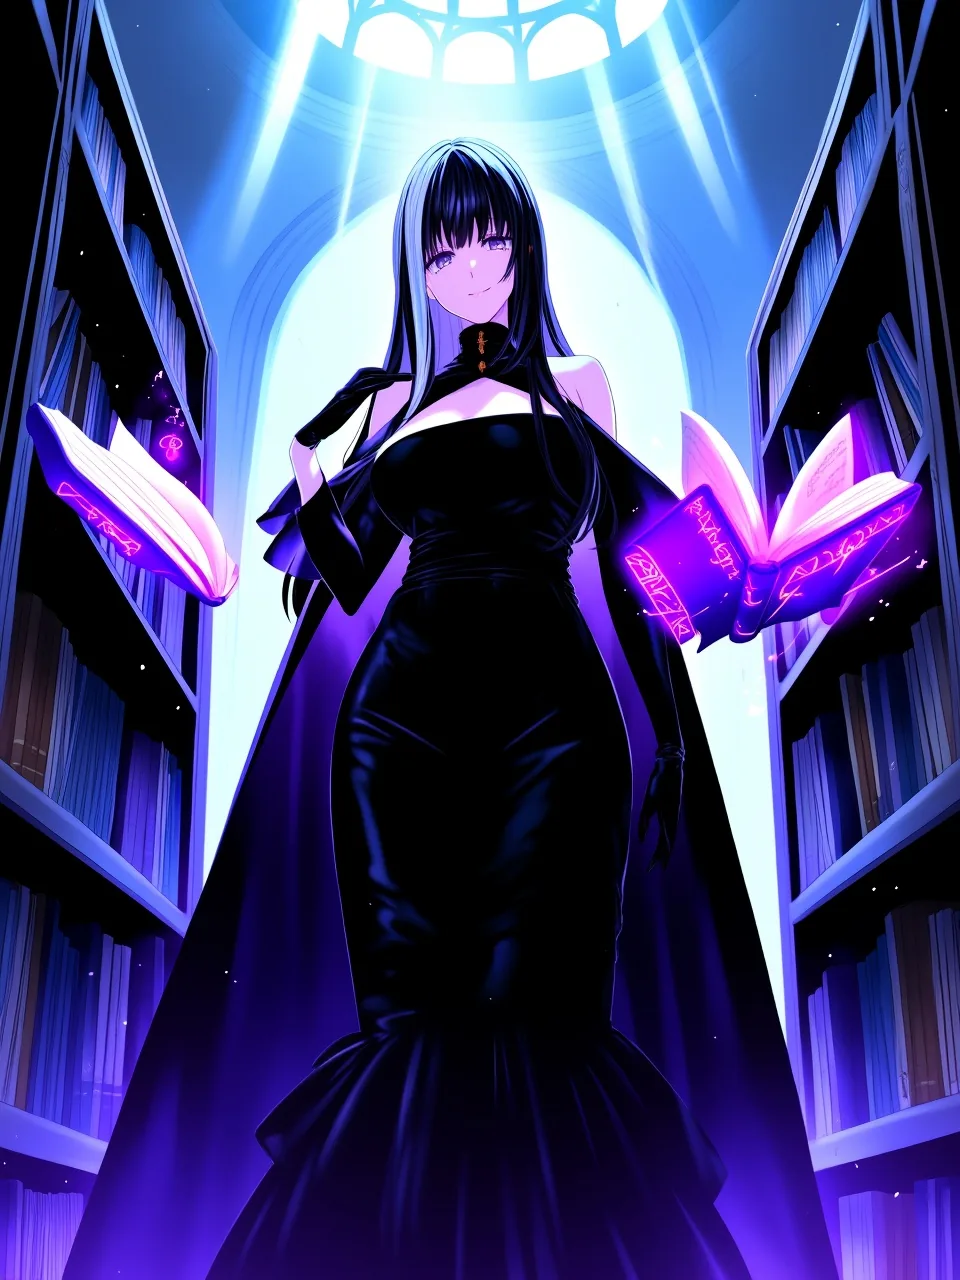
grimoire-archive Pure tags: quality tags, head count, then the character, her gown, the floating books and the light. The violet runes and the cold skylight each came from a short tag phrase.
- 203
- 3:4
 Output
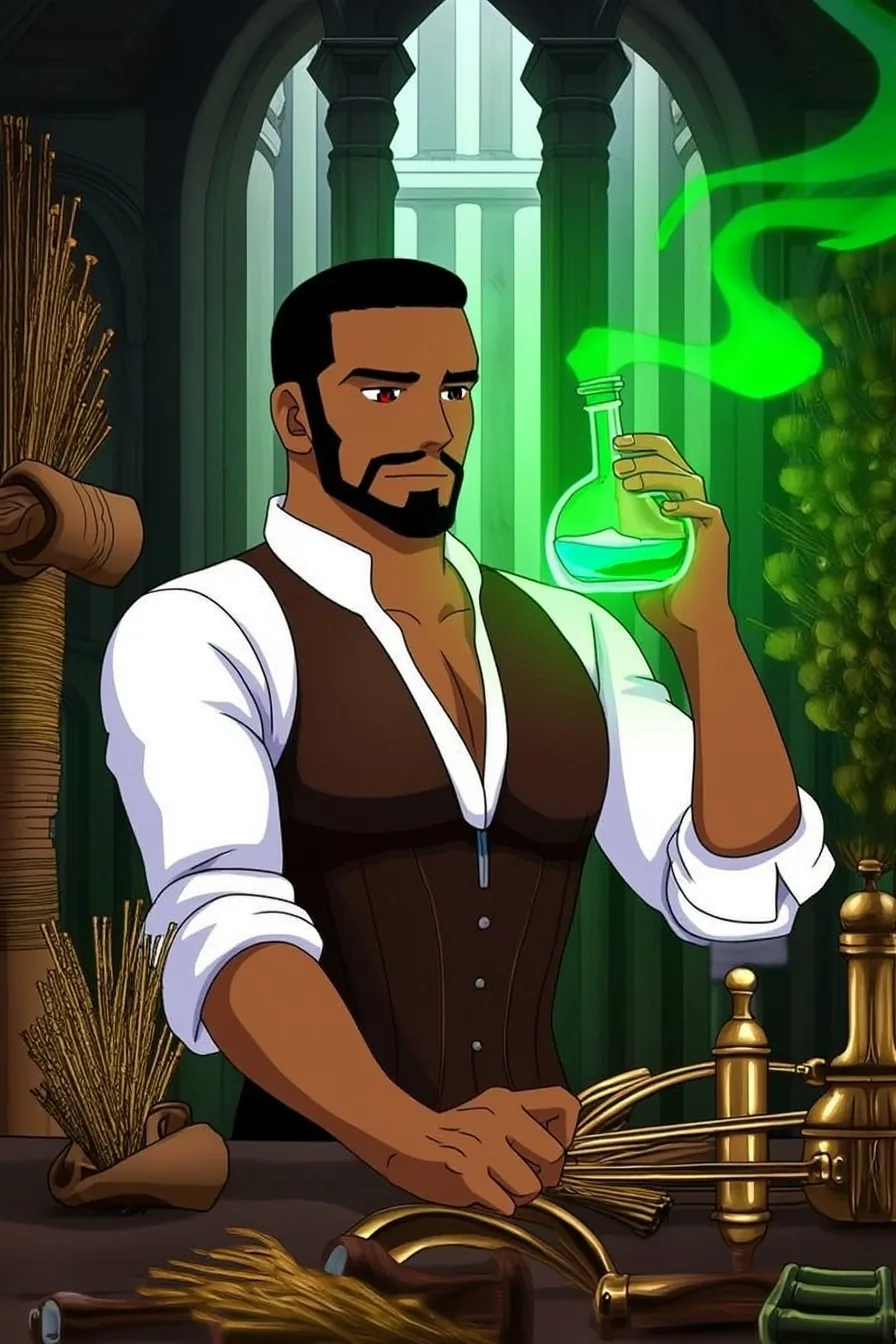
alchemist-tower The same model driven by three plain sentences instead of tags; the open collar, the waistcoat and the green glow of the flask all made it in.
- 212
- 2:3
 Output
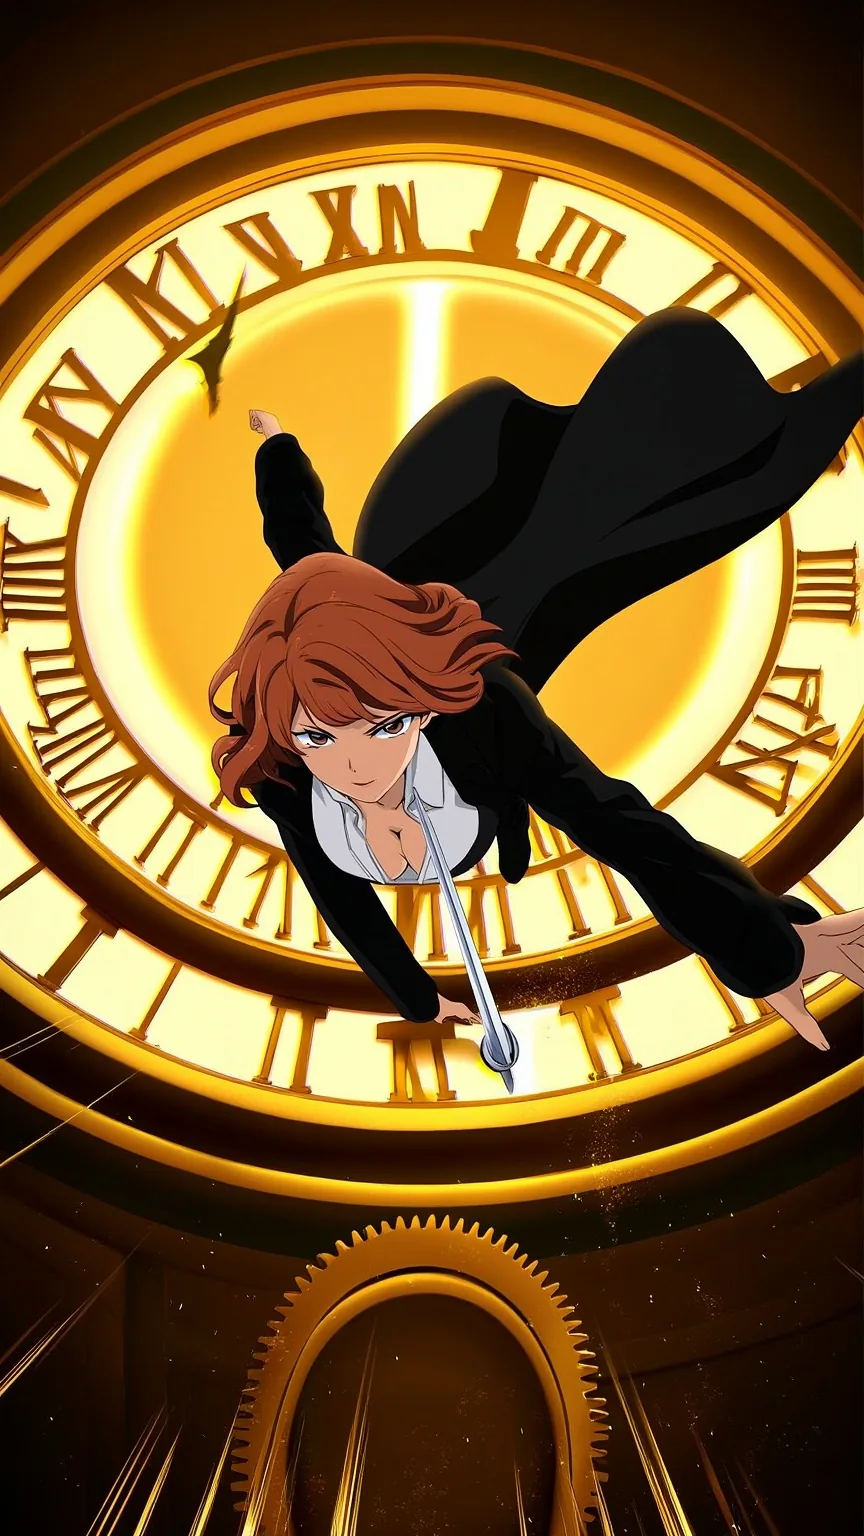
clocktower-leap "pov, extreme foreshortening, fisheye" in a tall 9:16 frame. An earlier wording without "pov" and "fisheye" drew the leap side-on, so name the camera if you want the dive aimed at you.
- 227
- 9:16
 Output
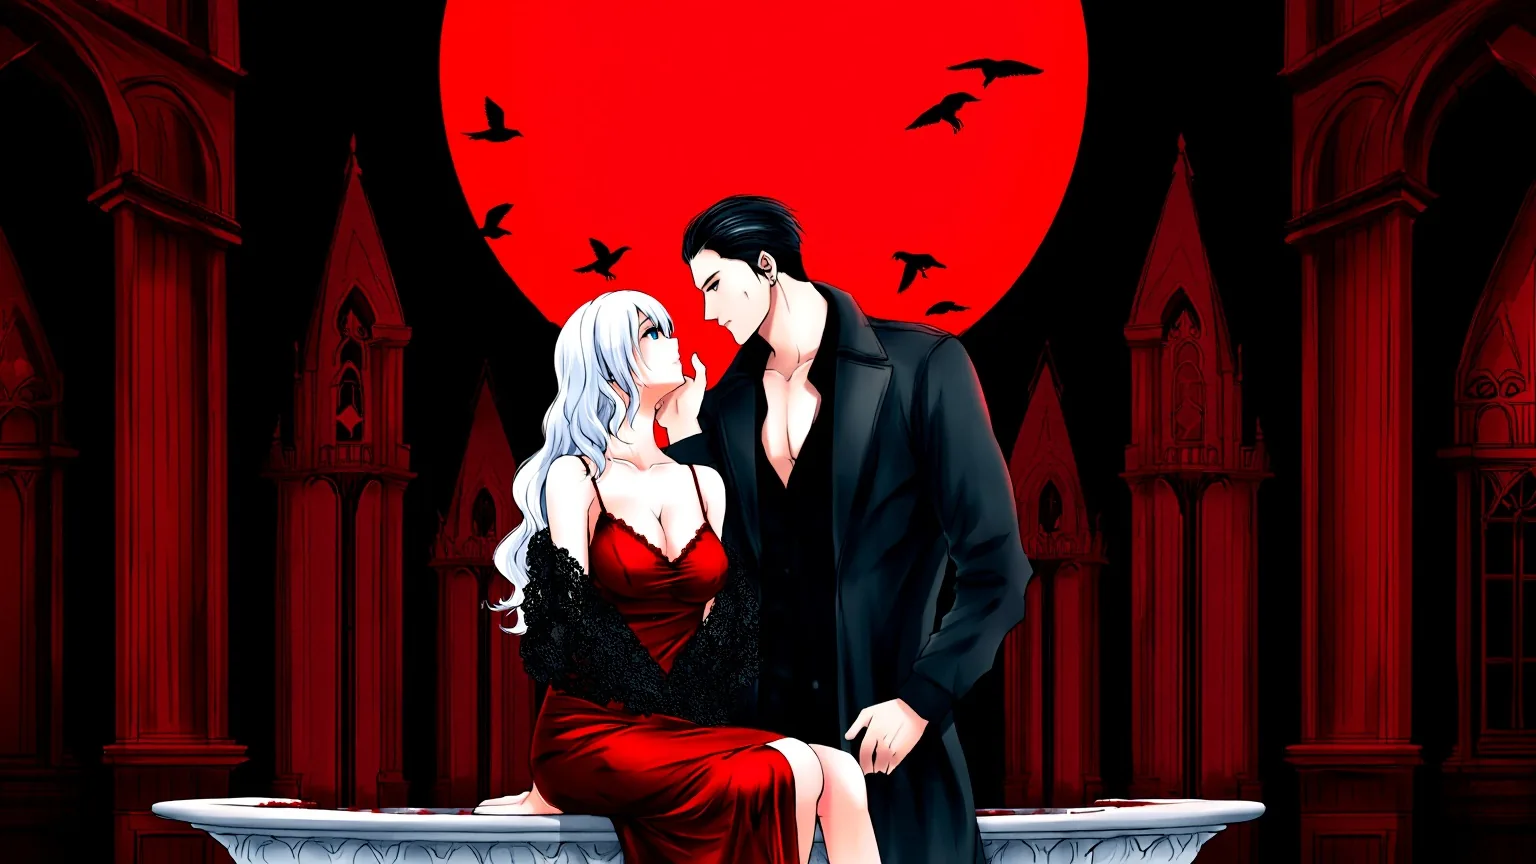
blood-moon-cloister Two characters in one prompt: head-count tags first, then each outfit in its own phrase so the model keeps them apart.
- 231
- 16:9
This example starts at $0.012 per image. The Playground updates the estimate when you change the settings.