Перейти к основному контенту

Этот обзор пока недоступен на языке «Русский», поэтому вы читаете оригинал на языке «English».

С фильтром — Эта модель прямо отклоняет запросы за пределами собственных ограничений. Это измеренный результат, а не предположение; у неизмеренных моделей отметки нет вовсе.

OmniHuman 2.0 Review: Talking Avatar From a Portrait and Audio

Pick OmniHuman 2.0 when you have a portrait and a recording and want the prompt to direct expression; expect about two minutes per short clip.

  • Мягкий

  • Умеренный

  • Сильный

  • Очень сильный

  • Максимальный

Цена
—
Медианное время
2,1 мин
Доля успешных
Собираем данные

OmniHuman 2.0 is ByteDance's audio-driven avatar model, released on 15 October 2026. SpicyAPI serves it as one endpoint, omnihuman/2.0/talking-avatar. You send a portrait (image_url) and a recording of speech or singing (audio_url), and you get back a 720p video of that person performing the recording. The face, lips, head and upper body move with it. An optional prompt of up to 300 characters directs mood, gestures and where the eyes go. There is no duration, resolution or aspect-ratio field: the clip is as long as your audio, from 4 to 300 seconds.

The verdict

We ran four portraits on 25 October 2026, each with its own recording of 4.55 to 5.2 seconds. All four clips came back at 1280 x 720 and 24 fps with the audio track, after 110 to 133 seconds of processing. The lips followed the audio in every clip, the face stayed recognisably the same person, and most of the small gestures we asked for appeared. One did not: a lean toward the microphone never showed. A fifth portrait was declined by the publisher's content check before any video was made, and nothing was charged.

Pick it when the words are already recorded and you want a face to deliver them: a narrated intro, a testimonial, a character whose portrait is settled. Look elsewhere if you need the voice generated from text, a 1080p tier or a vertical format you can select.

How it scores. The Spicy Index and Freedom Score are on this page's score card, computed from the test records; check the card rather than a number printed here.

Try OmniHuman 2.0 →

Key facts

  • Inputs: one portrait and one recording, both required. Portrait: JPEG, PNG, WebP, BMP, TIFF, GIF, HEIC or HEIF, under 30 MB, 300 to 6000 px per side, width-to-height ratio 0.4 to 2.5. Audio: WAV or MP3, under 15 MB, 4 to 300 seconds.
  • Output: 720p. In our four runs the clip was 0.2 to 1 second longer than the audio and landed on a whole number of seconds (4.55 s of audio gave 5 s, 5.2 s gave 6 s).
  • Speed: 110 to 133 seconds from submit to finished file for clips of about five seconds. It is an asynchronous task, so you poll for the result or use a webhook. We have not timed longer audio.
  • Price: billed per second of the input audio, 4-second minimum and 300-second maximum. At the time of writing that is $0.1084 a second, about $0.54 for five seconds. The model page shows the live price.
  • Content limits: the publisher reviews every portrait; see "How far it goes". The page label is Filtered.

Что понравилось и что мешало

Что понравилось

  • Lips follow the line. In all four clips the lip movement tracked the recording, including a slow, low-register line at a vintage microphone.
  • The face stays the person. Comparing frames to the input portrait, the face was recognisably the same in all four clips.
  • Small, specific beats land. A smile and a small head tilt on the last word, a half smile with a raised eyebrow, a glance away in the final second and a quick laugh all arrived roughly where the prompt placed them.
  • The body moves, not just the mouth. The publisher describes head and upper-body movement following the audio, and the examples show it.
  • Phone photos go in as they are. WebP, HEIC and HEIF portraits are accepted, so there is no conversion step.
  • Long recordings are supported. Up to 300 seconds of audio in one request, which we did not push to the limit.

Что мешало

  • It needs a recording. There is no text-to-speech path here. If you only have a script, you need a voice file first, or a model that generates the voice with the picture.
  • Body movement is less reliable than expression. "A lean toward the mic" did not visibly happen while the laugh and eyebrows beside it did. That is one run, so check a body movement before you build on it.
  • Slow for a short clip. About two minutes of processing for a clip of about five seconds.
  • Per-second price is higher than Kling Avatar 2.0. At the time of writing Kling Avatar 2.0 is $0.0512 a second at 720p, against $0.1084 here. Kling also has a 1080p tier; OmniHuman 2.0 is 720p only.
  • Every portrait goes through a content check. A declined portrait is not billed, but you only find out after submitting.
  • The output length is not exactly the audio length. Inspect the returned file if you are cutting to a precise timeline.

What the clips look like

The gallery holds four published examples from the OmniHuman 2.0 model page, all clothed and safe for work. Three of them use the same portraits and recordings as the Kling Avatar 2.0 page, trimmed to about five seconds, so the two pages can be compared side by side.

A slow line at a vintage microphone. A woman in a black velvet gown, 5.2 seconds of slow audio. The lips track the audio, a small head tilt and a smile land at the end as the prompt asked, and her hand stays on the microphone. The clip runs 6.0 seconds.

A low, teasing line behind a bar. A man behind a dim bar, a 5.0-second spoken line. His eyes close and reopen, the half smile and raised eyebrow follow the line, and the bottles behind him stay stable.

A glance away in the last second. A woman on a sunny stone terrace, 4.55 seconds of audio. Her head turns toward the sea in the final second and her hair moves slightly.

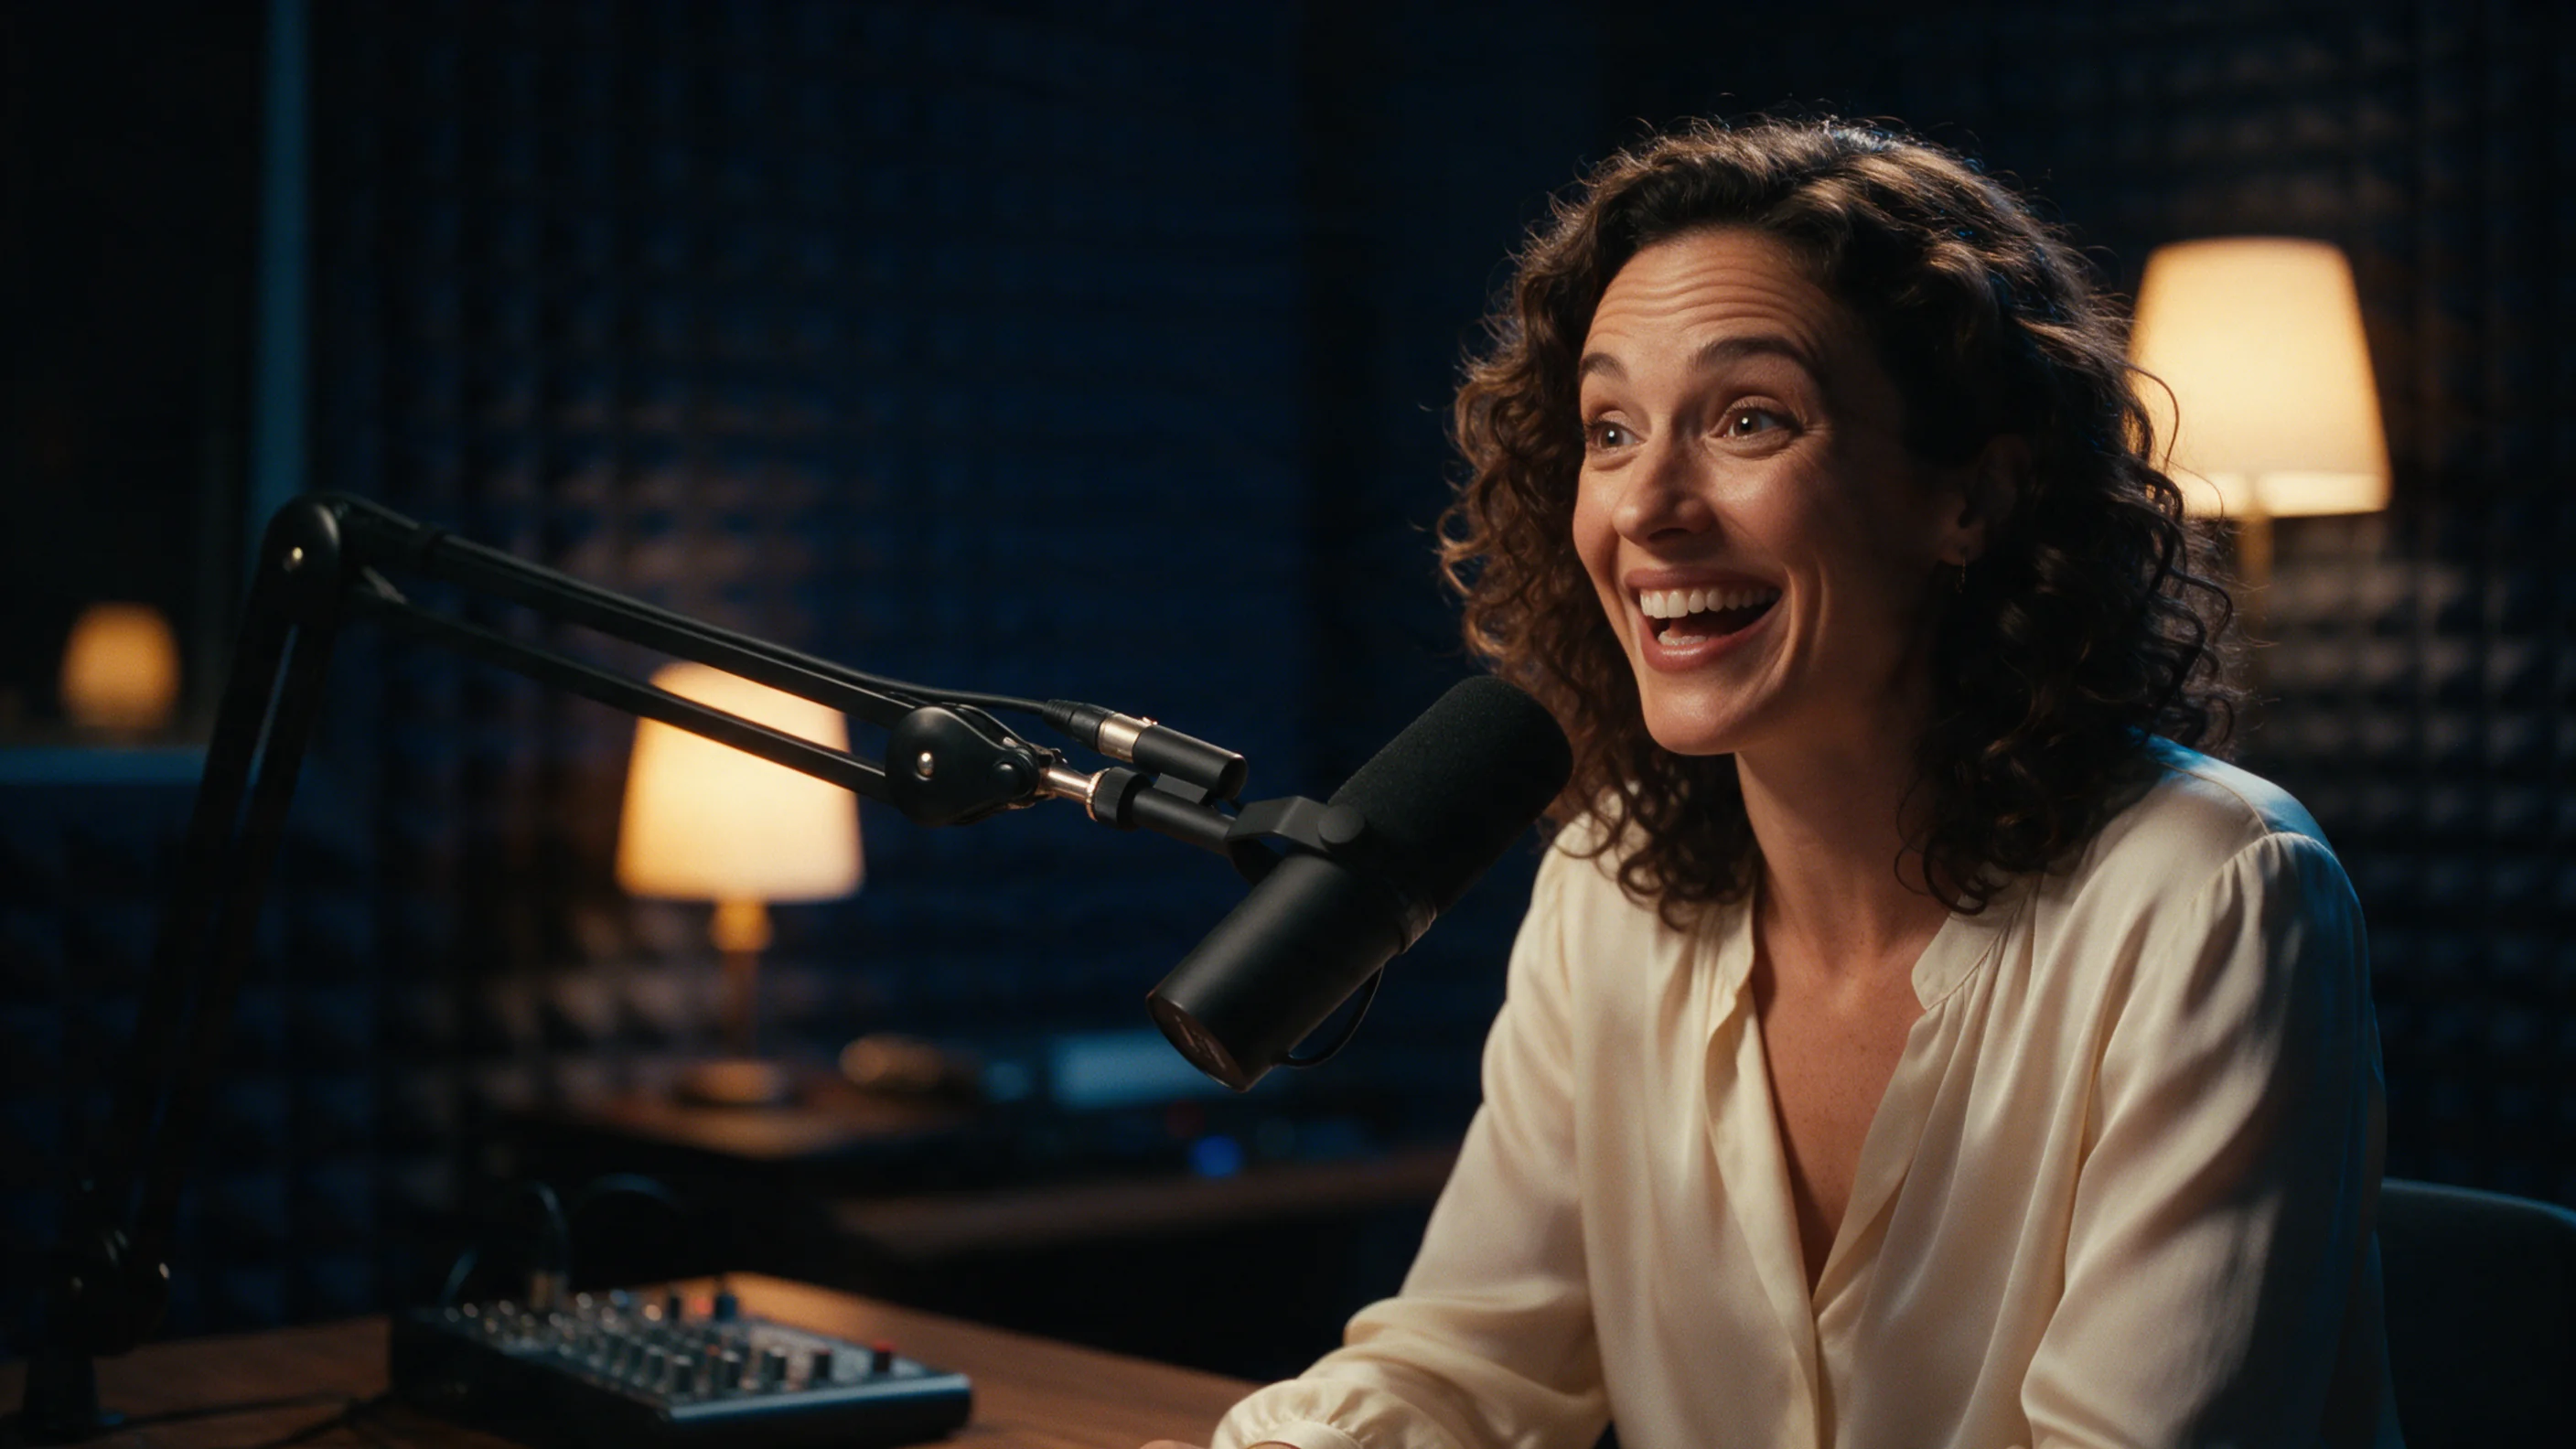
A late-night show opening. A woman in a podcast studio, an upbeat 4.8-second intro. Wide expressions, lively eyebrows and a laugh follow the prompt, but she does not visibly lean toward the microphone.

Prompts that worked

The prompt directs the performance. The portrait and the recording already decide who is on screen and what is said.

  • Tie a beat to a moment in the line. "Slow and languid, a lazy smile on the last word and a small tilt of the head, eyes on the lens." Both the smile and the tilt arrived at the end.
  • Pair a posture with an expression. "Leaning on the bar, he speaks low and teasing, a slow half smile and a raised eyebrow, warm amber light." The clip kept a consistent low register.
  • Give a gesture a moment to happen. "Relaxed on a sunny terrace, she murmurs the line with a knowing smile and glances away at the end." The head turn landed in the final second.
  • Keep to a few beats. Each of our prompts asked for a mood, one or two facial beats and sometimes a posture. That is enough to shape a five-second clip.
  • Trim the audio first. The clip runs as long as the file and billing follows the audio length, so cut the recording to the performance you want.

The publisher lists Chinese, English, Japanese, Korean, Spanish (Mexican) and Indonesian as prompt languages. Our prompts were in English, and we did not test camera-movement instructions.

How far it goes

SpicyAPI adds no filter of its own, but the publisher reviews every portrait before a clip is made. On 25 October 2026 we sent one portrait at the Moderate level of our five-level ladder (Mild, Moderate, Strong, Very strong, Maximum; test prompts not published). It was declined before any video was generated, in under half a minute, and nothing was charged. That is a refusal, not a toned-down result.

Not tested yet: Mild, Strong, Very strong and Maximum on this endpoint, so the score card has too few content levels for a full Freedom reading. We have no data on the other levels, so try your own portrait before you plan a project around it.

This endpoint makes a specific face say or sing specific words, which carries real personal risk if that face and voice are not yours to use. Send only a portrait and a recording that are your own, or that the person shown and heard has explicitly agreed to. Adults only, and never a real, identifiable person without consent.

Alternatives

Как далеко заходит OmniHuman 2.0

Баллы Freedom по уровням и задачам
УровеньГоворящий аватар
МягкийСамые лёгкие промпты в тестеПока не проверяли
УмеренныйЗдесь фильтрованные модели начинают отказывать
выполнено 0/10,0 / 20 б.
СильныйСередина шкалы; перед включением в рейтинг обязательно проверяетсяПока не проверяли
Очень сильныйЗдесь большинство моделей начинает сдерживатьсяПока не проверяли
МаксимальныйВерхняя часть шкалы, оценивается в двух половинах: класс A и класс BПока не проверяли
Оценка задачиДиапазон, если остальное пройдёт: 0,0–80,0Проверено 25 окт. 2026 г.

Проверено с 25 окт. 2026 г. по 25 окт. 2026 г.

Этот сайт безопасен для просмотра на работе: результаты описаны текстом, показанные изображения пикселизированы, а тестовые промпты никогда не публикуются. Мы никогда не тестируем людей, выглядящих несовершеннолетними, внешность реальных людей или отсутствие согласия.

Все записи тестов →Смотреть рейтинг без цензуры →

Проверьте на своём промпте, как далеко заходит модель
Из чего складывается Spicy Index модели OmniHuman 2.0

Публичные рейтинги 45 % качества
Пока не проверяли

В отслеживаемых публичных рейтингах пока нет точного совпадения. Как это работает

Слепой тест результатов 35 % качества
Пока не проверяли

Модель пока не проходила наш слепой тест результатов. Как это работает

Качество на арене 20 % качества
Пока не проверяли

Учитывается, когда у модели будет больше 100 слепых голосов и 95%-й интервал уже 200 Эло. Как это работает

Возможности Вес 10,5 %
Пока не проверяли

Пока не оценено. Как это работает

Freedom Score Вес 30 %
Пока не проверяли

Свобода не проверена или данных недостаточно. Index сохраняет исходный балл качества и возможностей, помечается как предварительный и продолжает участвовать в рейтинге. Отсутствие данных не равно нулю. Как это работает

Открыть полный отчёт о тестах →

Что OmniHuman 2.0 умеет на SpicyAPI

Возможности по эндпоинтам
ФункцияГоворящий аватар
Встроенный звукНет
Управление seedНет
Негативный промптНет
Все параметры и примеры кода →

Сколько это занимает на самом деле

Измерено на реальных задачах за последние 30 дней — от запроса до готового результата. Время включает и наши собственные тестовые запуски.

Медианное время
2,1 мин
90-й процентиль
3,3 мин
Ожидание на секунду видео
Собираем данные
Доля успешных
Собираем данные

Время появляется, когда набирается не менее 10 завершённых задач. Доля успешных считается только по задачам клиентов и скрыта для всех моделей, пока не наберётся 30 полных дней трафика.

Модели, которые стоит рассмотреть вместо OmniHuman 2.0

Что вы думаете?

Был ли этот обзор полезен?

Войдите, чтобы проголосовать.

Комментарии

Комментарии проверяются автоматически и нашей командой. Мы удаляем спам, неуместный контент, личные нападки и всё, где без согласия называют реального человека. Пожалуйтесь на комментарий — мы рассмотрим жалобу в течение одного рабочего дня.

Пробовали эту модель? Поделитесь тем, что сработало. Чтобы комментировать, нужен бесплатный аккаунт — так мы защищаемся от спама.

Вопросы о OmniHuman 2.0

Попробуйте OmniHuman 2.0 сами

Настройте каждый параметр в Playground и узнайте точную цену до запуска.

Другие обзоры

Смотреть рейтинги →
  • A white cliff-top hotel lit gold at night above a dark sea, a glass rooftop pavilion, a lantern-lit pool terrace and a mahogany motor launch speeding away under the moon

    P-Video 2 Pro

    Pick P-Video 2 Pro for fast takes with built-in sound; for Maximum-level requests delivered as written, try another video model.

    Spicy Index
    63,7
    Freedom Score
    58,7

    Проверено 17 окт. 2026 г.

    Читать обзор
  • Крупный план женщины, поющей в винтажный микрофон под одиночным прожектором на фоне глубокого синего бархата

    Kling Avatar 2.0

    Kling Avatar 2.0 превращает один портрет и один аудиофайл в говорящий или поющий клип длиной до пяти минут, в 720p или 1080p.

    Spicy Index
    —

    Проверено 28 сент. 2026 г.

    Читать обзор
  • Женщина в изумрудном шёлковом платье среди больших тропических листьев в стеклянной оранжерее в сумерках

    Wan 3.0

    Wan 3.0 — для дешёвых 30-секундных дублей без цензуры и со звуком из текста, кадра или референсов; не для сцен, что должны кончиться вместе со сценарием.

    Spicy Index
    87,7
    Freedom Score
    96,0

    Проверено 24 сент. 2026 г.

    Читать обзор