
Wan 2.1 Image LoRA text-to-image renders a single photorealistic frame from Alibaba's 14B video model with up to three of your own Wan LoRA files. Nine aspect ratios at 1k or 1.5k, one flat price per image, nothing filtered.
Workbench
These examples were written for this endpoint. Replace the prompt and sample media URLs with your own accessible inputs, then check the current quote and model availability before submitting.
 Output
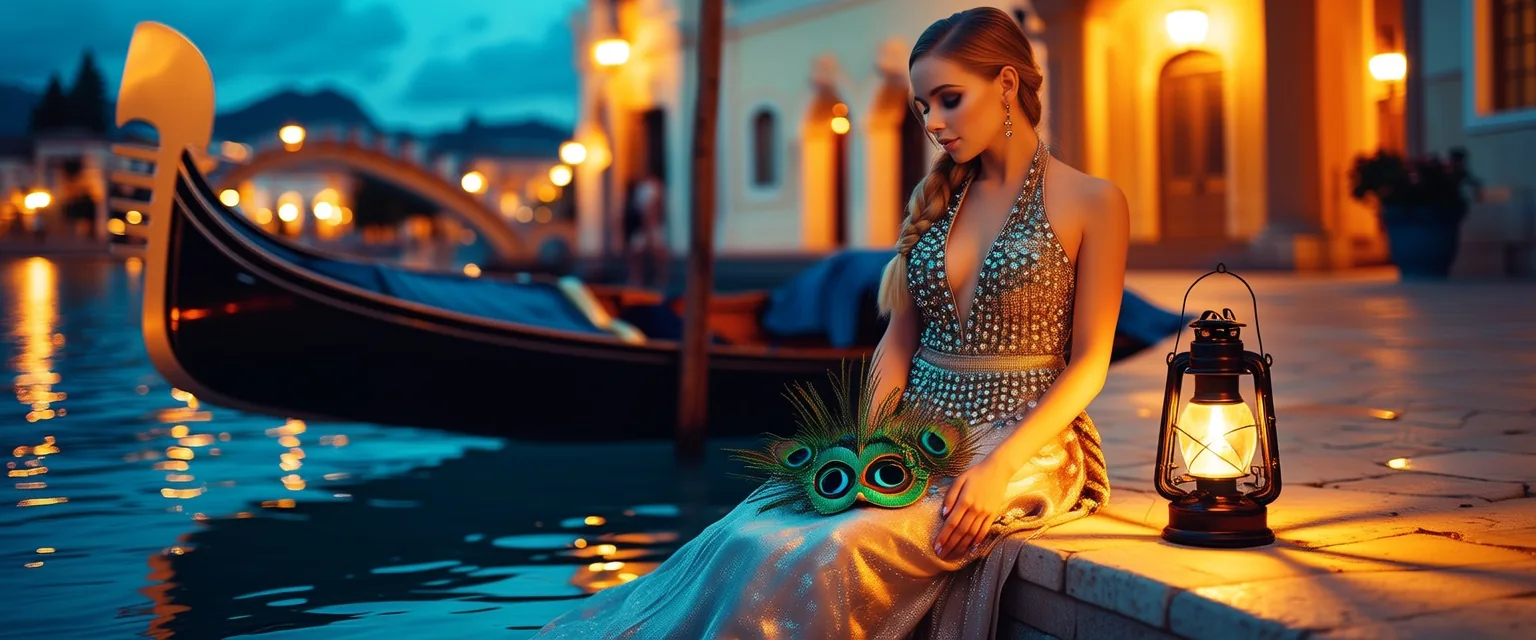
water-steps-feathers No LoRA, 21:9 at the 1.5k tier, which comes back 1536 x 640. Sequins, lantern light on skin and the reflections on the canal hold together across the wide frame.
- 210944
- 1.5k
- 21:9
 Output
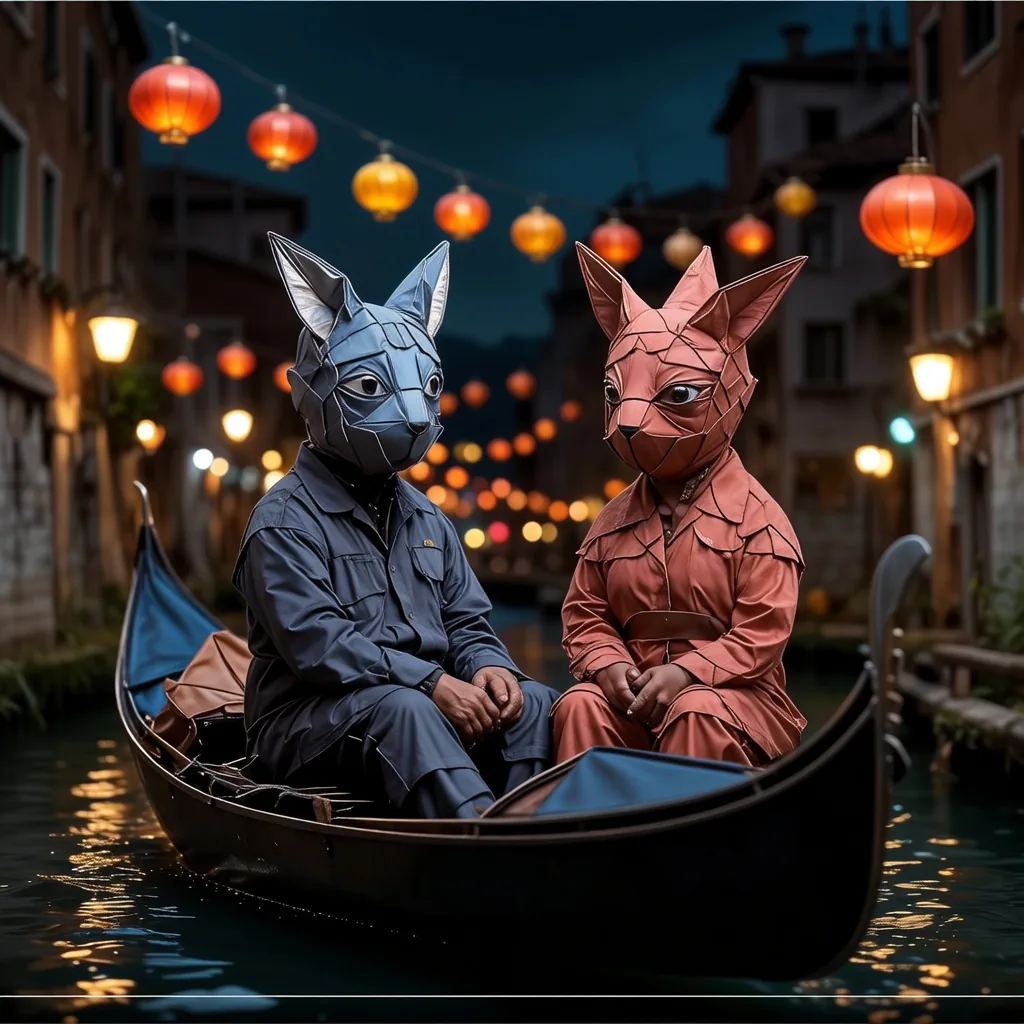
origami-gondola-masks An origami LoRA for Wan 2.1 at 1 with its trigger word. The same prompt and seed without the LoRA gave two people in painted carnival masks; with it the couple turns into folded-paper figures, gondola and lanterns unchanged.
- 7006
- 1:1
 Output
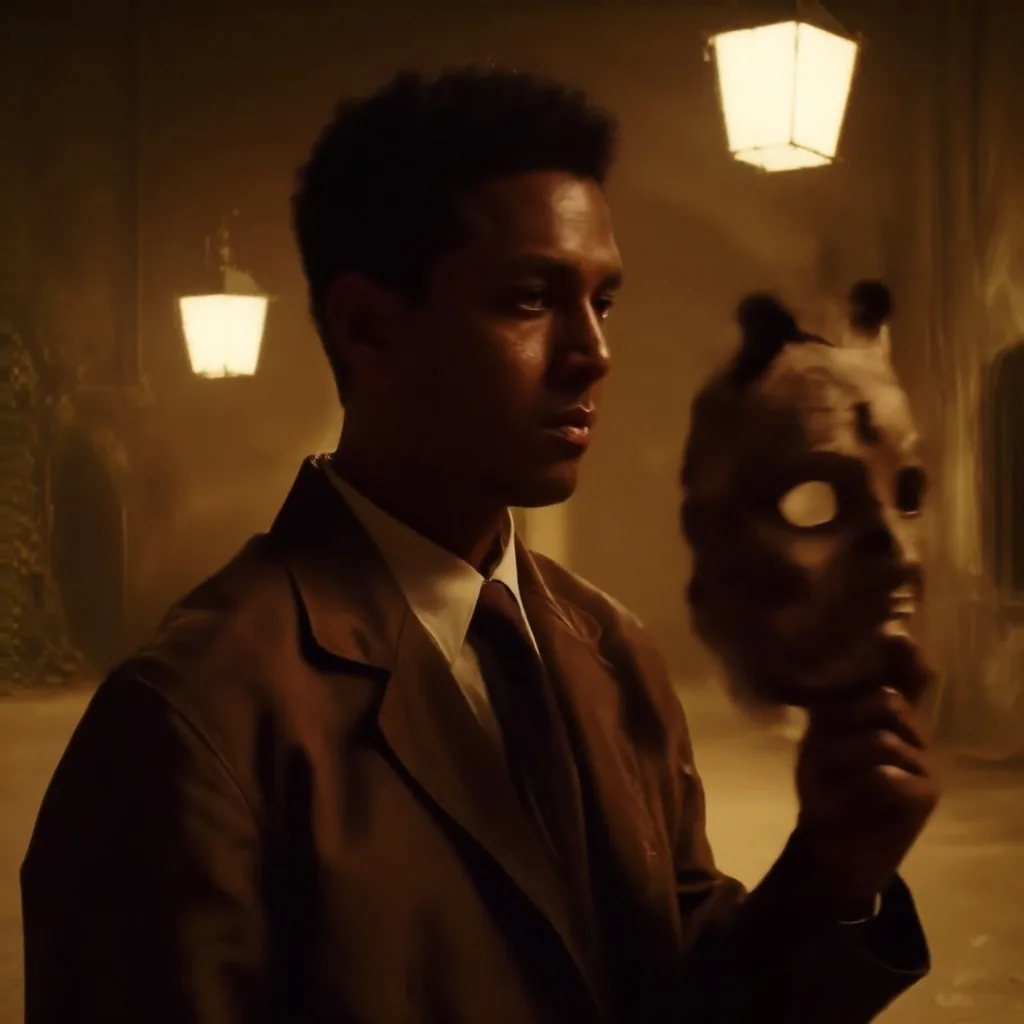
vintage-lantern-alley A Wan 2.2 single-file style LoRA (vintage film) at 1 on this Wan 2.1 model. The same prompt and seed without it gave a crisp, cool colour photograph; with it the frame turns warm brown with soft film light, and the scene is redrawn.
- 7004
- 1:1
 Output
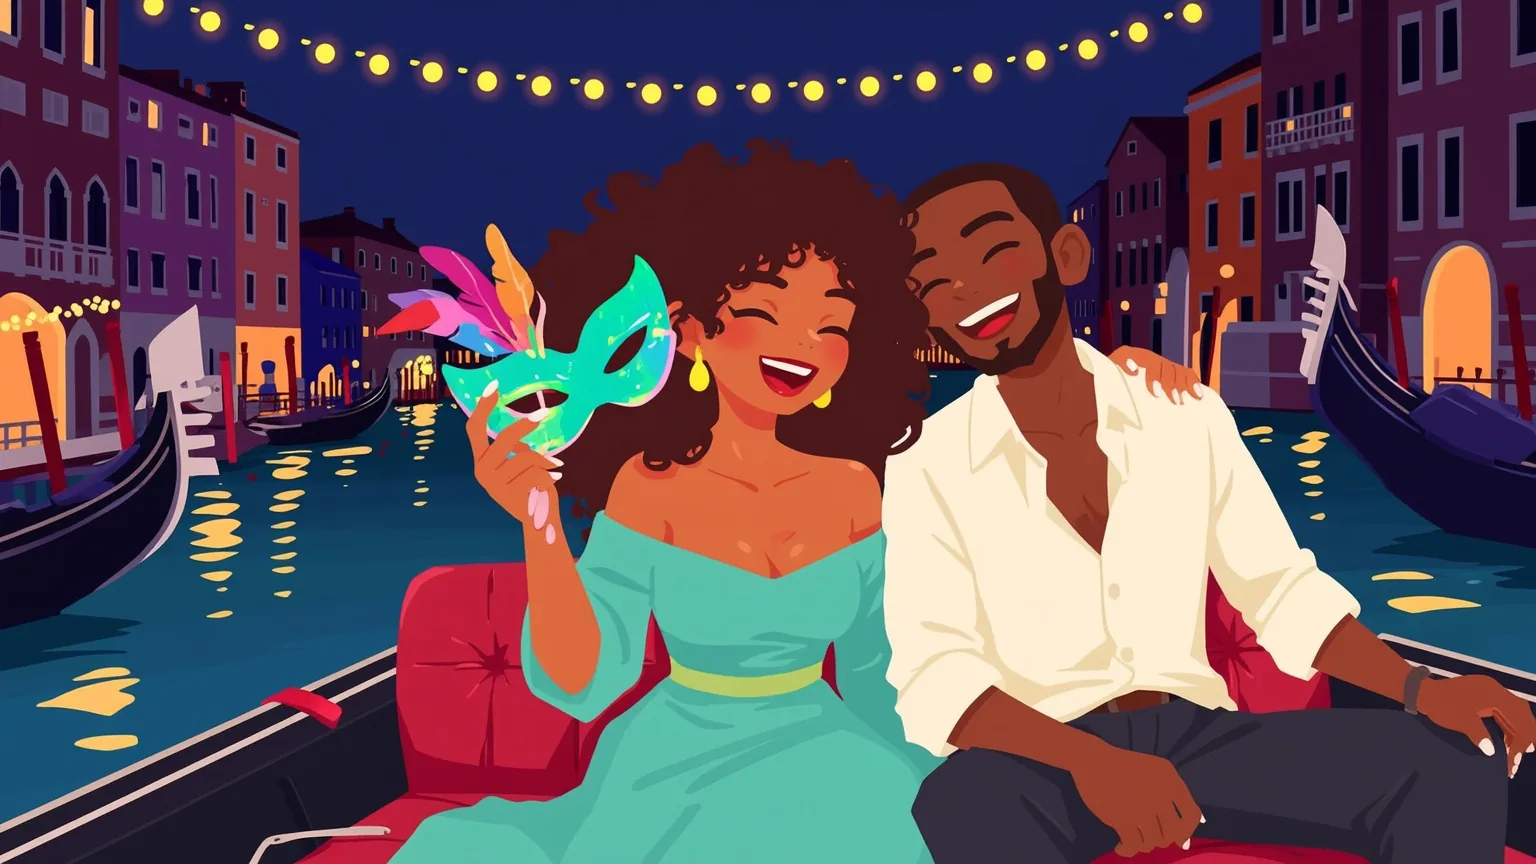
gondola-pair-flat-color A flat-colour LoRA at 1 with its trigger words, 16:9 at 1.5k (1536 x 864). On stills the trigger words alone already lean toward flat illustration, so the LoRA's own effect is easier to see on video.
- 210943
- 1.5k
- 16:9
This example starts at $0.03 per image. The Playground updates the estimate when you change the settings.