Wan 2.1 Image LoRA text-to-image renders a single photorealistic frame from Alibaba's 14B video model with up to three of your own Wan LoRA files. Nine aspect ratios at 1k or 1.5k, one flat price per image, nothing filtered.

From $0.03/image

Workbench

Input

Text to image
356/5000
Trigger words first if your LoRA has them, then the subject, the setting and the light. Up to 5,000 characters. at least 1 characters · at most 5000 characters
1:1 (the default), 16:9, 9:16, 4:3, 3:4, 3:2, 2:3, 21:9 or 9:21. At 1k: 1024 x 1024, 1344 x 768, 1152 x 896, 1216 x 832, 1344 x 576 and their portrait swaps. The shape does not change the price.
1k (about one megapixel, the default) or 1.5k (1536 pixels on the long edge, for example 1536 x 864 for a landscape frame). Same price for both.
Style LoRAs0/3
Up to three {path, scale} entries trained for Wan 2.1 14B; path is a public direct link to a .safetensors file, scale runs from 0 to 4 (1 by default). Loading LoRAs does not change the price. at most 3 items
Output format
JPEGPNGWebP
jpeg (the default), png or webp. No effect on price.
Seed
Use it to compare runs; the same seed did not always return the same image in our test. no lower than 0 · no higher than 2147483647
Safety checkerOff

SpicyAPI does not run a safety checker on this model. Your prompt and media go to the model as written, and the model itself decides what comes back.

Checking your account before enabling submission and pricing.

Output

Ready for a new run
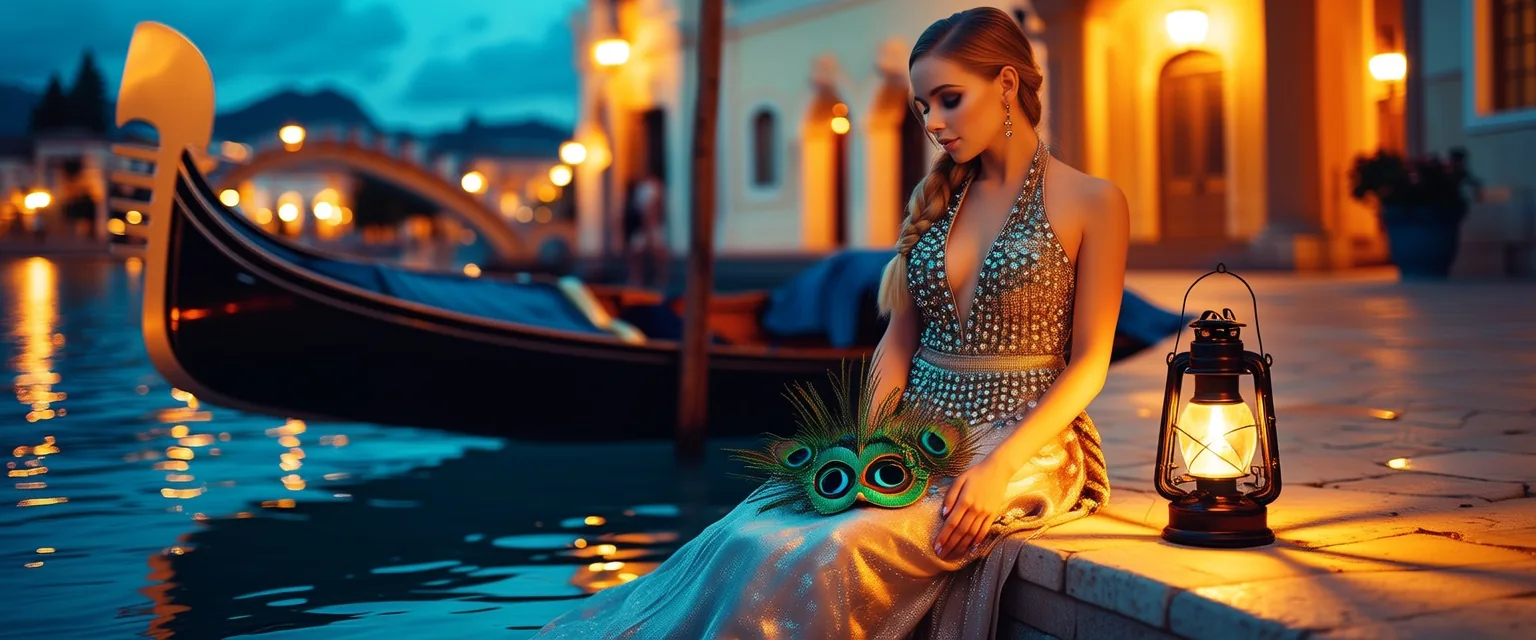
water-steps-feathersExample result

Missing the model you need?

Tell us what to add and where you would use it. Requests go to the people who decide what gets onboarded next.

LORA IMAGE API

Wan 2.1 Image LoRA API at a glance

Wan 2.1 as a still-image model with your own LoRAs: text to image and image editing, up to 1536 px, no content filter.

LoRAs per image
3
Up to three weight files per request, each with its own strength from 0 to 4.
Aspect ratios
9
From 21:9 to 9:21, each at 1k or 1.5k.
Long edge
1536 px
The 1.5k tier puts 1536 pixels on the long edge, at the same price as 1k.
LoRAs that load
2.1, 2.2
Wan 2.1 14B LoRAs load, and in our test a Wan 2.2 style LoRA changed the image too.
Price
Flat
One price per image, whatever the size, source image or LoRAs.
Content filter
None
Uncensored: no review of your LoRAs and no filter on the result.

Results

What you can make with Wan 2.1 Image LoRA

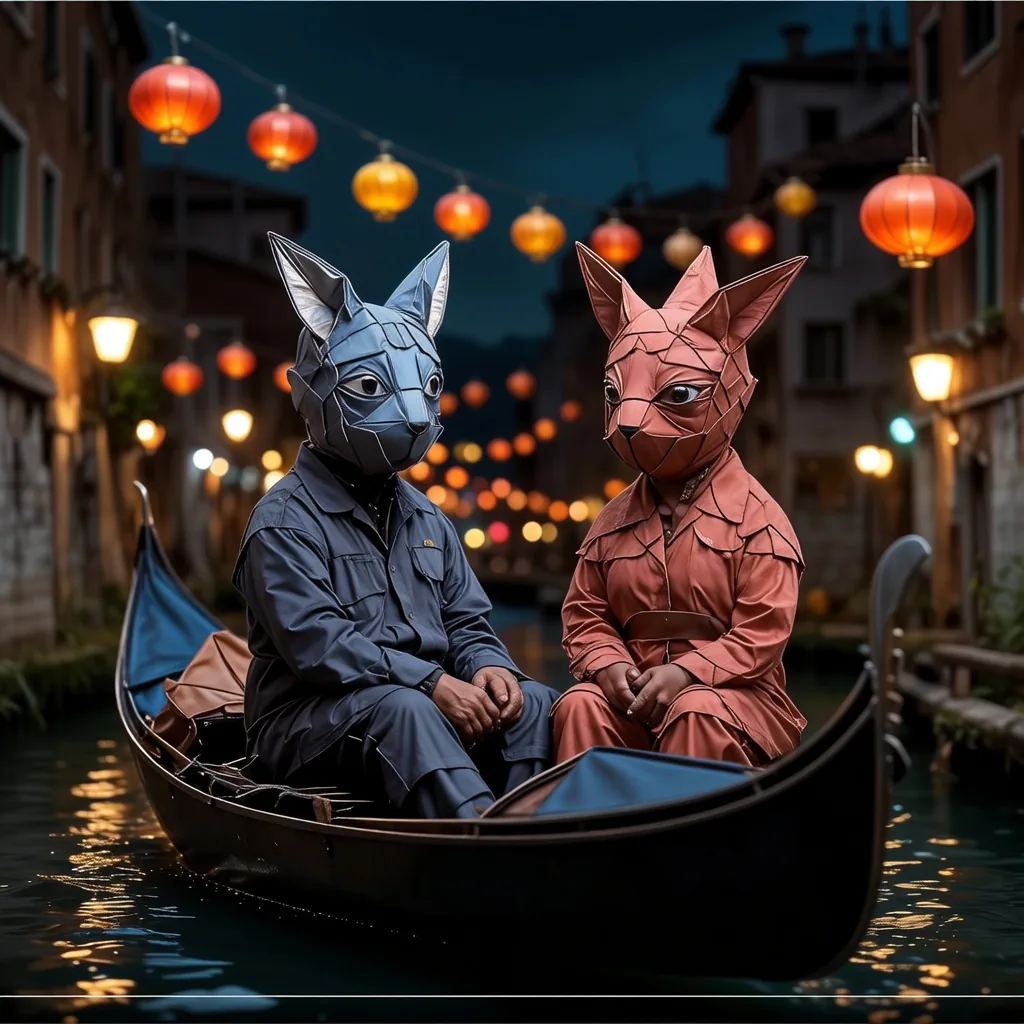
  • Two folded-paper figures with fox-like origami heads, one blue and one terracotta, sitting in a gondola under hanging lanterns on a Venetian canal at night

    Style LoRAs

    Folded paper from one trigger word

    An origami LoRA for Wan 2.1 at scale 1: the masked couple in the gondola becomes folded-paper figures, while the canal and the lanterns stay photographic.

    Text-to-image with an origami LoRA at 1, 1:1.

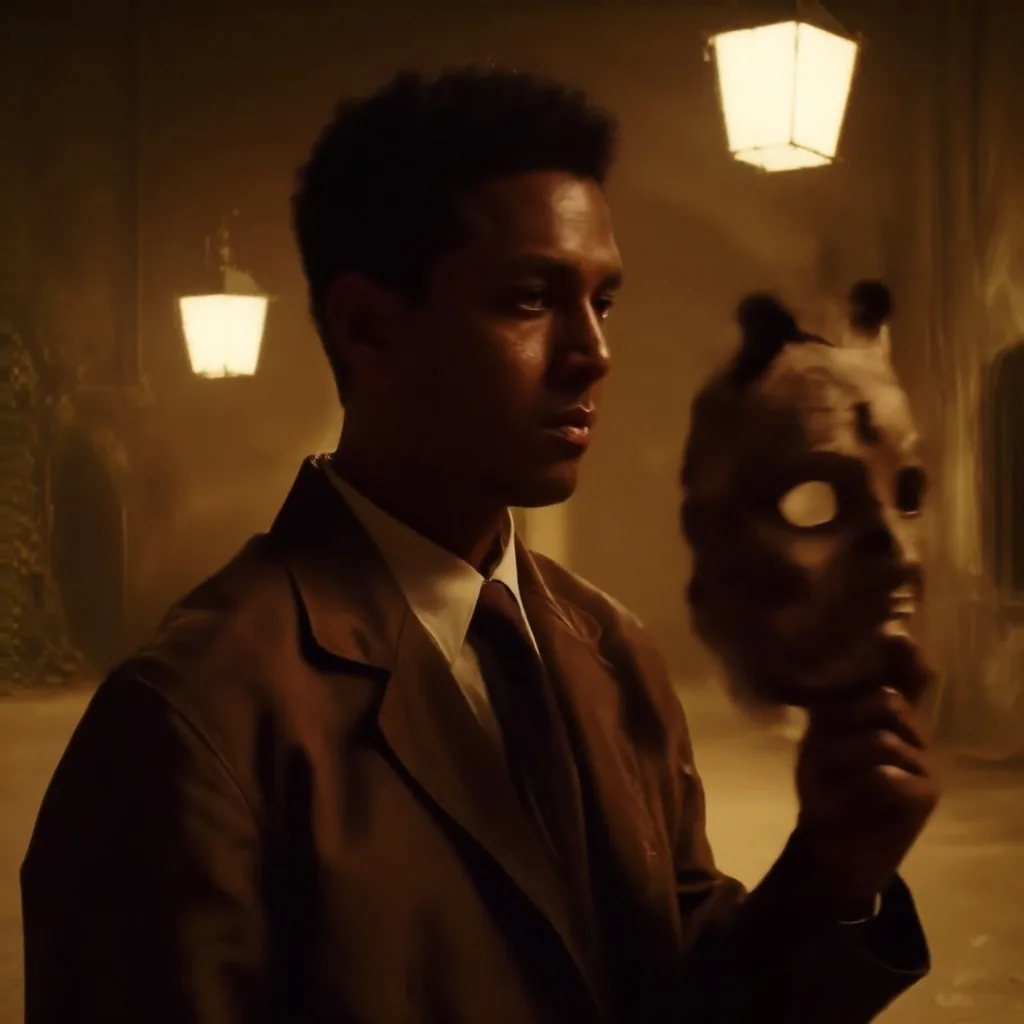
  • A man in a brown coat and tie holding a weathered carnival mask in a lantern-lit alley, in warm brown vintage film tones

    Wan 2.2 LoRAs

    Wan 2.2 LoRAs work here too

    A Wan 2.2 vintage-film LoRA turned a crisp colour photograph into warm brown film light. Single-file Wan 2.2 LoRAs took effect on this model in our tests.

    Text-to-image with a Wan 2.2 vintage-film LoRA at 1, 1:1.

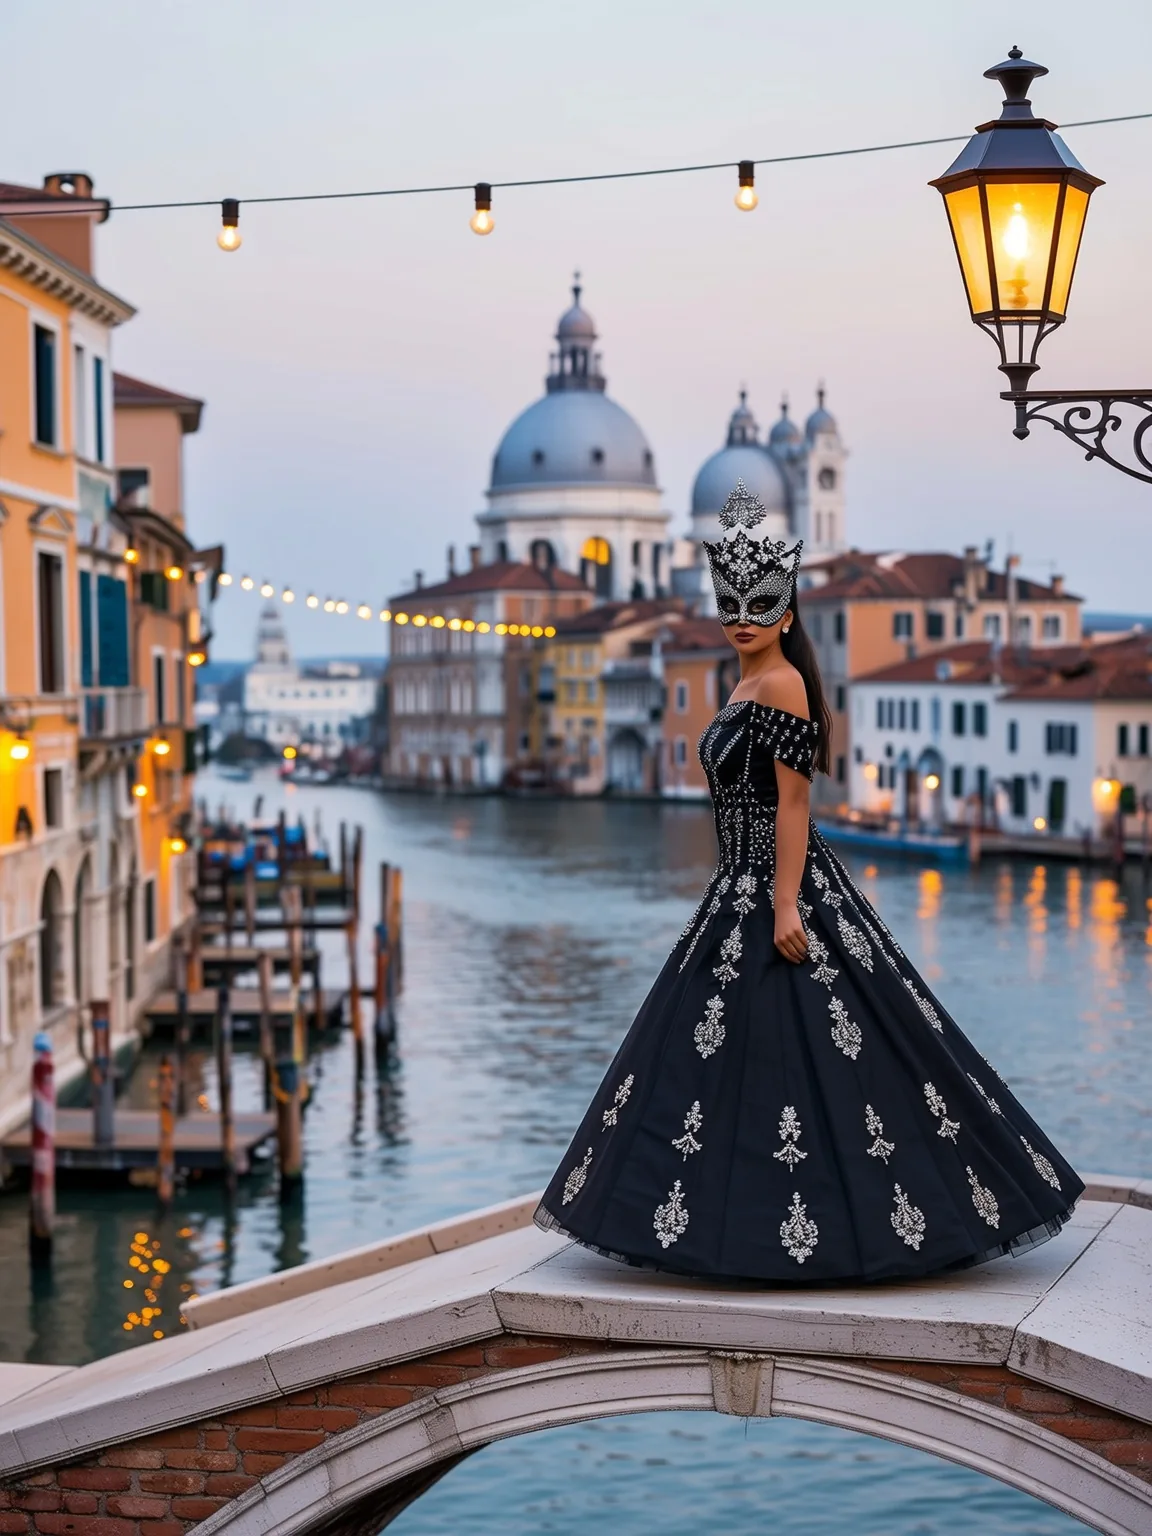
  • A woman in a black lace masquerade gown and a silver filigree mask standing on a small stone bridge over a Venetian canal at dusk, string lights between the houses

    Image editing

    Daylight street to carnival night

    Strength 0.75 keeps the bridge and the pose from a daylight photo and redraws the hour, the gown and the mask.

    Image editing at strength 0.75, 1.5k, from a daylight street photo.

Content test

Is Wan 2.1 Image LoRA uncensored? What we tested

We ran each level on our live setup and checked every clip frame by frame. A pass means the content was actually on screen, not just that the request went through.

Content levels tested on Wan 2.1 Image LoRA, by mode
LevelImage editingText to image
MildThe lightest prompts in the test
RendersTested Oct 9, 2026
ModerateWhere filtered models start to refuse
RendersTested Oct 9, 2026
StrongThe middle of the scale
RendersTested Oct 9, 2026
Very strongWhere most models start to hold back
Not tested yet
Not tested yet
MaximumThe top of the scale
RendersTested Oct 9, 2026

Renders: on screen as written. Softened: generated, but milder than what was written. Refused: rejected. Not tested yet: we have not run that level on that mode.

How each mode behaves

All modes
LoRAs must be public direct links to .safetensors files, at most three; a page link, a gated file or a LoRA for an unrelated model fails the request, which is not charged. The same seed does not guarantee the same image here. Scenes between two people come back toned down; the other content levels we tested were drawn as asked.
Image editing
The result keeps the source's shape, and faces change at the strengths that change the scene. Style prompts and style LoRAs did not override the source's colours at strength 0.7.

Use cases

What to build with the Wan 2.1 Image LoRA API

  • Preview a video LoRA cheaply

    See what a Wan LoRA does to a face or a style on a still before paying for clips.

  • Opening frames for image-to-video

    Render the first frame here with the same LoRA, then animate it with Wan 2.1 LoRA image-to-video.

  • Photoreal portraits and scenes

    Lantern light, skin and fabric texture come out well at 1.5k, in any of nine shapes.

  • Uncensored community LoRAs

    LoRAs of any kind load like any other file: no allow-list, no review, no filter on the result. Everyone shown must be an adult.

Prompts

Wan 2.1 Image LoRA prompt examples you can copy

Paste one into the playground as it is, then change one thing at a time.

  • Text to image

    Feathers on the water steps

    Photorealistic photograph. On the water steps of a palazzo at night, an adult Ukrainian woman in her late twenties with braided blonde hair sits with her silver sequinned gown pooled around her, a peacock-feather mask resting in her lap, her bare shoulders lit by a lantern while a gondola waits at the mooring pole. Wide shot, 35mm, teal and gold palette.

    Why it works. No LoRA, 21:9 at the 1.5k tier, which comes back 1536 x 640. Sequins, lantern light on skin and the reflections on the canal hold together across the wide frame.

    Try this prompt
  • Image editing

    From hoodie to masquerade

    Night on the same small stone bridge over a Venetian canal during carnival. The same adult Indian woman now wears a black lace masquerade gown with bare shoulders and a silver filigree half-mask, lanterns glowing along the canal and strings of lights between the houses, cinematic photograph.

    Why it works. Strength 0.75 on a daylight photo of a woman in a grey hoodie on a canal bridge: the bridge, her stance and the canal stay, while the hour, the gown and the mask change. Her face is redrawn too, as it is at any strength that changes the scene.

    This mode starts from your own image: add it in the playground before you run.

    Try this prompt
  • Text to image

    Origami gondola and masks

    origami. An adult couple in carnival masks sits in a gondola under hanging lanterns on a Venetian canal at night.

    Why it works. An origami LoRA for Wan 2.1 at 1 with its trigger word. The same prompt and seed without the LoRA gave two people in painted carnival masks; with it the couple turns into folded-paper figures, gondola and lanterns unchanged.

    Try this prompt

Pricing

Wan 2.1 Image LoRA API pricing

One image starts at $0.03.

The playground shows the exact price for your settings before you run. Failed or timed-out tasks are usually not charged. Some models charge for content refusals as stated on their model page; check those billing terms before submitting.

See every price tier

Get started

How to use the Wan 2.1 Image LoRA API in three steps

  1. Step 1

    Use video LoRAs on stills

    Wan 2.1 renders an image as a single frame, so Wan 2.1 14B text-to-video LoRAs work here. Test a LoRA on a still first: a still costs a fraction of a clip and comes back in seconds.

  2. Step 2

    Pick the 1.5k tier

    1.5k costs the same as 1k and renders cleanly; in our runs 1536 x 1536 showed no doubled people. Both sides are rounded down to a multiple of 32.

  3. Step 3

    Editing is redrawing

    Image-to-image redraws the source at the strength you set. Around 0.5 the source comes back nearly unchanged, around 0.75 to 0.8 the scene changes and faces change with it. It is not an instruction editor.

Parameter reference and code samples are in the API and Readme tabs at the top of this page.

Why SpicyAPI

Why run Wan 2.1 Image LoRA on SpicyAPI

  • No filter from us

    We add no content filter of our own. What the model renders is what you get back.

  • Tested, not guessed

    Content labels come from real generations we ran and checked, with the test date on the page.

  • Pay per result, in dollars

    No subscription and no credits. Failed or timed-out tasks are usually not charged. Some models charge for content refusals as stated on their model page; check those billing terms before submitting.

  • One key for every model

    One API key and balance cover image, video, audio and chat models, so you can explore more models from the same account.

FAQ

Wan 2.1 Image LoRA API FAQ

About Wan 2.1 Image LoRA

Wan 2.1 Image LoRA turns Alibaba's open 14B video model into a photoreal still-image model that loads your Wan LoRAs: up to three per request, nine aspect ratios at 1k or 1.5k, image-to-image from your own source, one flat price per image. LoRAs are not reviewed and nothing is filtered.

All Wan models22

Video models18

Related models and next tasks