
Text-to-image on Z-Image Base, the 6-billion-parameter non-distilled Z-Image model from Alibaba's Tongyi-MAI team, with up to three of your own LoRAs per request. Sentence prompts, nine aspect ratios, JPEG, PNG or WebP, and no filter on prompts, weights or results.
Workbench
These examples were written for this endpoint. Replace the prompt and sample media URLs with your own accessible inputs, then check the current quote and model availability before submitting.
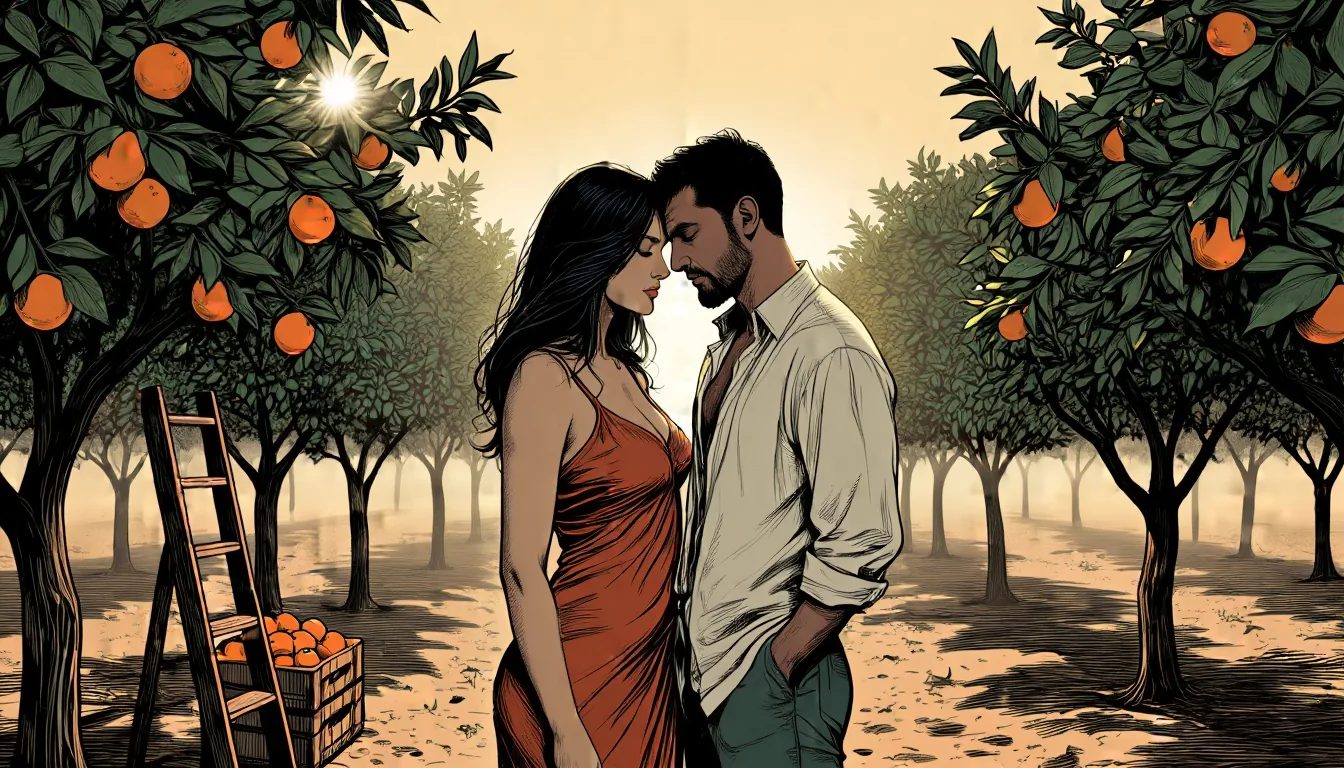 Output
orange-grove-sunrise An illustration LoRA trained on Z-Image Base at 1, with its trigger phrase "mature illustration with muted color and complex linework" first.
- 321
- 16:9
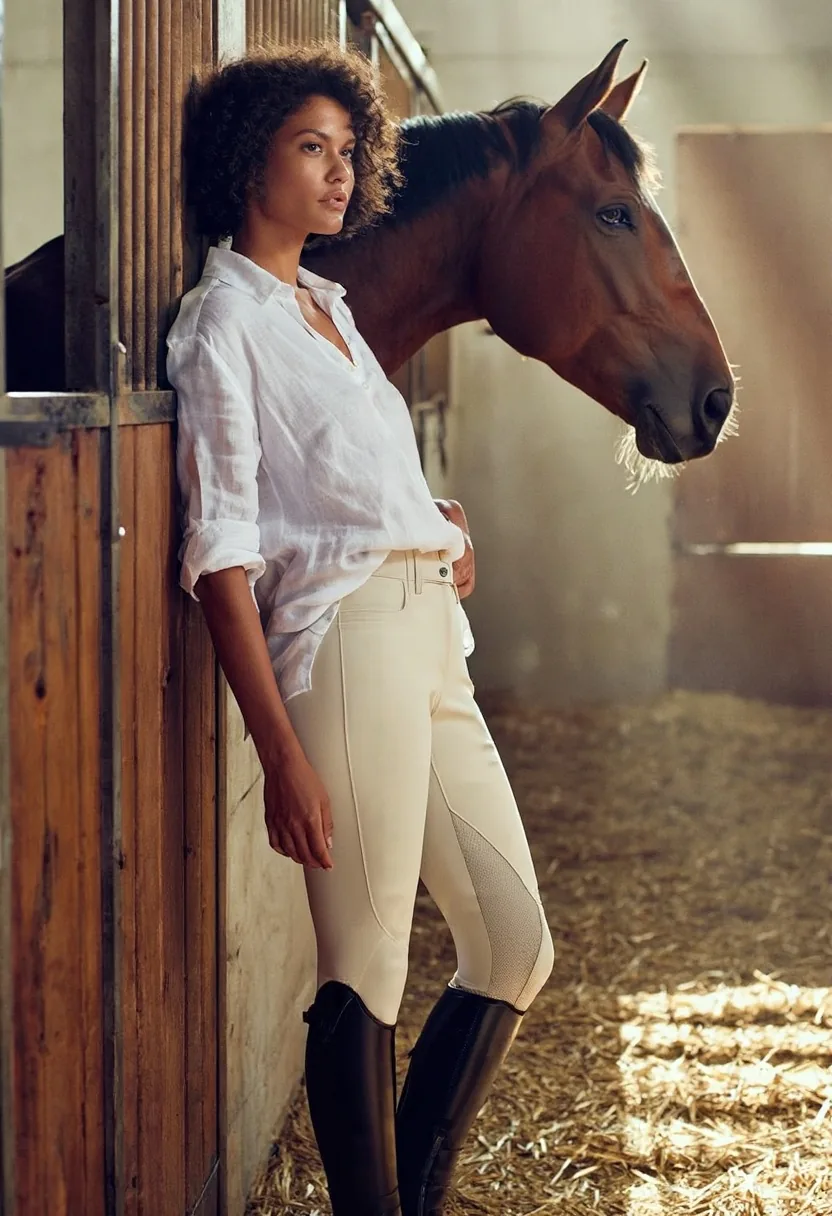 Output
stable-first-light No LoRA: one long sentence of subject, clothing, place and light, then the lens. The base model handles the photographic look on its own.
- 302
- 2:3
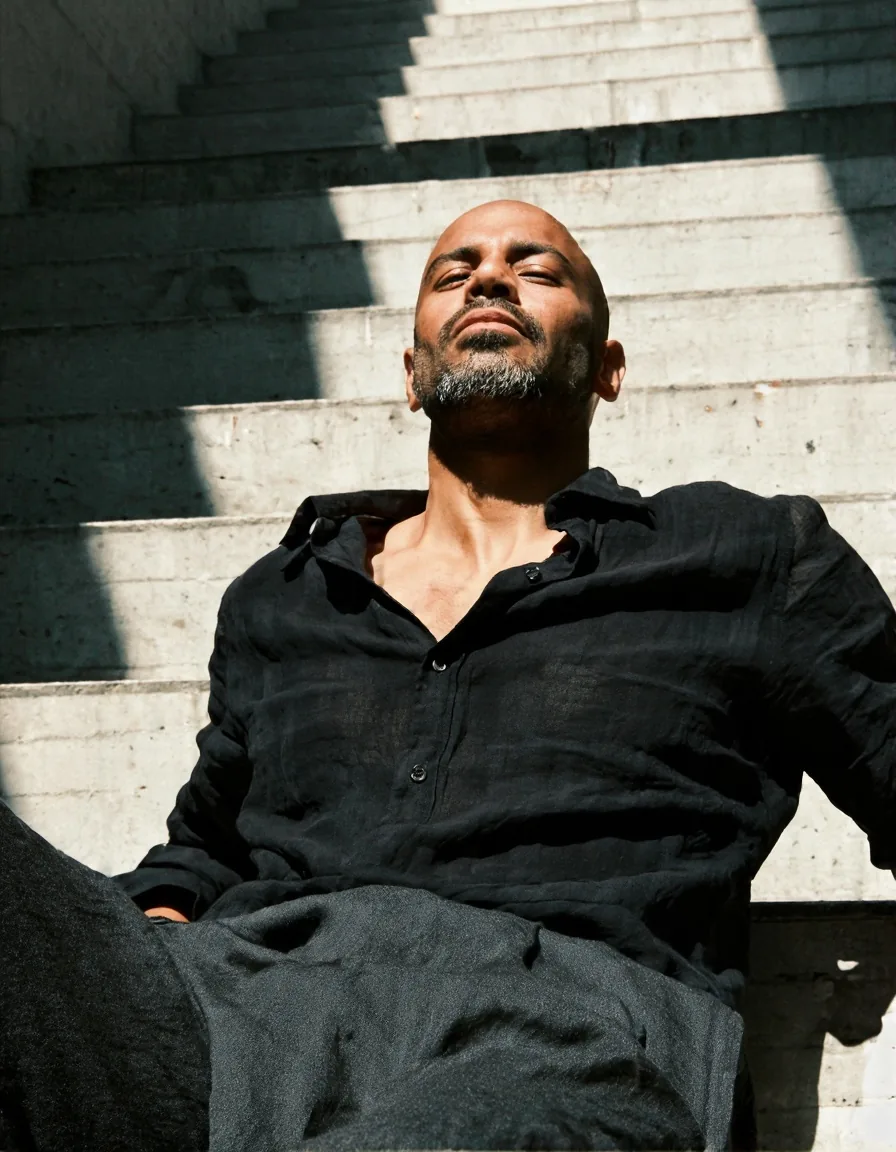 Output
brutalist-stair-noon No LoRA, 3:4. The hard light and the diagonal bands of shadow written into the prompt are what shape the frame.
- 311
- 3:4
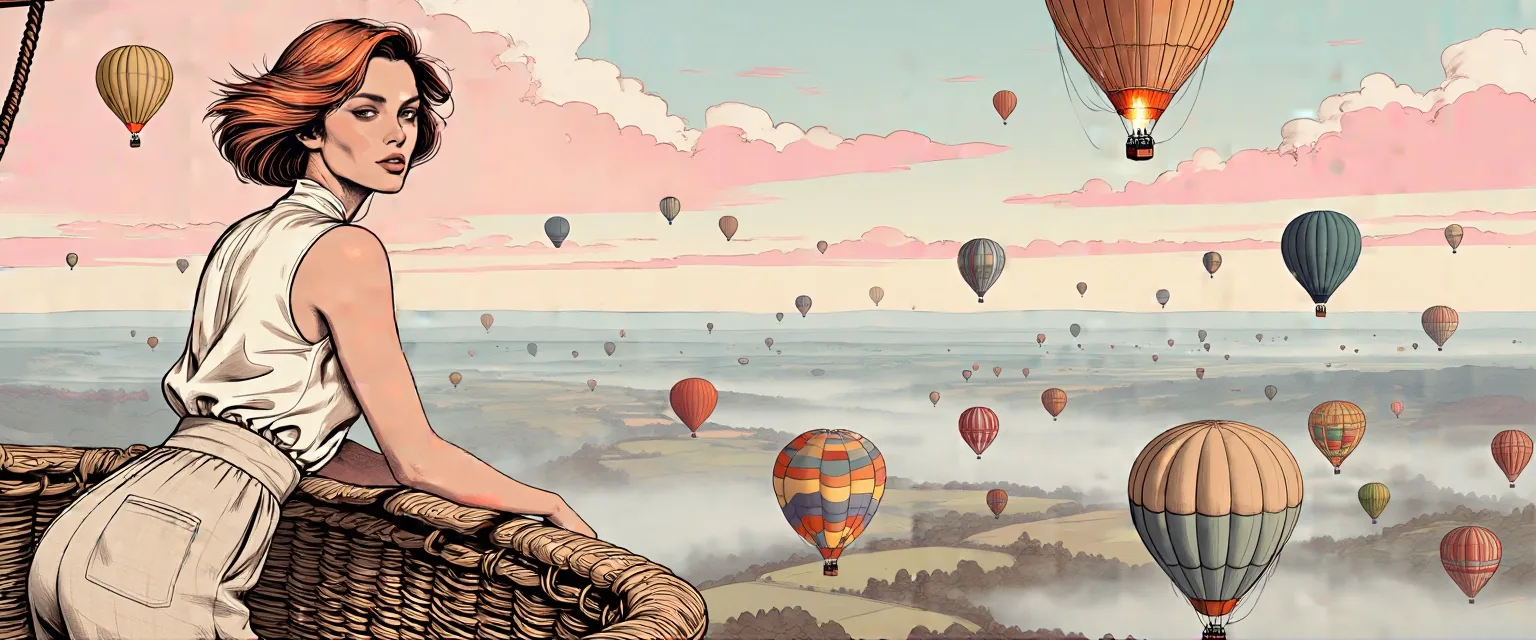 Output
balloon-dawn-21x9 The same LoRA at 0.8 at the widest shape, 21:9 (1536 x 640): a panorama with a figure in the foreground.
- 337
- 21:9
This example starts at $0.014 per image. The Playground updates the estimate when you change the settings.