Text-to-image on MOSS-Image, OpenMOSS's open 5-billion-parameter model that sets long, exact text into posters, covers and signs. Prompts up to 12,000 characters, an experimental JSON layout, 15 aspect ratios, three resolution tiers, and no content filter.

From $0.024/image

Workbench

Input

Text to image
634/12000
Put each piece of text in quotes and say where it goes. Up to 12,000 characters; English works well. A layout JSON (summary.caption plus items with yxyx bbox in centre-origin pixels) is accepted and marked experimental. at least 1 characters · at most 12000 characters
15 shapes from 1:3 to 3:1; 1:1 by default. At 1k, 4:3 is 1168 x 880 and 16:9 is 1360 x 768. The ratio changes the shape, not the price.
affects price
1k (about 1 megapixel, default), 1.5k or 2k. The tier sets the price; a widescreen image at 1.5k came back at 2048 x 1152.
Output format
JPEGPNGWebP
JPEG by default, or PNG or WebP. The format does not change the price.
Seed
Keeps images comparable while you change one sentence at a time. It does not promise identical pixels. No seed means a random one. no lower than 0 · no higher than 2147483647
Safety checkerOff

SpicyAPI does not run a safety checker on this model. Your prompt and media go to the model as written, and the model itself decides what comes back.

Checking your account before enabling submission and pricing.

Output

Ready for a new run
meridian-film-posterExample result

Missing the model you need?

Tell us what to add and where you would use it. Requests go to the people who decide what gets onboarded next.

TEXT-TO-IMAGE API

MOSS-Image API at a glance

MOSS-Image: Apache-2.0 text-to-image that spells out long, exact text on posters and covers, reads very long prompts to the end, and filters nothing.

Parameters
5B
OpenMOSS's single-stream diffusion transformer, released as open weights.
Prompt characters
12,000
A 13,000-character prompt was followed to its last sentence in our tests.
Aspect ratios
15
From 1:3 to 3:1, plus 16:9, 9:16, 21:9 and 9:21; 1:1 by default.
Top resolution
2k
1k, 1.5k and 2k tiers; a 9:16 image at 2k came back at 1536 x 2720.
Weights licence
Apache
Weights and inference code are released under Apache-2.0.
Content filter
None
No filter on prompts or results.

Results

What you can make with MOSS-Image

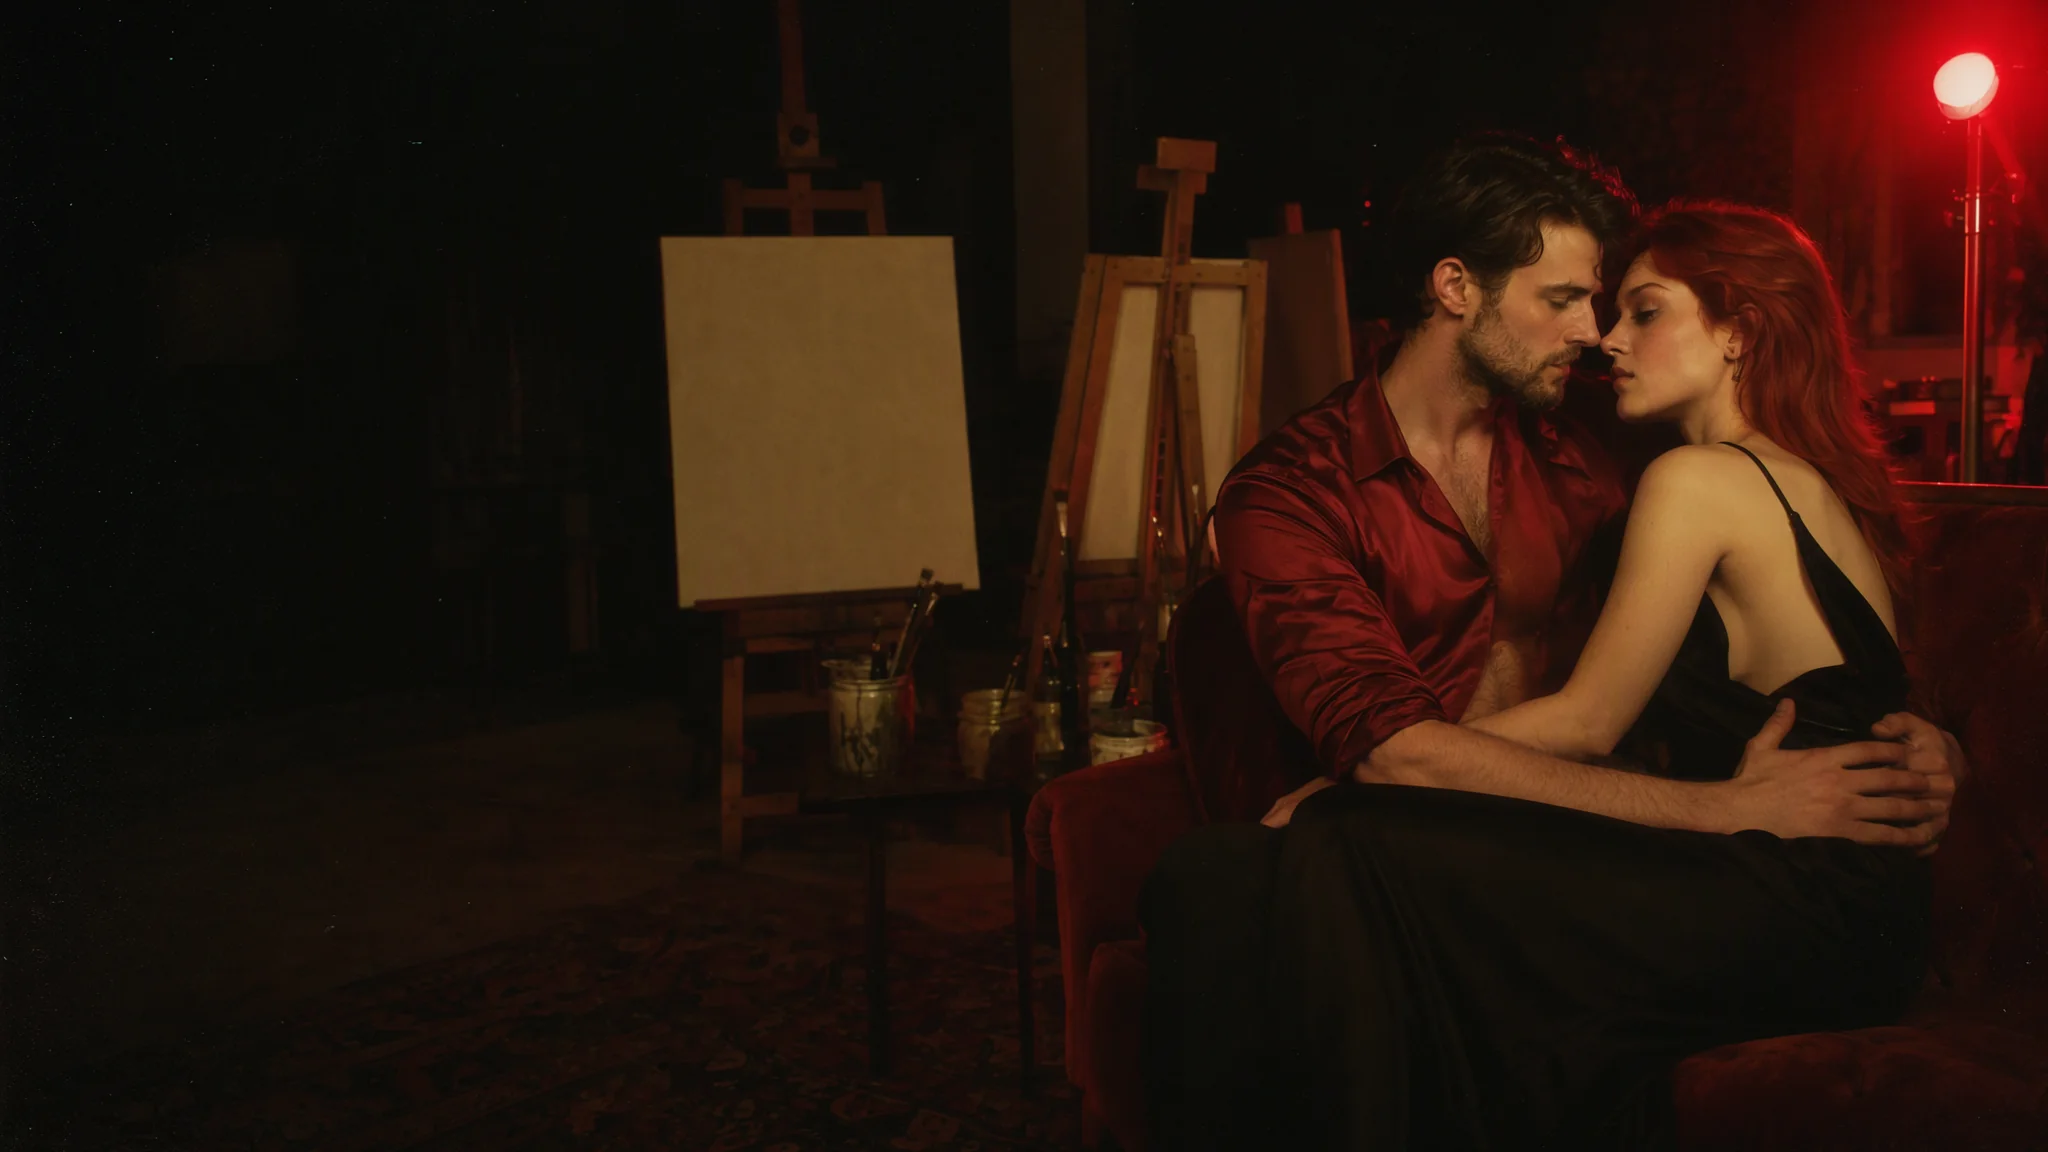
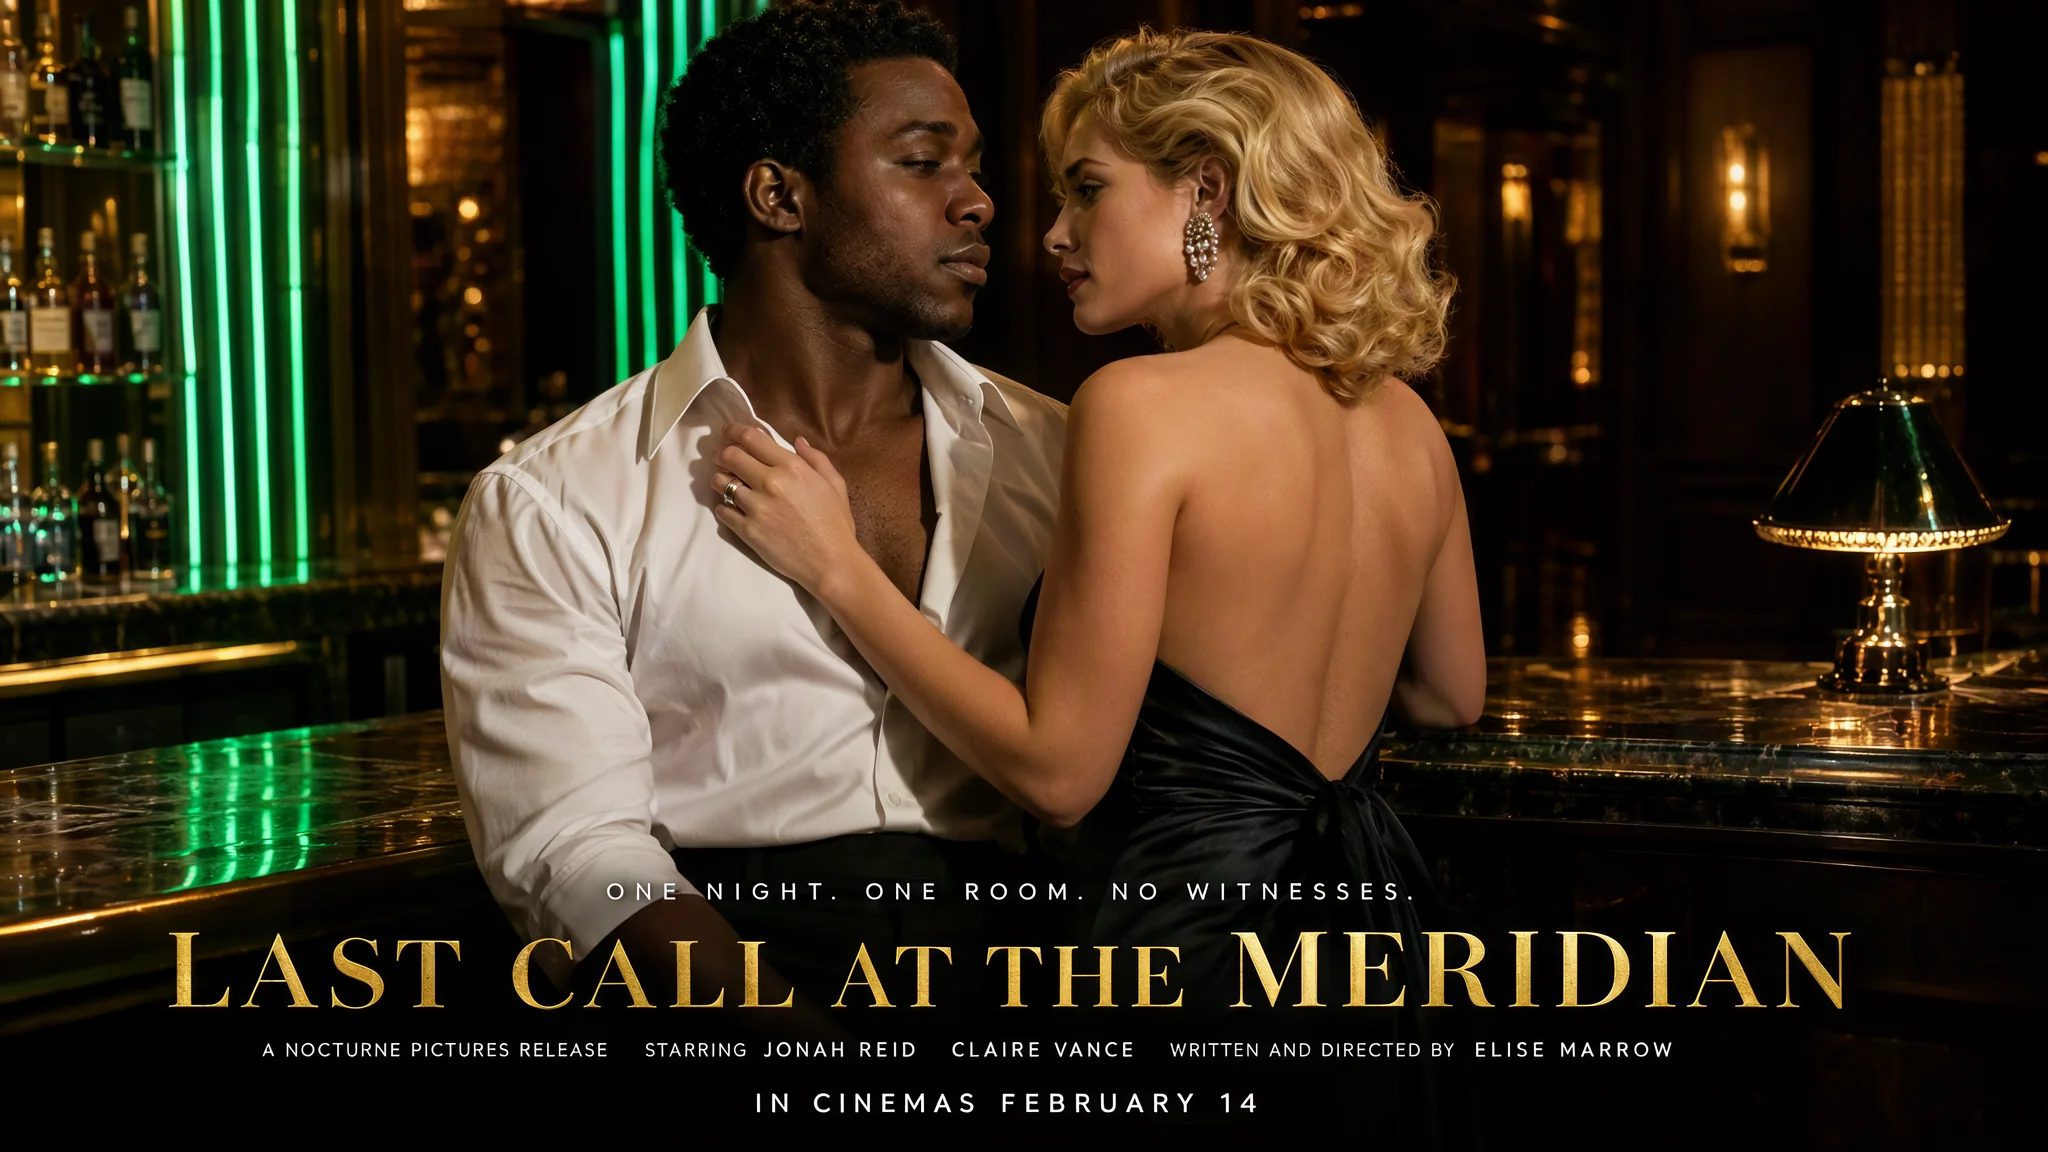
  • A film poster of a couple leaning toward each other at a dim art-deco hotel bar under green and gold neon, with the title LAST CALL AT THE MERIDIAN in gold capitals, a tagline above it and the cast and director names below

    Long text

    A whole poster's worth of words

    A title, a tagline, the cast and director names and a release date, all spelled correctly at 1.5k in 16:9. The prompt quotes every string and says where it sits.

    Long text, 16:9, 1.5k.

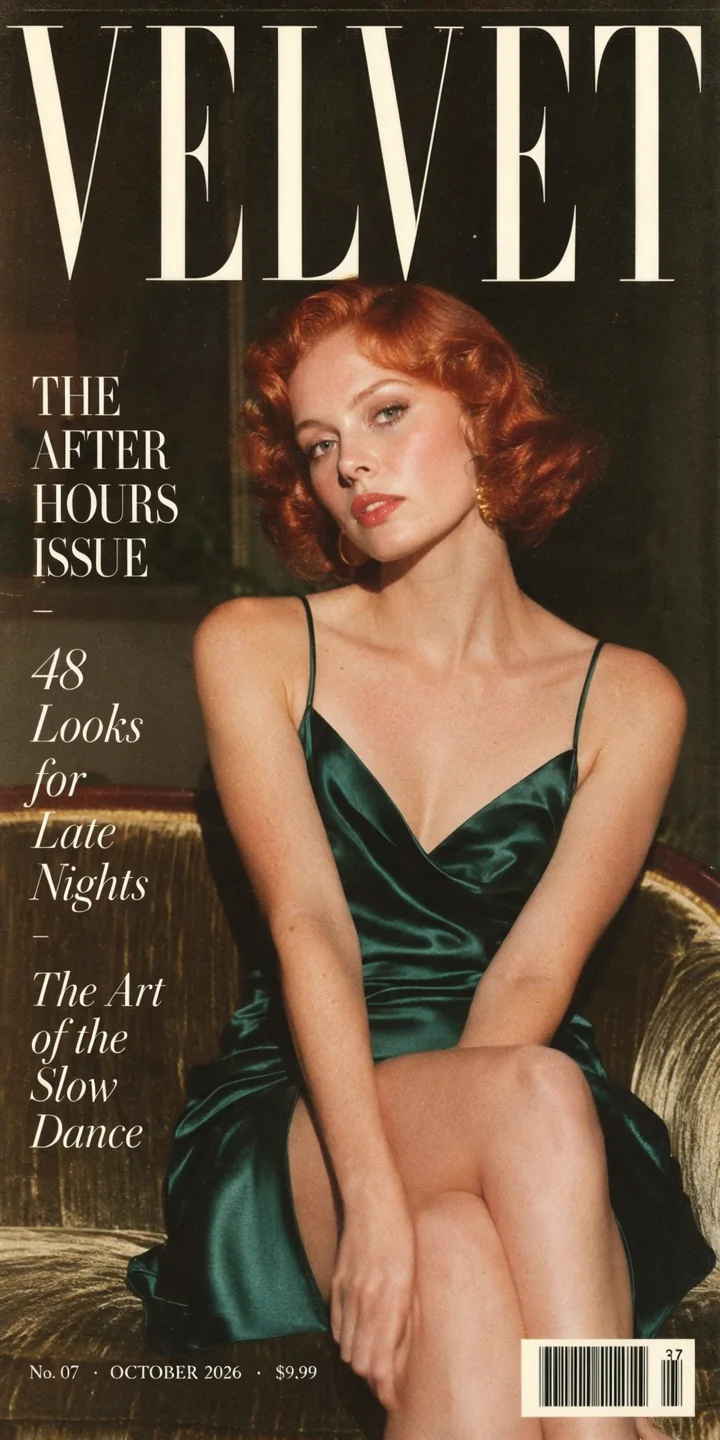
  • A vintage-style fashion magazine cover with the masthead VELVET, a red-haired woman in an emerald satin dress seated on a velvet chaise, three cover lines on the left and a price line with a barcode at the bottom

    Covers

    Masthead, cover lines, small print

    A tall 1:2 magazine cover with a masthead, three cover lines and a price line at the bottom, each one rendered as written.

    Cover lines and small print, 1:2, 1k.

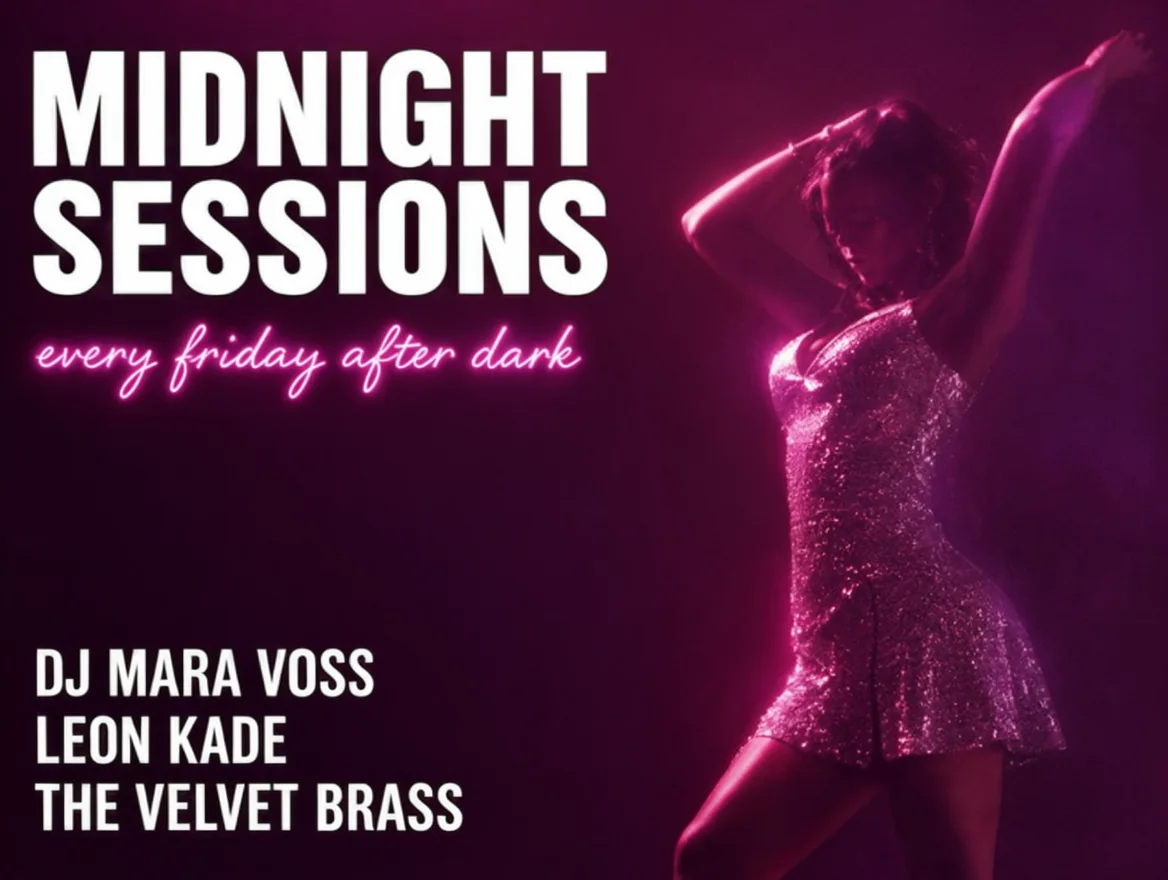
  • A nightclub flyer on a deep plum background with a pink neon glow: the title MIDNIGHT SESSIONS at top left, a script line, a three-name lineup at the bottom left and a woman in a silver sequined dress dancing on the right

    JSON layout

    Boxes for text and objects

    A club flyer made from a layout JSON: the title, a neon script subtitle, a lineup and a dancer, each placed in its own box and each landing where it was told.

    JSON layout prompt, 4:3, 1k.

Content test

Is MOSS-Image uncensored? What we tested

We ran each level on our live setup and checked every clip frame by frame. A pass means the content was actually on screen, not just that the request went through.

Content levels tested on MOSS-Image, by mode
LevelText to image
MildThe lightest prompts in the test
RendersTested Oct 21, 2026
ModerateWhere filtered models start to refuse
RendersTested Oct 21, 2026
StrongThe middle of the scale
RendersTested Oct 21, 2026
Very strongWhere most models start to hold back
RendersTested Oct 21, 2026
MaximumThe top of the scale
RendersTested Oct 21, 2026

Renders: on screen as written. Softened: generated, but milder than what was written. Refused: rejected. Not tested yet: we have not run that level on that mode.

How each mode behaves

All modes
Text is usually accurate, not always. In our tests a perfume ad came back right on one seed and with letters fused in the wordmark on another; try a new seed if that happens. English gives reliable results. The JSON layout is marked experimental by OpenMOSS.
All modes
Text to image only: there is no reference image input and no editing. There is no negative prompt, no guidance control and no step control, and each request returns one image. It is not a quick model: about 20 seconds at 1k and about a minute at 2k.
All modes
Every person you describe must be an adult. You are responsible for the lawfulness of what you generate and publish. Generated media is retained for 14 days and then deleted.

Use cases

What to build with the MOSS-Image API

  • Posters and film one-sheets

    Title, tagline, the cast and director names and a release date in one image, as in the 1.5k poster on this page.

  • Magazine covers and ads

    Masthead, cover lines, price line and a perfume wordmark rendered as part of the picture rather than added afterwards.

  • Signage and flyers

    Neon motel signs, club flyers and banners where the words are the point. The JSON layout is there when you want a box for each block.

  • Unfiltered stills

    Nothing is filtered, so even the strongest requests come back as written. For your own LoRAs, use MOSS-Image LoRA.

Prompts

MOSS-Image prompt examples you can copy

Paste one into the playground as it is, then change one thing at a time.

  • Text to image

    Club flyer from a JSON layout

    {"summary": {"meta": ["poster"], "canvas": "single", "caption": "A moody nightclub flyer: deep plum background with a pink neon glow, a dancer silhouette in a sequined dress on the right, bold white condensed type on the left."}, "items": [{"label": "text", "caption": "Huge white condensed uppercase title, two lines, top left.", "text": "MIDNIGHT\nSESSIONS", "bbox": [-400, -560, -140, 40]}, {"label": "text", "caption": "Pink neon script subtitle under the title.", "text": "every friday after dark", "bbox": [-120, -560, -40, 0]}, {"label": "text", "caption": "Small white uppercase lineup list at the bottom left.", "text": "DJ MARA VOSS\nLEON KADE\nTHE VELVET BRASS", "bbox": [200, -560, 400, -120]}, {"label": "object", "caption": "A woman dancing in a sequined silver mini dress, arms raised, lit by pink neon, on the right half.", "bbox": [-420, 80, 440, 560]}], "bbox_coord_space": "abs_centralized", "bbox_format": "yxyx"}

    Why it works. The prompt is the layout JSON itself. Each text block and the dancer get a bbox in yxyx pixels from the canvas centre, worked out for 1168 x 880. Title, subtitle, lineup and figure all landed in their boxes.

    Try this prompt
  • Text to image

    Perfume ad with a wordmark

    A luxury fragrance advertisement photograph. A Mediterranean man in his thirties with dark stubble and wet slicked-back hair, a black silk shirt open to the sternum, holds a square smoked-glass perfume bottle against his collarbone, looking into the lens. Deep black background, one hard rim light from behind, drops of water on his skin. Large thin white serif wordmark at the top: "NOIR No. 9". Under it in small spaced capitals: "EAU DE PARFUM". At the bottom, an italic line: "Wear the night."

    Why it works. Each line of text is quoted and given a place and a type style, and the light is named once. It came out right on this seed; on another seed the letters of the wordmark fused, so keep a spare seed.

    Try this prompt
  • Text to image

    Neon motel sign at dusk

    Wide cinematic photograph of a retro desert motel at dusk. A red neon sign on a tall pole reads "MOTEL PARADISO" with a smaller flickering line "VACANCY". A woman in a red one-piece swimsuit and oversized sunglasses lounges on a white chaise by a glowing turquoise pool, a man in an open Hawaiian shirt carries two cocktails toward her. Pink and violet sky, long shadows, 35mm film look.

    Why it works. The sign text is quoted, with a smaller second line. 21:9 gives the sign, the pool and the sky room to breathe.

    Try this prompt

Pricing

MOSS-Image API pricing

One image starts at $0.024 at 1K and $0.096 at 2K.

The playground shows the exact price for your settings before you run. Failed or timed-out tasks are usually not charged. Some models charge for content refusals as stated on their model page; check those billing terms before submitting.

See every price tier

Get started

How to use the MOSS-Image API in three steps

  1. Step 1

    Put the words in quotes

    Write each piece of text exactly as it should appear, in quotation marks, and say where it goes and how it looks: masthead, cover lines, small print. Use new lines to control where a line breaks.

  2. Step 2

    Go long when you need to

    The prompt box takes up to 12,000 characters. A detail mentioned only in the last sentence of a 13,000-character prompt still showed up in our test, so you can keep a full brief in one request.

  3. Step 3

    Try a JSON layout

    For a poster where position matters, pass the layout JSON itself as the prompt: a summary.caption for the whole picture and an items list, each with a label, a caption, optional text and a bbox. Coordinates are yxyx pixels measured from the centre of the canvas. OpenMOSS marks this as experimental.

Parameter reference and code samples are in the API and Readme tabs at the top of this page.

Why SpicyAPI

Why run MOSS-Image on SpicyAPI

  • No filter from us

    We add no content filter of our own. What the model renders is what you get back.

  • Tested, not guessed

    Content labels come from real generations we ran and checked, with the test date on the page.

  • Pay per result, in dollars

    No subscription and no credits. Failed or timed-out tasks are usually not charged. Some models charge for content refusals as stated on their model page; check those billing terms before submitting.

  • One key for every model

    One API key and balance cover image, video, audio and chat models, so you can explore more models from the same account.

FAQ

MOSS-Image API FAQ

About MOSS-Image

MOSS-Image is the open model to reach for when the words in the picture matter: posters, covers, ads and signs with long, exact text, prompts that run to thousands of characters, and an experimental JSON layout for placing it. Three resolution tiers, one price per image, and nothing is filtered.

All MOSS-Image models2

Related models and next tasks