A user tells Rowan, a fictional adult companion character, "show me the observatory tonight". The chat model can answer in character, but your application has to make the picture, keep the scene consistent and attach a real asset once one exists. Keep chat responsive while image and video jobs run separately.
Give the user control over two purchases:
- Approve the still: show a free scene card, quote the image and create it only after the user accepts the price.
- Approve the clip: show the finished still, quote its animation and create the video only after the user accepts that image and price.
Persist each request before submission, use a separate key for each stage, and deliver from your own stored copy. A tool call starts the scene card; it never authorizes a purchase or announces a nonexistent attachment.
For a concrete budget, a 1k Qwen edit ($0.036) plus a five-second 720p Seedance 2.5 clip comes to $1.4225, before extra-reference-image charges, chat tokens and retries. Ask for a quote before showing any price to a user.
The whole flow, in order:
1. Chat model calls request_scene_image(scene, details)
2. Server validates owner and scene -> free draft card -> tool result back to the chat
3. Gate 1: user approves the still's price -> Qwen edit task (own idempotency key)
4. Callback or poll -> still ready -> copy it to your own storage
5. Gate 2: user accepts the still -> quote the clip -> user approves its price
6. Seedance task (own key) -> callback or poll -> ready_for_review
7. Review the whole clip -> copy to your storage -> delivered
Turn a chat request into a picture the app can actually make
A user might write, “Send another photo in the green coat,” while a navy-coat video is already generating. The chat reply and the media request should not share one mutable description. The app needs to know which fictional adult, which coat, which setting and whether the user wants a still or a clip. Otherwise “another” can accidentally create a new face, reuse an outdated scene or buy a video when the user requested a photo.
Keep the permanent character data small: the approved portrait, adulthood, stable appearance notes and the user's chosen character. Keep the current scene separate: coat, room, camera view and requested action. The conversation can suggest a scene, but your application resolves the stored character and approved source assets. Do not let the chat model invent a reference URL, task ID or claim that a picture exists.
For the observatory example, turn the request into an explicit scene description before quoting: Rowan, the approved portrait, navy coat, observatory balcony, medium shot, one still. For a later “make it move” request, use the accepted observatory still and a small head turn. Do not send the whole conversation to the image model; unrelated descriptions of other characters or previous outfits can conflict with the current request.
The interface can show a compact scene summary while the image generates. If a user changes green to navy, make it a new revision and label the earlier pending result accordingly. A finished old revision can remain in their private history, but should not silently appear as the answer to the latest request.
For an NSFW companion product, verify image and video suitability separately. An image task's adult-content acceptance does not establish that the next video model accepts the same scene. Check the selected model page for each stage, and present an unavailable task honestly rather than promising an adult clip the selected model does not support.
Try it in the Playground first
Open the Qwen Image 2.1 edit Playground. Under Images choose Add a file and upload the approved character portrait, describe the new scene in Prompt (the prompt below works), set Resolution to 1k and Aspect ratio to 16:9, press Run model and judge the still. Approve that composition, then open the Seedance 2.5 image-to-video Playground: add the still as Input image, describe the motion in Prompt, and press Run model again. Closing frame is optional.
Let the chat request media with a tool call
Give the chat model a request_scene_image tool that asks your application to prepare a scene card. Use the signed-in user and approved character portrait from your application, not IDs invented in the chat response.
- The chat model: describes the scene and asks whether the user wants it made.
- Your application: checks character ownership, shows the price and waits for approval.
- The media task: creates the image only after approval; animation is a separate purchase.
Grok 4.6 chat supports tool calls in the OpenAI format. The API keeps no conversation memory, so resend the character card and fiction-writing context with every request; the chat recipes show the tool-message format.
{
  "type": "function",
  "function": {
    "name": "request_scene_image",
    "description": "Ask the app to prepare a picture of the character. Call only when the user asks to see something. The app shows a free scene card first; nothing is made or charged until the user approves a quoted price.",
    "parameters": {
      "type": "object",
      "properties": {
        "scene": {"type": "string", "enum": ["observatory-balcony", "kitchen-morning", "rooftop-dusk"]},
        "details": {"type": "string", "description": "Clothing, props and mood the user asked for, in one sentence."}
      },
      "required": ["scene"]
    }
  }
}
Answer the call with a tool message saying a draft card is waiting for approval, so the model writes an honest line ("Here is the scene card, want me to make it?") instead of claiming a delivery.
Keep the character and the scene as separate records
Keep the approved portrait apart from the requested scene: a navy coat, an observatory balcony and a small turn toward a telescope. The portrait anchors the character; the accepted scene image becomes the video's opening frame. Do not replace the character portrait with every new scene.
Persist one record per request before you submit it (these are your application's fields, not an API payload):
{
  "mediaRequestId": "scene-104-r1",
  "ownerId": "application-user-id",
  "sceneRevision": 1,
  "referenceAssetId": "approved-rowan-portrait",
  "approvedStillAssetId": null,
  "model": "alibaba/qwen-image-2.1/edit",
  "inputSnapshot": {},
  "idempotencyKey": "<uuid generated for this request>",
  "taskId": null,
  "state": "draft",
  "deliveredAssetId": null
}
If the user changes the coat to green, create revision 2 with a new key; never edit the blue-coat request while it runs.
Store the approved still yourself. A task's result link lasts about 20 minutes and the generated file about 14 days, so copy the accepted still into your own storage and give Seedance a stable public HTTPS URL that returns the image file itself (a share-page link fails). Passing the Qwen result link straight to the video stage works only until it expires. Reuse the stored still for motion revisions; changing the portrait and movement together makes it harder to correct either.
Set image and video controls separately
The Qwen Image 2.1 edit route accepts a prompt and one to ten image_urls. Extra reference images increase the 1k price; 2k costs $0.048 with one to ten reference images. For the first scene use one approved portrait, 1k, 16:9 PNG and prompt expansion off.
Use the supplied portrait as the identity reference for the same fictional adult Rowan. Create a medium shot on an observatory balcony, wearing a navy coat. Keep both hands relaxed and visible. A telescope rests on its tripod beside Rowan. Leave open space on the right for a small head turn. Warm doorway light, natural night background, no text or extra people.
Compare the face and outfit with the approved portrait before offering the still to the user. At gate 2, the user accepts that still and the clip price before animation. If the telescope floats or the right side has no room for movement, fix the image stage; the video cannot repair a bad first frame.
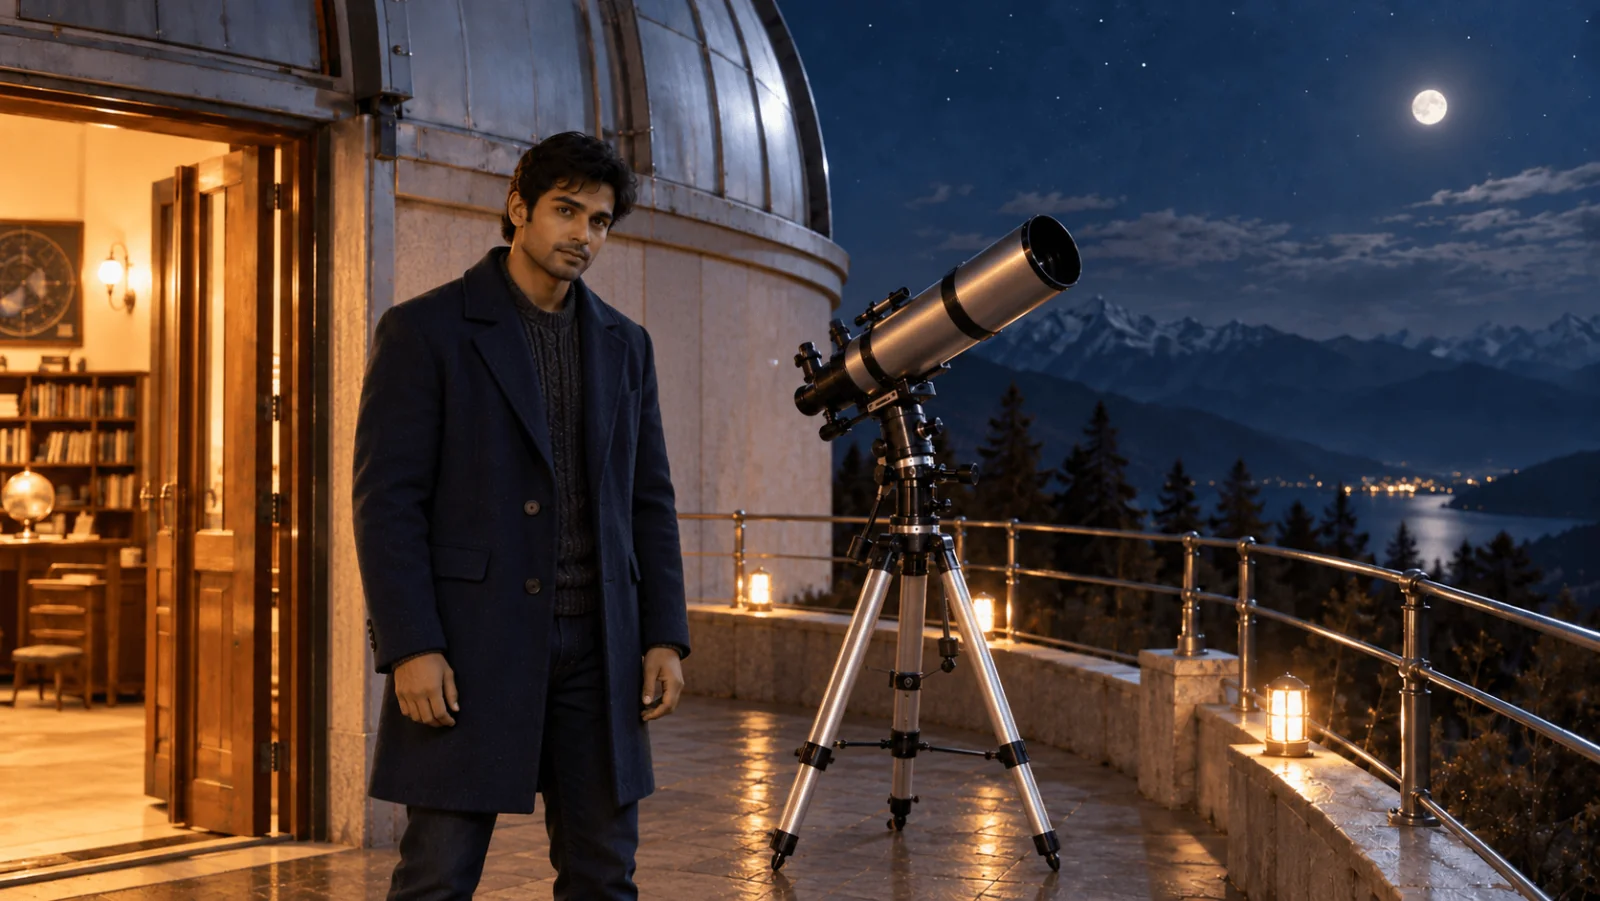
Illustration of a proposed first frame: the character has space for a small turn, and the telescope is physically supported. This is not a Qwen output or a generation test.
The Seedance 2.5 image-to-video route takes image_url, 4 to 30 seconds, 480p, 720p or 1080p, an audio toggle and an optional seed. aspect_ratio accepts only adaptive, so the clip follows the still's shape; crop the still to your delivery format first. The reference-to-video route has a different contract, so do not mix its fields in.
Quote at the decision point
Qwen edits list at $0.036 for 1k, $0.048 for 2k and $0.072 for 1.5k with one reference image included. Additional reference images increase the 1k and 1.5k prices. Seedance is $0.1234 per second at 480p, $0.2773 at 720p and $0.6823 at 1080p, with audio on or off at the same rate.
Reuse the accepted still when retrying motion.
| Plan | Cost |
|---|---|
| 1k still only | $0.036 |
| Still + 5 s clip at 480p | $0.653 |
| Still + 5 s clip at 720p | $1.4225 |
| Still + 5 s clip at 1080p | $3.4475 |
| Still + two 720p clip attempts | $2.809 |
These include one reference in the 1k edit and exclude extra-reference-image charges, chat tokens and any extra still edits.
Show the still price before generation and the clip price after the user accepts the still, not on every chat turn. A quote is free, reserves nothing and stays valid for five minutes for that account, API key, model and input; change the duration, resolution or references and you need a new one. A submitted task holds its estimated cost immediately, and that hold is the most it can charge. Reusing the approved image keeps a motion revision to the video charge.
A video-stage client that survives a lost response
Install spicyapi with python -m pip install spicyapi, set SPICY_API_KEY and APPROVED_STILL_URL, then run this after approving the still. Keep the saved run file to resume the same attempt. For another creative take, use a new run name.
import json
import os
import time
import uuid
from pathlib import Path
from spicyapi import SpicyClient, output_assets

client = SpicyClient()

def run(model, inputs, name):
    path = Path(name + ".json")
    request = {"model": model, "input": inputs}
    saved = json.loads(path.read_text()) if path.exists() else {"request": request, "key": str(uuid.uuid4())}
    if saved["request"] != request:
        raise ValueError("Changed input needs a new run name; preserve the old attempt.")
    def save():
        temporary = path.with_suffix(".tmp")
        temporary.write_text(json.dumps(saved))
        temporary.chmod(0o600)
        temporary.replace(path)
    if not saved.get("taskId"):
        if time.time() - saved.get("sentAt", time.time()) >= 23 * 3600:
            raise RuntimeError("Reconcile the saved attempt before submitting again.")
        if "quote" not in saved:
            saved["quote"] = client.quote_task(model=model, input_data=inputs)
            if input(f"Maximum ${saved['quote']['maxCharge']}. Create? [y/N] ") != "y":
                raise SystemExit("Stopped without creating this task.")
        saved.setdefault("sentAt", time.time())
        save()
        quote = saved["quote"]
        task = client.create_task(model=model, input_data=inputs,
            idempotency_key=saved["key"], quote_id=quote["quoteId"], expected_cost=quote["estimatedCost"])
        saved["taskId"] = task["taskId"]
        save()
    print("Task:", saved["taskId"])
    for _ in range(360):
        task = client.get_task(saved["taskId"])
        if task["state"] in {"failed", "expired", "canceled"}:
            raise RuntimeError(str(task.get("errorMessage", task["state"])))
        if task["state"] == "succeeded":
            assets = output_assets(task)
            if assets and assets[0].get("unavailable"):
                raise RuntimeError("Output unavailable; keep the task ID for reconciliation.")
            if assets and assets[0].get("url") and not assets[0].get("pending"):
                return assets[0]
        time.sleep(5)
    raise TimeoutError("Rerun the same saved attempt to resume; no new task is needed.")

asset = run("bytedance/seedance-2.5/image-to-video", {
    "image_url": os.environ["APPROVED_STILL_URL"],
    "prompt": "The adult character slowly turns toward the telescope. Hold the camera steady. Keep the navy coat and balcony unchanged.",
    "duration_seconds": 5, "resolution": "720p", "aspect_ratio": "adaptive", "generate_audio": True,
}, "companion-video")
print(asset["url"])
The Python SDK and task documentation cover production integration.
One update function for polling and callbacks
Use one application handler for both a polled result and a verified completion event. It should attach the asset once, keep it private, and notify the chat only when it is ready for review. A duplicate event must not create another gallery entry.
For a live companion app, send completion to a verified webhook and keep a periodic status sweep for callbacks that never arrive. Callback bodies carry the prompt and signed result links, so treat them as private; the task documentation covers setup. Webhooks with a reconciliation sweep suit production; polling is enough for a prototype. Use bounded dispatch when many users request media together.
Delivery states, failures and cancel
Use draft, submitted, generating, ready_for_review, delivered, failed and rejected. API succeeded means result handling starts; it does not mean the user sees it. Review the whole clip for face drift, moving props and unrequested cuts before delivered.
| API outcome | What to show | Charge |
|---|---|---|
succeeded, asset ready | review, then deliver | read settled and cost |
succeeded, asset pending | "still preparing", poll again in seconds | not final yet |
succeeded, asset unavailable | restore an already saved copy, or offer a deliberate new generation | read cost |
failed or expired | plain failure and a retry button | hold normally released; some content refusals are charged when the model page says so |
An expired quote needs a fresh quote and approval; recover an already accepted request with its original key. An accepted task cannot be cancelled. If the user says "never mind", hide the pending attachment and let the job finish; do not promise that closing the chat releases the charge. A retry is a new request with its own quote.
Keep private companion media private
Check that a scene belongs to the signed-in user before serving it. Copy accepted media to storage with your own access rules; temporary result links should not become public gallery addresses.
For deletion, handle the platform copy and your own copy separately. Shorten how long the platform keeps a result with the per-task retention setting, and when a user deletes a scene or account, destroy each finished task's stored content (the billing record stays). A retention of 0 can remove the result before your worker copies it. Delete your own copy and revoke its delivery access separately; details are in the retention documentation. Use retention controls and a durable storage pipeline appropriate to the product.
Test four failures with fixtures
Simulate a double click, a lost acceptance response, a duplicate success event and an unavailable asset. You should get one logical request, recovery with the original key, one gallery attachment and an honest unavailable state. None needs a paid generation. Consistency of the face across stills and clips is a visual question, so inspect every output. Do not let a chat message saying “your video is ready” override the real task or asset state. The observatory illustration is an editorial scene, not a Qwen or Seedance output.
Let an Agent handle the call
Use an Agent when you want it to prepare the inputs and return the result while you approve the price and creative choices.
- CLI: with an
input.jsonsuch as{"image_urls": ["<approved portrait URL>"], "prompt": "<the scene prompt above>", "resolution": "1k", "aspect_ratio": "16:9", "output_format": "png", "enable_prompt_expansion": false}, runnpx @spicyapi/cli tasks create --model alibaba/qwen-image-2.1/edit --input-file input.json --wait. The CLI confirms the price; keep the returned task ID for recovery. - MCP: ask your assistant to use
spicyapi_task_createforalibaba/qwen-image-2.1/edit, thenspicyapi_task_wait. The MCP server requests price confirmation before creation. - Skill: install with
npx skills add spicyapi-ai/spicy-skill, then ask$spicyapito run the same workflow and stop for your approval. The Skill uses a configured CLI or MCP connection.