무검열 — 이 모델은 콘텐츠 필터를 걸지 않는다고 스스로 밝히고 있습니다. SpicyAPI는 여기에 플랫폼 검사를 더 얹지 않고 그대로 전달하고, 법률과 동의에 관한 책임은 고객에게 있습니다.
MiniMax H3 X Review: Uncensored Video With Sound, Lower Price
Pick MiniMax H3 X for low-cost uncensored video with spoken lines; start from an image or references when the scene is a single person or male subjects.
MiniMax H3 X is a tuned build of MiniMax H3 that runs only on SpicyAPI. It is not an official MiniMax release. The trainers describe the tuning as a round of reinforcement-learning post-training aimed at prompt following, picture quality and stable bodies and objects; we have not run a side-by-side quality comparison against standard H3, so we report what it did on our own clips. It starts at $0.022 a second at 480p, with sound on every clip.
테스트 실행 결과를 그대로 옮겼습니다. 프롬프트를 복사하거나 플레이그라운드에서 열어 직접 사용해 보세요.
텍스트→영상
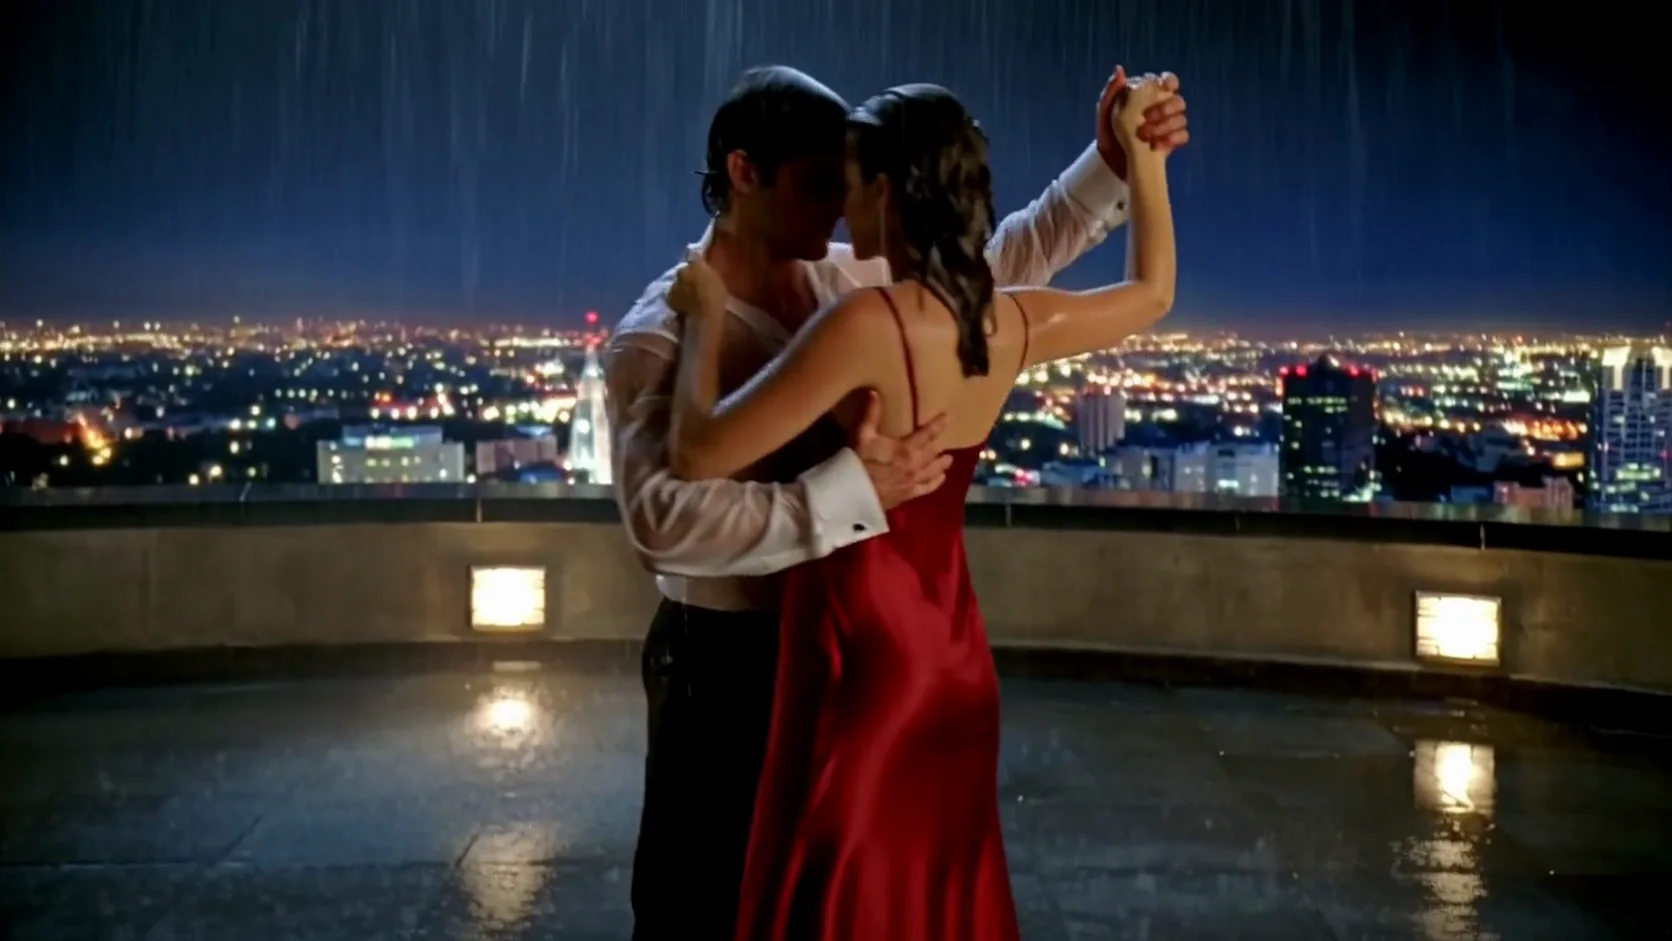
Night, a rain-soaked rooftop above a glittering city. A couple dances a slow tango in the downpour: she wears a clinging crimson satin slip dress, he wears a soaked white shirt open at the collar. He dips her low, she pulls him back up by the collar, their faces an inch apart, and she says, "Not yet." Rain hissing on the tiles, distant traffic, a bandoneon playing a slow tango. Cinematic, shallow depth of field, wet reflections, warm city glow against blue night.
Three shots in a dim, art deco hotel at night. From 0 to 4 seconds: wide shot, a woman in a black backless satin dress walks away from the camera down a long carpeted corridor, heels clicking. At 4 seconds the shot cuts to a close-up of her hand sliding a brass room key into a door lock, the latch clicks. At 8 seconds the shot cuts to a medium shot inside the room: she slips off her heels, glances back over her shoulder at the camera and smiles. Same woman in all three shots. Soft jazz from another room, cinematic, warm amber light. Full-frame 16:9 widescreen picture filling the whole frame, no black bars.
She sets the glass down slowly, leans across the bar toward the camera, rests her chin on her hand and whispers, "Last call." A record crackles on the turntable, low soul music, ice clinking. The camera pushes in slowly. Warm amber light, shallow depth of field.
The man from Image 1 performs the same moves as the dancer in Video 1, in a sunlit concrete loft: a smooth spin, a shoulder roll, then he points at the camera and laughs. Keep his face and white tank top from Image 1, copy only the motion from Video 1. Upbeat funk music with a clear beat.
The woman from Image 1, in her black slip dress, tries on the trench coat from Image 2 in the fitting room from Image 3. She belts it, turns to the gold mirror, then lets the coat slide off one shoulder and glances back at the camera over that shoulder. Soft spotlight, rustle of wool, quiet lounge music. Cinematic, shallow depth of field.
Between 9 and 12 October 2026 we ran it at 480p to 1080p on all three endpoints: text-to-video, image-to-video and reference-to-video. Not one request was refused. Mild and Moderate came back as written everywhere. Image-to-video and reference-to-video also delivered Strong, Very strong and Maximum; at Very strong the clip stays implied, with the most direct moments kept out of frame. Text-to-video is the soft spot: single-person scenes at Strong and requests with male subjects were toned down in every run.
Pick it for a cheap NSFW video that still talks, cuts between shots on cue and holds two faces across a scene. Start from a still or from references whenever the scene is one person or involves male subjects. Pick base MiniMax H3 when you need the full grid from a written prompt: on the same prompts it delivered 21 of 21.
Content: no refusals across more than 250 clips from this build and its Turbo sibling on 9 to 12 Oct 2026. Image and reference endpoints delivered every level; text-to-video toned down single-person Strong scenes and male-subject requests. Details under How far it goes.
Price: from $0.022 per second at 480p; 720p and 1080p cost more. The model page shows live prices.
Limits: 2 to 15 seconds per clip, 480p, 720p (default) or 1080p, 24 fps, stereo sound that cannot be switched off. Prompts run up to 7,000 characters.
Inputs: text-to-video takes six aspect ratios; image-to-video takes an opening frame and an optional closing frame and keeps the frame's shape; reference-to-video takes up to 9 images, 2 video clips (15 seconds in total) and 3 voice clips.
Speed: a 5-second clip took about 50 to 65 seconds at 480p and 75 to 130 seconds at 720p; 1080p took about three minutes.
좋았던 점과 아쉬웠던 점
좋았던 점
Spoken lines come out word for word. We put a quoted line in the prompt and ran speech-to-text on the soundtrack; it matched in all three checks, with lip movement to match, including a run that used a reference voice clip.
Timed shots land where you put them. A 15-second prompt with three timed shots cut at about 5 and 10 seconds, with the same two people in every shot.
Two faces survive a scene. Reference-to-video held both faces and both outfits when we sent two portraits, and the model-page example keeps a face, a coat and a room from three separate photos.
Stronger input is not blocked. Opening frames, closing frames, reference images and reference clips that already showed the higher levels were all accepted, and the clips came back as written.
Prompt expansion is optional. It is off by default and made no visible difference in our reruns, so what you write is what you get.
아쉬웠던 점
Text-to-video tones down more than the other two. Single-person scenes at Strong were toned down in 2 of 2 runs, male-subject requests in every run, and close-ups and scenes with more than two people were softened too. A scene with two men stayed implied.
Very strong stays implied. On every endpoint the most direct moments are kept out of frame. Reference-to-video delivered it once and stopped short once.
1080p is a bigger frame, not a sharper one. The file is 1920 x 1088 but encoded at about 3.3 Mbps against about 10 Mbps at 720p, and in our crops it looked no crisper. Use 720p unless you need the pixels.
No aspect-ratio control on image-to-video. The clip keeps the shape of your opening frame. Opening and closing frames cannot be mixed with references in one request.
Slower than the Turbo build. The same 5-second clip takes roughly twice as long here as on H3 X Turbo.
A tuned build is not a new model. Its content limits are slightly stricter than base H3, and we have not measured the quality gain the trainers claim.
What the clips look like
The gallery holds published, safe-for-work examples from the MiniMax H3 X model page. Our content-test clips are not shown; we report those results in words.
A line in the rain. A couple dances a slow tango on a rooftop, he dips her low, and in a close-up she says "Not yet." The prompt names rain, traffic and a bandoneon; the line is heard over slow, melancholic music.
Three shots in 12 seconds. One prompt lists a wide corridor walk, a hand turning a key at 4 seconds and a medium shot in the room at 8. The cuts came at about 3.9 and 8.3 seconds with the same woman throughout.
A frame that whispers. A woman behind a walnut bar goes in as the opening frame, and the prompt only says what follows: she sets her glass down, leans in and says "Last call." Quiet soul music sits under the line.
Copying a move. One portrait and one short dance clip go in as Image 1 and Video 1. "Copy only the motion from Video 1" and "keep his face and white tank top from Image 1" split the two jobs, and the clip repeats the spin and the shoulder roll.
Three references, one scene. A portrait, a coat photo and an empty fitting room go in as Images 1, 2 and 3, and face, outfit, coat and room all match.
Prompts that worked
Write dialogue in double quotes, say who speaks, and give each shot a start time. For image-to-video, describe only what happens next. For reference-to-video, name references by type and position: "the woman from Image 1", "the motion of Video 1".
1. Timed shots, one woman (text-to-video, 16:9, 12 s). The prompt behind the corridor clip.
text
Three shots in a dim, art deco hotel at night. From 0 to 4 seconds: wide shot, a woman in a black backless satin dress walks away from the camera down a long carpeted corridor, heels clicking. At 4 seconds the shot cuts to a close-up of her hand sliding a brass room key into a door lock, the latch clicks. At 8 seconds the shot cuts to a medium shot inside the room: she slips off her heels, glances back over her shoulder at the camera and smiles. Same woman in all three shots. Soft jazz from another room, cinematic, warm amber light. Full-frame 16:9 widescreen picture filling the whole frame, no black bars.
2. A frame, then a spoken line (image-to-video, 6 s). Send your own opening frame; the prompt starts after it.
text
She sets the glass down slowly, leans across the bar toward the camera, rests her chin on her hand and whispers, "Last call." A record crackles on the turntable, low soul music, ice clinking. The camera pushes in slowly. Warm amber light, shallow depth of field.
3. Move transfer (reference-to-video, 16:9, 5 s). Needs one portrait and one short motion clip.
text
The man from Image 1 performs the same moves as the dancer in Video 1, in a sunlit concrete loft: a smooth spin, a shoulder roll, then he points at the camera and laughs. Keep his face and white tank top from Image 1, copy only the motion from Video 1. Upbeat funk music with a clear beat.
Weak: "A woman walks down a hallway and talks." No shot times, no line in quotes, no light, and the model fills every gap itself. Strong: prompt 1, where shots, times, sound and the repeat-the-person sentence are all written out.
How far it goes
SpicyAPI adds no content filter. Between 9 and 12 October 2026 we ran adult fictional subjects through all three endpoints, one prompt per level, then reran the weak spots with prompt expansion off; the test prompts are not published. Zero requests were refused. Results for the first full grid on this build:
Level
Text-to-video
Image-to-video
Reference-to-video
Mild
Delivered
Delivered
Delivered
Moderate
Delivered
Delivered
Delivered
Strong, one person
Toned down (2 of 2)
Delivered (2 of 2)
Delivered (2 of 2)
Very strong
Delivered (2 of 2)
Delivered (2 of 2)
1 delivered, 1 toned down
Maximum, restraint and impact
Delivered (2 of 2)
Delivered (2 of 2)
Delivered (2 of 2)
Maximum, cinematic gore
Delivered
Delivered
Delivered
Strong, male subjects
Toned down (2 of 2)
Toned down (2 of 2)
Delivered (2 of 2)
Reruns on 11 and 12 October, with prompt expansion off and requests sent one at a time, gave the same picture: text-to-video still toned down single-person Strong scenes and male-subject requests, and the other two endpoints did not change. Reference-to-video is the endpoint that delivered male-subject requests as written.
Same-prompt check: on 11 October base MiniMax H3 delivered all 21 of 21 clips on the same seven levels across the three tasks, including the two cases where H3 X toned down text-to-video. That is the reason to choose base H3 for text-only work at the upper levels.
Not tested yet: a blind output-quality comparison against base H3, 1:1, 4:3 and 3:4 text-to-video ratios, and long 15-second clips at the upper levels.
Adults only, in every prompt, frame and reference. Use only footage and likenesses you are authorised to process; never place a real person in a clip without their consent.
Alternatives
Want a lower price per second still?MiniMax H3 X Turbo is a distilled build at about half the price per second and roughly two to three times the speed.
Need the full grid from a written prompt?MiniMax H3 delivered every level on all three tasks in our runs. Our MiniMax H3 review.
댓글은 자동 검사와 당사 팀의 확인을 거칩니다. 스팸, 부적절한 내용, 인신공격, 동의 없이 실존 인물을 거론하는 글은 삭제합니다. 댓글을 신고하면 영업일 기준 하루 안에 검토합니다.
이 모델을 써 보셨나요? 잘 된 방법을 공유해 주세요. 스팸을 막기 위해 댓글을 달려면 무료 계정이 필요합니다.
MiniMax H3 X 자주 묻는 질문
Yes. SpicyAPI adds no filter, and none of our test requests was refused. Image-to-video and reference-to-video delivered every level we tested; text-to-video toned down single-person Strong scenes and male-subject requests, so start those from a still or from references.
A tuned build of MiniMax H3 that runs only on SpicyAPI, with its own prompt enhancer. It is not an official MiniMax release. Its trainers describe the tuning as reinforcement-learning post-training for prompt following, picture quality and structural stability; those are their goals, not our measurements.
It costs less per second and has slightly stricter content limits. On the same prompts base H3 delivered 21 of 21 clips, including text-to-video cases that H3 X toned down. Choose H3 X for price and for image or reference work; choose base H3 for full range from text.
Yes. Every clip has stereo sound and it cannot be switched off. Put spoken lines in double quotes; in three speech-to-text checks the line came back word for word.
Clips run 2 to 15 whole seconds. A 5-second request returned a 5.18-second clip. Reference-to-video takes up to 9 images, 2 video clips (15 seconds in total) and 3 voice clips.
From $0.022 per second at 480p, billed per second of output; 720p and 1080p cost more. Sound and prompt expansion do not change the price. See the model page for live prices.
Only if you need the larger frame. The 1080p file is 1920 x 1088 but encoded at a lower bitrate than 720p, and it looked no sharper in our crop comparison.
Pick MiniMax H3 HighSpeed if you want 768p takes with sound that we saw come back as written at Very strong; for cheaper drafts or 2K, look at Lite or H3.