본문으로 건너뛰기

이 리뷰는 아직 한국어 버전으로 제공되지 않아 English 원문을 표시합니다.

필터 적용 — 이 모델은 모델 자체의 허용 범위를 넘는 요청을 명확히 거부합니다. 실측한 결과이며, 측정하지 않은 모델에는 표시가 붙지 않습니다.

OmniHuman 2.0 Review: Talking Avatar From a Portrait and Audio

Pick OmniHuman 2.0 when you have a portrait and a recording and want the prompt to direct expression; expect about two minutes per short clip.

  • 약함

  • 보통

  • 강함

  • 매우 강함

  • 최대

가격
—
소요 시간 중앙값
2.1분
성공률
데이터 수집 중

OmniHuman 2.0 is ByteDance's audio-driven avatar model, released on 15 October 2026. SpicyAPI serves it as one endpoint, omnihuman/2.0/talking-avatar. You send a portrait (image_url) and a recording of speech or singing (audio_url), and you get back a 720p video of that person performing the recording. The face, lips, head and upper body move with it. An optional prompt of up to 300 characters directs mood, gestures and where the eyes go. There is no duration, resolution or aspect-ratio field: the clip is as long as your audio, from 4 to 300 seconds.

The verdict

We ran four portraits on 25 October 2026, each with its own recording of 4.55 to 5.2 seconds. All four clips came back at 1280 x 720 and 24 fps with the audio track, after 110 to 133 seconds of processing. The lips followed the audio in every clip, the face stayed recognisably the same person, and most of the small gestures we asked for appeared. One did not: a lean toward the microphone never showed. A fifth portrait was declined by the publisher's content check before any video was made, and nothing was charged.

Pick it when the words are already recorded and you want a face to deliver them: a narrated intro, a testimonial, a character whose portrait is settled. Look elsewhere if you need the voice generated from text, a 1080p tier or a vertical format you can select.

How it scores. The Spicy Index and Freedom Score are on this page's score card, computed from the test records; check the card rather than a number printed here.

Try OmniHuman 2.0 →

Key facts

  • Inputs: one portrait and one recording, both required. Portrait: JPEG, PNG, WebP, BMP, TIFF, GIF, HEIC or HEIF, under 30 MB, 300 to 6000 px per side, width-to-height ratio 0.4 to 2.5. Audio: WAV or MP3, under 15 MB, 4 to 300 seconds.
  • Output: 720p. In our four runs the clip was 0.2 to 1 second longer than the audio and landed on a whole number of seconds (4.55 s of audio gave 5 s, 5.2 s gave 6 s).
  • Speed: 110 to 133 seconds from submit to finished file for clips of about five seconds. It is an asynchronous task, so you poll for the result or use a webhook. We have not timed longer audio.
  • Price: billed per second of the input audio, 4-second minimum and 300-second maximum. At the time of writing that is $0.1084 a second, about $0.54 for five seconds. The model page shows the live price.
  • Content limits: the publisher reviews every portrait; see "How far it goes". The page label is Filtered.

좋았던 점과 아쉬웠던 점

좋았던 점

  • Lips follow the line. In all four clips the lip movement tracked the recording, including a slow, low-register line at a vintage microphone.
  • The face stays the person. Comparing frames to the input portrait, the face was recognisably the same in all four clips.
  • Small, specific beats land. A smile and a small head tilt on the last word, a half smile with a raised eyebrow, a glance away in the final second and a quick laugh all arrived roughly where the prompt placed them.
  • The body moves, not just the mouth. The publisher describes head and upper-body movement following the audio, and the examples show it.
  • Phone photos go in as they are. WebP, HEIC and HEIF portraits are accepted, so there is no conversion step.
  • Long recordings are supported. Up to 300 seconds of audio in one request, which we did not push to the limit.

아쉬웠던 점

  • It needs a recording. There is no text-to-speech path here. If you only have a script, you need a voice file first, or a model that generates the voice with the picture.
  • Body movement is less reliable than expression. "A lean toward the mic" did not visibly happen while the laugh and eyebrows beside it did. That is one run, so check a body movement before you build on it.
  • Slow for a short clip. About two minutes of processing for a clip of about five seconds.
  • Per-second price is higher than Kling Avatar 2.0. At the time of writing Kling Avatar 2.0 is $0.0512 a second at 720p, against $0.1084 here. Kling also has a 1080p tier; OmniHuman 2.0 is 720p only.
  • Every portrait goes through a content check. A declined portrait is not billed, but you only find out after submitting.
  • The output length is not exactly the audio length. Inspect the returned file if you are cutting to a precise timeline.

What the clips look like

The gallery holds four published examples from the OmniHuman 2.0 model page, all clothed and safe for work. Three of them use the same portraits and recordings as the Kling Avatar 2.0 page, trimmed to about five seconds, so the two pages can be compared side by side.

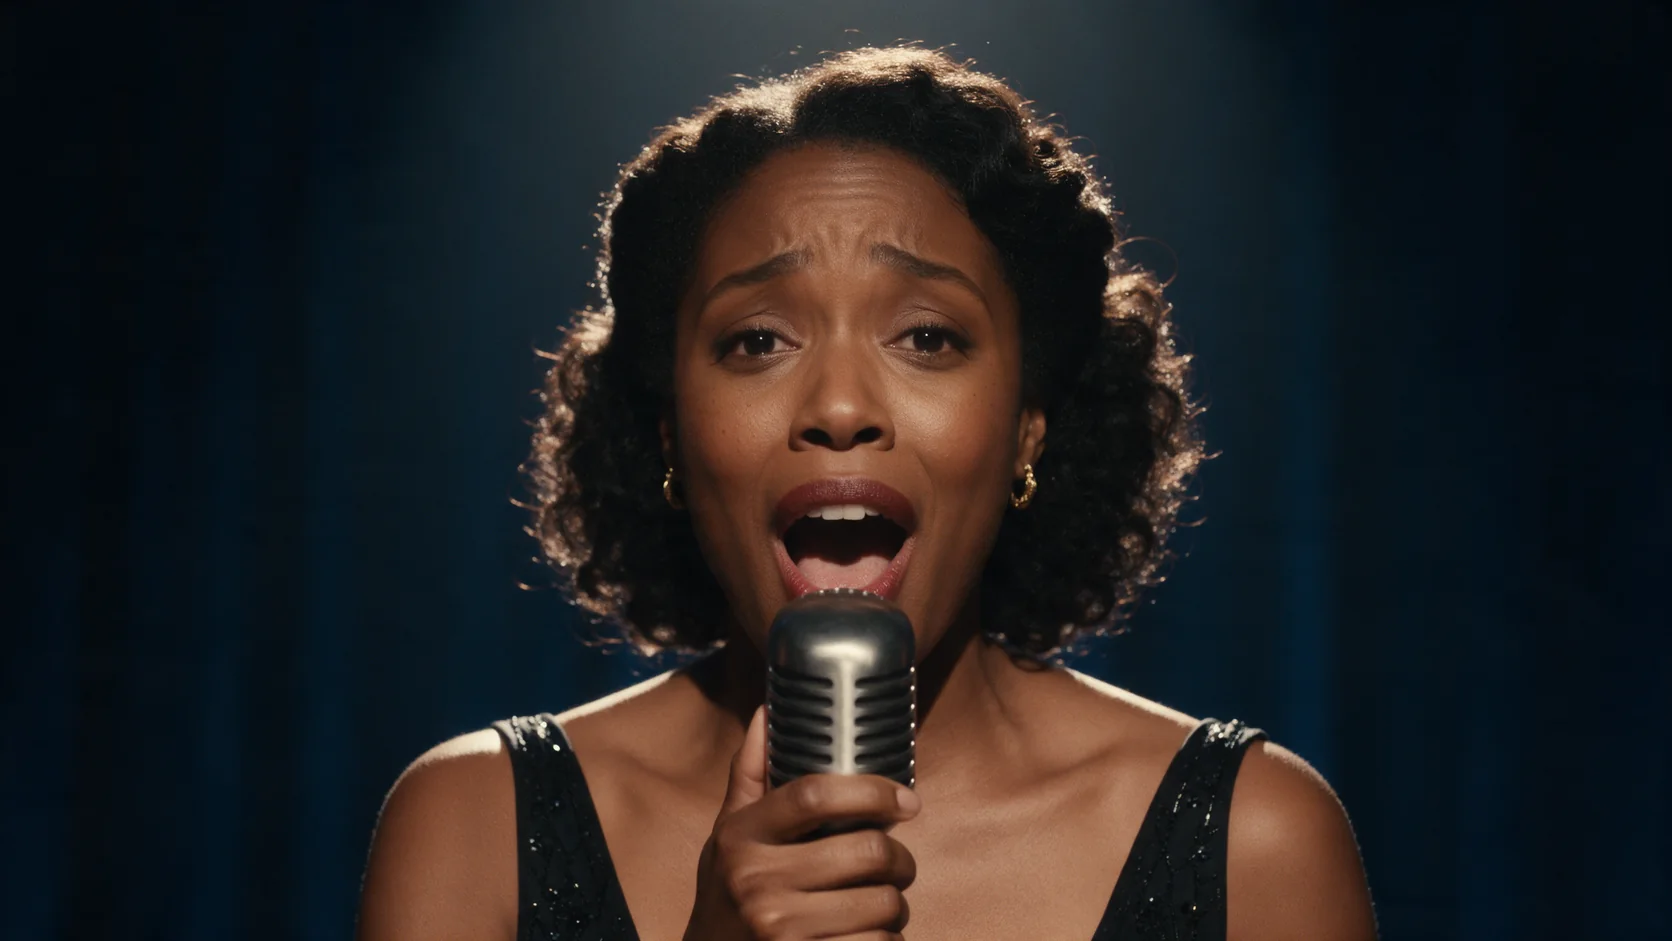
A slow line at a vintage microphone. A woman in a black velvet gown, 5.2 seconds of slow audio. The lips track the audio, a small head tilt and a smile land at the end as the prompt asked, and her hand stays on the microphone. The clip runs 6.0 seconds.

A low, teasing line behind a bar. A man behind a dim bar, a 5.0-second spoken line. His eyes close and reopen, the half smile and raised eyebrow follow the line, and the bottles behind him stay stable.

A glance away in the last second. A woman on a sunny stone terrace, 4.55 seconds of audio. Her head turns toward the sea in the final second and her hair moves slightly.

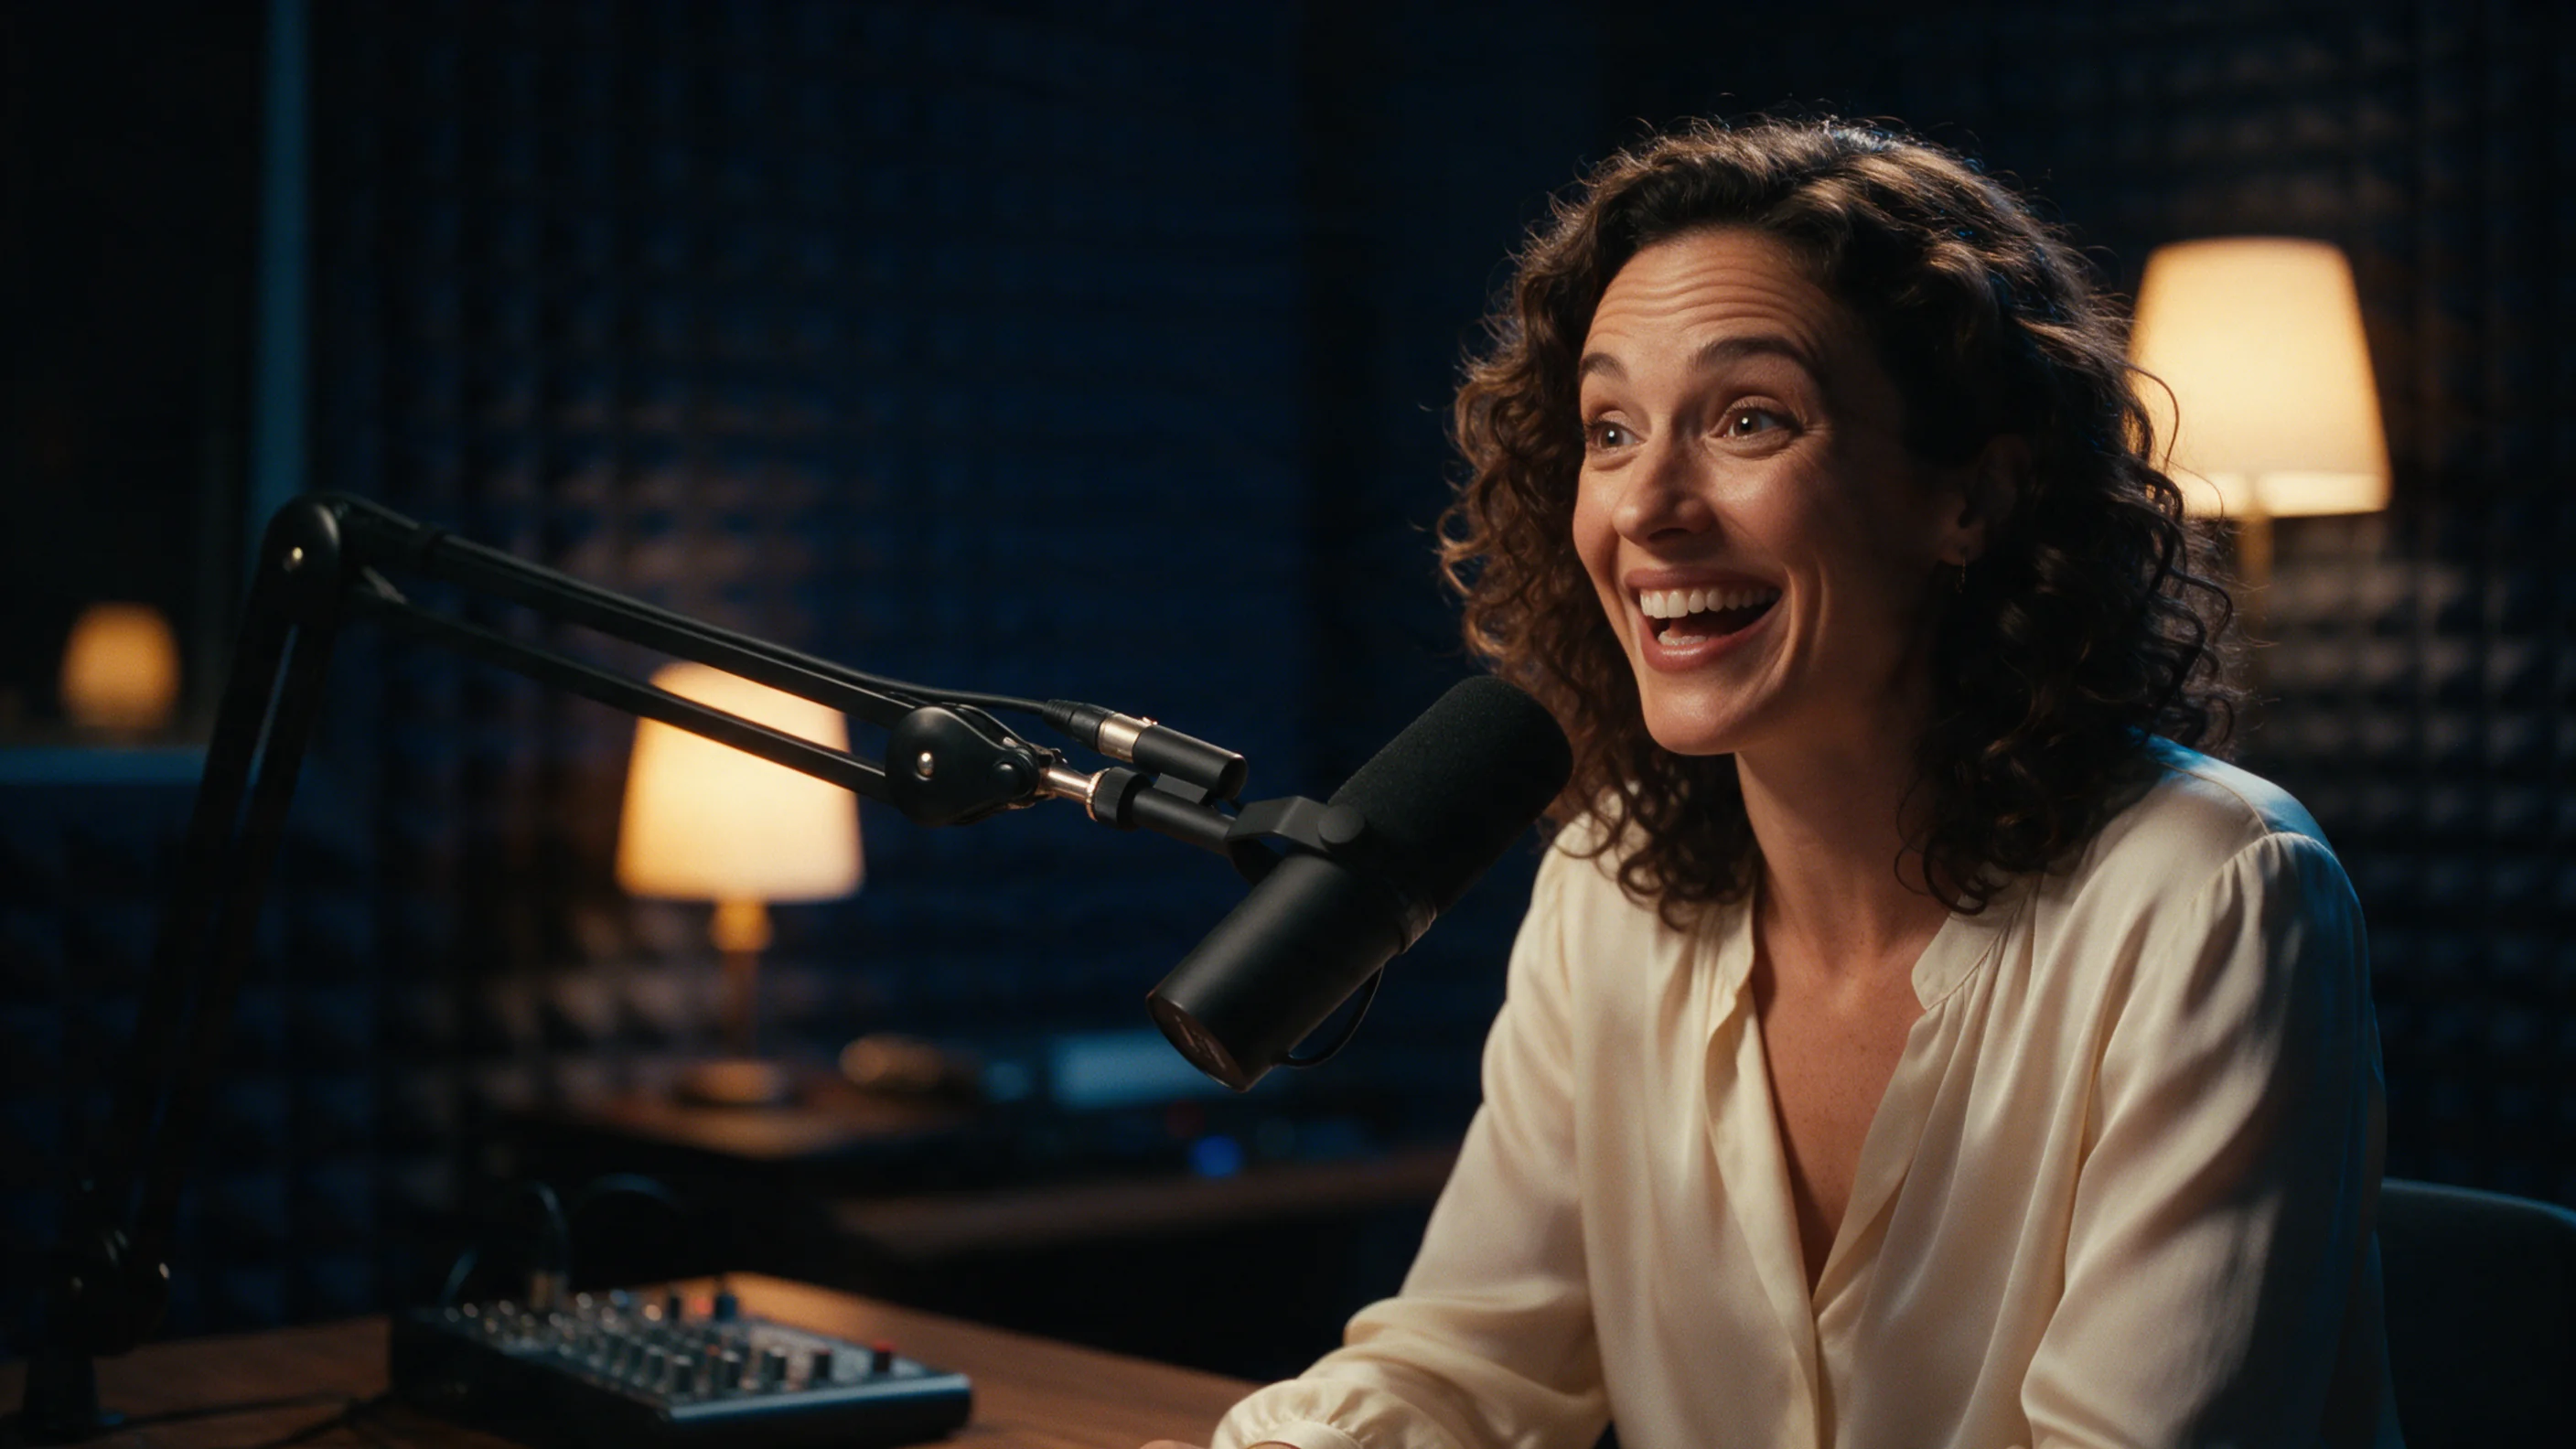
A late-night show opening. A woman in a podcast studio, an upbeat 4.8-second intro. Wide expressions, lively eyebrows and a laugh follow the prompt, but she does not visibly lean toward the microphone.
Prompts that worked

The prompt directs the performance. The portrait and the recording already decide who is on screen and what is said.

  • Tie a beat to a moment in the line. "Slow and languid, a lazy smile on the last word and a small tilt of the head, eyes on the lens." Both the smile and the tilt arrived at the end.
  • Pair a posture with an expression. "Leaning on the bar, he speaks low and teasing, a slow half smile and a raised eyebrow, warm amber light." The clip kept a consistent low register.
  • Give a gesture a moment to happen. "Relaxed on a sunny terrace, she murmurs the line with a knowing smile and glances away at the end." The head turn landed in the final second.
  • Keep to a few beats. Each of our prompts asked for a mood, one or two facial beats and sometimes a posture. That is enough to shape a five-second clip.
  • Trim the audio first. The clip runs as long as the file and billing follows the audio length, so cut the recording to the performance you want.

The publisher lists Chinese, English, Japanese, Korean, Spanish (Mexican) and Indonesian as prompt languages. Our prompts were in English, and we did not test camera-movement instructions.

How far it goes

SpicyAPI adds no filter of its own, but the publisher reviews every portrait before a clip is made. On 25 October 2026 we sent one portrait at the Moderate level of our five-level ladder (Mild, Moderate, Strong, Very strong, Maximum; test prompts not published). It was declined before any video was generated, in under half a minute, and nothing was charged. That is a refusal, not a toned-down result.

Not tested yet: Mild, Strong, Very strong and Maximum on this endpoint, so the score card has too few content levels for a full Freedom reading. We have no data on the other levels, so try your own portrait before you plan a project around it.

This endpoint makes a specific face say or sing specific words, which carries real personal risk if that face and voice are not yours to use. Send only a portrait and a recording that are your own, or that the person shown and heard has explicitly agreed to. Adults only, and never a real, identifiable person without consent.

Alternatives

OmniHuman 2.0의 콘텐츠 표현 범위

단계·작업별 Freedom 점수
단계말하는 아바타
약함테스트에서 가장 가벼운 프롬프트아직 테스트 안 함
보통필터가 있는 모델이 거부하기 시작하는 지점
1회 중 0회 생성0.0 / 20점
강함중간 단계입니다. 순위를 매기기 전에 반드시 테스트합니다.아직 테스트 안 함
매우 강함대부분의 모델이 수위를 낮추기 시작하는 지점아직 테스트 안 함
최대척도의 맨 위. A 부문과 B 부문 두 부분으로 나눠 채점아직 테스트 안 함
작업 점수나머지가 통과할 경우의 범위: 0.0–80.02026년 10월 25일 테스트

2026년 10월 25일–2026년 10월 25일 테스트

이 사이트는 직장에서도 안전하게 볼 수 있도록 유지합니다. 결과는 글로 전하고, 보여 주는 이미지는 픽셀 모자이크를 거치며, 테스트 프롬프트는 절대 공개하지 않습니다. 미성년자로 보이는 인물, 실존 인물의 외모, 동의 없는 상황은 절대 테스트하지 않습니다.

모든 테스트 기록 보기 →무검열 리더보드 보기 →

내 프롬프트로 어디까지 되는지 확인하기

OmniHuman 2.0의 Spicy Index 구성

공개 리더보드 품질의 45%
아직 테스트 안 함

추적 중인 공개 리더보드에 아직 정확히 일치하는 항목이 없습니다. 작동 방식

블라인드 결과물 테스트 품질의 35%
아직 테스트 안 함

아직 자체 블라인드 결과물 테스트를 거치지 않았습니다. 작동 방식

아레나 품질 품질의 20%
아직 테스트 안 함

블라인드 투표 100표 이상이고 95% 신뢰구간의 폭이 200 Elo 미만일 때 반영합니다. 작동 방식

기능 가중치 10.5%
아직 테스트 안 함

아직 채점하지 않았습니다. 작동 방식

Freedom Score 가중치 30%
아직 테스트 안 함

자유도가 미측정이거나 근거가 부족합니다. Index는 원래 품질·기능 점수를 유지하고 잠정 표시로 순위에 포함됩니다. 근거가 없다고 0점으로 처리하지 않습니다. 작동 방식

전체 테스트 리포트 보기 →

SpicyAPI에서 지원하는 OmniHuman 2.0 기능

엔드포인트별 기능
기능말하는 아바타
네이티브 오디오아니요
시드 지정아니요
네거티브 프롬프트아니요
모든 파라미터와 코드 예시 보기 →

실제로 걸리는 시간

지난 30일 동안의 실제 작업에서 요청부터 완성까지를 측정했습니다. 시간에는 당사가 직접 돌린 테스트 작업도 포함합니다.

소요 시간 중앙값
2.1분
90번째 백분위수
3.3분
영상 1초당 대기 시간
데이터 수집 중
성공률
데이터 수집 중

완료된 작업이 10건 이상 모이면 시간을 표시합니다. 성공률은 고객 작업만으로 계산하며, 30일 분량의 트래픽이 모일 때까지 모든 모델에서 숨겨 둡니다.

OmniHuman 2.0 대신 고려할 만한 모델

어떻게 생각하세요?

이 리뷰가 도움이 되었나요?

투표하려면 로그인하세요.

댓글

댓글은 자동 검사와 당사 팀의 확인을 거칩니다. 스팸, 부적절한 내용, 인신공격, 동의 없이 실존 인물을 거론하는 글은 삭제합니다. 댓글을 신고하면 영업일 기준 하루 안에 검토합니다.

이 모델을 써 보셨나요? 잘 된 방법을 공유해 주세요. 스팸을 막기 위해 댓글을 달려면 무료 계정이 필요합니다.

OmniHuman 2.0 자주 묻는 질문

OmniHuman 2.0 직접 써 보기

플레이그라운드에서 모든 파라미터를 설정하고 실행 전에 정확한 가격을 확인하세요.

  • A white cliff-top hotel lit gold at night above a dark sea, a glass rooftop pavilion, a lantern-lit pool terrace and a mahogany motor launch speeding away under the moon

    P-Video 2 Pro

    Pick P-Video 2 Pro for fast takes with built-in sound; for Maximum-level requests delivered as written, try another video model.

    Spicy Index
    63.7
    Freedom Score
    58.7

    2026년 10월 17일 테스트

    리뷰 읽기
  • 짙은 파란 벨벳 배경 앞, 단 하나의 스포트라이트 아래 빈티지 마이크에 대고 노래하는 여성의 클로즈업.

    Kling Avatar 2.0

    Kling Avatar 2.0은 인물 사진 하나와 오디오 파일 하나를 720p 또는 1080p로 최대 5분까지 말하거나 노래하는 클립으로 바꿉니다.

    Spicy Index
    —

    2026년 9월 28일 테스트

    리뷰 읽기
  • 해 질 녘 유리 온실에서 커다란 열대 잎 사이에 서 있는 에메랄드 실크 드레스 차림의 여성

    Wan 3.0

    텍스트, 스틸, 참조로 싸게 무검열 사운드 포함 30초 테이크를 뽑으려면 Wan 3.0. 대본이 끝나는 곳에서 장면이 멈춰야 한다면 피하세요.

    Spicy Index
    87.7
    Freedom Score
    96.0

    2026년 9월 24일 테스트

    리뷰 읽기