You have a scene in mind, an uncensored video model, and a prompt that either gets refused or comes back tamer than you wrote. Seedance 2.5 and 2.5 Spicy are easier to steer when the prompt, first frame and task all describe the same shot.
Short answer: start on base Seedance 2.5 for text, an opening still or reference images, video or audio; use Spicy when you need its upscaled 4K output. Both delivered advanced NSFW in our September and October 2026 tests; each also produced a toned-down clip. Kissing-related requests can be refused by Seedance's own input check.
The categories below are L1 suggestive, L2 moderate NSFW, L3 advanced NSFW, L4 higher-intensity adult scenes, and L5A an additional adult-content category. L5B is a separate non-adult violence probe. The Seedance uncensored test gives the full results.
The 30-second version
- One formula: the adult subject and what they wear, two or three beats of action, one camera move, the light, the sound. Plain sentences, in the order things happen.
- Be specific. Name the wardrobe, action and shot you want. Prompt 3 links a whisper, a laugh and a final pose into one scene.
- On image-to-video, write the motion of what's already in the still. A different scene or camera position can produce a cut instead of continuing your composition; the hot-spring example below shows that failure.
- Spicy is image-to-video only. It adds upscaled 4K and costs 56% to 75% more per second at the same resolution. Both support uncensored prompts; Spicy is not a permission upgrade.
- Draft 5 seconds at 480p for $0.62 on 2.5 ($1.08 on Spicy); keep at 720p for $1.39 ($2.16).
Open Seedance 2.5 in the Playground →
Seedance 2.5 or 2.5 Spicy: pick before you write
| Model · task | What your prompt carries | Levels in our tests | 5 s from |
|---|---|---|---|
| 2.5 text-to-video | Everything | Uncensored: L3 and adult L5A in the recorded runs | $0.62 |
| 2.5 image-to-video | Only what moves | Uncensored: L3 and adult L5A; see the cut-away limitation below | $0.62 |
| 2.5 reference-to-video | Who each image is, then the action | Uncensored: L3 and adult L5A from reference images | $0.62 |
| 2.5 Spicy image-to-video | Only what moves; the prompt is optional | Uncensored: recorded adult probes through L5A | $1.08 |
Uncensored is the label on our model pages: we add no content filter. The refusals described below come from Seedance's own check, which runs before rendering.
How to write a Seedance 2.5 prompt: one shot, five parts
Seedance renders what you name and improvises what you don't. Give it five things, in the order they happen on screen. Here is prompt 3, taken apart:
| Part | What to write | From prompt 3 |
|---|---|---|
| Subject | "Adult", who, wardrobe, where | Two adult women in a jazz bar's back hallway, one in a black velvet slip, the other in an open white shirt |
| Action | Two or three beats, joined by "then" | One whispers against the other's ear; she closes her eyes and laughs, then they rest their foreheads together |
| Camera | One move, or "locked off" | Handheld 35mm |
| Light | One source and its colour | Amber glow, warm practical lights |
| Sound | What we hear | Muffled saxophone, a whispered line and soft laughter |
- Link the action beats. "Tips her head back, mouths the lyrics, then hops down" gives the shot a beginning, middle and end; a rise followed by a long hold can leave most of the clip still.
- Describe the action positively; use exclusions for a specific limit. Our night-train prompt said "neither looks at the other", yet they ended face to face. By contrast, "do not pull back, do not widen the shot" held in the steamed-glass clip. Keep the desired action explicit rather than expecting a list of exclusions to supply it.
- Call everyone an adult. With two people, say who does what to whom.
- Choose one camera move: "slow push in" (prompts 9 and 11), "handheld first-person" (prompt 7), "slow orbit around her as she turns" (spin clip), "slow dolly following her up the stairs" (stair clip), or "extreme close-up, locked-off camera" (tear close-up clip).
- Name the sound.
generate_audiois on by default and costs no extra. Switch it off for loops or clips you will score yourself. Audio can still be absent: the spin clip, prompt 7's point-of-view clip and both hot-spring clips have no track. Play the returned file before relying on its sound.
When a paragraph is not enough: time the important beat
For a short shot, prose is enough. If a turn, walk and final pose collapse into one movement, give each its own interval. A timed fashion variation:
One continuous medium shot of an adult performer in an evening dress on a rooftop.
0–2s: she turns toward the lens; the wind moves her coat. Camera holds.
2–4s: she takes two steps to camera-right. Camera slowly follows.
4–5s: she stops and looks into the lens. Hold the final composition.
Sound: wind and distant city traffic, no music.
Set five seconds in the duration control. Timestamps communicate sequence, not frame-accurate editing. For a longer scene, give each stage one event and an end position that the next inherits. The creator prompt library has more staged shot briefs.
What gets refused, what gets toned down, what gets through
| You wrote | What came back | Write this instead |
|---|---|---|
| Kissing-related requests (the model pages warn about this) | Some requests refused before rendering | For a romantic image-led scene, put the composition in the opening still and describe the motion, as the model pages advise. Prompt 3 includes cheek contact; use a tested alternative below when Seedance cannot deliver your intended action |
| L3 and adult L5A elements in plain words (2.5, all three tasks) | Matching sampled results in these recorded runs | Nothing to change |
| An L4 prompt in plain words (base 2.5) | Matched in 8 of 9 clips: 3/3 from a still, 3/3 from reference images, 2/3 from text; one text clip was milder | Put the intended composition in the still or reference images, then describe the movement |
| A strong prompt on a safe still (Seedance 2.0 and older) | Tame clips: the still won | Use an opening still that contains the intended composition |
| A scene the still doesn't show | A split second of the still, then a cut: to the red-lit adult L5A scene we described, or to the backs of two heads and 17 seconds of almost nothing (the hot-spring clip) | Direct the motion inside the still's own scene (prompt 9), or build the new scene into the still |
| An L2 prompt on 2.5 Spicy image-to-video (three runs) | As written in 2 of 3; one clip came back toned down, with the scene cropped | Identify the missing action or tighter crop in the whole clip. Revise that part of the brief before paying for another take; keep essential people and props visible in the still |
| A photo of a real, identifiable person as the still or a reference | The model pages warn that Seedance's input check may turn such photos away | Use a suitable generated or consented character; see the mixed reference-face reports in the stills section |
| "Neither looks at the other" | Face to face, eyes locked | Write the look you want |
Refusals come from Seedance's own check, before rendering. A content refusal can appear in a failed task record as errorCode: content_rejected; a rendered but milder clip is a completed result. Failed tasks normally release the hold without a charge, and our Seedance 2.5 pages disclose no refusal charge (billing rules); the task's settled and cost fields show what you were actually charged. A clip that comes back tamer than you asked is billed like any other, so judge clips on their frames, not on the status.
12 copy-paste Seedance 2.5 prompts, by scene
The examples focus on adult fashion and atmosphere; applying the structure covers stronger briefs. For image-led tasks, upload your still or reference images and set the duration and resolution before generating.
1. Solo: the 3am laundromat (text-to-video)
Black-and-white handheld documentary shot, photorealistic live action. 3am in a 24-hour laundromat. An adult woman sits cross-legged on top of a running washing machine wearing an oversized men's denim jacket open over a black sports bra and cotton boy shorts, bare legs, big headphones on, nodding along to music while the machine vibrates under her. She tips her head back, mouths the lyrics, then hops down and pulls open the dryer door. Fluorescent tubes overhead, wet floor reflections, grainy monochrome 16mm, loose handheld drift.
Run this prompt on Seedance 2.5 →
Change the wardrobe line for a fashion variation while keeping the three action beats.
2. Solo: the shower, framed from the shoulders up (text-to-video)
An adult woman stands under a rain shower in a dark slate bathroom, framed from the shoulders up, water running over her shoulders and down her back. She tips her head back into the stream, pushes her wet hair off her face with both hands, then turns toward the glass and wipes a clear streak through the fog to look out at the camera. One warm pendant lamp, steam rolling across the frame. Slow push-in through the steam. Running water, a soft echo, no music.
Run this prompt on Seedance 2.5 →
"Framed from the shoulders up" specifies the shot boundary, as the collarbone framing does in prompt 9.
3. Two adults: a whisper and a laugh (text-to-video)
Warm, clearly lit close two-shot. Two adult women stand very close in the amber glow of a jazz bar's back hallway, one in a black velvet slip, the other in an open white shirt. One leans in and whispers something against the other's ear; the other closes her eyes and breaks into a wide laugh, then they rest their foreheads together. Handheld 35mm, warm practical lights, shallow focus, muffled saxophone, a whispered line and soft laughter.
Run this prompt on Seedance 2.5 →
4. Rim light at dawn (text-to-video)
An adult woman in a loose linen shirt stands at a tall loft window at dawn and turns slowly toward the camera, soft rim light tracing her shoulders, a sheer curtain moving in the draft. One continuous shot, slow push-in, photorealistic, fine film grain.
Run this prompt on Seedance 2.5 →
Keep one mood and one continuous shot; let the curtain supply the secondary movement.
5. A 15-second story that edits itself (text-to-video)
Set duration to 15 seconds. The original prompt below said “Thirty seconds,” but the duration setting determined the delivered length. For a new attempt, omit that duration phrase and use the control.
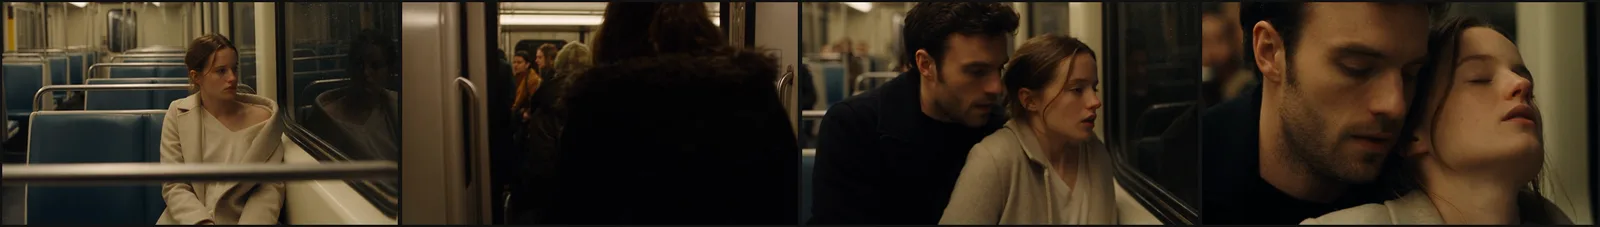
Cast: one man and one woman. Thirty seconds on a last train at night: she sits alone in an empty carriage with her coat falling open, and at each stop more people board until the two of them are pressed chest to back against the door, her head tipped back on his shoulder, neither of them speaking. Warm carriage light against tunnel black. Cinematic, shallow depth of field, heavy film grain, colour.
Run this prompt on Seedance 2.5 →
The Run link opens at the page defaults, so set the duration to 15 and the resolution to 1080p to match this clip: 15 seconds at 1080p is 15 x $0.6823, about $10.23, while the same prompt at 480p is about $1.85. At 15 seconds, Seedance cut it into four shots on its own, and the same woman in the same coat carries through the cuts where she is on screen. Length comes from the duration setting, not from "thirty seconds" in the text. For one unbroken take, write "one continuous shot, no cuts".
6. Image-to-video: write only what moves (the hotel window)
She turns slowly from the window toward camera, the silk slip catching the city light as it moves, one hand trailing along the glass, then she tilts her head and holds the look. Subtle handheld drift, warm lamp against cool skyline, quiet room tone.
Run on Seedance 2.5 → · Run on 2.5 Spicy →
The still defines the person, outfit and room; the prompt supplies movement. This clip keeps the portrait shape (786 x 1178).
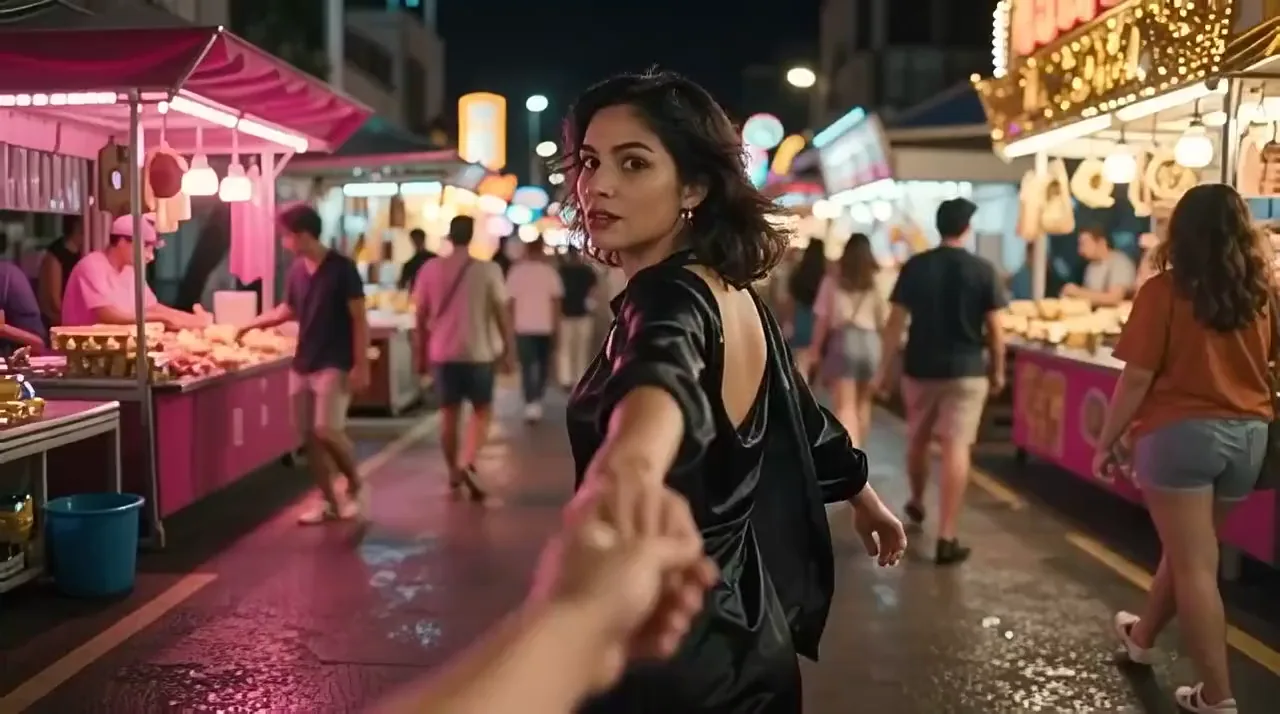
7. First person: she pulls the viewer along (image-to-video)
She closes her hand around the viewer's and pulls, breaking into a run and towing the camera after her through the neon stalls, laughing back over her shoulder once. Handheld first-person motion, neon streaking past, crowd noise and sizzling griddles.
Run on 2.5 Spicy → · Run on Seedance 2.5 →
For POV, put the viewer's hand in the still and say what it does. Crowd noise is requested here but absent from the returned file.
8. Your own still (image-to-video)
She rolls from her side onto her back, stretches both arms over her head, then turns her face to the lens and holds the look, taking one long breath. Morning light slides across the sheets. Slow handheld drift from the foot of the bed toward her face. Birdsong outside, the sheets rustling.
Run on 2.5 Spicy → · Run on Seedance 2.5 →
Make the starting composition with an uncensored image model, then describe its movement.
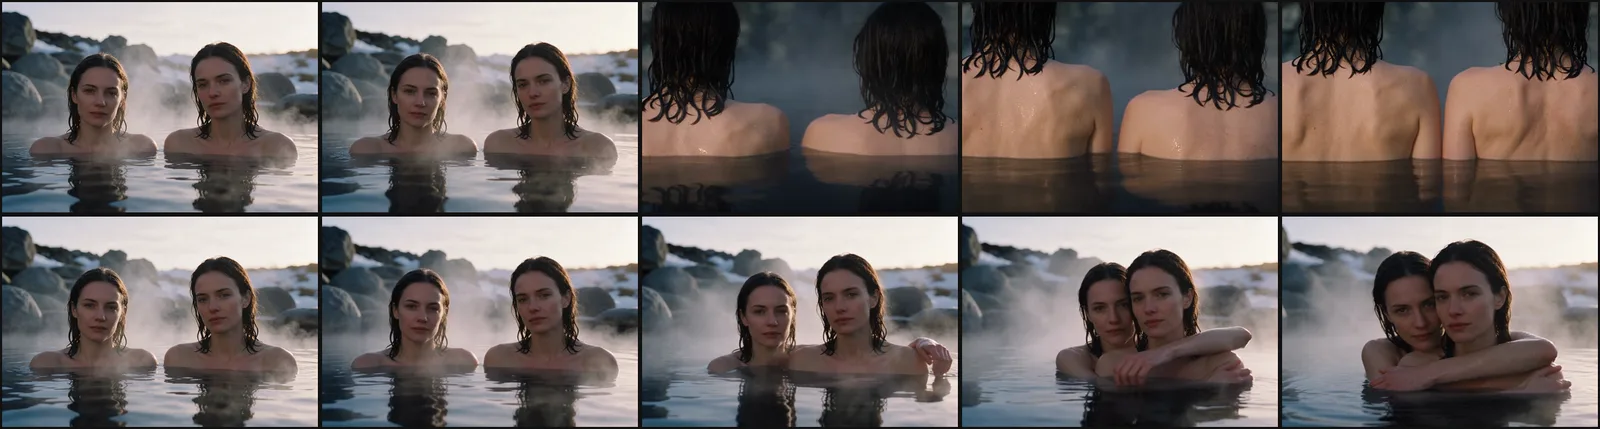
9. Two people in the still: the hot spring (image-to-video)
The two women rise toward camera only as far as the collarbone, water sheeting off their shoulders, and the steam banks thick across the surface in front of them. One slides behind the other and wraps both arms around her from behind, her forearm crossing high over the chest; they settle cheek to cheek and hold the look into the lens while the water swells and slaps the rocks. Slow push in on their faces and shoulders, framed from the collarbone up the whole time. Dusk light on wet skin, drifting snow beyond. Cinematic, shallow depth of field, heavy film grain.
Run on 2.5 Spicy → · Run on Seedance 2.5 →
The earlier prompt asked for their backs while the still showed their fronts, then specified a stop and locked framing. The clip cut behind them within 3 seconds and held almost still for the remaining 17 (watch it). The four-second rewrite keeps the front view and gives it a rise, an embrace and a final pose. For that framing, "from the collarbone up the whole time" states the boundary while leaving room for movement; it does not require removing every negative instruction.
10. A loop: the same still first and last (image-to-video)
She lifts her head from the pillow, turns to watch the rain on the window, runs one hand slowly through her hair, then settles back into exactly the pose she started in. Camera locked off. Rain on the glass, quiet room tone.
Run on 2.5 Spicy → · Run on Seedance 2.5 →
Set the same still as the opening and closing frame. Both models accept last_image_url together with image_url. Keep camera and light steady and end the action in the starting pose. Trim or crossfade the join if the boundary frames or audio do not meet smoothly.
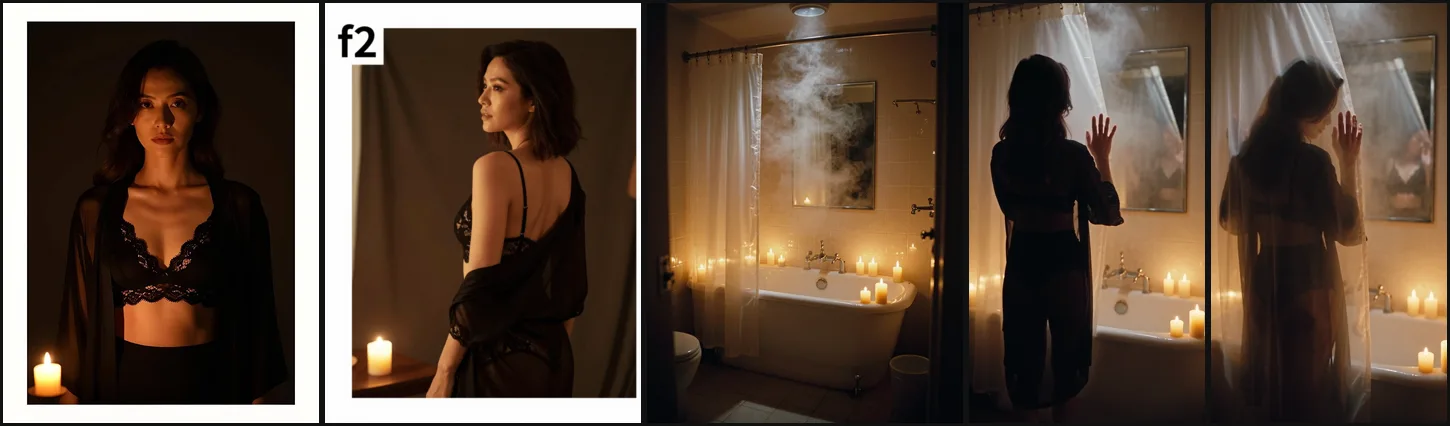
11. Reference-to-video: cast the images before the action
Put the woman from @Image1 and @Image2 into the candlelit bathroom of @Image3. She steps behind the translucent shower curtain so she reads as a warm silhouette through it, one hand pressed flat against the fabric, then leans her forehead to it. Steam rolls past the candles. Slow push in, no cut.
Run this prompt on Seedance 2.5 →
Seedance reads reference images in upload order as @Image1, @Image2 and @Image3 (a clip is @Video1, a track @Audio1). Say what each one is before the action. Our clip kept the black lace outfit and the robe from the first two and put her in the bathroom from the third, tub, candles and steam included, in one unbroken shot.
12. Reference-to-video: the person and the room
@Image1 is the woman, front view. @Image2 is the same woman from behind. @Image3 is the hotel bedroom. She walks into the room from @Image3, sits on the edge of the bed, pulls her hair over one shoulder and looks up at the camera, then lies back slowly. One continuous shot, slow push-in. Warm bedside lamp, city hum through the window.
Run this prompt on Seedance 2.5 →
Use consistent character views for the first two reference images and assign the room to the third.
Applying the structure to your adult brief
For a stronger adult brief, keep clear subjects, one main action, one camera instruction and a definite ending. Intensity words cannot turn a filtered model into an uncensored one.
- For image-led work, compose the scene first. Put both adult characters and any essential prop in the still when they must remain in the original shot. A prompt describing a new room or cast can produce a cut rather than animate that composition.
- Choose one mood. Calm and intense cues compete; use one clear direction instead of asking for both.
- If the result is milder, identify what changed. A tighter crop, a different action and a refused request are three different problems. Fix the crop or the missing action in the creative brief; if the model rejects the requested content, choose a suitable tested model rather than treating wording changes as a guaranteed fix.
Preparing the still and reference images
- Frame for the final clip. Make the still 16:9 or 9:16, with whole faces, every person and essential props inside the crop. Both image tasks follow its shape; each side must be 300 to 6,000 pixels.
- Generate the starting composition. Qwen Image 2.1 costs $0.024 per 1k image; Seedream 5.0 Pro costs $0.036 at 1k. The Seedance image-to-video guide uses a Seedream rooftop still; the image generator comparison helps choose the image model. Upload the selected still through the Playground or use an accessible HTTPS image, then draft at 480p.
- Photoreal faces can trigger Seedance's input check, including generated portraits in community reports. An unexplained 422 does not identify its cause; check the actual error and input. Text-to-video avoids the image dependency. Each file can be up to 10 MB on image-to-video and reference-to-video.
- One job per reference. Two angles of the person and one of the room did the job in prompt 11. Put the wardrobe on the person images.
Where Seedance 2.5 trips up, and the fix
- Stiff, nearly frozen motion. If the prompt asks for one brief movement followed by a hold, a long duration can leave most of the clip still, as in the old hot-spring example. Give the shot a connected sequence—rise, embrace, settle—and shorten the duration to fit it. Add a camera move only if the shot needs one.
- Cuts you didn't ask for. Prompt 5 became four shots in 15 seconds; image-to-video can also cut when the prompt describes another scene. For continuity, keep the action inside the opening composition and specify "one continuous shot, no cuts". Our six-second reference clip stayed in one shot, but the instruction is not a lock. For deliberate cuts, separate each shot's action and framing into timed sections, following the staged structure in the creator library above.
- Face drift. Reuse a clear character reference, remove competing faces from location reference images and reduce simultaneous actions when identities blend.
- Allow minutes for either model. Allow several minutes for generation and queueing. Base is the cheaper draft.
- 30 seconds is the ceiling. Chain clips through the last frame: How to make longer uncensored AI videos.
What a usable clip costs
| Clip | Seedance 2.5 | 2.5 Spicy |
|---|---|---|
| 5 s at 480p (draft) | $0.62 | $1.08 |
| 5 s at 720p | $1.39 | $2.16 |
| 5 s at 1080p | $3.41 | $5.40 |
| 5 s at 4K (upscaled from 1080p) | — | $10.80 |
| 30 s at 720p | $8.32 | $12.96 |
Sound on costs the same. Two costs matter when planning revisions:
- Drafts plus the final: three five-second 480p drafts and one five-second 720p final total $3.24 on base 2.5 or $5.40 on Spicy.
- Reference video: output seconds plus measured reference seconds are billed at $0.0738, $0.1659 or $0.4082 per second at 480p, 720p or 1080p. The initial quote reserves the maximum 30-second reference allowance and releases the unused part. Reference-image-only requests use the ordinary base rates.
Failed and refused tasks normally aren't billed; completed but milder results are. Prices are from our public catalogue.
When to use MiniMax H3 or Wan instead
Seedance 2.5 suits longer shots and reference-led scenes. Consider another model for these jobs:
- A kiss asked for by name: Wan has rendered this action. Wan 2.6 text-to-video also supports higher-intensity adult scenes, at $0.45 for 5 seconds at 720p; see every Wan version, tested. MiniMax H3 is another uncensored option, starting at $0.125 for five seconds. Its prompt guide has 14 more prompts.
- A cheaper, different look from a still: Wan 2.2 Spicy at $0.095 for 5 seconds.
Try the prompt, then use the API
- Open the Seedance 2.5 text-to-video Playground.
- Paste the chosen prompt, select five seconds at 480p and choose whether the shot needs sound.
- Generate a draft. Keep the same model while refining the action and camera.
Set SPICY_API_KEY in your environment. This Python 3 example submits one new shot after you confirm its price.
import json
import os
import urllib.request
import uuid

base = "https://api.spicyapi.ai/api/v1"
headers = {"Authorization": "Bearer " + os.environ["SPICY_API_KEY"],
           "Content-Type": "application/json", "User-Agent": "SpicyAPI-Blog/1.0"}
settings = {
    "duration_seconds": 5,
    "resolution": "480p",
    "generate_audio": False,
    "aspect_ratio": "16:9"
}
settings["prompt"] = 'A slow camera push toward the subject. Keep the setting and clothing unchanged. One continuous shot.'
payload = {"model": "bytedance/seedance-2.5/text-to-video", "input": settings}

def post(path, body):
    request = urllib.request.Request(base + path, json.dumps(body).encode(), headers)
    with urllib.request.urlopen(request, timeout=60) as response:
        result = json.load(response)
    if result.get("code") != 200:
        raise RuntimeError(result)
    return result["data"]

quote = post("/jobs/quote", payload)
if input(f"Maximum charge ${quote['maxCharge']}. Type yes to generate: ") != "yes":
    raise SystemExit("Stopped before generation")
headers["Idempotency-Key"] = str(uuid.uuid4())
print("Request key:", headers["Idempotency-Key"], flush=True)
task = post("/jobs/createTask", {**payload, "quoteId": quote["quoteId"],
                              "expectedCost": quote["estimatedCost"]})
print("Task ID:", task["taskId"])
Keep the printed request key for recovery of that same request; a new shot gets a new key. Task API documentation covers result delivery and recovery.
For repeated shots, let an Agent use an approved input file: CLI spicyapi tasks create --model bytedance/seedance-2.5/text-to-video --input-file input.json --wait; MCP ask it to call spicyapi_task_create with that model and input; Skill ask “Use the spicyapi Skill to generate this approved shot and return the result.” CLI and MCP show the price before creation. See the Agent integration documentation.
FAQ
How do I write uncensored prompts for Seedance 2.5?
Five plain sentences in screen order: the adult subject and wardrobe, two or three beats of action, one camera move, the light, the sound. On image-to-video, write only the motion. Prompt 3 is the template.
Why was my Seedance prompt rejected?
Read the returned error first. Kissing-related requests are a documented refusal risk, but image validation, inaccessible files and upstream failures need different fixes. Seedance can also reject photoreal reference inputs; an unexplained 422 is not proof that a face or word caused it. Use a genuinely different creative action only if it still answers your brief.
Why did my Seedance video come back tame?
An older Seedance task, an omitted action or a tighter crop can all yield a milder scene. For a crop issue, reframe the still; for missing motion, simplify the action; for refusal, choose a suitable model rather than adding intensity words.
Is Seedance 2.5 Spicy better for uncensored prompts?
Spicy is not needed for uncensored access: both delivered higher-intensity adult scenes. In two takes each from the same still and prompt, base stayed with a clothed embrace both times; Spicy took the stronger direction once and stayed gentler once. It is a different interpretation to try, not a consistently stronger result. Choose Spicy for an upscaled 4K file; choose base for lower cost and text/reference inputs. Use one clear mood cue on either model. Seedance 2.5 vs 2.5 Spicy has the side-by-side.
How do I keep the same face across Seedance clips?
Reuse the same still or character reference images. Keep hairstyle, wardrobe and light consistent, and assign location reference images only the setting. If a new camera angle changes the face, rebuild the starting still for that angle before adding movement.
Run your first prompt
Create an account, open Seedance 2.5 text-to-video with prompt 3 filled in, and draft it at 480p for $0.62. When the motion is right, run it again at 720p.