MOSS-Image Review: Uncensored NSFW Images With Readable Text
Pick MOSS-Image for posters, covers and ads where the lettering must be right, and for very long prompts; skip it for edits, reference images or quick drafts.
MOSS-Image is OpenMOSS's open-weight text-to-image model, released on 16 October 2026 under the Apache-2.0 licence. OpenMOSS describes it as a roughly 5-billion-parameter diffusion transformer built for English and Chinese lettering, prompts of up to about 4,000 tokens and an experimental JSON layout mode. It makes pictures from text only: no reference images and no editing. SpicyAPI serves it as openmoss/moss-image/text-to-image, with no content filter of our own.
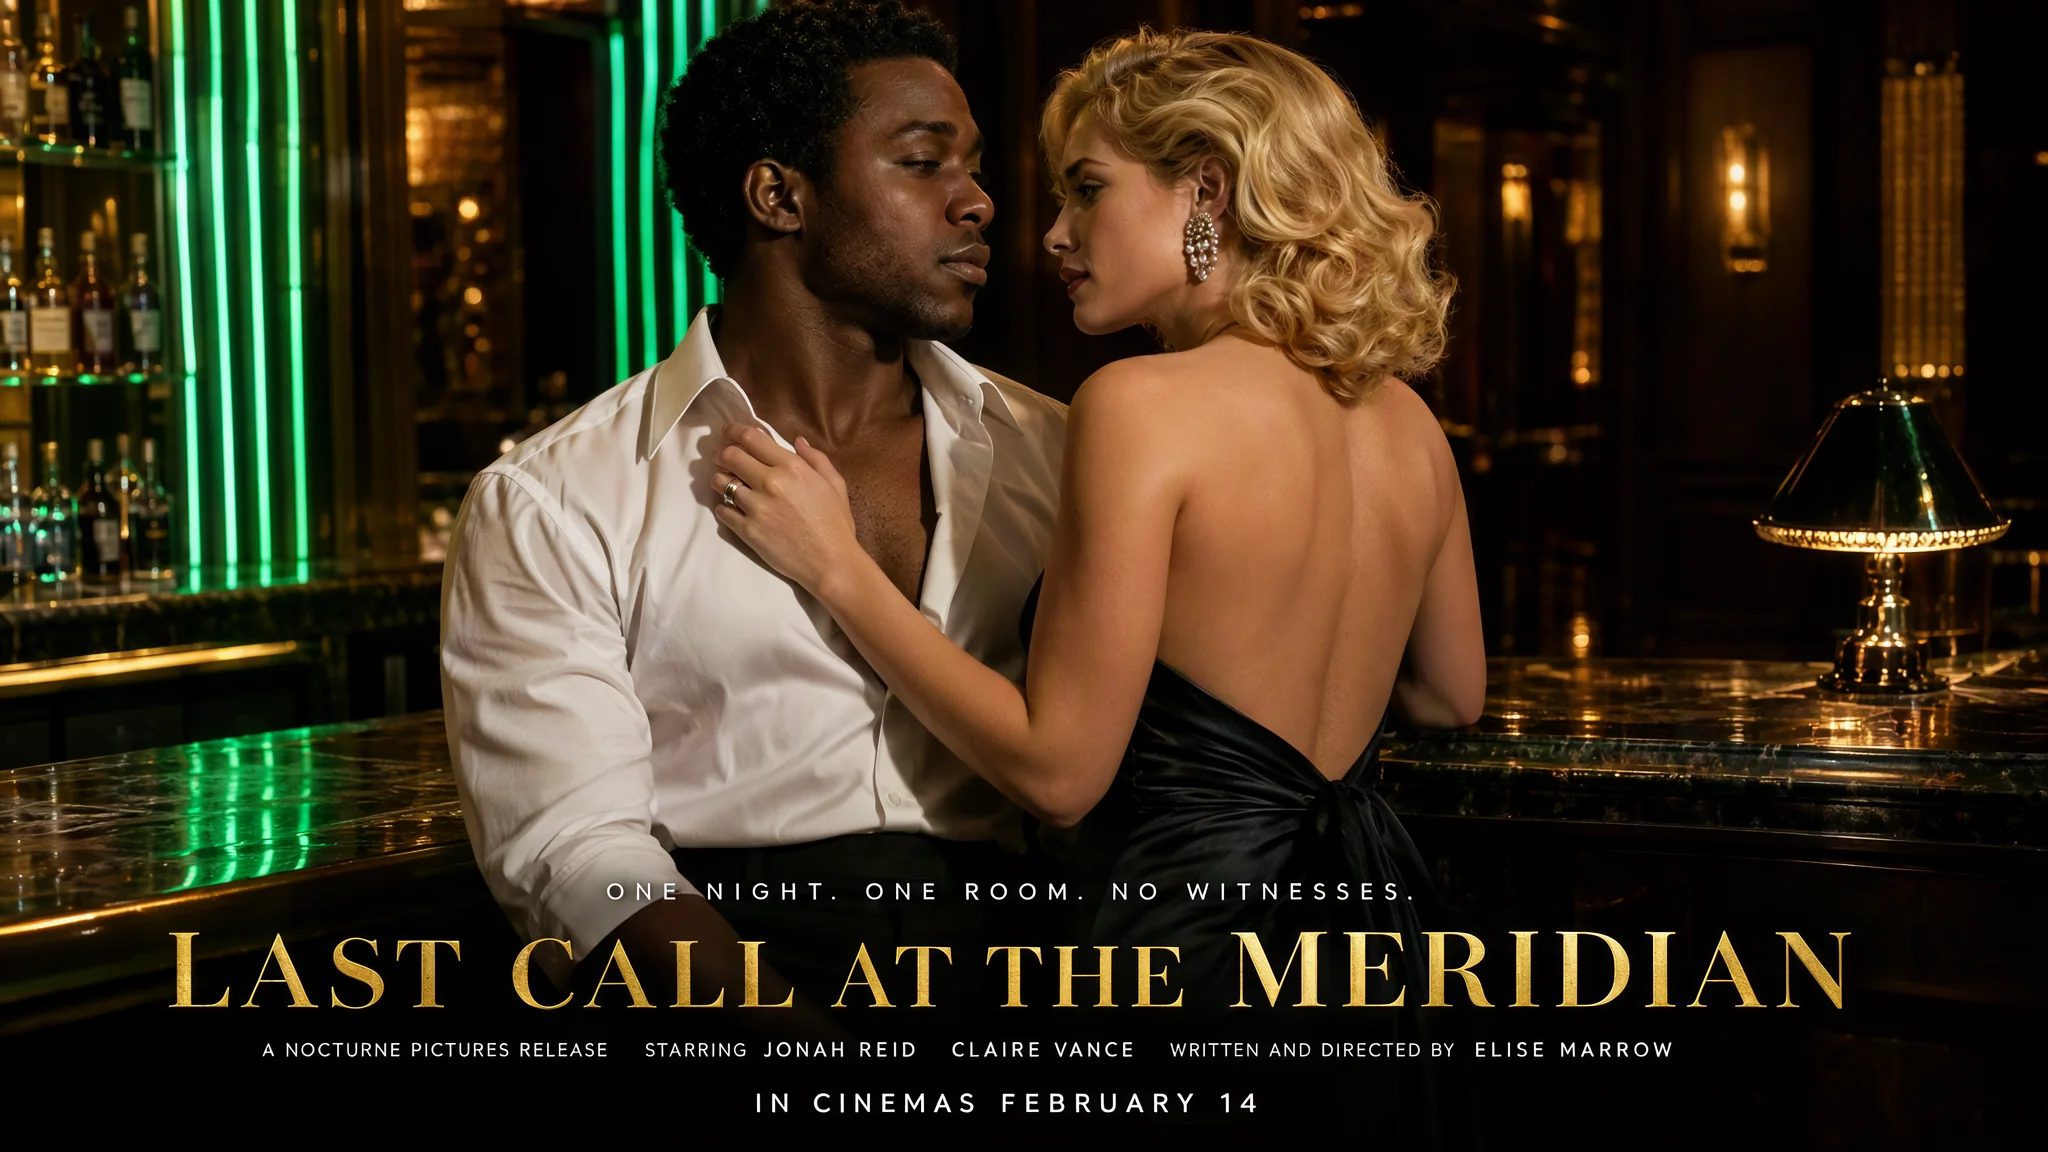
A cinematic film poster, photographed. A Black man in his thirties in an open white dinner shirt and a blonde woman in a backless black satin gown lean toward each other at a dim art-deco hotel bar, her hand on his collar, green-and-gold neon reflected on the polished bar top. Title in large gold serif capitals across the lower third: "LAST CALL AT THE MERIDIAN". Above it, small white capitals: "ONE NIGHT. ONE ROOM. NO WITNESSES." At the very bottom, a narrow white credit block in condensed type: "A NOCTURNE PICTURES RELEASE STARRING JONAH REID CLAIRE VANCE WRITTEN AND DIRECTED BY ELISE MARROW" and "IN CINEMAS FEBRUARY 14".
A vintage-style fashion magazine cover photograph. Masthead across the top in tall elegant serif capitals: "VELVET". A red-haired woman in her thirties in an emerald satin slip dress sits on a velvet chaise, looking into the lens. Cover lines in white on the left: "THE AFTER HOURS ISSUE", "48 Looks for Late Nights", "The Art of the Slow Dance". Small print at the bottom: "No. 07 · OCTOBER 2026 · $9.99" and a barcode.
{"summary": {"meta": ["poster"], "canvas": "single", "caption": "A moody nightclub flyer: deep plum background with a pink neon glow, a dancer silhouette in a sequined dress on the right, bold white condensed type on the left."}, "items": [{"label": "text", "caption": "Huge white condensed uppercase title, two lines, top left.", "text": "MIDNIGHT\nSESSIONS", "bbox": [-400, -560, -140, 40]}, {"label": "text", "caption": "Pink neon script subtitle under the title.", "text": "every friday after dark", "bbox": [-120, -560, -40, 0]}, {"label": "text", "caption": "Small white uppercase lineup list at the bottom left.", "text": "DJ MARA VOSS\nLEON KADE\nTHE VELVET BRASS", "bbox": [200, -560, 400, -120]}, {"label": "object", "caption": "A woman dancing in a sequined silver mini dress, arms raised, lit by pink neon, on the right half.", "bbox": [-420, 80, 440, 560]}], "bbox_coord_space": "abs_centralized", "bbox_format": "yxyx"}
A luxury fragrance advertisement photograph. A Mediterranean man in his thirties with dark stubble and wet slicked-back hair, a black silk shirt open to the sternum, holds a square smoked-glass perfume bottle against his collarbone, looking into the lens. Deep black background, one hard rim light from behind, drops of water on his skin. Large thin white serif wordmark at the top: "NOIR No. 9". Under it in small spaced capitals: "EAU DE PARFUM". At the bottom, an italic line: "Wear the night."
Wide cinematic photograph of a retro desert motel at dusk. A red neon sign on a tall pole reads "MOTEL PARADISO" with a smaller flickering line "VACANCY". A woman in a red one-piece swimsuit and oversized sunglasses lounges on a white chaise by a glowing turquoise pool, a man in an open Hawaiian shirt carries two cocktails toward her. Pink and violet sky, long shadows, 35mm film look.
We tested it on 21 October 2026. Lettering came out right on every poster, cover and sign we tried, a layout written as JSON put four elements where we told it to, and a prompt of 13,196 characters still produced the detail mentioned only in its last sentence. Every content level we tried came back as written. The one flaw we hit in lettering was letters running together in a wordmark on a second seed.
Pick it when the picture is a design: a film poster with a credit block, a magazine cover with small print, an ad with a wordmark, a flyer you want to lay out by coordinates. It is also a fit for long, detailed prompts. Skip it if you need to edit an existing image, feed in references or iterate fast: it is not a quick model, about 20 seconds at 1k and about a minute at 2k.
How it scores. The Spicy Index and Freedom Score are computed by the server and shown on this page's score card; check the card rather than a number printed in this text. We have not run our blind output test on MOSS-Image yet, so this review gives no image-quality score and makes no ranking claim against other models.
Content limits: SpicyAPI adds no filter of its own, and the model weights do not review prompts. On 21 October 2026, seven probe runs across all five intensity levels came back as written; none was toned down or refused.
Parameters:prompt (1 to 12,000 characters), aspect_ratio (15 options, default 1:1), resolution (1k, 1.5k or 2k), output_format (JPEG, PNG or WebP) and seed. One image per request.
Not available: negative prompt, guidance or step controls, reference images, editing, several images per request.
Sizes: at 1k, 1:1 is 1024 by 1024 and 16:9 is 1360 by 768. At 1.5k, 16:9 is 2048 by 1152. At 2k, 9:16 is 1536 by 2720.
Speed: model time at 1k had a median of about 23 seconds (10 to 40); at 1.5k about 38 seconds; at 2k about a minute.
Price: billed per image by resolution tier, with the same price for every aspect ratio and file format and no charge for failed requests. Live prices are on the model page.
Seeds: the same seed keeps a comparison fair, but we do not promise identical pixels.
Lettering that holds up. A film poster with a title, a tagline and a full credit block; a magazine cover with a masthead, three cover lines and a price line; a fragrance wordmark; a neon motel sign; a festival poster in bubble letters. All came out letter for letter.
JSON layout control. OpenMOSS's own layout format goes straight into prompt: a caption for the whole picture plus a list of items, each with text, a description and a box. In our flyer test the title, the neon subtitle, the three-line lineup and the dancer landed where their boxes said.
Long prompts are read to the end. A 13,196-character prompt with one detail in its final sentence, a red umbrella at the lower left, drew that umbrella. The public limit is 12,000 characters, below what we tested.
Every aspect ratio is real. All 15 ratios returned the size we expected, from 1:3 to 3:1 and 9:21 to 21:9.
Larger tiers are native. The 1.5k and 2k tiers are generated at that size, not upscaled.
No content filter. All five intensity levels came back as written on the plain endpoint.
Open weights. Apache-2.0, so the same model can be run elsewhere if you need to.
足りなかった点
Text only. No reference image, no editing, no variations from a source picture. For edits pick another family.
Not fast. About 20 seconds for a 1k image and about a minute at 2k, so it suits finished pieces more than rapid drafting.
Lettering still slips occasionally. On a second seed, the wordmark NOIR came out as NOIIR. Rerun with another seed when exact spelling matters.
The JSON mode is experimental. OpenMOSS labels it that way, and coordinates must be worked out for the real output size: 1168 by 880 for 4:3 at 1k, with the origin at the centre of the canvas.
No negative prompt or step controls. What you do not want has to be left out of the prompt, not subtracted.
Seeds are not a guarantee. Expect close, not identical, repeats.
We have no blind quality score yet. Fine detail, hands and crowds were not scored against other models.
What the images look like
The gallery holds the five published MOSS-Image examples, made at 1k to 2k. Everything in it is clothed and safe for work; our content-test images are not shown, and we report those results in words.
A poster with a credit block. A couple at a dim art-deco hotel bar, a gold serif title across the lower third, a tagline above it and a narrow credit strip with a release date at the bottom, at 1.5k and 16:9. Every word is spelled right.
A magazine cover. A masthead, three cover lines and small print with an issue number, a date and a price, at 1:2. The small print is the hard part and it held.
A flyer laid out by coordinates. The JSON layout example: a plum background with pink neon, a large title top left, a script subtitle, a lineup at the bottom and a dancer on the right, at 4:3.
A product ad at 2k. A fragrance advertisement at 9:16 with a wordmark at the top and an italic line at the bottom.
A wide banner. A desert motel at dusk with a red neon sign at 21:9, the sign text correct.
Prompts that worked
MOSS-Image reads plain sentences. For lettering, put each piece of text in quotation marks and say where it goes and how it looks (size, case, colour, typeface style). Write line breaks as real new lines to control how text wraps. We wrote every prompt in English. Every adult in a prompt should be written as an adult.
1. A magazine cover with small print. 1:2, 1k, seed 7.
text
A vintage-style fashion magazine cover photograph. Masthead across the top in tall elegant serif capitals: "VELVET". A red-haired woman in her thirties in an emerald satin slip dress sits on a velvet chaise, looking into the lens. Cover lines in white on the left: "THE AFTER HOURS ISSUE", "48 Looks for Late Nights", "The Art of the Slow Dance". Small print at the bottom: "No. 07 · OCTOBER 2026 · $9.99" and a barcode.
2. A layout written as JSON. Pass this as the whole prompt, 4:3, 1k. Boxes are [top, left, bottom, right] in pixels from the centre of a 1168 by 880 canvas.
text
{"summary": {"meta": ["poster"], "canvas": "single", "caption": "A moody nightclub flyer: deep plum background with a pink neon glow, a dancer silhouette in a sequined dress on the right, bold white condensed type on the left."}, "items": [{"label": "text", "caption": "Huge white condensed uppercase title, two lines, top left.", "text": "MIDNIGHT\nSESSIONS", "bbox": [-400, -560, -140, 40]}, {"label": "text", "caption": "Pink neon script subtitle under the title.", "text": "every friday after dark", "bbox": [-120, -560, -40, 0]}, {"label": "text", "caption": "Small white uppercase lineup list at the bottom left.", "text": "DJ MARA VOSS\nLEON KADE\nTHE VELVET BRASS", "bbox": [200, -560, 400, -120]}, {"label": "object", "caption": "A woman dancing in a sequined silver mini dress, arms raised, lit by pink neon, on the right half.", "bbox": [-420, 80, 440, 560]}], "bbox_coord_space": "abs_centralized", "bbox_format": "yxyx"}
3. A long, detailed brief. There is no need to trim. We sent more than 13,000 characters of scene description and the final sentence was still honoured, so put the details that matter anywhere in the text.
Weak: "a poster for a movie called Last Call". It leaves the model to invent every other word on the poster. Strong: prompt 1, with each string quoted and placed.
How far it goes
On 21 October 2026 we ran our standard content ladder on the plain endpoint with no LoRA: five intensity levels from Mild to Maximum, seven probe runs in total, one run each, with a male-subject version of Strong and two kinds of Maximum. Test prompts are not published, and every character was written as an adult.
Level
Result
Mild
delivered as written
Moderate
delivered as written
Strong
delivered as written (female and male subjects)
Very strong
delivered as written
Maximum
delivered as written (both types)
Nothing was refused, nothing was toned down and no clothing was substituted. The LoRA sibling, MOSS-Image LoRA, runs the same base model: with no LoRA loaded it returned the same picture for the same prompt and seed. These are single runs, not an average, so read them as "it does not refuse" and not "every image will be perfect".
Adults only, in every prompt and output. Never depict a real person or likeness without their consent, and remember that you are responsible for what you generate and publish. Generated media is kept for 14 days and then deleted.
Alternatives
Your own LoRA files?MOSS-Image LoRA is the same model with up to three LoRA slots.
A photoreal generalist?Z-Image Turbo is a different family worth comparing on speed.
Edits as well as new images?Qwen Image 3.0 takes source images.
Another unfiltered option?Seedream 5.0 Flash is a text-to-image and edit family.
Yes. We add no content filter and the model weights do not review prompts. On 21 October 2026 all seven of our probe runs, across the five intensity levels, came back as written.
Yes, and it is the reason to pick it. Posters, covers, signs and ads came out letter for letter in our tests, with one run on a different seed where letters ran together.
You pass OpenMOSS's layout format as the prompt: a caption for the picture and a list of items with text, description and a box in pixels from the canvas centre. OpenMOSS labels it experimental. It worked on our flyer test.
No. It is text-to-image only and takes no reference images.
Up to 12,000 characters. We tested 13,196 and a detail from the last sentence still appeared.
About 20 seconds at 1k, 40 seconds at 1.5k and a minute at 2k.
It is billed per image by resolution tier and failed requests are not charged. See the live price on the model page.