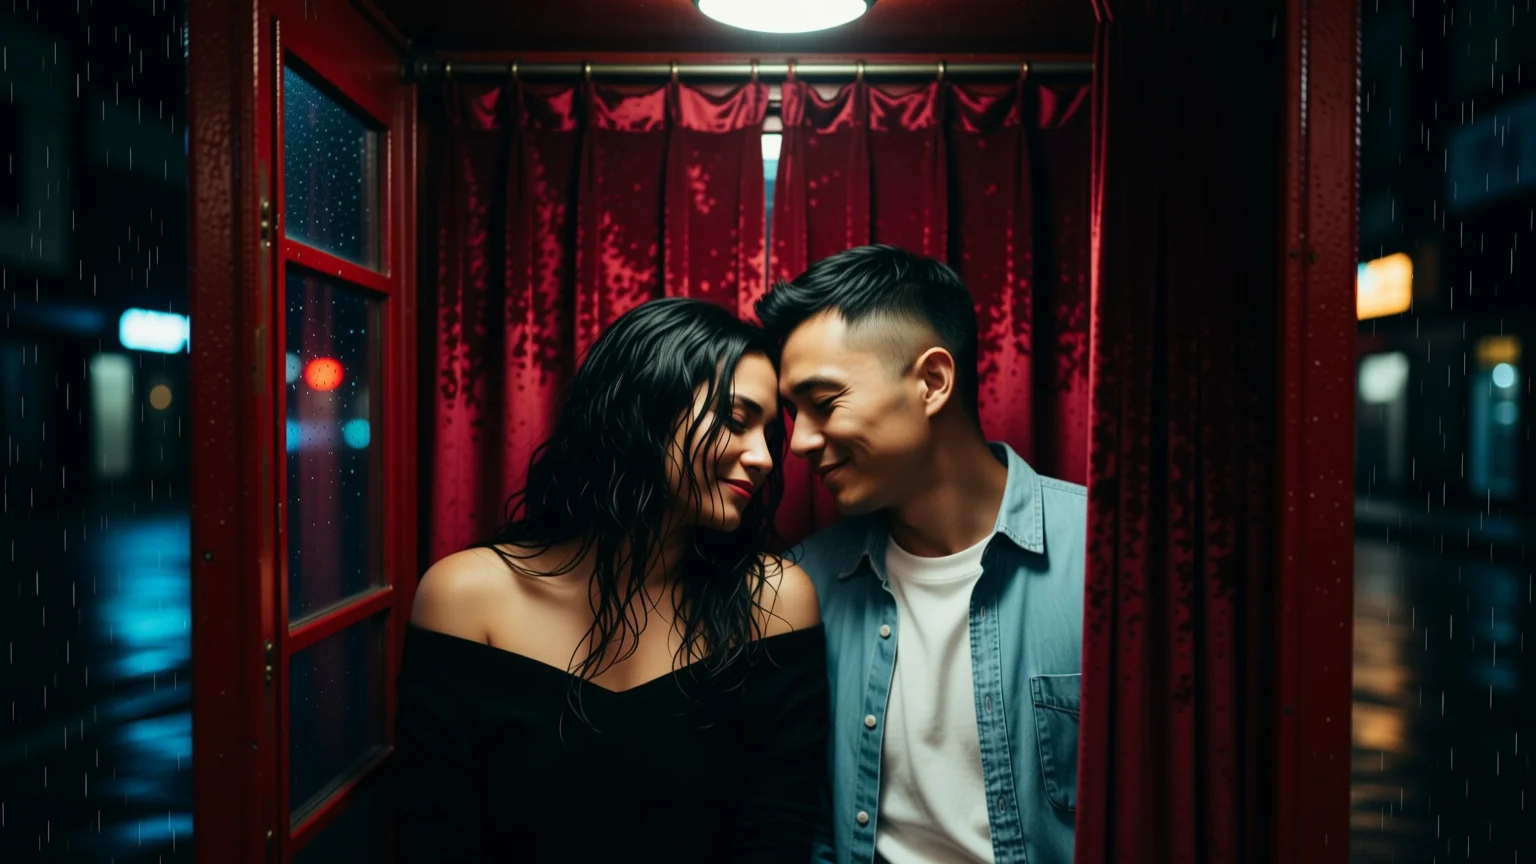
Qwen Image Edit 2509 LoRA edits and combines one to three source images with Alibaba's 20B Qwen-Image-Edit-2509 and up to three of your own LoRAs at strengths from 0 to 4. Faces stay consistent across sources, nine aspect ratios are optional, one flat price per image and no content filter.

From $0.03/image

Workbench

Input

Image editing
388/5000

Reordering updates prompt references. Removing media also removes its references; review your prompt.

Say what each picture contributes and what should change. Some edit LoRAs expect a fixed phrase, such as "Next Scene:" or "transform into anime"; the LoRA card gives it. Up to 5,000 characters. at least 1 characters · at most 5000 characters
2/3

Drop files or media links, paste, or browse · Up to 3 files · Max 10 MB · JPG · PNG · WEBP · GIF

  • Picture 1
  • Picture 2
2 / 3 files
One to three source images as public HTTPS links or uploads, up to 10 MB each, addressed in the prompt as Picture 1, Picture 2 and Picture 3. Without aspect_ratio the result follows the first image's shape. at least 1 items · at most 3 items
Optional. Leave it empty and the result follows the first source at about one megapixel. Pick one of nine ratios to reframe the edit: 1:1 is 1328 x 1328, 9:21 is 656 x 1536 and 16:9 is 1536 x 864. Every ratio costs the same.
Style LoRAs0/3
Up to three {path, scale} entries. path is a direct HTTPS link to a .safetensors file trained for Qwen-Image-Edit-2509 (original Qwen-Image-Edit LoRAs load too); scale runs from 0 to 4, default 1. No extra charge. at most 3 items
Output format
JPEGPNGWebP
JPEG by default, PNG or WebP if you need them. Does not change the price.
Seed
Keeps edits comparable while you change the instruction or a LoRA scale. Any whole number from 0 to 2147483647; leave it empty for a random seed. no lower than 0 · no higher than 2147483647
Safety checkerOff

SpicyAPI does not run a safety checker on this model. Your prompt and media go to the model as written, and the model itself decides what comes back.

Checking your account before enabling submission and pricing.

Output

Ready for a new run
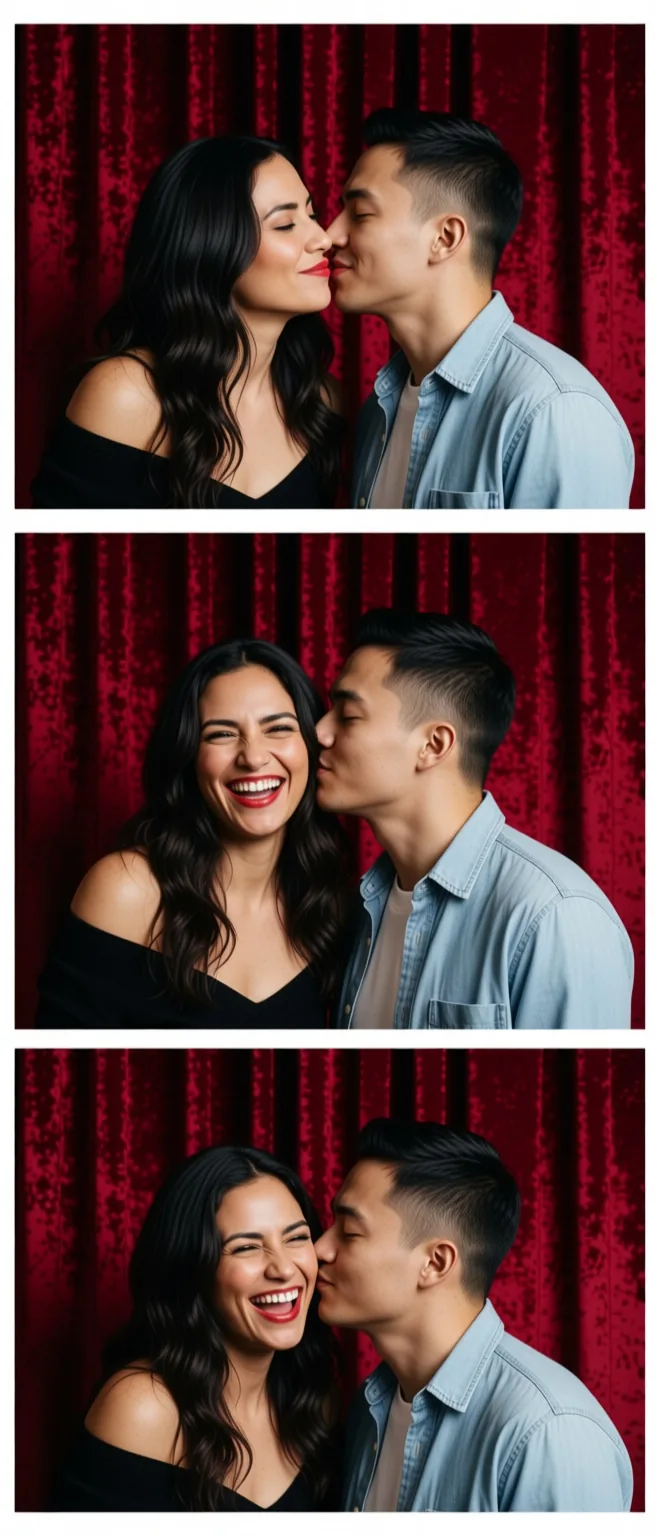
booth-strip-duoExample result

Missing the model you need?

Tell us what to add and where you would use it. Requests go to the people who decide what gets onboarded next.

LORA EDIT API

Qwen Image Edit 2509 LoRA API at a glance

Qwen-Image-Edit-2509 with your own LoRAs: one to three sources, faces kept, nothing filtered.

Sources per edit
3
Combine up to three images, addressed as Picture 1, 2 and 3.
LoRAs per call
3
Up to three weight files, each with its own strength from 0 to 4.
Parameters
20B
Qwen-Image-Edit-2509, Alibaba's September 2025 open release.
Per edit
~12 s
Median model time across our test runs; a new LoRA file adds a few seconds.
Price per image
Flat
Same price for one, two or three sources and any number of LoRAs.
Content filter
None
Uncensored: nothing was refused or blurred in our tests.

Results

What you can make with Qwen Image Edit 2509 LoRA

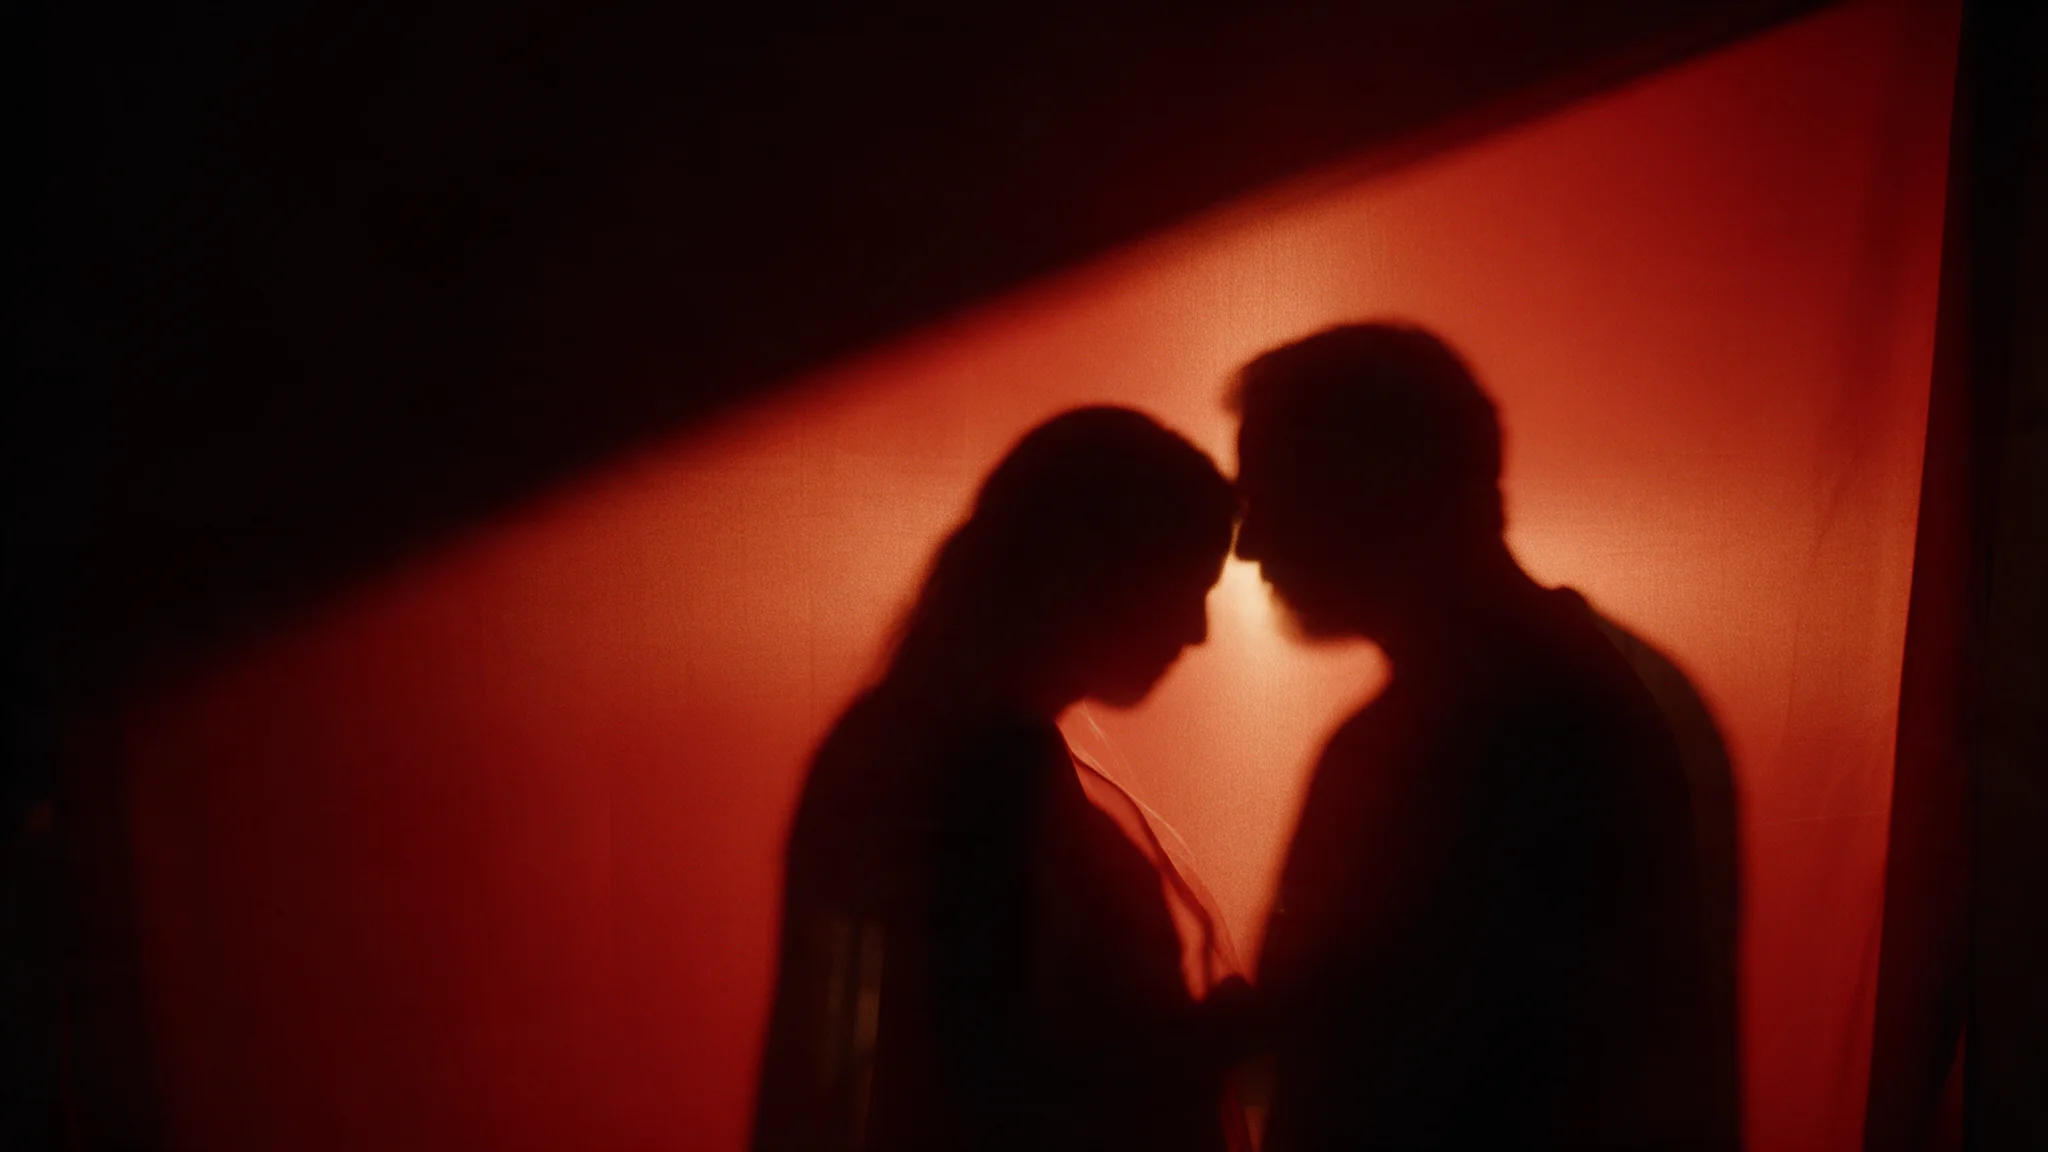
  • Three-frame photo-booth strip of a smiling woman with long dark waves and red lipstick and a man in a light denim shirt kissing and laughing in front of a red velvet curtain

    Two sources

    Two portraits, one photo-booth strip

    A studio portrait of her and one of him became a three-frame booth strip in front of a red curtain: a kiss, a laugh and a cheek kiss, with both faces held in every frame.

    Two sources, no LoRA, 9:21.

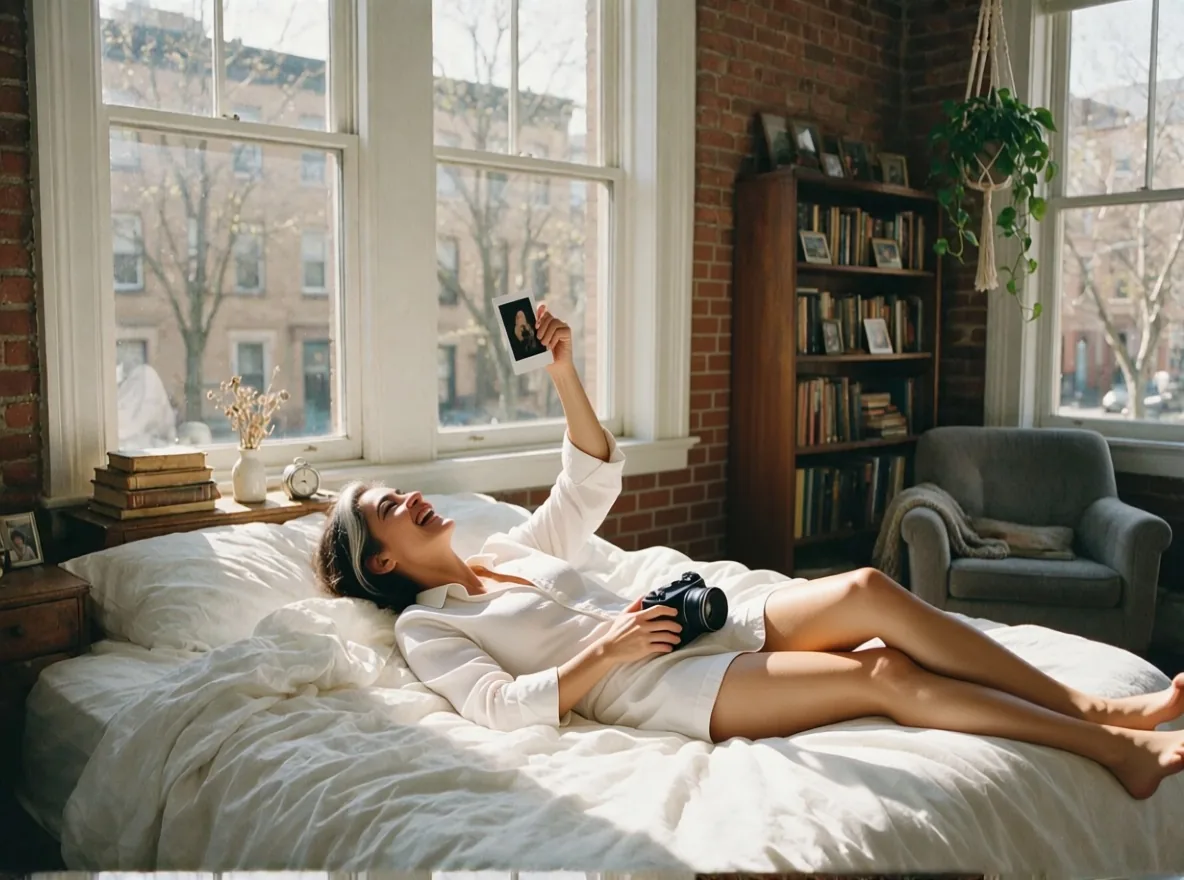
  • Wide photograph of a woman with a silver-streaked bob in a white shirt in a sunlit loft, laughing at an instant photo she holds up, a camera in her other hand

    Next-scene LoRA

    The same loft from a new angle

    From a photo of a woman aiming an instant camera in a sunlit loft, the next-scene LoRA staged the following shot: a wide view of the room as she laughs at the fresh print.

    One source with the next-scene LoRA at 1.

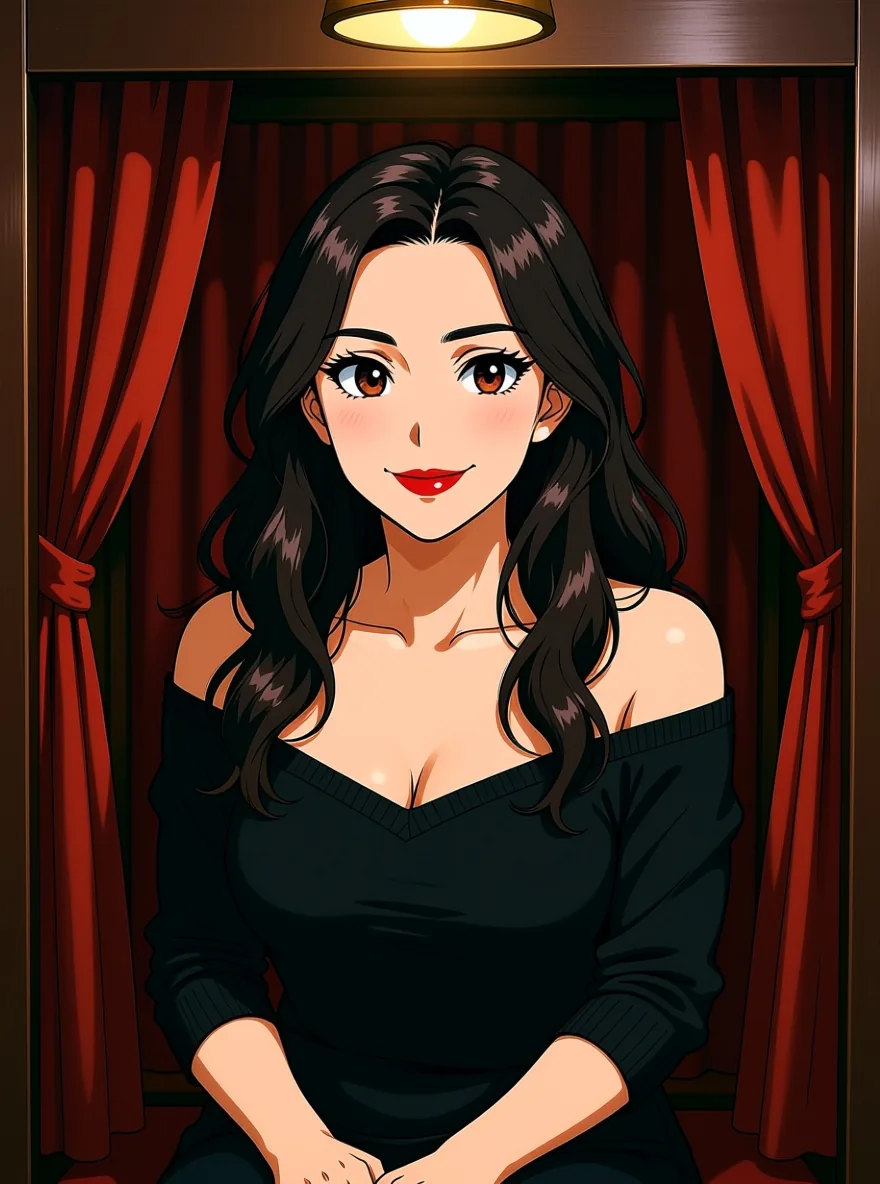
  • Anime illustration of a woman with long dark waves, red lipstick and an off-the-shoulder black top seated in a booth with red curtains

    Photo-to-anime LoRA

    A portrait redrawn as anime

    A photo-to-anime LoRA redrew a studio portrait as a cel-shaded woman in her thirties in a red-curtained booth, keeping her off-the-shoulder top and red lipstick.

    One source with a photo-to-anime LoRA at 1.

Content test

Is Qwen Image Edit 2509 LoRA uncensored? What we tested

We ran each level on our live setup and checked every clip frame by frame. A pass means the content was actually on screen, not just that the request went through.

Content levels tested on Qwen Image Edit 2509 LoRA, by mode
LevelImage editing
MildThe lightest prompts in the test
RendersTested Oct 9, 2026
ModerateWhere filtered models start to refuse
RendersTested Oct 9, 2026
StrongThe middle of the scale
RendersTested Oct 9, 2026
Very strongWhere most models start to hold back
Not tested yet
MaximumThe top of the scale
RendersTested Oct 9, 2026

Renders: on screen as written. Softened: generated, but milder than what was written. Refused: rejected. Not tested yet: we have not run that level on that mode.

How each mode behaves

All modes
At most three source images and three LoRAs per request, and one image back. With several sources, vague prompts can mix people up: in one of our test strips a frame showed the same man twice, so name each person's picture. LoRAs for other model families, such as FLUX, do not bring their style, and a link that needs a login fails. The Very strong level comes back without refusal but toned down.

Use cases

What to build with the Qwen Image Edit 2509 LoRA API

  • Two people, one picture

    Put a person from one photo next to a person from another in a new setting, with both faces kept.

  • New shots from one photo

    A next-scene LoRA re-stages a photo from another angle with the same person and room, for storyboards and photo sets.

  • Photo to illustration

    A photo-to-anime LoRA turns a portrait into a cel-shaded drawing of the same person, outfit and lipstick.

  • Uncensored edits

    Sources, instructions and results are not filtered, and unfiltered LoRAs load without review.

Prompts

Qwen Image Edit 2509 LoRA prompt examples you can copy

Paste one into the playground as it is, then change one thing at a time.

  • Image editing

    Two portraits, one photo-booth strip

    A vertical strip of four photo booth frames of the woman from Picture 1 and the man from Picture 2 squeezed together in one booth, top to bottom: both pulling faces, her cheek pressed to his, him whispering in her ear while she laughs, and a last frame where they lean in close with eyes closed, about to kiss. Hard flash, red curtain, slightly faded colour print with thin white borders.

    Why it works. Two studio portraits and a 9:21 frame. The prompt asked for four frames and the model drew three; both faces held in each one.

    This mode starts from your own image: add it in the playground before you run.

    Try this prompt
  • Image editing

    The loft, next scene

    Next Scene: a wide shot from the foot of the bed; she now lies back across the rumpled white sheets, holding the fresh instant print above her face and laughing at it, the camera resting on her stomach, morning light pouring through the tall windows.

    Why it works. The next-scene LoRA at 1 with a prompt that starts with "Next Scene:" and names the new camera position.

    This mode starts from your own image: add it in the playground before you run.

    Try this prompt
  • Image editing

    Photo booth to anime

    transform into anime: a mature woman in her thirties with a grown-up face, sitting inside a retro photo booth with a red velvet curtain, lit by the booth flash, same off-the-shoulder black top and red lipstick.

    Why it works. A photo-to-anime LoRA at 1. Writing "a mature woman in her thirties with a grown-up face" kept the drawing true to the adult in the photo.

    This mode starts from your own image: add it in the playground before you run.

    Try this prompt

Pricing

Qwen Image Edit 2509 LoRA API pricing

One image starts at $0.03.

The playground shows the exact price for your settings before you run. Failed or timed-out tasks are usually not charged. Some models charge for content refusals as stated on their model page; check those billing terms before submitting.

See every price tier

Get started

How to use the Qwen Image Edit 2509 LoRA API in three steps

  1. Step 1

    Say what each picture brings

    With two or three sources, name them: the woman from Picture 1, the man from Picture 2, the room from Picture 3. Our two-portrait photo-booth strip kept both faces in every frame.

  2. Step 2

    Use edit LoRAs for repeatable looks

    LoRAs trained for 2509, such as next-scene and photo-to-anime, turn a short instruction into a specific edit. LoRAs made for the original Qwen-Image-Edit load too: a relighting one changed the light clearly here.

  3. Step 3

    Give a camera direction for a new shot

    The next-scene LoRA wants a prompt that starts with "Next Scene:" and a camera move. "A wide shot from the foot of the bed" re-staged our loft photo from a new angle.

Parameter reference and code samples are in the API and Readme tabs at the top of this page.

Why SpicyAPI

Why run Qwen Image Edit 2509 LoRA on SpicyAPI

  • No filter from us

    We add no content filter of our own. What the model renders is what you get back.

  • Tested, not guessed

    Content labels come from real generations we ran and checked, with the test date on the page.

  • Pay per result, in dollars

    No subscription and no credits. Failed or timed-out tasks are usually not charged. Some models charge for content refusals as stated on their model page; check those billing terms before submitting.

  • One key for every model

    One API key and balance cover image, video, audio and chat models, so you can explore more models from the same account.

FAQ

Qwen Image Edit 2509 LoRA API FAQ

About Qwen Image Edit 2509 LoRA

Qwen Image Edit 2509 LoRA puts Alibaba's Qwen-Image-Edit-2509 behind your own LoRAs: one to three sources per edit, faces kept across them, up to three weight files, nine aspect ratios and one flat price per image. Nothing is filtered.

Related models and next tasks