HunyuanVideo 1.5 follows a prompt best when it reads like a shot list: one adult, what they wear, two or three small actions in order, one camera move and the light. Across 50 adult-content runs on 5 October 2026, every request from L1 to L3 came back as written (26 of 26), while all 8 intimate scenes between two adults came back softened, so that is where rewording stops paying. On image-to-video the start frame does most of the work: small actions kept the face from the photo, and asking for a new place replaced it.
The full content ladder, sizes, speeds and the comparison with LTX-2 are in our HunyuanVideo 1.5 NSFW test. This guide is about the prompt: which wording the model follows and which it ignores, shown with side-by-side clips we ran for this guide. Every prompt printed here is a clothed adult scene at the suggestive end, and you can run them from the HunyuanVideo 1.5 family page.
At a glance
| HunyuanVideo 1.5 prompting, from our runs | |
|---|---|
| Prompt shape that worked | Subject, wardrobe, two or three action beats in order, one camera move, light and look |
| Mood adjectives ("sultry", "seductive") | A posed stare and little movement, in both test seeds |
| L1 to L3 | 26 of 26 delivered, both endpoints |
| L4, two adults | 0 of 8 delivered: all softened, none refused |
| L5 | Restraint 7 of 8 delivered, cinematic gore 6 of 8 |
| Negative prompt | Text-to-video only. Cuts down artefacts, never a guarantee |
| Image-to-video prompt | Optional. Describe the next moment in the same place |
| Settings | 480p or 720p, 5 or 8 seconds, silent; 16:9 or 9:16 on text-to-video; image-to-video keeps the photo's shape |
| Price | $0.024 per second at 480p, $0.048 at 720p ($0.12 for a 5-second draft) |
The five slots HunyuanVideo 1.5 reads
Tencent's HunyuanVideo 1.5 prompt handbook builds a text-to-video prompt from subject, motion and scene, with shot, camera, lighting, style and atmosphere as extras. It asks for actions in time order ("first… then… finally") and for emotions written as small physical details. For adult-oriented clips we split the subject in two, because the wardrobe line is where the level of the scene lives.
| Slot | What to write | Our example |
|---|---|---|
| 1. Subject | One adult: age range, hair, one defining detail | An adult woman in her early thirties |
| 2. Wardrobe | Garment, fabric, colour, and its state | in a black satin slip dress |
| 3. Action beats | Two or three small actions with "first", "then", "finally" | slides one strap back onto her shoulder, glances back at the camera, smiles |
| 4. Camera | One move: push-in, orbit, locked, handheld | Slow push-in |
| 5. Light and look | The light source, plus a short style tag | warm lamp light, cinematic, photorealistic |
The place goes between the subject and the action. The full prompt:
An adult woman in her early thirties in a black satin slip dress stands by the window of a dim hotel room at night, city lights behind her. First she slides one strap back onto her shoulder, then she glances over her shoulder at the camera, and finally she lets a slow, knowing smile break. Slow push-in, warm lamp light, cinematic, photorealistic.Open this prompt in HunyuanVideo 1.5 text-to-video →
Three habits made the biggest difference in our runs:
- One adult per clip unless the scene needs two.
- Name the room by what is in it. In both two-person clips on seed 62001 (see below), "hotel bar" came back as a hotel room with a bed. If the place matters, list the counter, the stools and the bottles.
- Keep the subject line fixed while you iterate. Changing one sentence redraws the whole person, even on the same seed.
Mood words or action details
Adult prompts tend to pile up mood words. We ran the prompt above against the same prompt with the action sentence replaced by "She is sultry, seductive and sensual, radiating desire." Same seed, same negative prompt, 480p, 5 seconds, two seeds each.
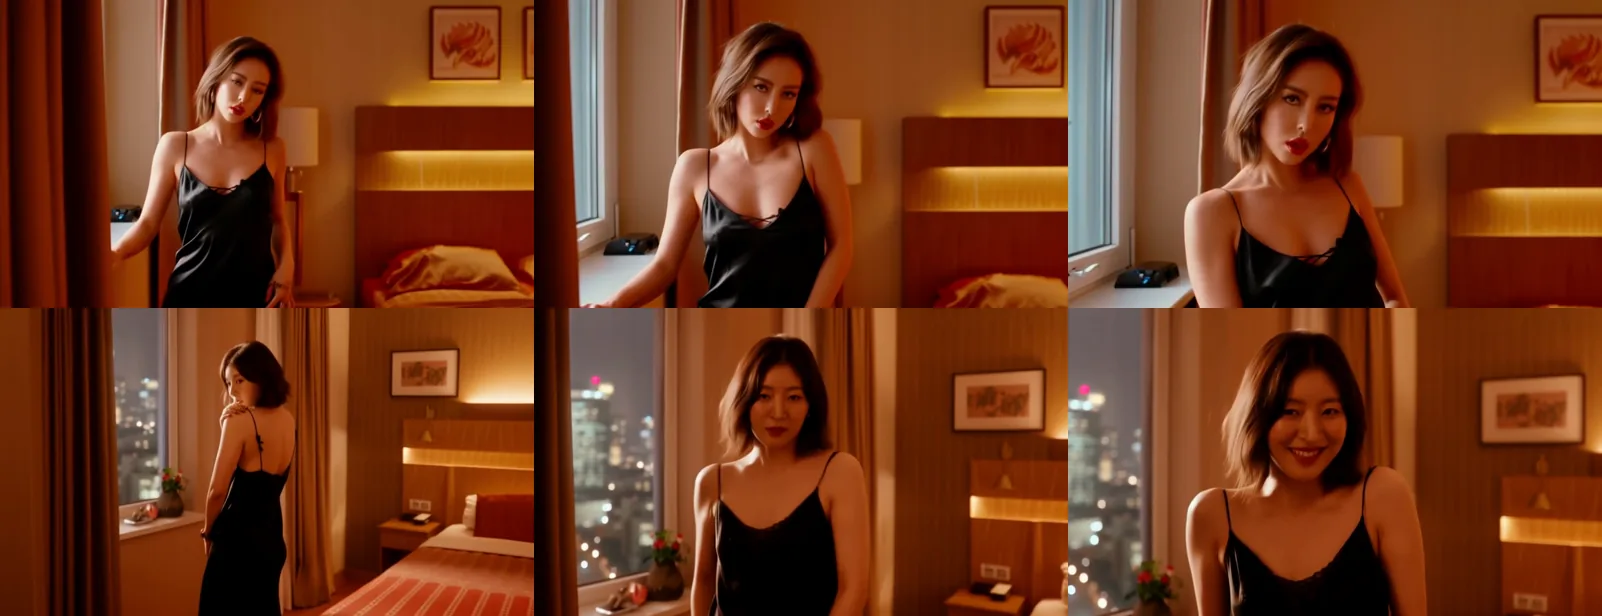
Text-to-video, 480p, seed 61002, start, middle and end of each clip. Top: the mood-word prompt. Bottom: the action-beat prompt. Seed 61001 behaved the same way.
The adjectives produced a fashion-shoot pose: parted lips, a fixed stare, a hand held still, and the push-in doing all the moving. In this seed the night city behind her also disappeared. The action version moved through all three beats in both seeds and ended on the smile, although the first two beats ran together (she was already looking back as her hand went to the strap). That is the usual cost of three actions in five seconds.
The rule: write what the viewer should see happen, not how it should feel. "A slow, knowing smile" does the work of "seductive", and the model can draw it.
Pick gestures the model knows
The prompt behind this guide's cover asked a man on a hotel balcony to "loosen one cuff", then hold a look at the camera, then half-smile. In both seeds the cuff never moved: one man pulled his collar open, the other rested a hand at his collar and chin. The look came through both times.
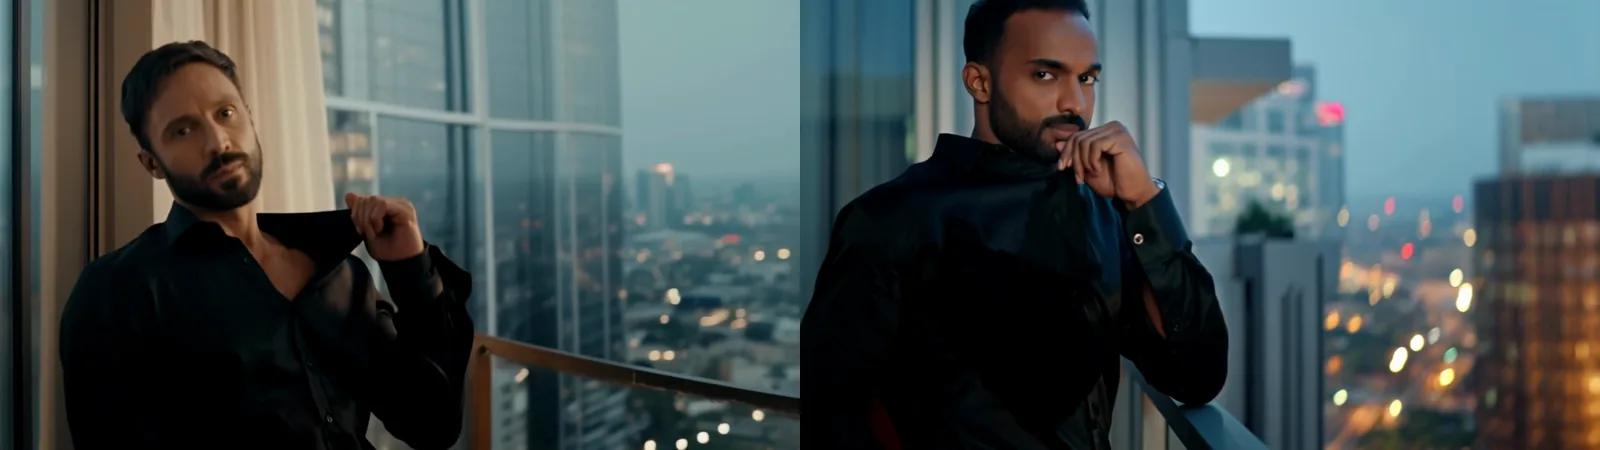
Text-to-video, 720p, the same prompt on seeds 64001 (left) and 64002 (right). The prompt asked him to loosen one cuff.
Unusual small gestures get swapped for familiar ones. If a gesture matters, pick one the model has plainly seen many times (a hand through the hair, a strap slipping, a collar adjusted) and check it in a 480p draft first.
How far to push, level by level
Nothing on our side filters the prompt, the photo or the result. What changes between levels is how the model itself responds, and that decides whether another rewrite is worth paying for. These numbers pool both endpoints across 50 runs on 5 October 2026, at 480p and 5 seconds, all subjects adults. We do not print prompts above L1.
| Level | What it means | Delivered | For your prompt |
|---|---|---|---|
| L1 Suggestive | Lingerie, a slipping strap | 8 of 8 | Name the garment and the one thing that happens to it |
| L2 Partial | Partial-level prompt | 8 of 8 | Same five slots; the wardrobe line and one action carry the level |
| L3 Strong | Strong-level prompt | 10 of 10 | Same; one person, one action |
| L4 Intense | An intimate scene between two adults | 0 of 8 | Softened every time. Do not spend retries here |
| L5 Extreme | Consensual restraint between adults, or cinematic gore | 7 of 8 and 6 of 8 | The misses kept the props or the blood but left out part of the scene |
No run was refused or blurred. At L4, text-to-video gave two tangled or cropped figures on a bed without drawing the scene in all four runs, and image-to-video cut away from the start frame to a new bedroom shot with nobody else in it (all three probes in our second run). We saw no refusal or blur, so this looks like the model's own restraint, not a filter. The practical ceiling for adult work is one adult per clip, where every L1 to L3 run came through. The HunyuanVideo 1.5 review puts its Freedom Score at 88.1.
Two adults in one clip: one touch point
Two people in close contact is this model's weak spot. We wrote one moment two ways: a full embrace ("They wrap their arms around each other and sway pressed close together, her face buried in his neck") and a single touch point with space between them:
An adult couple in their thirties in a dim hotel bar at night, she in a dark green satin dress on the left, he in a white shirt with rolled sleeves on the right. They stand a hand's width apart; her palm rests flat on his chest and his hand rests at her waist. She leans in until her forehead touches his, then they both smile. Warm amber light, slow push-in, cinematic, photorealistic.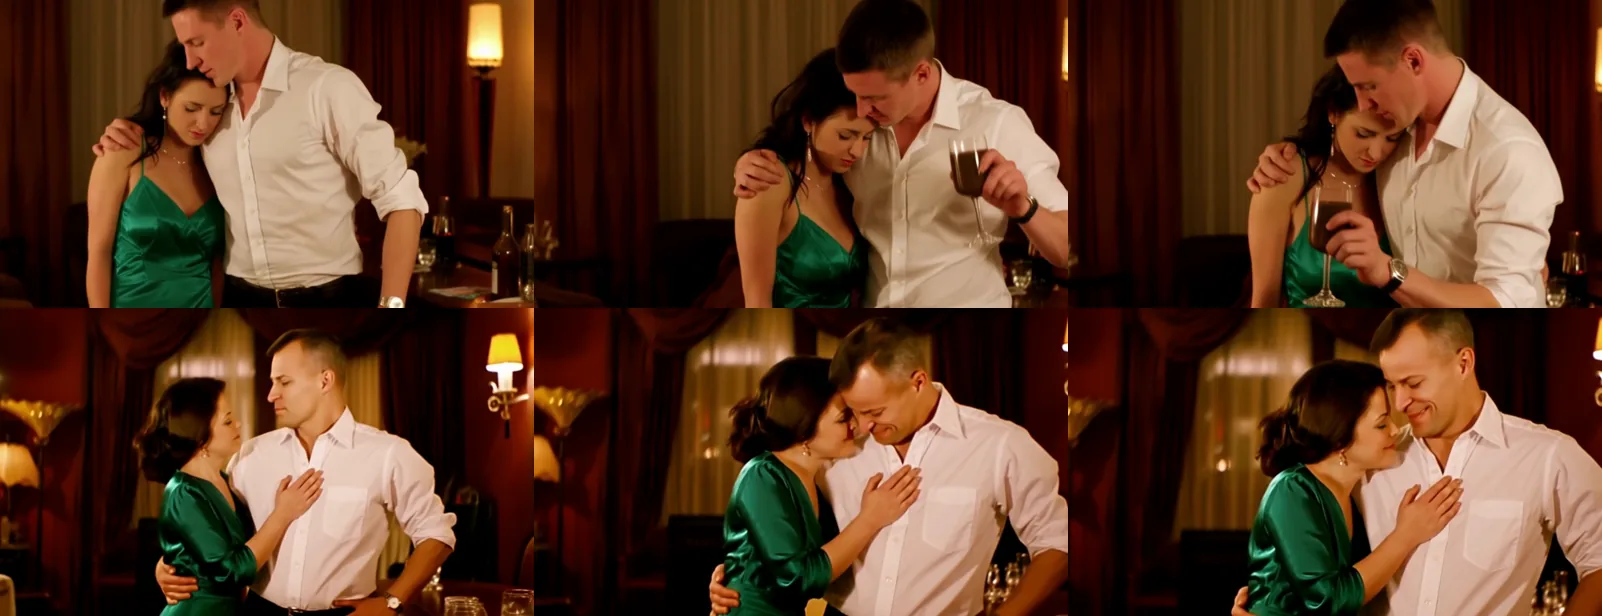
Text-to-video, 480p, seed 62002. Top: the full-embrace prompt. Bottom: the touch-point prompt.
The embrace never happened as written. In this seed it became a side hug while he drank from a glass nobody asked for; in the other, their hands blurred together at her shoulder. The touch-point version delivered every beat in both seeds: palm on chest, hand at the waist, foreheads together, two smiles. Left and right were followed in one seed and swapped in the other, so treat positions as a hint.
For two people: give each a distinct outfit, describe one or two points of contact and the space between them, and end on a facial beat.
The negative prompt: what it is for
Text-to-video takes a negative_prompt; image-to-video does not. The publisher's own code leaves it empty by default and its handbook does not mention it, so treat it as a list of things you never want in frame. Our starter list:
blurry, distorted hands, extra fingers, extra limbs, text, watermarkWhat it did and did not stop in our example runs on 5 October:
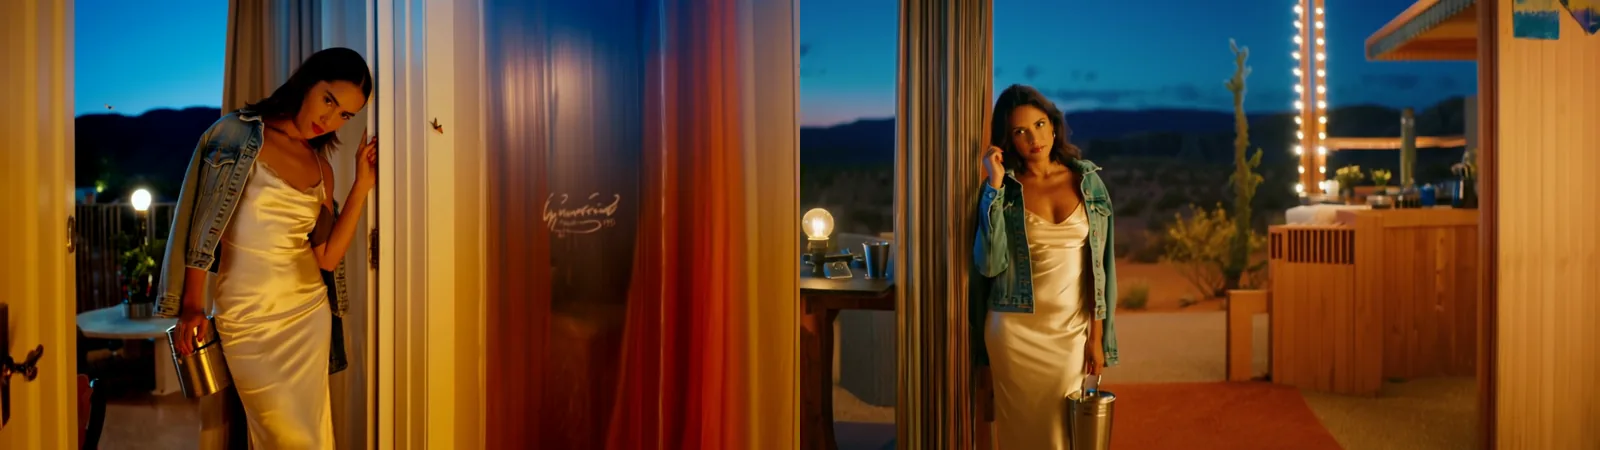
Text-to-video, 720p, the same prompt and negative prompt (which lists "text, lettering, logo") on two seeds. The left clip still drew script on the curtain.
That prompt also said "no signs or lettering anywhere". HunyuanVideo 1.5 is built to render text (its handbook shows it writing quoted words into scenes), and in our runs it invented lettering on curtains, number plates and car badges. The negative prompt lowers the odds; a new seed is the cheapest retry for what slips through.
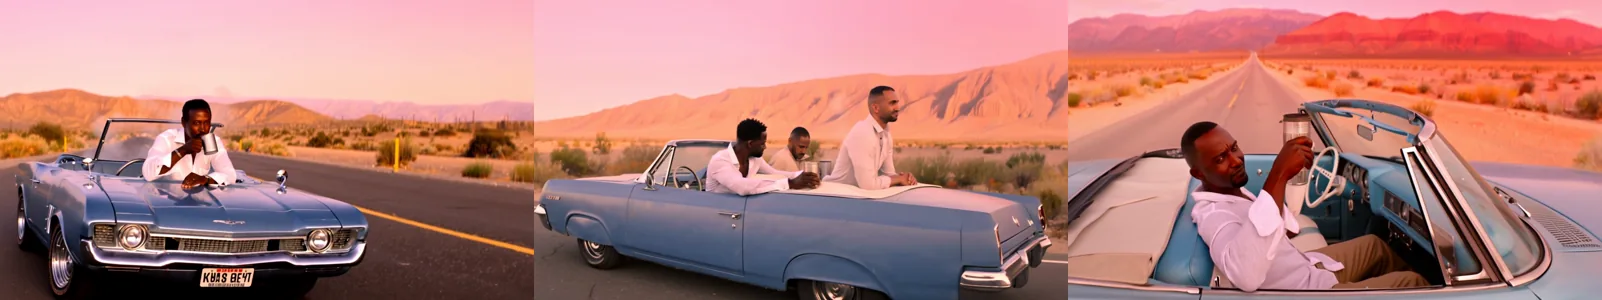
Text-to-video, 720p, three versions of one shot. Left: "no number plate, no lettering" in the prompt, no negative prompt. Middle: a negative prompt without "extra people". Right: "extra people" added and the camera moved in close.
Two lessons. The negative prompt only covers what you name: the middle clip asked for one man and got three, and adding "extra people" fixed it. And the frame is a stronger fix than the list: wide shots gave the model room to invent plates, badges and passengers, while the close shot left only a small chrome mark in the opening second. In adult scenes, watch mirrors, posters and screens in the background the same way.
Image-to-video: the start frame does the heavy lifting
On the image-to-video endpoint, the photo fixes the face, the wardrobe, the light, the shape of the frame and the starting level of the scene. The prompt only says what happens next, in the publisher's order: subject motion, scene motion, camera. It is optional, and there is no negative prompt field.
We gave one start frame two prompts, two seeds each: one that stays in the photo and one that walks out of it. The frame is a 3:4 still made with the Jib Mix Qwen image model, a common way to set up a character before animating it.
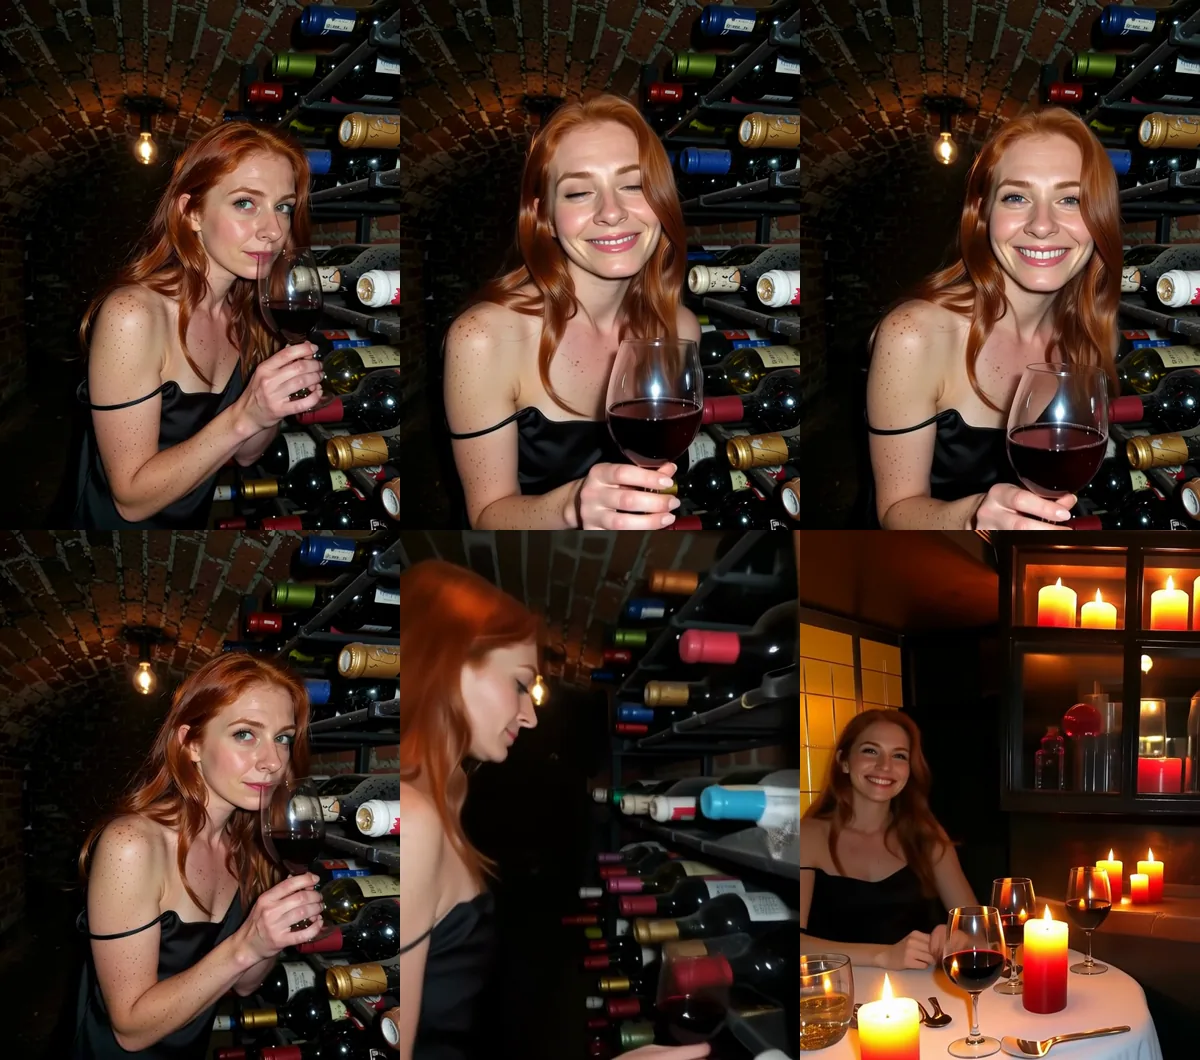
Image-to-video, 480p, seed 63001; the clip came back 544 x 720. Top: "She lowers the wine glass, turns her head toward the camera and holds the look, then lets a slow smile spread. The light bulb above her sways slightly. The camera holds still." Bottom: "She sets the wine glass down, walks up the cellar stairs into a candlelit restaurant upstairs, sits at a table by the window and smiles at the camera." Seed 63002 matched.
Staying in the cellar kept her face, freckles and slipping strap in both seeds. Walking out cut to a new room in both seeds, and after the cut the face, the dress and the strap all changed. If the scene needs a second location, make a second start frame.
The size of the move matters too, as two of our 5 October runs at 720p suggest:
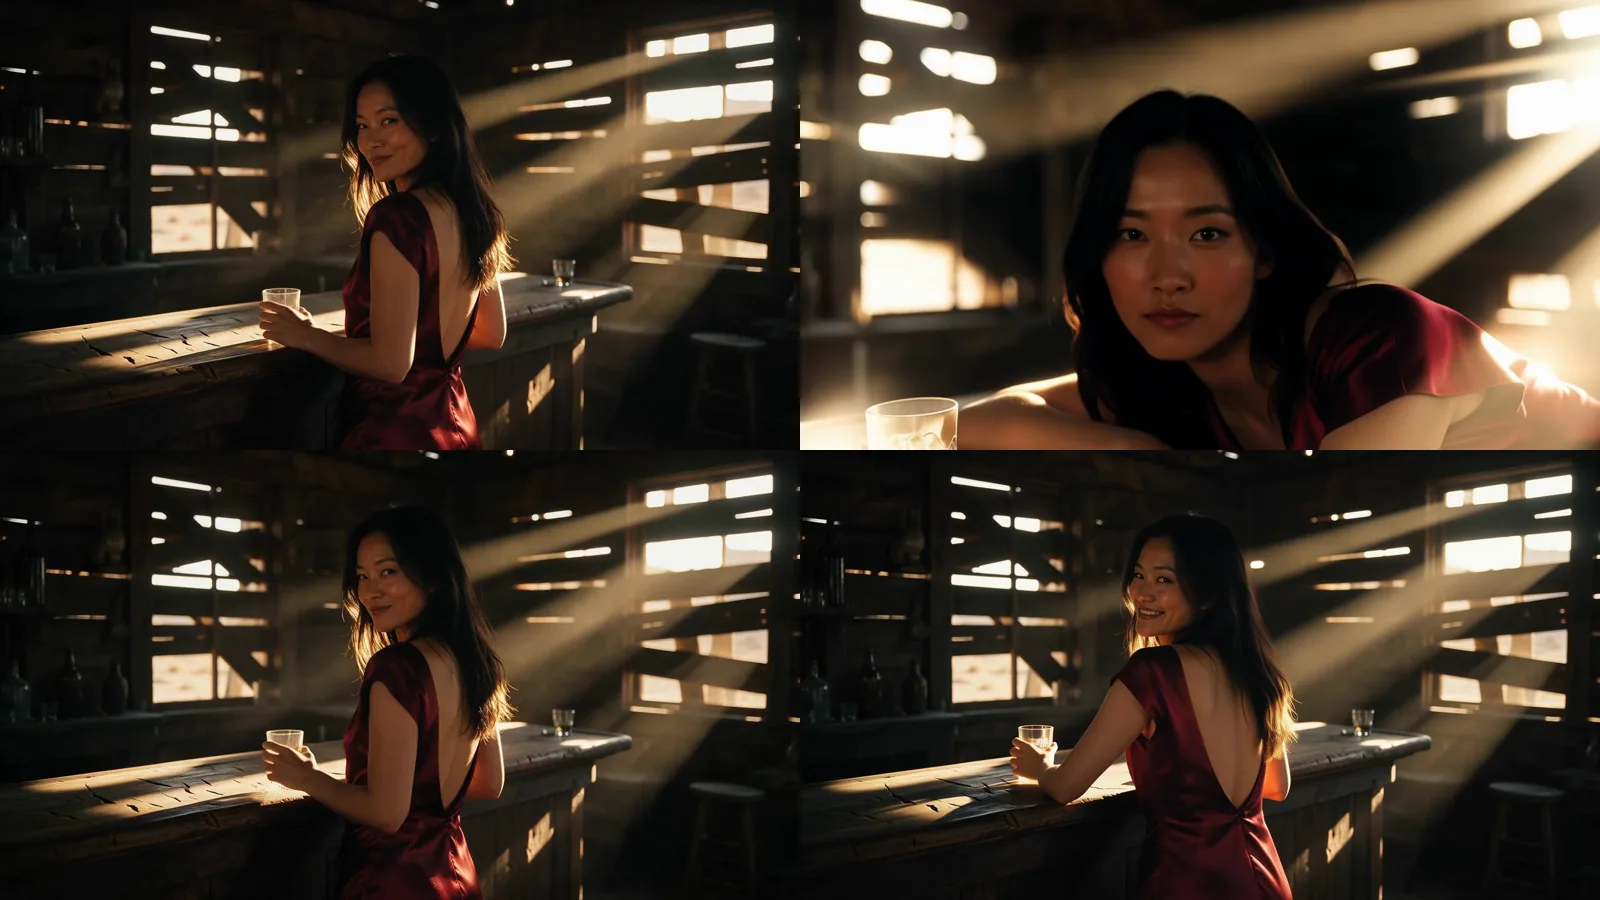
Image-to-video, one start frame, start and end of two clips on different seeds. Top: "turns slowly to face the camera and leans back on her elbows", slight push-in. Bottom: "takes a slow sip… lets a slow, amused smile spread", static camera.
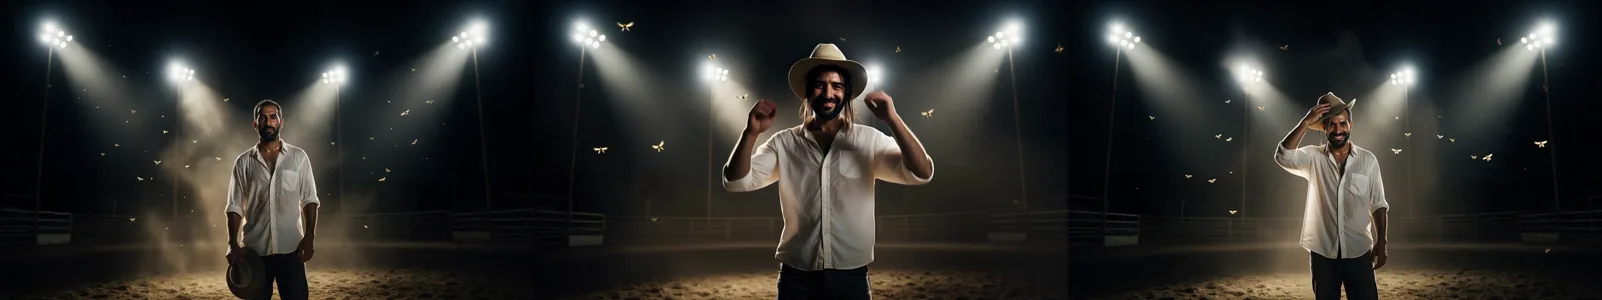
Image-to-video, one start frame. Middle: asked to slap the dust off his hat, run a hand through his hair and put the hat on. Right: asked only to wipe his brow; the model put the hat on by itself and the face held.
In both failures, hands crossed the face or the face moved closer to the lens than in the photo, so the model likely had to redraw it, and drew someone else. Keep the beats small (a sip, a glance, a smile), the camera static or slow, and anything that covers the face to one gesture.
The start frame also sets the starting level: from clothed photos, our ladder prompts took a single figure as far as L3 while keeping the face and room, but a two-person scene from a one-person photo never appeared.
Resolution, length and aspect
| Choice | Our pick | Why |
|---|---|---|
| 480p or 720p | 480p drafts, 720p for the keeper | Half the price; 480p took 39 to 73 seconds of model time in this guide's runs, 720p two to four minutes |
| 5 or 8 seconds | 5, unless you have four or more beats | Three beats filled 5 seconds; 8 seconds costs 60% more |
| 16:9 or 9:16 | 9:16 for phone feeds | Write framing for the shape, such as "vertical medium shot from waist height" |
| Image-to-video shape | Crop the photo first | The clip follows the photo |
| Seed | Fixed while you edit | Same seed does not promise an identical clip |
A 5-second 480p draft costs $0.12, a 5-second 720p final $0.24 and an 8-second 720p clip $0.384, on either endpoint. Clips are silent, so plan sound in the edit: adding voice and music to an NSFW AI video.
Patterns that drifted, and what to write instead
| Pattern | What we saw | Instead |
|---|---|---|
| Mood adjectives | Posed stare, scene details dropped | Two or three visible beats |
| Full embrace between two adults | A hug, blurred hands, an invented prop | One or two touch points |
| A rare gesture ("loosens one cuff") | Swapped for a hand at the collar | A common gesture |
| "No lettering" in the main prompt | An invented number plate | Negative prompt and a tighter frame |
| Wide shot with cars or signs | Invented text and extra people | Move the camera in |
| Reclining full-body pose | An extra foot; a requested close-up ignored | Frame from the waist up |
| Image-to-video: a new place or a lean into the lens | A new face | Second start frame, small moves |
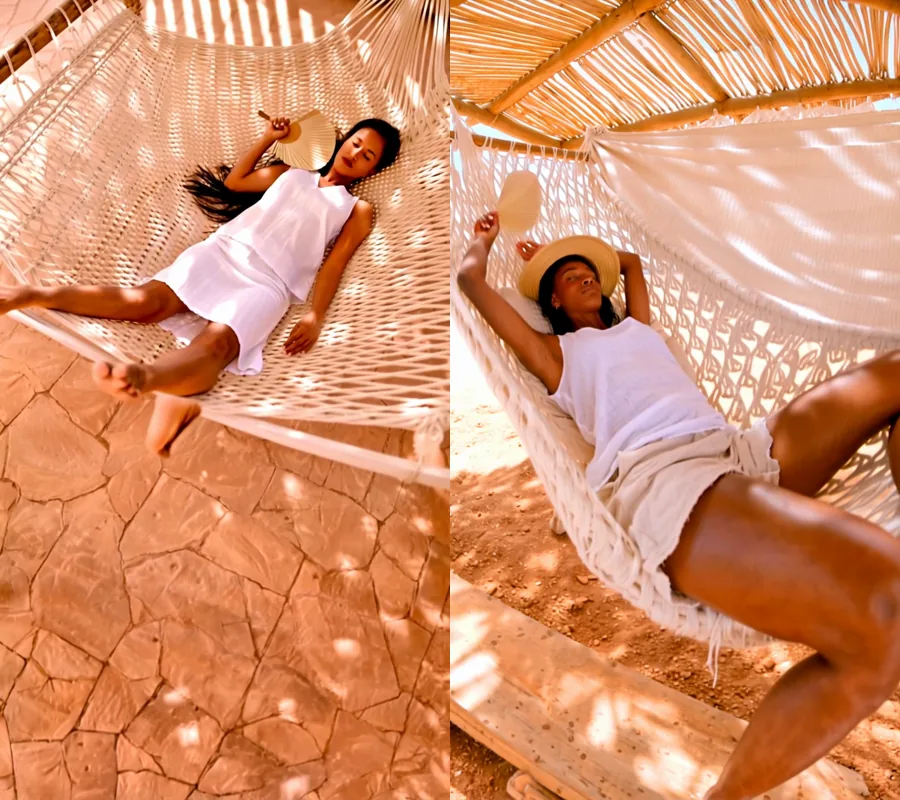
Text-to-video, 720p, 9:16, two takes of one reclining shot from our 5 October runs. The right-hand prompt asked for her face and shoulders in close-up. Neither was kept.
Prompt checklist
Before you pay for a 720p take:
- The subject line says "adult" and gives an age range; the wardrobe line gives garment, fabric, colour and state.
- Two or three visible action beats in order, using common gestures, with no mood adjectives standing in.
- One camera move, framed tight enough to leave out signs, plates, screens and extra people; the place described by its objects.
- Two people only if needed: distinct outfits, one or two touch points, a facial beat to end on.
- Text-to-video: a short negative prompt naming your actual problems. Image-to-video: a cropped photo, the same room, small beats.
- A 480p, 5-second draft on a fixed seed, then 720p for the keeper.
If you need sound with the picture, LTX-2 19B adds an audio track to every clip, and our uncensored AI video prompt guide compares how one prompt behaves across models.
FAQ
How do I write NSFW prompts for HunyuanVideo 1.5?
Write a shot list: one adult, the wardrobe, two or three small actions in order, one camera move, then light and a short style tag. In our 50 runs every L1 to L3 request came back as written, while intimate two-person scenes were softened every time, so keep adult work to one person per clip.
How do I prompt an image into a video?
Use the image-to-video endpoint and describe only what happens next in the same place: a small action, a facial beat and the camera. The photo already fixes the face, outfit and light. Prompts that sent the person somewhere new cut to a new shot with a different face in both of our seeds.
Does Hunyuan have image-to-video?
Yes. HunyuanVideo 1.5 has a text-to-video endpoint and an image-to-video endpoint. The image-to-video clip keeps your photo's shape, and its prompt is optional.
Does HunyuanVideo 1.5 use a negative prompt?
On text-to-video, yes. It was accepted in every run where we passed one, and naming a specific problem ("extra people") removed it, but invented lettering still got through once. Image-to-video has no negative prompt field.
Why did my HunyuanVideo clip come back toned down?
If it was an intimate scene between two adults, that is the model's own limit: all 8 of our runs at that level came back softened, with no refusal. If it was one adult, make the actions concrete; mood words gave us posed, static clips that read as tame.
Why is my image-to-video clip in slow motion?
We have not measured this ourselves. When a user reported slow motion on the publisher's GitHub issue tracker, the maintainers advised describing faster actions in the prompt, for example "turns quickly and laughs" rather than "slowly turns".