You wrote a scene, but the clip came back milder or refused. Start by separating a model’s content limits from an unclear action or an opening still that contradicts the prompt.
Short answer: the model matters more than the words. Based on our September 2026 tests, plain, direct prompts produced matching results in sampled scenes on MiniMax H3, Wan 3.0, Wan 2.6, Wan 2.5, Seedance 2.5 and LTX 2.5, while H3 Max and Wan 2.2 refuse or soften most prompts at the upper levels.
Levels: Mild, Moderate, Strong, Very strong and Maximum; the test prompts are not published.
The 30-second version
- On text-to-video, choose the model first: MiniMax H3, Wan 3.0, Seedance 2.5 or LTX 2.5. Then specify the action and framing.
- On image-to-video, compose the opening frame first. The prompt directs motion from that visual starting point.
- Five parts, in order: subject, action, camera, light, sound. Two or three beats per 5 seconds.
- Drafts are cheap: 5 seconds costs $0.095 on Wan 2.2 Spicy at 480p and $0.185 on MiniMax H3 at 768p.
Try MiniMax H3 text-to-video →
Working on one model? The MiniMax H3 prompt guide and the Seedance 2.5 prompt guide go deeper.
How to write an uncensored video prompt: five parts, in order
A video model renders what you name and invents the rest. Prompt 5, taken apart:
| Part | What to write | From prompt 5 |
|---|---|---|
| Subject | "Adult", who, wardrobe, where | An adult woman in an oversized linen shirt wakes on a sheepskin rug by a loft window |
| Action | A short sequence of linked action beats | She rolls onto her back, stretches, sits up, then turns and looks into the lens |
| Camera | One move, its own sentence | One slow dolly-in at floor height. |
| Light | One source and its colour | Soft white window light, dust in the air. |
| Sound | What we hear, or "no music" | Birdsong outside, quiet room tone, no music. |
- Be specific. Name the wardrobe, props and setting rather than a mood.
- Match the words to the input. From text, describe the cast, wardrobe and setting. From a still, concentrate on what changes while keeping the existing scene clear.
- Fit the beats to the time. One small action stretched over the clip plays slow; six crammed in leave some dropped. Use one flowing paragraph and one camera move. Length is not the limit (Wan 2.6 takes 1,500 characters, H3 7,000).
- Write what you want, not what to avoid. A prohibition-heavy H3 take stalled; "stays fully on for the entire shot" kept an outfit on for a whole H3 clip.
- Call everyone an adult, and with two people, say who does what. Skip "8k, masterpiece", and treat "cinematic" as nearly empty on its own: grain, depth of field and a named camera move do the work.
- Leave prompt expansion off for a precise prompt. It is off by default on Wan 3.0 and Wan 2.6; switch it off on Wan 3.0 Pro, where it is on. Expansion rewrites your prompt: it can develop a one-line idea or change a detailed brief.
A soft clip, rewritten
A vague brief leaves action, framing and tone for the model to invent. Clarifying it is useful when the clip renders but misses your intent; it is not a fix for every rejection. A typical weak first draft:
A beautiful sensual woman in a bedroom, cinematic, moving slowly, don't zoom, 8k masterpiece.
The same scene in five parts:
An adult woman in a white cotton shirt sits on the edge of an unmade bed in morning light. She pulls her hair over one shoulder, then turns and looks into the lens. Static camera at mattress height. Soft window light from the left. Sheets rustling, quiet room tone.
What changed: the vague adjectives became a named wardrobe, place and action; "slowly" and "don't zoom" became two beats and a static camera; light and sound are named. If the result still drifts, change one thing per run and keep the seed where the model has one (Wan 3.0, Seedance, LTX 2.5).
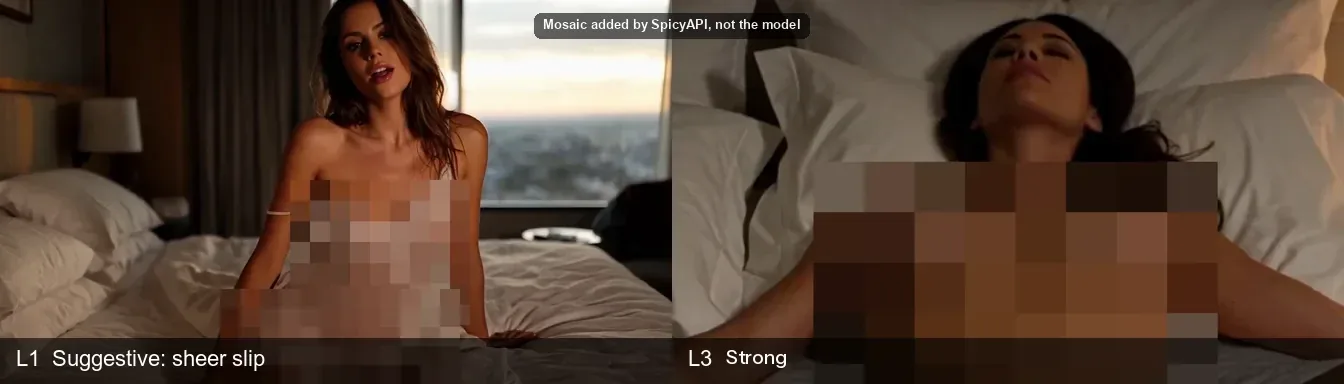
MiniMax H3 text-to-video. Left: a Mild subject line. Right: a Strong subject line, cropped. The mosaic is ours.
Text-to-video vs image-to-video: who decides how far it goes
Text-to-video: the model decides
For stronger scenes, choose Wan 3.0, Seedance 2.5 or LTX 2.5 before polishing the wording. Older base Seedance 2.0, Fast and Mini often softened the action. Select the input task as well as the family: a text result does not tell you how the same model will animate a still.
Name the final beat. Wan 3.0 can continue the action beyond what you intended, so give the shot a clear finish.
Image-to-video: the still sets the level, the prompt moves it
The still establishes the visible scene. Put the styling and composition you want into the image; the prompt mostly moves what is already there. MiniMax H3 and Vidu Q3 tend to stay close to the supplied image; Seedance, Wan 3.0 and LTX 2.5 can develop it further.
The prompt directs the movement. Changing the room in words can move the whole scene there; keep the action consistent with the still. More model-specific behaviour appears in the Vidu Q3 test.
For a specific ending, add a closing frame on H3, Seedance 2.5, LTX 2.5 or Wan 3.0 image-to-video. Match the pair in subject, wardrobe and light.
Wan 2.6 image-to-video follows the still’s shape, so crop before uploading. H3 Spicy, Vidu Q3 Spicy, LTX 2.3 Spicy, Seedance 2.5 Spicy and Wan 3.0 can animate a still without a prompt; write one when the movement matters. Prepare the still with an uncensored image model.
15 copy-paste uncensored video prompts, by scene
Adapt these SFW examples by changing the adult cast, scene and action while keeping the camera and ending clear.
1. First person, at the bed (text-to-video)
Try on LTX 2.5: say where the camera is before what she does.
First-person point of view: the camera is a person lying back against the headboard of a bed at night, looking toward the end of the bed. An adult woman in a long ivory silk robe over a black slip dress steps up, kneels onto the mattress and leans down toward the lens with one hand planted beside it, her hair falling forward around her face. She stops close, tilts her head, smiles, and reaches out and taps one fingertip against the lens. Warm bedside lamp rim light, deep shadow, shallow focus, gentle handheld drift, 35mm film grain.
2. A robe and a look, from a still (image-to-video)
Try on Vidu Q3 Spicy: prompt optional. One beat, one sound, one camera move; the still carries the rest.
She finishes pouring, sets the flask down and lifts her eyes to camera with a small smile, steam rising from the cup, the yukata sliding a fraction lower on her shoulder. Paper shoji glow, evening cicadas, very slow push-in.
3. Steam and a look back (image-to-video)
Try on MiniMax H3 Spicy: one continuous move; let the steam carry the ending. There is no sound switch, so add sound in the edit if you need it.
She rolls her shoulders back and stretches upward in the cedar heat, water running the length of her spine. She turns her head to look back over one shoulder into the lens, then steps forward into the billowing steam. The vapour boils up around her and swallows the far wall. Slow handheld drift following her, warm cedar light, condensation crawling down the glass. Cinematic, shallow depth of field, heavy film grain.
4. A turn to camera by lamplight (text-to-video)
Try on Seedance 2.0: sound at no extra cost, and a seed. If it comes back with a copyright error, re-roll or use Seedance 2.0 Fast or 2.5.
An adult woman sits on the rim of a clawfoot bath in a dark tiled bathroom at night, a white towel wrapped around her. She pins her wet hair up with both hands, turns her head toward the camera in profile, then lowers her arms and looks straight into the lens. Slow push-in from the doorway. One warm wall sconce, steam fogging the mirror behind her. A dripping tap, quiet room tone.
5. Morning light, solo, from text (text-to-video)
Try on Wan 2.6: stays close to your words.
An adult woman in an oversized linen shirt wakes on a sheepskin rug in front of a tall loft window in morning light. She rolls onto her back, stretches both arms above her head, sits up, then turns and looks straight into the lens with a slow smile. One slow dolly-in at floor height. Soft white window light, dust in the air. Birdsong outside, quiet room tone, no music.
6. The cheapest text draft (text-to-video)
Try on Seedance 2.0 Mini: cheapest Seedance. Give the subject something ordinary to do.
An adult woman in a white cotton sundress lies on her stomach across a rumpled white bed in afternoon light, reading a paperback, ankles crossed in the air. She lowers the book, rolls onto her side toward the camera and props her head on one hand, then laughs at something off screen. Static camera at mattress height. Warm sun through half-closed blinds, striped light across the sheets. Pages turning, a ceiling fan ticking.
7. Your own still: write only the motion (image-to-video)
Try on MiniMax H3: keep the existing scene and describe its continuation.
She tips her head back under the water and runs both hands through her wet hair, then turns to face the camera and wipes the water from her eyes with the back of her wrist. Steam drifts across the glass behind her. Static camera at chest height. Running water, a soft echo, no music.
8. Couple: wind on the balcony (text-to-video)
Try on Wan 3.0 Prime: about $0.31 for five seconds at 480p; one shared action, one camera move.
Golden hour on a hotel balcony: she stands at the rail in a silk robe that lifts and falls in the wind, and he comes up behind her and closes both arms around her waist. She leans back into him and turns her face up to his. The robe streams sideways, the city hazes gold below. Slow orbit around the pair at the rail. Cinematic, shallow depth of field, heavy film grain.
9. Couple: the back seat (text-to-video)
Try on Wan 2.6, for the same reason as prompt 5. This example file has no audio track.
A couple in a rain-streaked car at night: she climbs across from the passenger seat into his lap and takes his face in both hands. He slides a hand up her back and the window fogs where her shoulder presses it. Rain runs down the glass, headlights sweep past and go. Slow push in from the back seat, warm dashboard glow against cold rain light. Cinematic, shallow depth of field, heavy film grain.
10. Couple: two women at the drive-in (text-to-video)
Try on Wan 3.0: sound on or off, and a seed. Wardrobe per person, then who moves first.
35mm film still, warm grain and halation. Two adult women lie back in the open tailgate of a station wagon at a drive-in cinema, a plaid blanket over their legs; one wears a white ribbed tank top, the other a red gingham bikini top and denim shorts. The projector beam flickers across them; one turns, brushes hair from the other's face, and they kiss slowly as the screen light shifts from blue to gold. Summer night, moths in the beam, loose handheld frame.
11. Camera: the crane down (text-to-video)
Try on LTX 2.5: up to 4K, with a seed. The camera gets its own three words.
Ultra-detailed cinematic shot: an adult woman in a floor-length emerald silk gown descends a marble staircase in an empty opera house, the high slit opening across her leg with each step, chandelier light glittering through the fabric. Slow crane down, immaculate texture detail, orchestra tuning drifting up from the pit.
12. Camera: point of view, from a still (image-to-video)
Try on Wan 2.6 Spicy: $0.475 for five seconds at 720p; the still establishes the framing. For a point of view, move the camera like a body: a sway, not a crane.
Her toes flex and hook deeper into the silk, one knee slowly straightening, the sheets sliding and rippling under her legs. The slatted bars of light creep across the bed as the blind stirs in the draught. Handheld point-of-view sway, warm red and gold, quiet morning room tone.
13. Slow motion, on purpose (text-to-video)
Try on Wan 3.0 Pro: 1080p minimum, about $0.72 for five seconds; switch prompt expansion off, since it is on by default on Pro. Say "slow-motion" once, up front; otherwise keep "slowly" off your verbs.
Slow-motion perfume commercial. An adult woman in a backless black gown turns away from a rain-lashed window, the low back of the dress catching a single hard key light down her spine, droplets of water flicking from her hair as she moves. Macro-sharp fabric detail, deep shadow, 4K product-film polish, low cello note and rain.
14. Sound-led: the bar (text-to-video)
Try on Seedance 2.0: sound at no extra cost. Every sound comes from something on screen. If it comes back with a copyright error, re-roll or use Seedance 2.0 Fast or 2.5.
Photorealistic live-action, not animation. A real adult woman in a chocolate satin robe works behind a dim neon bar, a large fluffy faux fox tail accessory clipped at the small of her back. She shakes a cocktail, turns to set the glass on the counter and the tail sways with the movement, then she looks back at camera with a teasing smile. Warm red lantern light, 35mm grain, slow push-in, ice rattling and low bar chatter.
15. Keep it on: a safe cut from a Spicy model (image-to-video)
Try on Seedance 2.0 Fast Spicy: about $0.41 for five seconds at 480p. Some Spicy test clips changed the wardrobe without being asked. Name what must stay on; inspect the result rather than treating that instruction as a lock.
First person point of view, the camera stays where it is on the pillow and does not move. She lowers herself closer toward the lens, her long hair falling forward around the edges of the frame, and holds eye contact. She keeps the black lace top and the black satin robe on the whole time and stays fully dressed. Candlelight flickers behind her; the background stays black. Only her movement, no camera move, no cut.
What gets toned down, and what gets through
Separate the returned error from a rendered but milder clip. Model policy, input validation and a contradictory brief call for different changes.
| You sent | To | What came back | Send this instead |
|---|---|---|---|
| A Maximum-level prompt | Wan 2.2 text-to-video | Refused, not billed (Mild refused too) | Wan 3.0, Wan 2.6 or Wan 2.5 text-to-video |
| A Very strong prompt on a Strong-level still | H3 Max image-to-video | Refused | MiniMax H3 image-to-video |
| A Maximum-level prompt on a Strong-level still | Wan 2.2 image-to-video | Partly kept, the rest toned down | Wan 2.2 Spicy or Wan 3.0 image-to-video |
| A Very strong prompt | H3 Max text-to-video | A much milder scene, billed; later runs refused or toned down | MiniMax H3 text-to-video: as written |
| A Very strong prompt | HappyHorse 1.1 text-to-video | Refused at the prompt, not billed; Strong mostly passed | MiniMax H3 text-to-video |
| A strong prompt on an SFW still | Seedance image-to-video | Several tame clips | Match the prompt to the still |
| A Very strong prompt on a Strong-level still | Seedance 2.0, 2.0 Fast, 2.0 Mini image-to-video | Mostly toned down | Seedance 2.5 or Wan 3.0 image-to-video |
| A plain Mild prompt | Seedance 2.0 text-to-video | Repeated copyright errors | Re-roll, or Seedance 2.0 Fast or 2.5 text-to-video |
| A Strong-level still, no prompt | H3 image-to-video; Vidu Q3, Pro, Turbo | Rejected, not billed | One line of motion |
| Strong-level reference footage | Wan 2.6 reference-to-video | Refused, not billed | Wan 3.0 reference-to-video |
| Plain words vs a genre label | Wan 2.6 text-to-video | Both as written | Either |
A refusal normally releases the hold; exceptions appear on the model page. Check settled and cost (policy). A toned-down clip is billed, so inspect the frames.
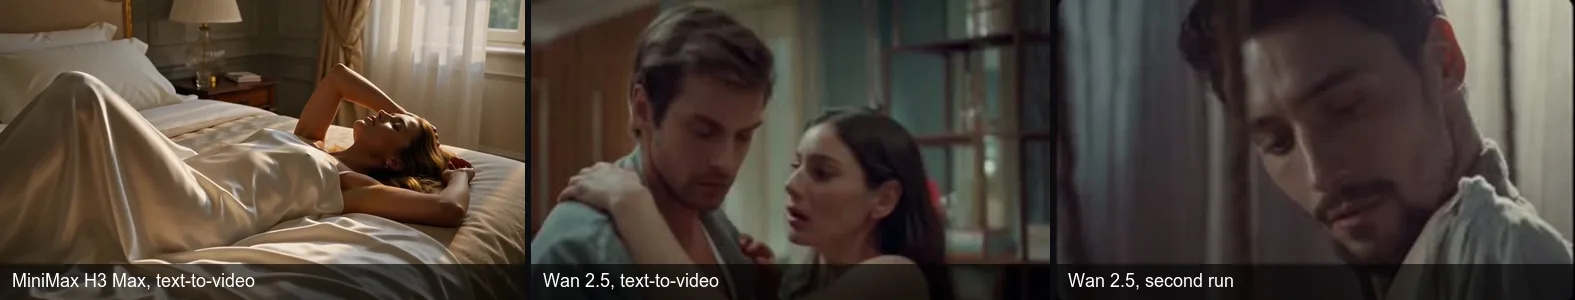
What "toned down" looks like. Left: MiniMax H3 Max text-to-video, Very strong prompt. Middle and right: Wan 2.5 text-to-video, our first Maximum-level prompt and a reworded second run. Unedited frames, all billed. Later Wan 2.5 runs delivered this category as requested; these frames illustrate its earlier softened outputs.
One prompt, different models: what we actually saw
An additional Maximum-level brief produced different pacing and staging across models:
| Model | What it did with the same brief | For your prompt |
|---|---|---|
| MiniMax H3 | Every element, as written | Name the beats and the ending |
| Wan 3.0 models | Rendered the brief, then added further action | Name the last beat, check the ending |
| LTX 2.5 | Followed the text brief; from a still, needed clearly written actions and showed merged limbs | From a still, write two or three actions |
| Wan 3.0 Prime, image | Kept the solo still solo | Put what you need in the still |
| Wan 2.2 Spicy | Brought in a second person | Check for extra people |
| Vidu Q3, Q3 Spicy | Added elements from the brief and a second person; relit the room red | Name the room and light you have |
| Seedance 2.0 Fast | Held close to the still and softened stronger requested action | Put the action in the still |
| Seedance 2.0 Spicy, 2.0 Fast Spicy, LTX 2.3 Spicy | Escalated to Very strong when nobody asked for it | Use MiniMax H3 image-to-video, or specify the ending and check the last frames |
Two versions of the same fashion scene show why duration belongs in the motion brief.
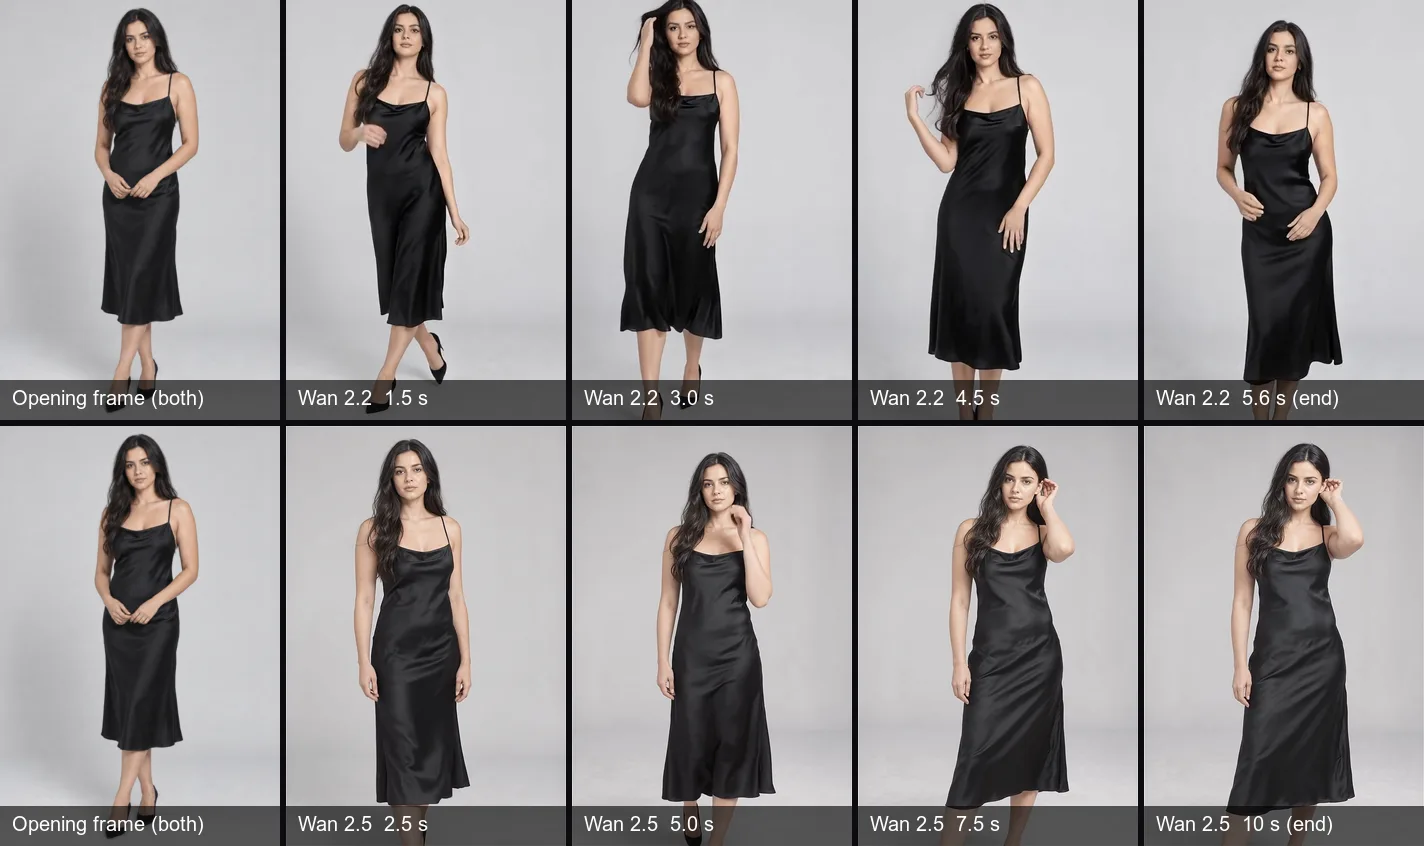
Same still, closely related motion prompts. Top: Wan 2.2, 720p, 5.8 seconds. Bottom: Wan 2.5, 1080p, 10 seconds. Wan 2.2 clip · Wan 2.5 clip.
The shared motion brief was:
She shifts her weight, turns her shoulders toward the lens and takes two slow steps forward, the satin of the dress catching the light as it moves. She tucks her hair behind one ear and holds the look. Locked camera, clean grey studio.
Wan 2.2 finished the steps by 1.5 seconds and drifted back toward its opening pose; Wan 2.5 spread the beats over ten seconds and held the last one. Match beats to length and give the ending something to hold.
Where clips go wrong, and the fix
| What you see | Fix |
|---|---|
| Slow motion, stiff movement | Two or three beats per 5 seconds, no "slowly" on every verb; on Wan, add "real-time speed" |
| Image-to-video barely moves | Verbs only, no description of the still |
| The whole clip freezes | If the prompt mainly forbids movement, try a short sequence of positive action beats; simplify the action before adding more instructions |
| A different face every run | Reuse one clear still or character reference; keep the seed where offered. MiniMax H3 base and Vidu Q3 Spicy have no seed field |
| A toned-down or safer scene | Switch to an uncensored model (H3 instead of H3 Max, Wan 3.0 instead of Wan 2.2) |
| The camera cuts away | "One continuous shot, no cuts"; keep shot_type on single (the Wan 2.6 default) |
| The camera creeps in | "Static tripod shot: the framing stays as in the first frame"; on Wan, add "zoom, push-in, close-up" to the negative prompt where there is one |
| It goes further than you asked | Name the ending, add a compatible closing frame where offered, or try a task whose test outputs stayed closer to the brief |
| A rewrite changes everything | Change one field per run and keep the seed where offered; leave expansion off |
| Music you didn't ask for | H3 adds sound to every clip: name the sound and add "no music" |
| No sound at all | Add sound in the edit or use an audiovisual task. H3 Spicy has no sound switch; check its delivered track |
Longer than one take? The longer uncensored video guide chains clips from the last frame.
Prompt cheat sheet: one line per model
Price: five seconds at the cheapest available resolution. These are output costs; reference-video tasks can add separate charges.
| Model | Starts from | Write it like this | 5 s from |
|---|---|---|---|
| MiniMax H3 | Text, image, reference images/video | Name each element; a still establishes the face. Guide | $0.185 |
| MiniMax H3 Spicy | Image | Prompt optional; one beat is plenty; no sound switch | $0.19 |
| MiniMax H3 Max | Text, image | Text-to-video is Filtered, image-to-video Softened: upper-level prompts go to H3 | $0.25 |
| Wan 3.0 | Text, image, reference images/video | Name the last beat; it escalates | $0.225 |
| Wan 2.6 | Text, image | Stays close to your words | $0.45 |
| Wan 2.5 | Text, image | Clear, specific prompts on both paths | $0.225 |
| Wan 2.2 Spicy | Image | Three or four beats, "real-time speed"; silent | $0.095 |
| Seedance 2.0 | Text, image, reference images/video | "One continuous shot, no cuts" | $0.35 |
| Seedance 2.0 Mini | Text, image, reference images/video | Cheapest Seedance draft | $0.12 |
| Seedance 2.5 | Text, image, reference images/video | 30-second takes. Guide | $0.62 |
| Seedance 2.5 Spicy | Image | Prompt optional; draft at 480p on this model | $1.08 |
| LTX 2.5 | Text, image | Actions joined by "then" | $0.45 |
| LTX 2.3 Spicy | Image | Short prompt or none; escalates; silent | $0.095 |
| Vidu Q3 Spicy | Image | Name the room you have; prompt optional | $0.33 |
| Vidu Q3 Turbo | Image | Cheapest draft true to the still | $0.21 |
When you change model, check the new task's accepted inputs: text, image and reference tasks take different fields.
FAQ
How do I write uncensored prompts for AI video?
Use prompt 5 from text, or prompt 7 from a still. Replace the cast and setting, keep one camera move, then choose the matching input task in the model table.
Why did my AI video come back toned down?
If the category is unsupported, switch from H3 Max or base Wan 2.2 to a tested alternative. If the scene is right but its movement is wrong, simplify the beat instead of rewriting the whole shot.
Can my prompt take an image-to-video clip further than the still?
Yes. Some tasks add action, people or a new setting. To preserve wardrobe and framing, keep those instructions clear and avoid describing a different room.
Do I need special wording?
No. Name the adult cast, the styling, the action and the camera. Vague genre labels leave more for the model to invent.
How do I keep the same person across clips?
Reuse one clear still or character reference images. Keep hairstyle, wardrobe and lighting consistent, and remove competing faces from location reference images. See the longer uncensored video guide.
Do I pay for refused or toned-down clips?
Refused: normally no, the hold is released. Toned down: yes, at the normal price.
Your part
SpicyAPI adds no content filter; upstream models can still check or refuse inputs. Use consenting adults and material you have the rights to upload, and follow the law where you publish.
Run your first prompt
Create an account, pick a prompt above and hit Run. Draft at the lowest resolution, then rerun higher. Everything else is in the uncensored video catalogue.
From a Playground prompt to the API
Try a prompt through its model link first, choose five seconds at the lowest resolution, and inspect the completed shot. For an application that needs the same workflow repeatedly:
Set SPICY_API_KEY in your environment. This Python 3 example submits one new shot after you confirm its price.
import json
import os
import urllib.request
import uuid

base = "https://api.spicyapi.ai/api/v1"
headers = {"Authorization": "Bearer " + os.environ["SPICY_API_KEY"],
           "Content-Type": "application/json", "User-Agent": "SpicyAPI-Blog/1.0"}
settings = {
    "duration_seconds": 5,
    "resolution": "480p",
    "generate_audio": False,
    "aspect_ratio": "16:9"
}
settings["prompt"] = 'A slow camera push toward the subject. Keep the setting and clothing unchanged. One continuous shot.'
payload = {"model": "bytedance/seedance-2.5/text-to-video", "input": settings}

def post(path, body):
    request = urllib.request.Request(base + path, json.dumps(body).encode(), headers)
    with urllib.request.urlopen(request, timeout=60) as response:
        result = json.load(response)
    if result.get("code") != 200:
        raise RuntimeError(result)
    return result["data"]

quote = post("/jobs/quote", payload)
if input(f"Maximum charge ${quote['maxCharge']}. Type yes to generate: ") != "yes":
    raise SystemExit("Stopped before generation")
headers["Idempotency-Key"] = str(uuid.uuid4())
print("Request key:", headers["Idempotency-Key"], flush=True)
task = post("/jobs/createTask", {**payload, "quoteId": quote["quoteId"],
                              "expectedCost": quote["estimatedCost"]})
print("Task ID:", task["taskId"])
Keep the printed request key for recovery of that same request; a new shot gets a new key. Task API documentation covers result delivery and recovery.
For repeated shots, let an Agent use an approved input file: CLI spicyapi tasks create --model bytedance/seedance-2.5/text-to-video --input-file input.json --wait; MCP ask it to call spicyapi_task_create with that model and input; Skill ask “Use the spicyapi Skill to generate this approved shot and return the result.” CLI and MCP show the price before creation. See the Agent integration documentation.