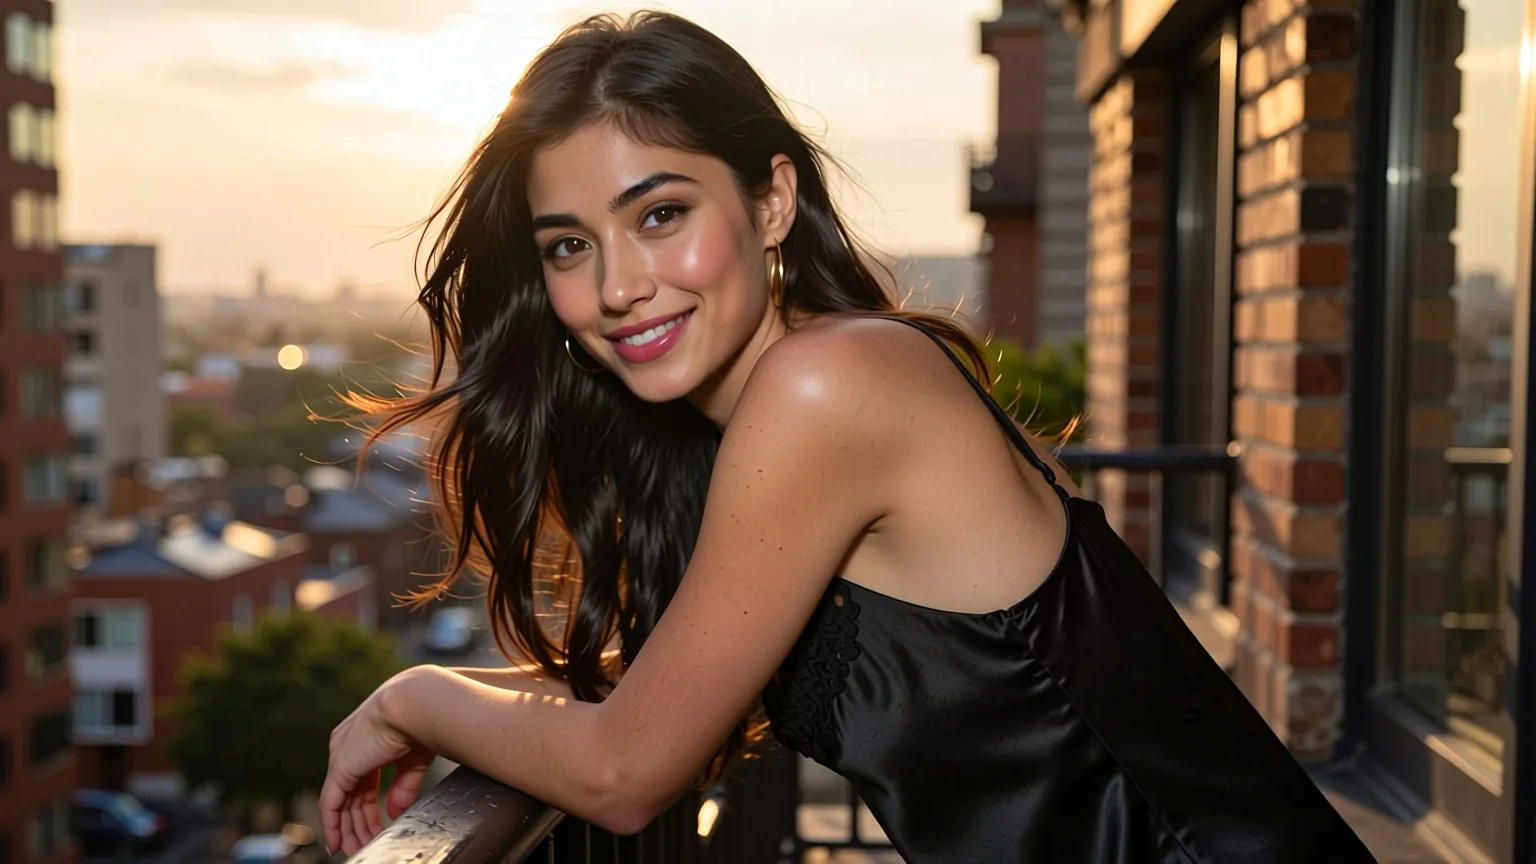
Jib Mix Qwen is a fast photorealistic portrait model: in our tests an image took a median of 5.8 seconds, and photo and camera LoRAs changed its look while style LoRAs barely did. It has two weak spots we want you to know before you build on it. Six requests for a Japanese, Korean or East Asian woman all came back European or ambiguous, and two-person intimate scenes were drawn without a refusal but with muddled anatomy.
We tested both Jib Mix Qwen and its LoRA build on 5 October 2026. Jib Mix is a community checkpoint series by the creator J1B, and this one is a merge of Qwen-Image fine-tunes and LoRAs built on Alibaba's 20-billion-parameter Qwen-Image. Every prompt printed below is an everyday scene with clothed adults.
At a glance
| Jib Mix Qwen and Jib Mix Qwen LoRA (tested 5 October 2026) | |
|---|---|
| Creator and base | J1B; a merge of Qwen-Image fine-tunes and LoRAs on Qwen-Image (20B, Qwen2.5-VL text encoder) |
| API model names | j1b/jib-mix-qwen-image/text-to-image and j1b/jib-mix-qwen-image-lora/text-to-image |
| Public fields | prompt (up to 5,000 characters), aspect_ratio, output_format, seed; the LoRA build adds loras |
| Aspect ratios | 9, up to 1536 pixels on the long side: 1328 x 1328 at 1:1, 1536 x 864 at 16:9 |
| Output | One image per request as JPEG (default), PNG or WebP |
| Speed in our tests | Base: 3.7 to 48 seconds over 30 runs, median 5.8, 21 of 30 under 10. LoRA build: 3.2 to 36 seconds over 38 runs, median 5.6 |
| Content policy | Uncensored, no content filter; single-subject content came back as asked, two-person scenes were drawn without a refusal but less precisely |
| Cannot do | Negative prompts, steps, guidance, image input, editing, more than one image per request |
What it is, and which version
The creator's notes for the first release say it merges Qwen models with favourite LoRAs at precise weights. The page on Civitai lists six versions between September 2025 and March 2026. The v4.0 note, from 15 October 2025, says "much more natural pretty faces (much better at Asian faces)". The v6.0 note, from March 2026, says "more European faces and fewer Asian by default" and "not quite as good at NSFW as V5".
The hosted route does not say which version it runs. Its description echoes the v4.0 note, but our outputs lean European, which matches v6, and the route was updated recently, so we cannot rule out a swap. We are flagging that as unverified rather than guessing. What we can report is what the route does, and that is the rest of this article.
Prompting for portraits
The model likes a photographer's brief in full sentences. The window portrait below used age, hair, freckles, clothing, pose and light, with a short photographic opener:
Photorealistic photo, natural skin texture. A 32-year-old woman with a short black bob, light freckles and minimal makeup sits on a windowsill in a cream silk camisole, knees drawn up, holding a mug of coffee. Soft morning light, sheer curtains, shallow depth of field.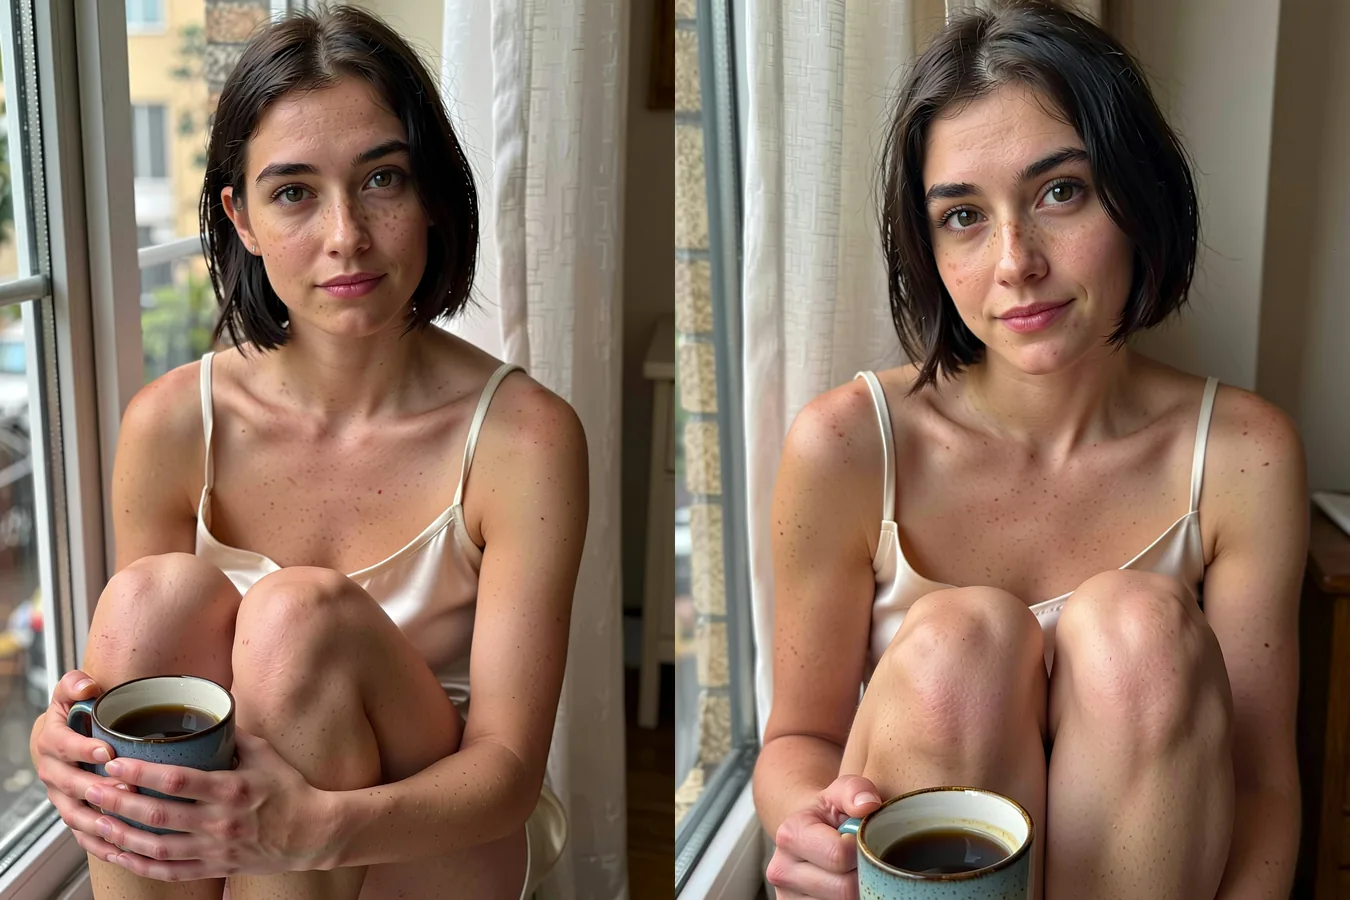
Seeds 1 and 2 of a version of this prompt that asked for a Japanese woman. See the faces section below. 3:4, text-to-image.
Habits that helped in our runs:
- Open with a photographic cue. "Photorealistic photo, natural skin texture" or "35mm film look" or "phone photo with flash" steers the look.
- Describe the person, not a nationality. Age, hair length and colour, freckles, a beard and the expression changed faces reliably. A nationality did not.
- Quote short words. Our chalkboard prompt asked for a sign reading "OPEN LATE" in white chalk letters. The board came back with those words in both seeds. Keep it to a short phrase and check the lettering.
- Fix the seed and change one thing. Light, clothing or lens feel, one at a time. Seeds make runs comparable but are not a promise of identical pixels.
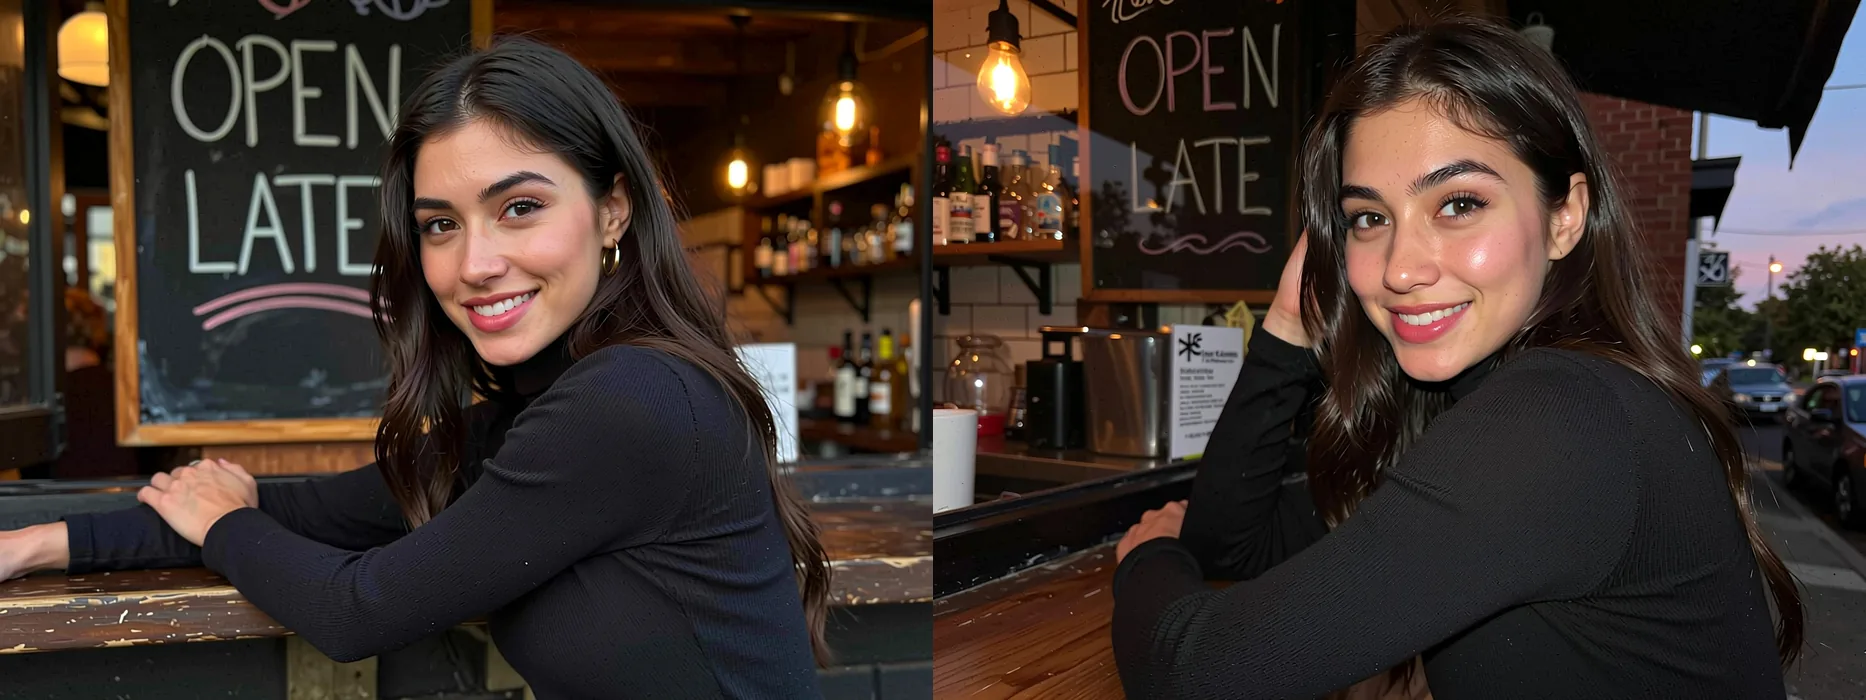
Seeds 1 and 2 of the chalkboard prompt (here asking for a Korean woman), 4:3. The sign reads "OPEN LATE" in both.
Aspect ratios and sizes
There is no size field. You pick one of nine aspect ratios, each mapped to a fixed size. We ran every ratio once on both endpoints, and every output came back at exactly the requested pixels. The long side stops at 1536.
| Ratio | Size | Ratio | Size |
|---|---|---|---|
| 1:1 | 1328 x 1328 | 21:9 | 1536 x 656 |
| 4:3 | 1472 x 1104 | 9:21 | 656 x 1536 |
| 3:4 | 1104 x 1472 | 16:9 | 1536 x 864 |
| 3:2 | 1536 x 1024 | 9:16 | 864 x 1536 |
| 2:3 | 1024 x 1536 |
Choose by the job. 3:4 and 2:3 suit portraits, 16:9 and 21:9 suit film stills and banners. A close portrait at 2:3 looks like this:
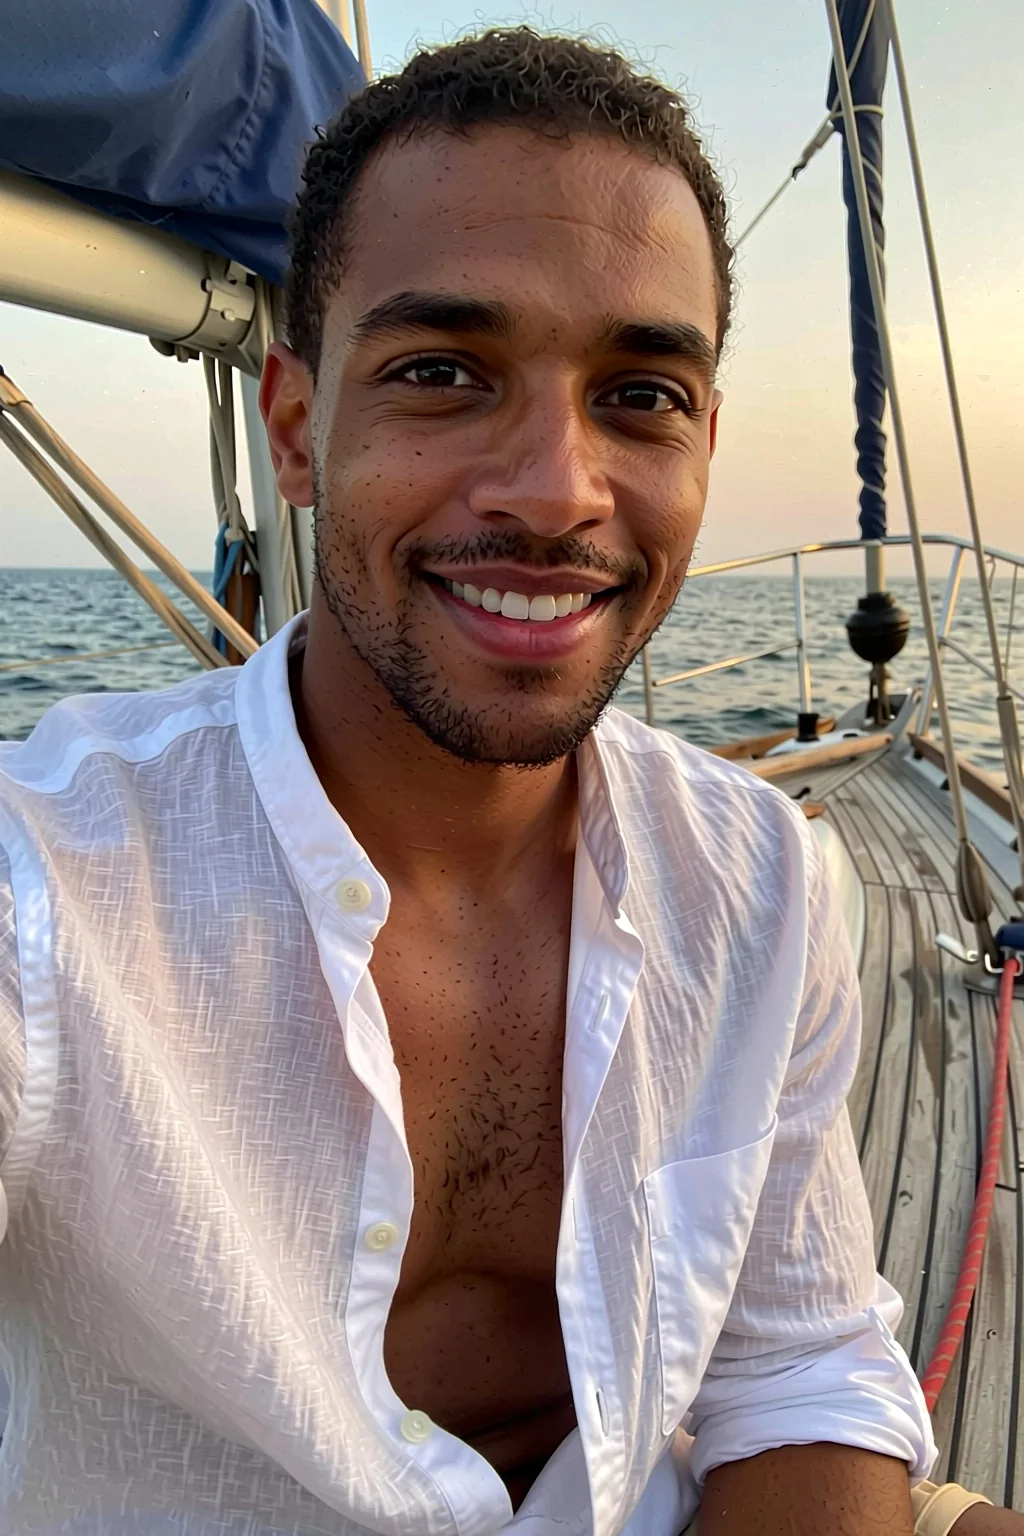
Published example: a 35-year-old man on a sailboat at golden hour, 2:3, seed 1.
Photorealistic photo, natural skin texture. A 35-year-old Black man with a trimmed beard and a warm smile, open white linen shirt, sits on the deck of a sailboat at golden hour. Sea spray, wind in his shirt, shallow depth of field.Speed
The base endpoint's model time ranged from 3.7 to 48 seconds across 30 runs, with a median of 5.8 seconds and 21 of 30 under ten. The LoRA build was almost the same: 3.2 to 36 seconds across 38 runs, median 5.6, and a request that loaded a LoRA file for the first time took 10 to 25 seconds. That is quick enough for iterating on a portrait.
Two people in one frame
Scenes with two clothed people worked. This film-still prompt drew a laughing couple under one umbrella in both seeds, each person with their own coat and place in the frame:
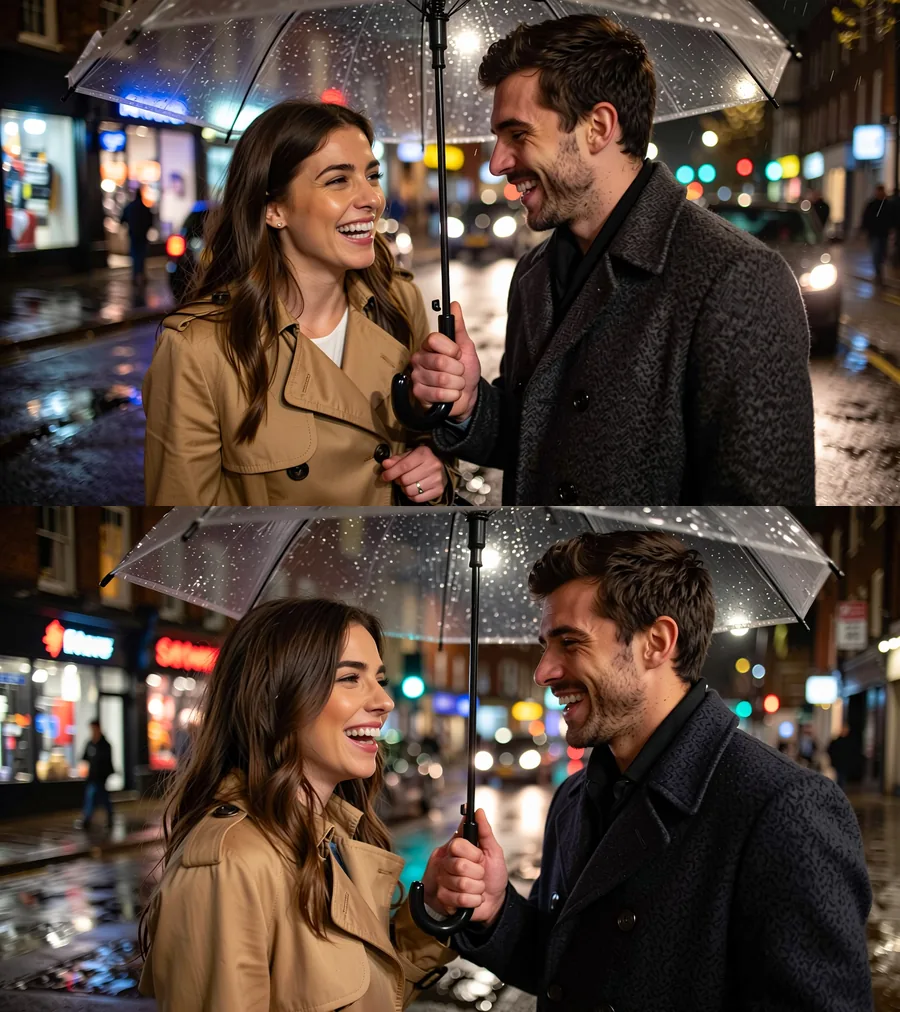
Seeds 1 and 2 of the umbrella prompt, 16:9, stacked. The model gave each person a distinct coat and kept the bokeh.
Photorealistic film still. A woman and a man in their early thirties laugh together under one clear umbrella on a rainy city street at night, she in a camel trench coat, he in a dark wool coat. Shop lights blur into colorful bokeh and reflect on the wet asphalt.Give each person a clear place in the frame and one outfit each. When hands or limbs merge, reroll the seed.
How far it goes
The platform adds no content filter. We ran one prompt per rung of our five-level ladder at 3:4, seed 1, with the characters stated as adults, and looked at every image.
| Level | Result on the base endpoint |
|---|---|
| L1 Suggestive (lingerie, a slipping strap) | Delivered |
| L2 Partial | Delivered, and across all nine ratios (9 of 9) on both endpoints |
| L3 Strong, female and male | Delivered |
| L4 Intense (an intimate scene between two adults) | Softened: three seeds all drew two adults, but the anatomy was muddled and only one of the three read as the scene we asked for |
| L5 Extreme (consensual restraint between adults; cinematic gore) | Both delivered |
There was no refusal anywhere. L4 is the honest finding: the model does not decline it, it just cannot draw it cleanly. Adding an adult Qwen-Image LoRA changed the composition to a posed couple and still did not produce the scene. So the practical limit is this: single-subject content came back as asked, and two-person scenes were drawn without a refusal but with less precise anatomy. If your work depends on L4, test the exact route first, and compare it with Qwen Image 2512 LoRA below.
The faces problem
We asked twice for a "32-year-old Japanese woman", twice for a "woman with East Asian features" and twice for a "30-year-old Korean woman". All six faces came out European or ambiguous.
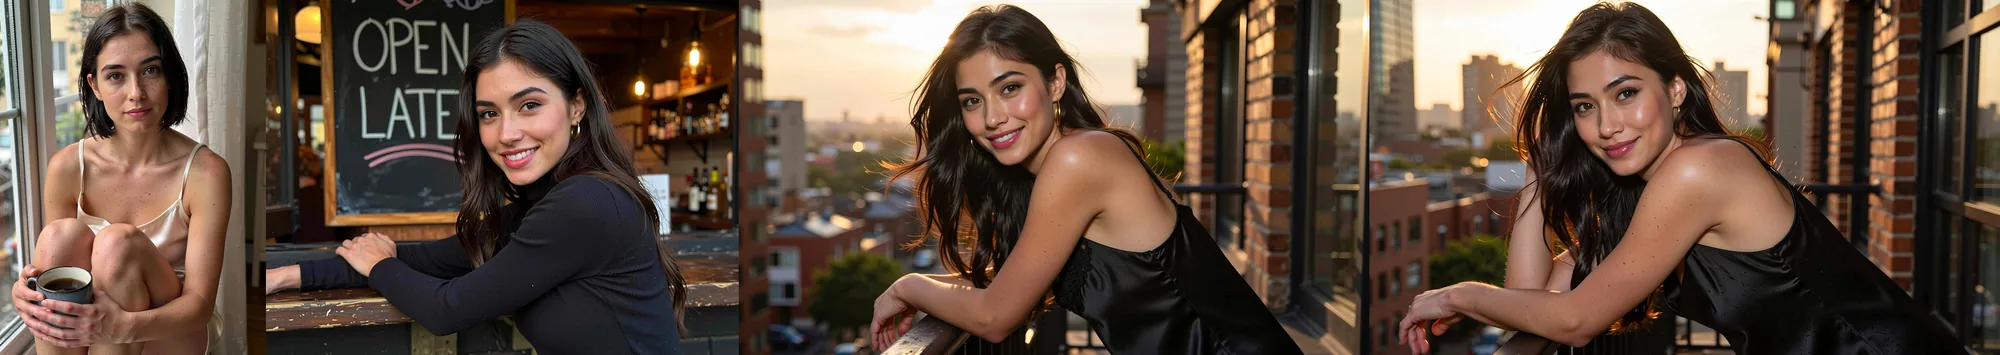
Left to right: "Japanese woman" seed 1 (3:4), "Korean woman" seed 1 (4:3), "East Asian features" seeds 1 and 2 (16:9).
Many seeds also settle on a similar dark-haired face, the "same face" habit that Civitai users report for early versions. Do not choose this model if you need strong East Asian faces. If you stay with it, vary age, hair, freckles, a beard and the expression explicitly and do not rely on a nationality word. The published examples on the model page were written without a nationality.
Which LoRAs change it
The LoRA build takes up to three LoRAs per request, each a direct link to a .safetensors file with a scale from 0 to 4. With no LoRA loaded it gave pixel-identical output to the base endpoint on the same seed in our checks, so use the base endpoint unless you plan to load one. A repository web page link fails with a message asking for the direct download link, and a gated repository fails with an HTTP 401 error.
Qwen-Image LoRAs load, from Hugging Face or from a Civitai direct link, and so do Qwen-Image-2512 LoRAs. What they do to the picture depends on the type.
Photo and camera LoRAs show. On one prompt and one seed, four photographic LoRAs each changed the face and light visibly but not drastically.
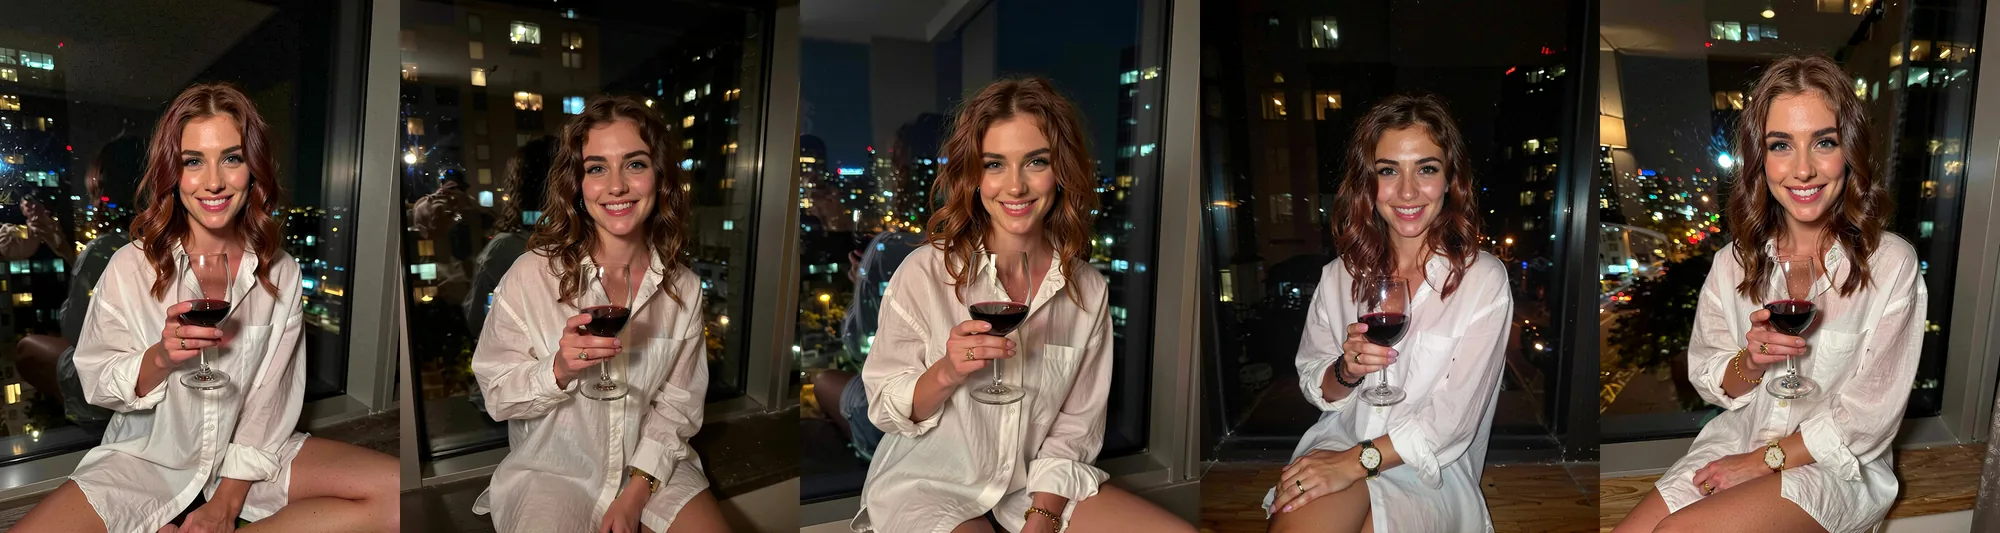
Left to right: no LoRA; a phone-camera LoRA (Samsung UltraReal); a portrait-retouch LoRA (AWPortrait-QW); a flash-photo LoRA (Lenovo); a realism LoRA (flymy-ai). Same prompt, seed 21, 3:4, all at scale 1.
| LoRA type | What we saw | Verdict |
|---|---|---|
| Phone-camera (Samsung UltraReal) | Curlier hair, harder light, a snapshot feel | Visible |
| Portrait retouch (AWPortrait-QW) | A more retouched portrait look | Visible, subtle |
| Flash photo (Lenovo) | Darker frame, flash-lit | Visible |
| Realism (flymy-ai) | Face and light changed | Visible, subtle |
| Two stacked (Samsung 0.8 plus AWPortrait 0.6) | Worked | Two LoRAs in one request |
Two published examples show the camera and retouch LoRAs at work:
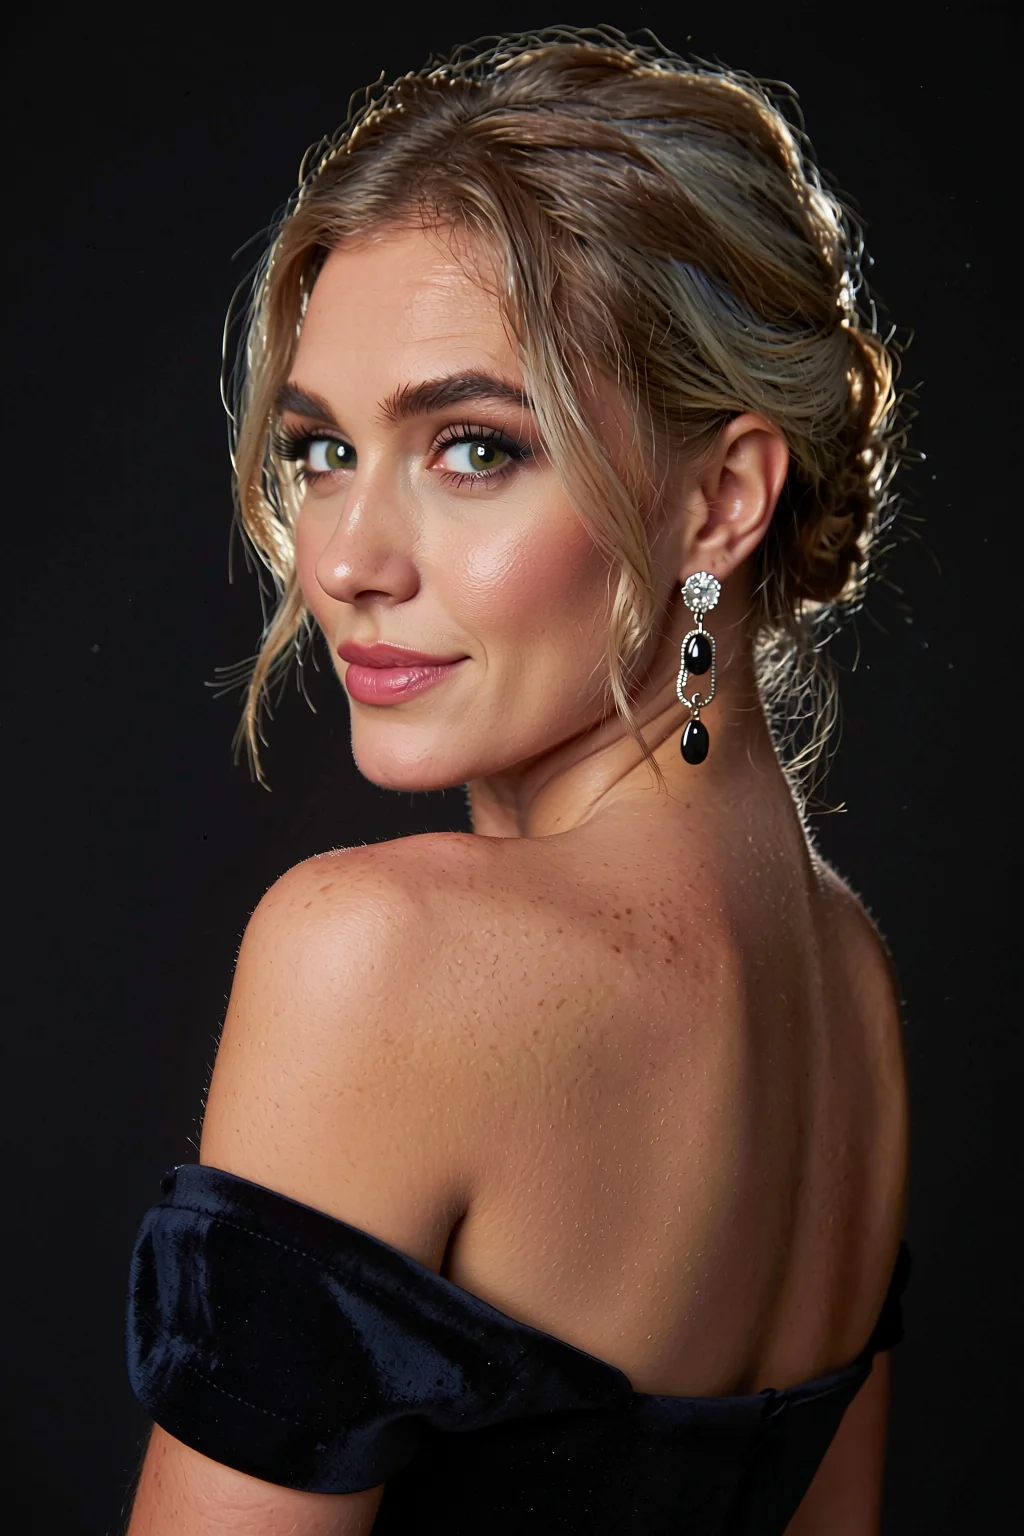
Portrait-retouch LoRA at scale 1, 2:3, seed 1.
Studio portrait photo. A 36-year-old woman with silver-blonde hair pinned up wears an off-shoulder black velvet gown and long earrings, looking over her bare shoulder at the camera. Soft key light, dark backdrop, rim light on her hair.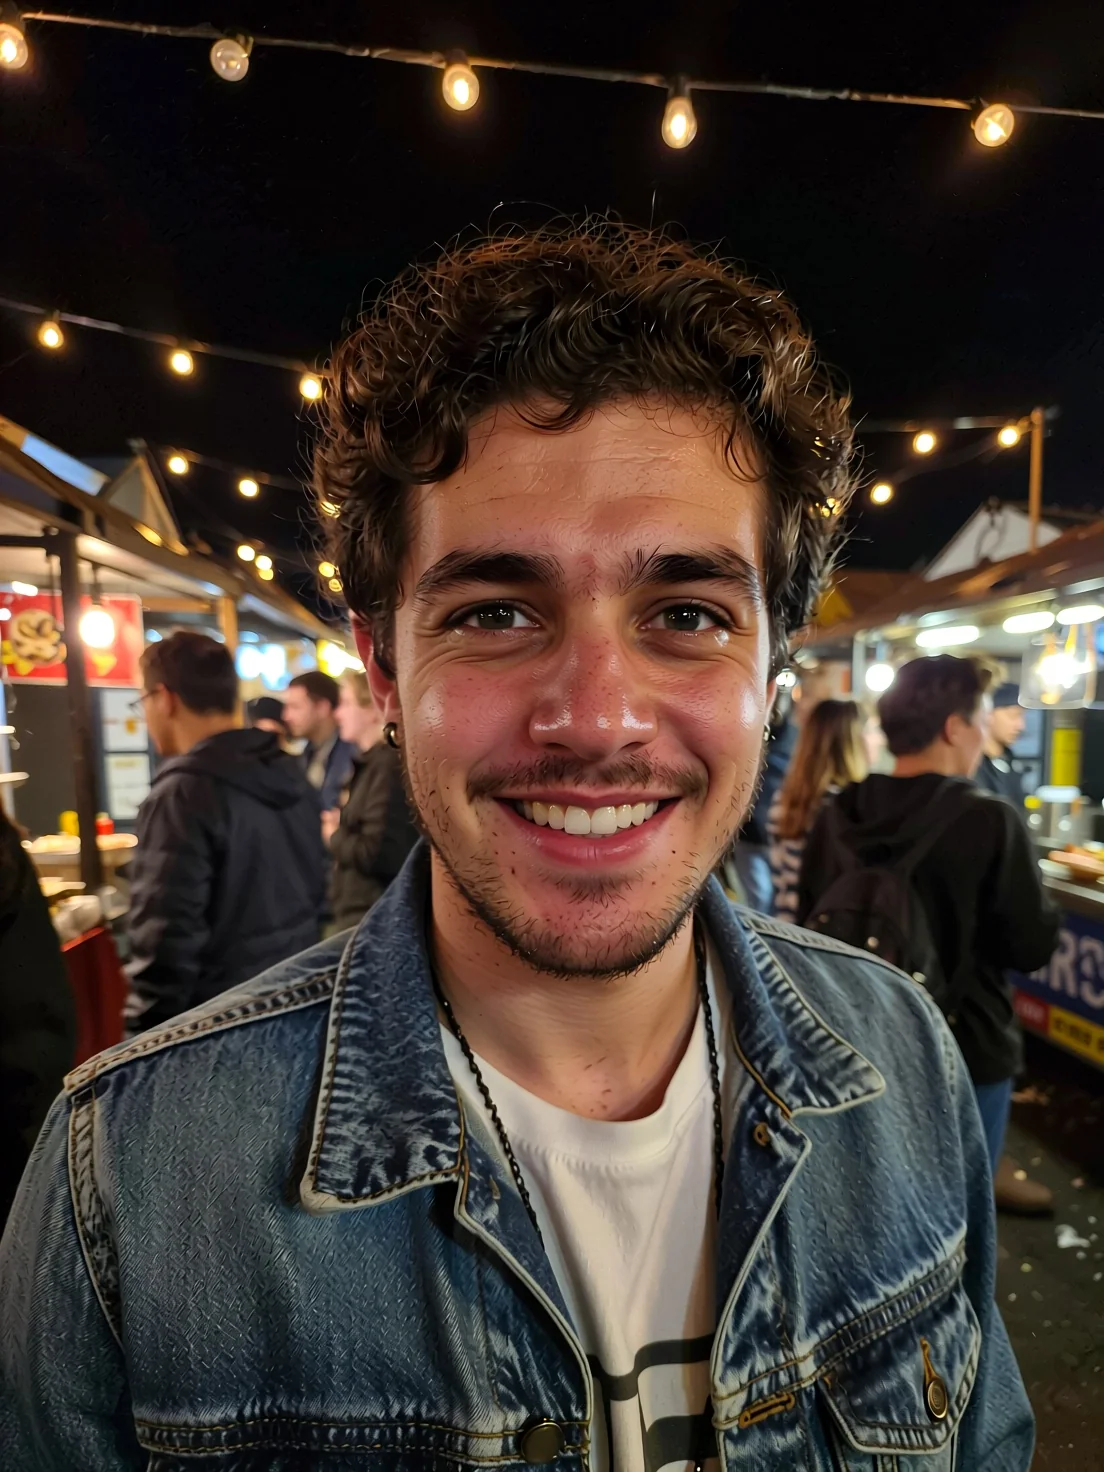
Phone-camera LoRA at scale 1, 3:4, seed 1. Prompt: "Amateur phone photo with on-camera flash. A 31-year-old man with curly dark hair and a short beard in a denim jacket over a white T-shirt grins at the camera at a crowded night market, string lights and food stalls behind him."
Style LoRAs barely move it. We asked for a "Japanese modern anime style" portrait. The base checkpoint ignored the phrase, and so did a Qwen-Image anime LoRA at scale 0.5, 1 and 2: the pixels changed but the picture stayed a photograph. At scale 4 the image broke into a distorted close-up with oversized eyes. A Qwen-Image-2512 pixel-art LoRA changed pixels and produced no pixel-art look.
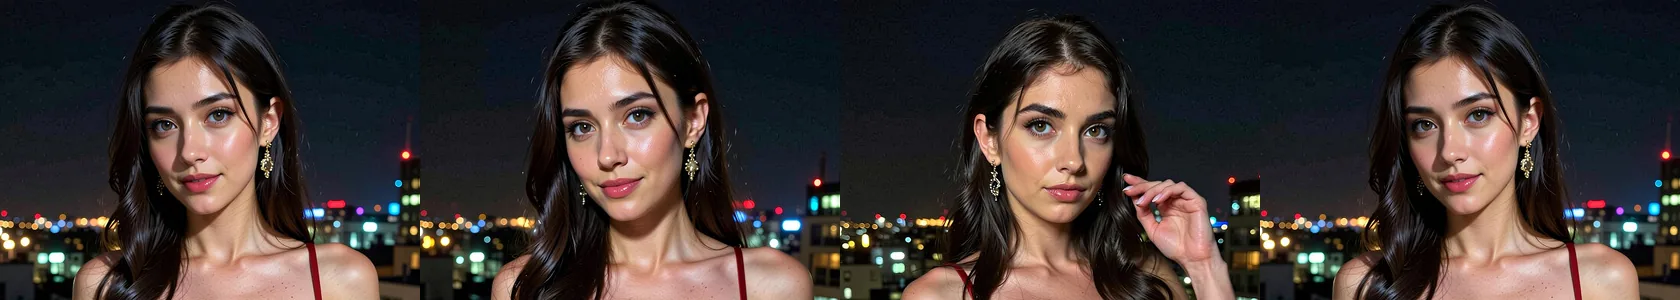
Face crops, left to right: no LoRA; an anime LoRA at 0.5; the same at 1; a FLUX LoRA at 1. Same prompt, seed 11, 3:4. All four stay photographs.
A LoRA for another base does nothing. A FLUX LoRA loaded without an error and gave pixel-identical output to using no LoRA. A successful response does not mean the file matched the model.
The useful scale range was about 0.5 to 1.5. Two stacked LoRAs worked well:
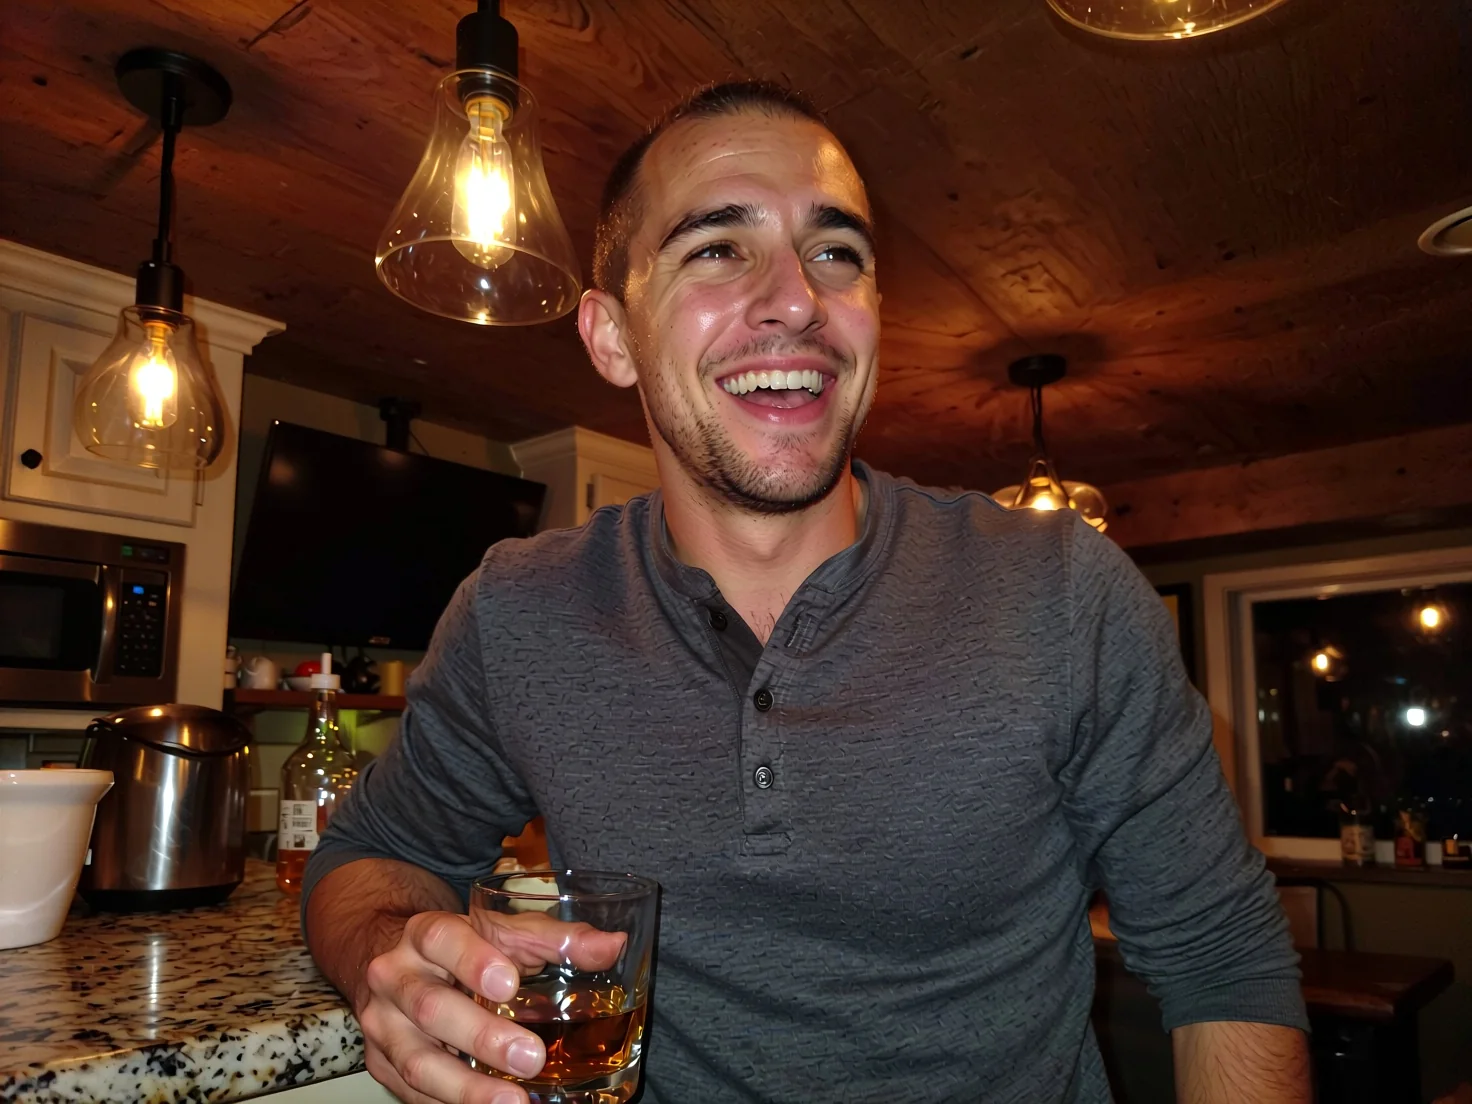
Samsung camera LoRA at 0.8 plus AWPortrait at 0.6, 4:3, seed 1.
Jib Mix Qwen or Qwen Image 2512 LoRA
Both are Qwen-Image family models with up to three LoRAs on the LoRA route. They are good at different jobs.
| Jib Mix Qwen (and LoRA build) | Qwen Image 2512 LoRA | |
|---|---|---|
| Base | Community merge on Qwen-Image | Qwen-Image-2512 for generation, Qwen-Image-Edit-2511 for editing |
| Tasks | Text-to-image only | Text-to-image and editing with 1 to 3 source images |
| LoRAs | Only on the LoRA build, up to 3 | Up to 3 on both tasks |
| Look out of the box | Photographic portraits, natural skin | General purpose; adapters set the style |
| Speed in our tests | Median 5.8 s (base) | Not measured in this round |
| Aspect ratios | 9, up to 1536 px | 9 for generation, up to 1536 px; editing follows the first source |
| Content in our tests | Ladder delivered except L4, softened | A 27 September ladder run delivered 15 of 18 briefs on each route; the three misses were the same intimate-scene class, which one external adult LoRA fulfilled on each task on 26 September |
Our rule of thumb: pick Jib Mix Qwen when you want a ready-made photographic portrait without hunting for LoRAs and you accept the faces limit. Pick Qwen Image 2512 LoRA when you need editing, when you already own a LoRA for the 2512 base, or when you want the base to take its look from your adapter. Our guide to matching weights to the task explains the 2512 versus Edit 2511 split, and the hosted LoRA roundup compares the wider field.
Limits
- Faces. Requests for East Asian faces came back European or ambiguous in all six of our tries, and many seeds converge on a similar face.
- Style range. Anime and pixel-art prompts and LoRAs left photographs. Use an illustration model for a drawn look.
- Two-person intimate scenes. Drawn without a refusal, with less precise anatomy.
- No negative prompt, steps or guidance, no image input, no editing.
- One image per request.
- Unknown version. The hosted route does not say which Jib Mix Qwen version it runs.
FAQ
Is Jib Mix Qwen uncensored?
Yes. The platform adds no content filter. Single-subject content came back as asked in our ladder, and two-person scenes were drawn without a refusal but with less precise anatomy.
Can it make East Asian faces?
Not reliably. Six requests for Japanese, Korean or East Asian women all came back European or ambiguous. Vary age, hair and features instead of using a nationality.
Do style LoRAs work on it?
Barely. An anime LoRA at 0.5, 1 and 2 left the image a photograph, and at 4 the picture broke. Photo, camera and portrait LoRAs are the ones that show.
What scale should I use for a LoRA?
Start at 1 and stay between about 0.5 and 1.5. Scale 4, the maximum, broke the image in our test.
Does a LoRA for another base model work?
No. A FLUX LoRA loaded without an error and changed nothing. Use LoRAs trained for Qwen-Image or Qwen-Image-2512.
Should I use the base endpoint or the LoRA endpoint?
The base endpoint if you will not load a LoRA. With no LoRA, the LoRA build gave pixel-identical output to the base on the same seed in our checks.
Can it render text inside the picture?
Short words, yes. Our chalkboard "OPEN LATE" read correctly in both seeds. Keep the phrase short and check the lettering before you publish.
Can I edit an existing photo with it?
No. Both endpoints are text to image. For editing with source images, use Qwen Image 2512 LoRA.