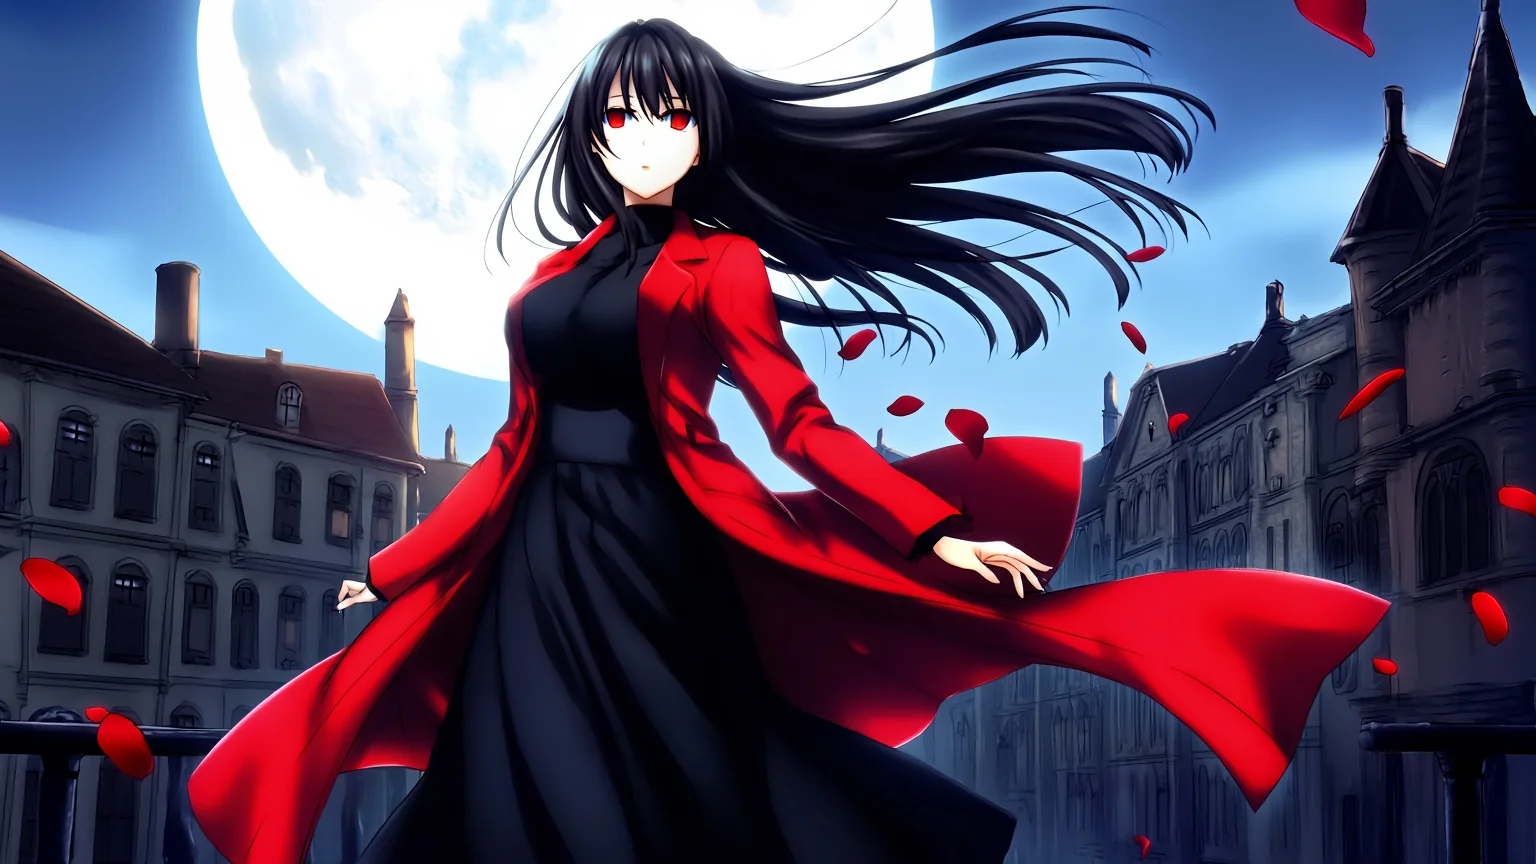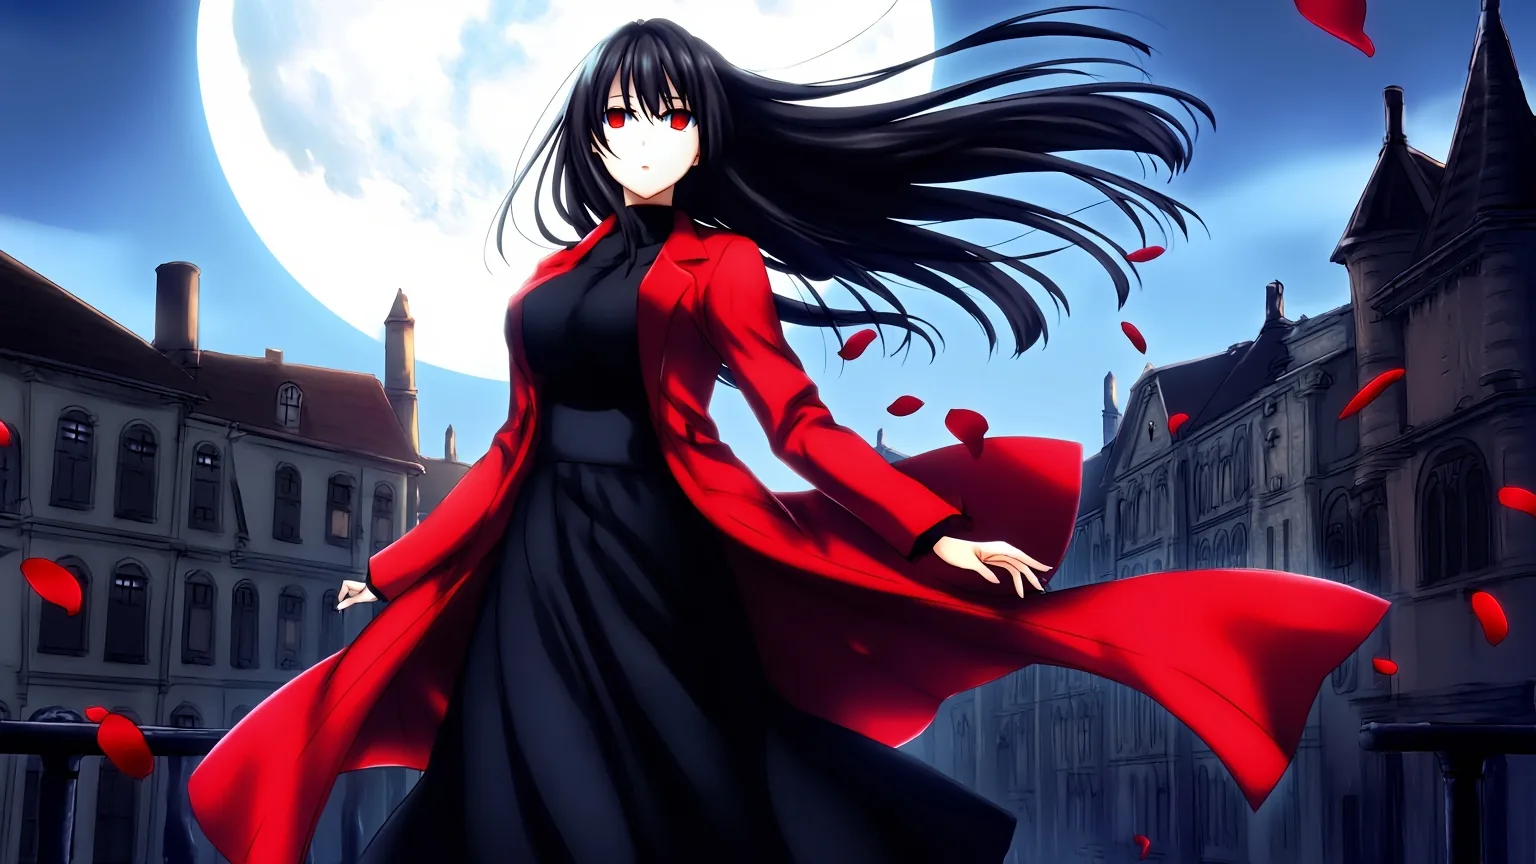
Neta Lumina is an uncensored anime model that reads Danbooru tags and plain sentences, and in our tests it delivered every level of our content ladder with no refusal and no substitution. The price of that freedom is time: across 31 runs on 5 October 2026 an image took 13 to 75 seconds, with a median of 40 and none under ten. It also has no negative prompt, no image input and no LoRA slot.
Neta Lumina is made by Neta.art Lab. It is a fine-tune of Alpha-VLLM's Lumina-Image-2.0 with a Gemma 2B text encoder, and it is public on SpicyAPI as neta-art/neta-lumina/text-to-image. Every prompt printed below is an everyday scene with clothed adults. The Neta Lumina family page lists the current per-image price.
At a glance
| Neta Lumina (tested 5 October 2026) | |
|---|---|
| Publisher and base | Neta.art Lab; fine-tune of Lumina-Image-2.0 with a Gemma 2B text encoder and the FLUX VAE |
| API model name | neta-art/neta-lumina/text-to-image (text-to-image only) |
| Public fields | prompt (up to 5,000 characters), aspect_ratio, output_format, seed |
| Aspect ratios | 9, all about one megapixel: 1024 x 1024 at 1:1, 1536 x 864 at 16:9, 1536 x 656 at 21:9 |
| Output | One image per request as JPEG (default), PNG or WebP |
| Speed in our tests | 13 to 75 seconds per image over 31 runs, median 40, none under 10 seconds |
| Content policy | Uncensored, no content filter; all five levels of our ladder delivered |
| Cannot do | Negative prompts, steps, guidance, sampler, image input, LoRAs, more than one image per request |
What Neta Lumina is
The publisher describes Neta Lumina as a high-quality anime-style image model. The Hugging Face card at huggingface.co/neta-art/Neta-Lumina says it is strong at anime illustration, posters, storyboards and character design, with wide coverage of characters and styles. The publisher says its prompt understanding is accurate even for complex prompts, that Danbooru tags are supported, and that Chinese, English and Japanese are the recommended languages. We tested English only.
The version question is worth a sentence. The publisher's repository dates from June 2025 and its v1.0 "official release" was uploaded on 22 July 2025. The hosted route does not state a version, so we cannot tell you which build answered our requests, and we did not try to guess from the images.
Two things set it apart from the other anime model we reviewed this week, Anima Turbo. It reads full descriptive sentences at least as well as tags, and it is slow. The table near the end puts the two side by side with Prefect Pony XL.
Tags, sentences or both
The publisher's prompt book suggests an order: characters, style, appearance, clothing, expression and action, camera, lighting, atmosphere, then quality tags. It also suggests an optional fixed opening line, "You are an assistant designed to generate anime images based on textual prompts." We ran one prompt twice with the same seed, once with that line and once without.
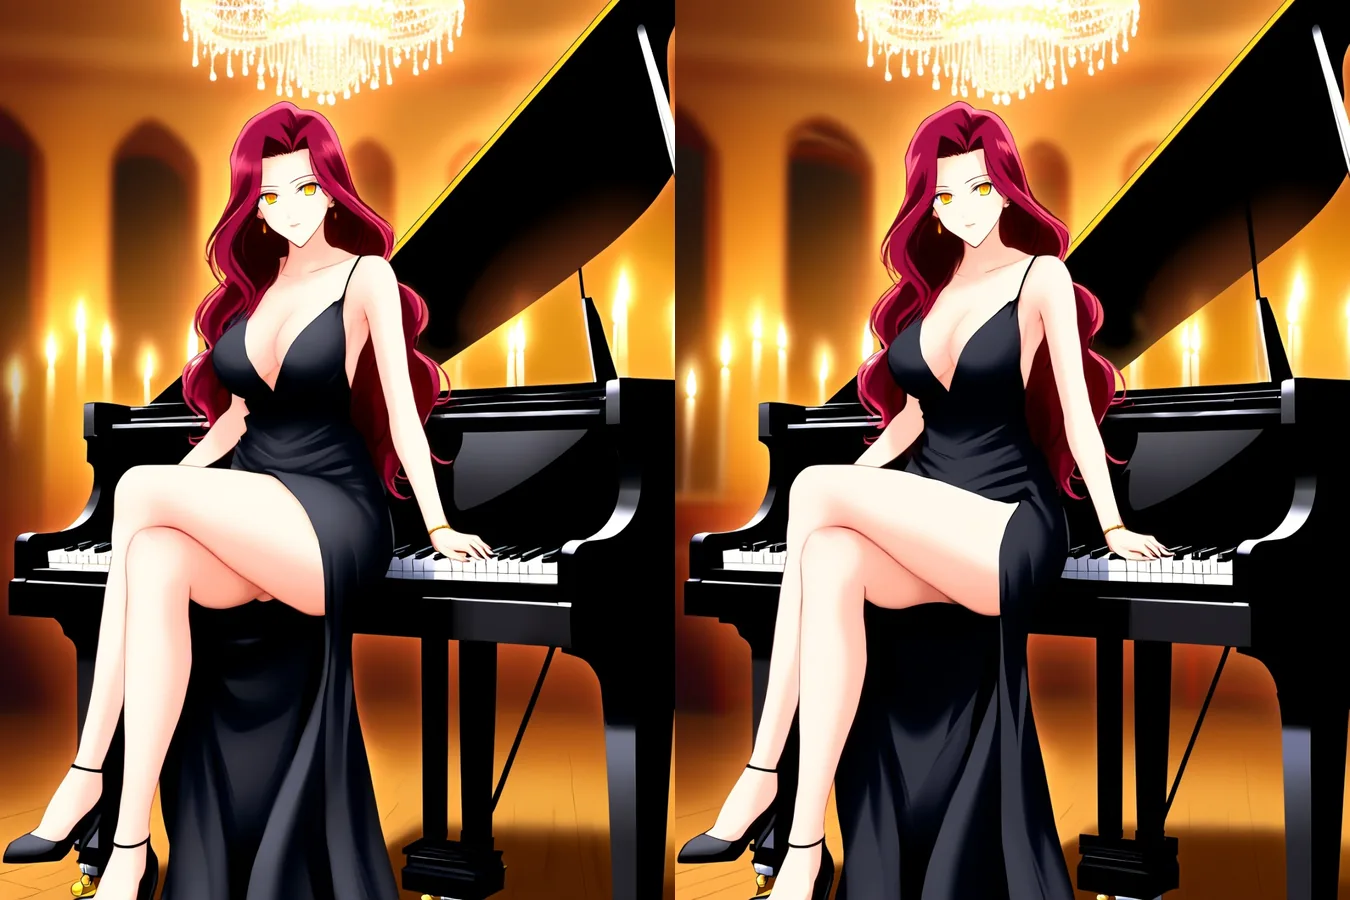
Left: with the publisher's opening line. Right: without it. Same prompt, seed 5, 3:4, text-to-image.
The two images are nearly identical, so on this endpoint the opening line is not needed. The prompt that drew the pianist was a plain tag list:
masterpiece, best quality, anime illustration, 1girl, solo, mature female, adult woman in her late twenties, long wavy crimson hair, golden eyes, black off-shoulder evening gown with a high leg slit, sitting on the lid of a grand piano, legs crossed, one hand resting on the keys, candlelit ballroom, crystal chandelier, warm rim light, looking at viewer, slight smileSentences work just as well. This one drew a man with a scar, an unbuttoned shirt and neon reflections without a single tag:
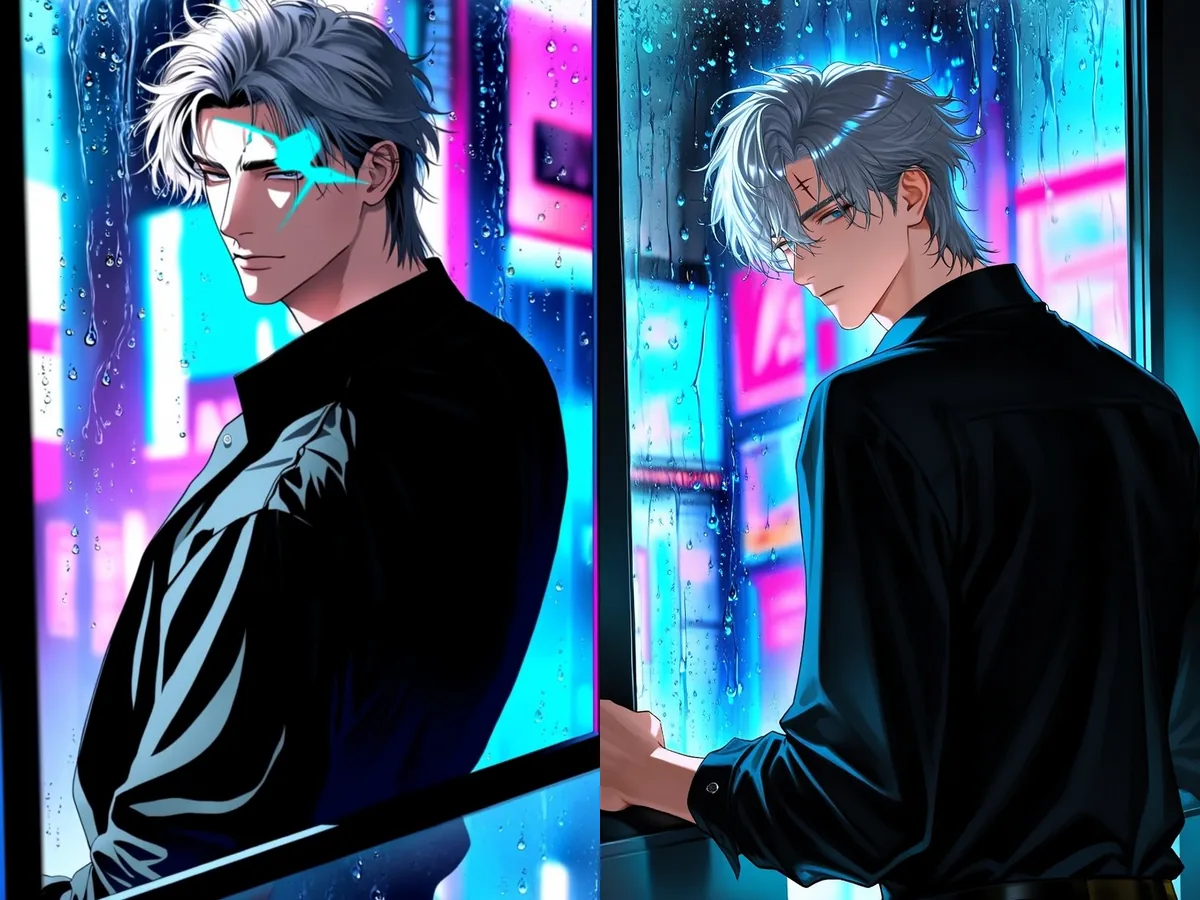
The same three sentences, seeds 1 and 2, 2:3. Seed 2 (right) is the published example; seed 1 drew a stray glowing cyan mark across the face.
An anime illustration of a handsome adult man in his early thirties with messy silver hair and a small scar through one eyebrow. He wears an unbuttoned black dress shirt and leans against a rain-streaked window in a neon-lit city at night, glancing over his shoulder at the viewer. Cyan and magenta reflections slide across his face.In our tests the scar, the shirt and the cyan and magenta light all made it into both seeds. What changed between seeds was execution: a stray mark in one, a clean face in the other. That is the pattern across this model, and it is why we recommend running two or three seeds of any prompt you care about.
| Situation | Better fit | Why, in our runs |
|---|---|---|
| One specific look: hair, eyes, outfit, setting | Tags | Each tag is its own instruction, and the pianist kept every detail |
| Camera position, light direction, how two people relate | Sentences | The neon-window man followed all three sentences |
| Two characters | Head-count tags first, then a phrase per person | In the shore couple, her sundress and his open shirt stayed with the right person |
| You want control and atmosphere | A tag header plus one or two sentences | A mix is what we would try first |
Sizes, formats and seeds
There is no size field. You choose one of nine aspect ratios, and each maps to a fixed size of about one megapixel. We ran every ratio once and every output came back at exactly the requested pixels.
| Ratio | Size | Ratio | Size |
|---|---|---|---|
| 1:1 | 1024 x 1024 | 21:9 | 1536 x 656 |
| 4:3 | 1280 x 960 | 9:21 | 656 x 1536 |
| 3:4 | 960 x 1280 | 16:9 | 1536 x 864 |
| 3:2 | 1344 x 896 | 9:16 | 864 x 1536 |
| 2:3 | 896 x 1344 |
The sizes follow the publisher's recommendation of roughly one to 1.3 megapixels. Output is JPEG by default; PNG and WebP both worked when we asked for them, and the output format does not change anything else. You can also set a seed from 0 to 2,147,483,647.
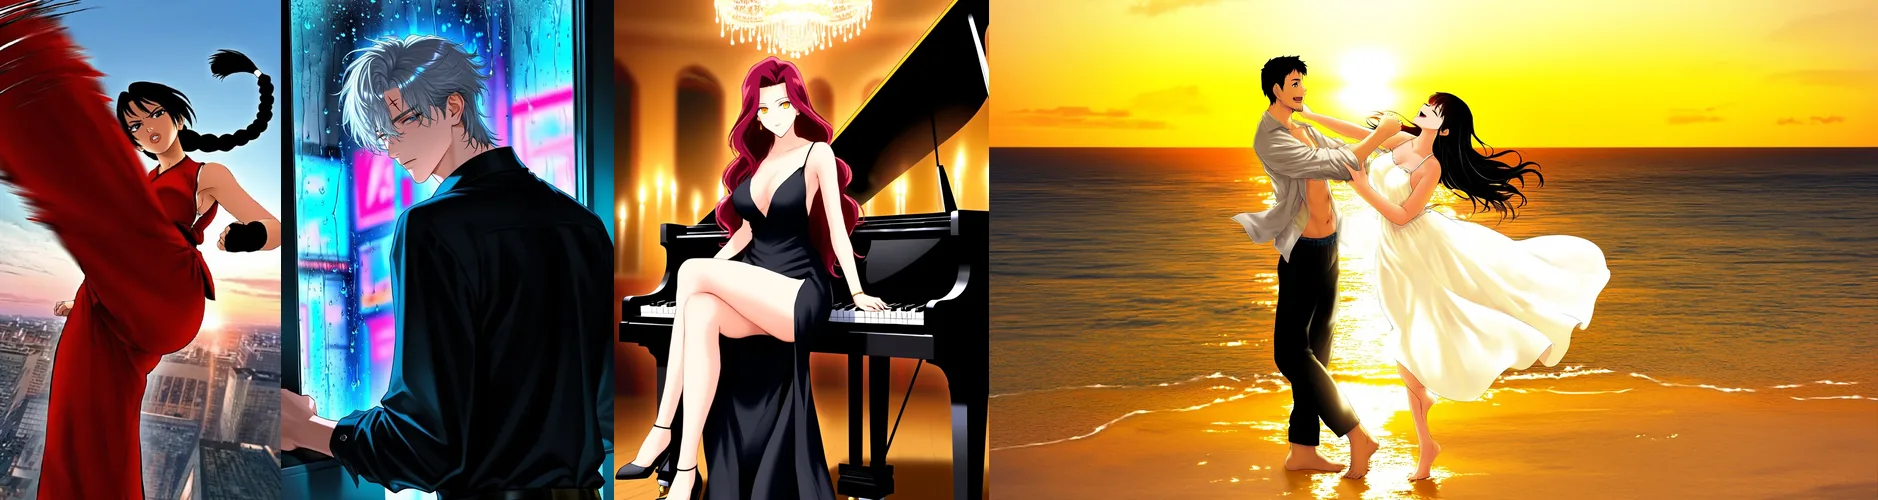
Left to right: 9:16, 2:3, 3:4 and 16:9, all text-to-image.
A wide frame suits scenes with two people. This one is the published 16:9 example:
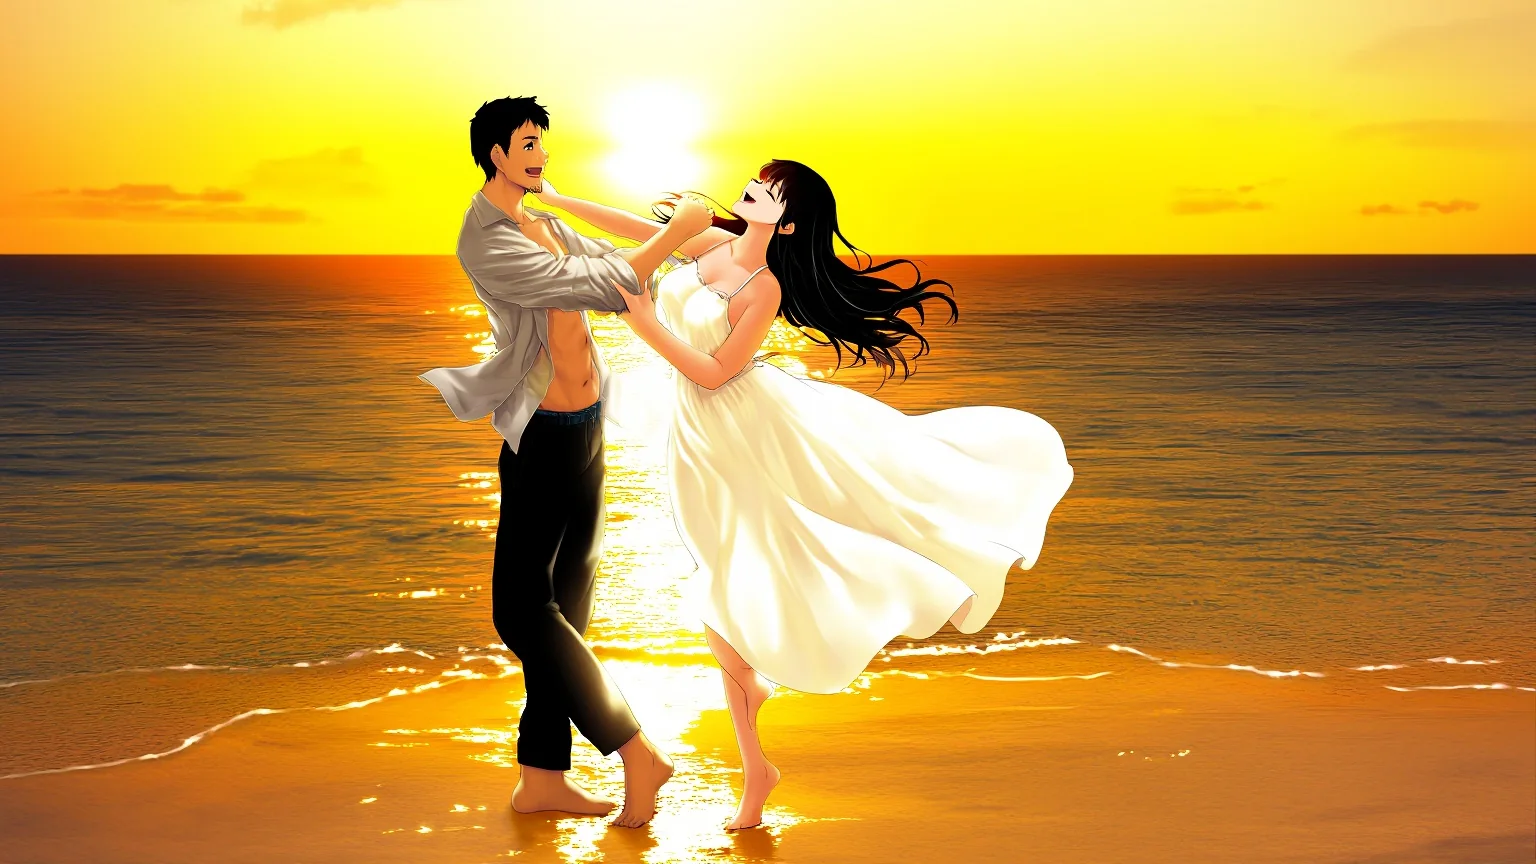
16:9, seed 2.
masterpiece, best quality, anime illustration, 1girl, 1boy, hetero, mature female, mature male, tall adult couple in their thirties, she has long wavy black hair and wears a white sundress with thin straps, he has short dark hair and stubble and wears an open linen shirt, barefoot, dancing at the edge of the sea at sunset, she laughs with her head tilted back, he spins her by the hand, golden sky, glittering waves, wide shotSeeds make runs comparable, not guaranteed identical, so use one to compare two prompt tweaks rather than to promise a pixel-exact redo.
Speed: plan for batches
We timed 31 runs. Model time was 13 to 75 seconds, the median was 40, and no run finished in under ten seconds. The publisher's host page quotes about 44 seconds, which matches. Size does not explain the spread: a 656 x 1536 image took 13 seconds, while 960 x 1280 images took anywhere from 14 to 75.
The practical consequences: do not build a live "type and see" box on it, send variations in parallel, and keep the seed fixed while you compare them. If you need drafts in a few seconds, Anima Turbo finished 52 of 60 runs in under ten.
How far it goes
The platform adds no content filter, so what you get is decided by the model and the prompt. We ran one prompt per rung of our five-level ladder at 3:4 with seed 1, and every prompt stated that the characters are adults. We looked at every image.
| Level | What we asked for | What came back |
|---|---|---|
| L1 Suggestive | Lingerie, a slipping strap | Delivered |
| L2 Partial | Partially revealing | Delivered, also across all nine ratios (9 of 9) |
| L3 Strong | Strong content, female and male | Delivered, both |
| L4 Intense | An intimate scene between two adults | Delivered as written, with no censoring |
| L5 Extreme | Consensual restraint between adults; cinematic gore | Both delivered |
There was no refusal and no substituted picture at any level. One detail is worth knowing for the L5 restraint prompt: the model drew a small mosaic-style censor over one area. L4 had none. We read that as a habit the model learned from its training art rather than a filter, since the platform adds nothing and the same area was uncensored elsewhere. If you need clean output, say so in the prompt, or reroll.
We do not print the ladder prompts, and the platform never provides prompts for stronger content. What we can say is that for an everyday request the model behaves like an anime model should, and for a stronger one it does not get in the way. Compare that with FLUX 3 and Ideogram v4.5, which refused almost everything past a neutral swimwear photo in our tests.
What went wrong
Honest reporting means showing the misses. Our key-visual prompt, an adult woman in a crimson coat on a moonlit rooftop, came out well on seeds 1 and 3 and badly on seed 2:
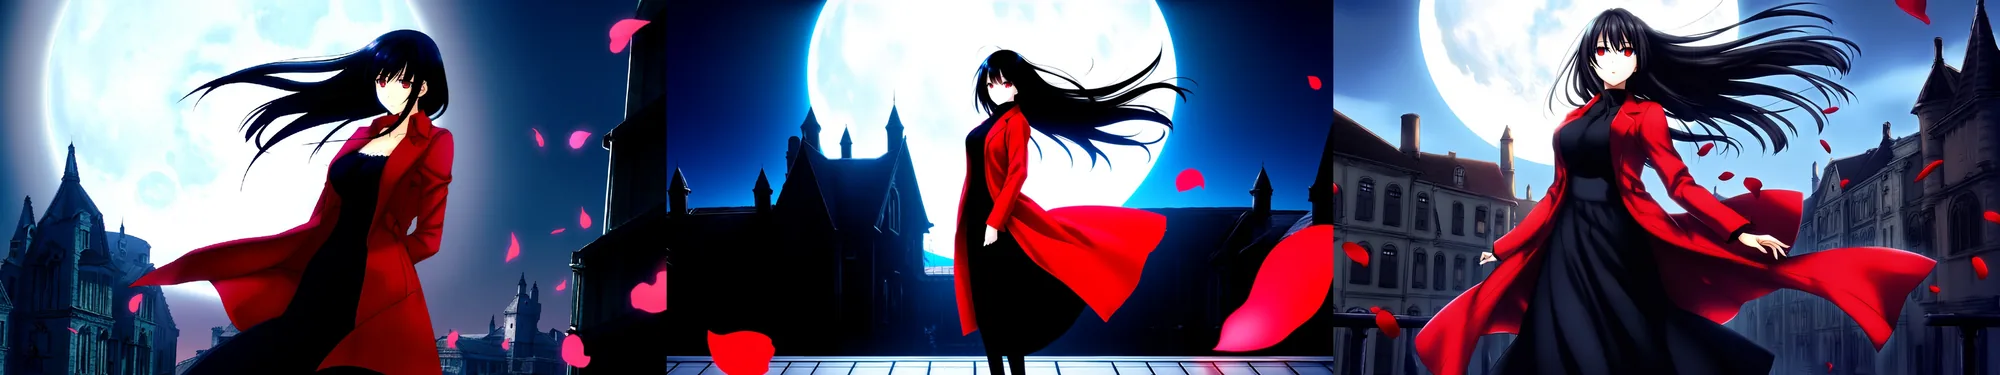
One prompt, seeds 1, 2 and 3, 16:9. Seed 2 (middle) turned the woman into a small figure against a silhouette.
Action poses are the least reliable corner. The prompt that gave us a clean flying kick on seed 1 tangled the limbs on seed 2:
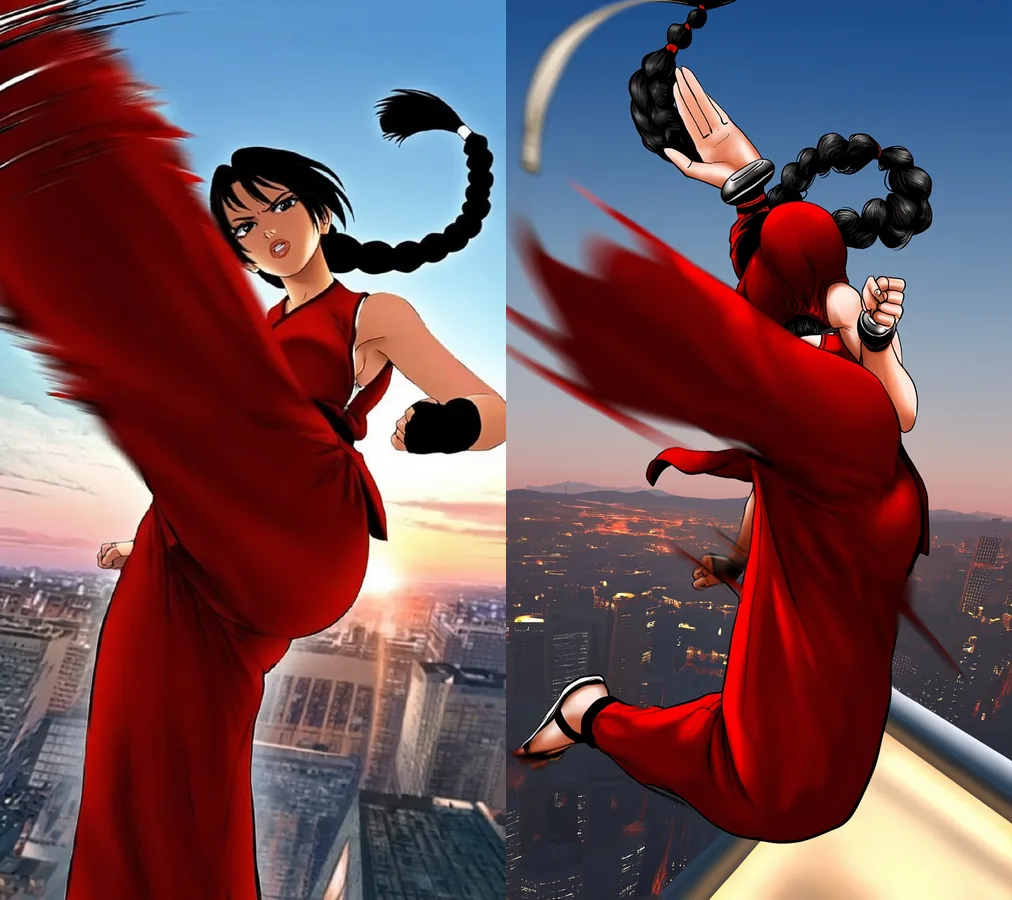
Left: seed 1. Right: seed 2. 9:16, same prompt.
masterpiece, best quality, anime illustration, 1girl, solo, mature female, adult woman martial artist with a long black braid, red sleeveless fighting outfit, flying kick toward the viewer, foreshortening, dynamic angle, motion lines, rooftop at dusk, city skyline, dramatic lightingEven the pianist varies. Two seeds of the same prompt gave two different rooms and poses:
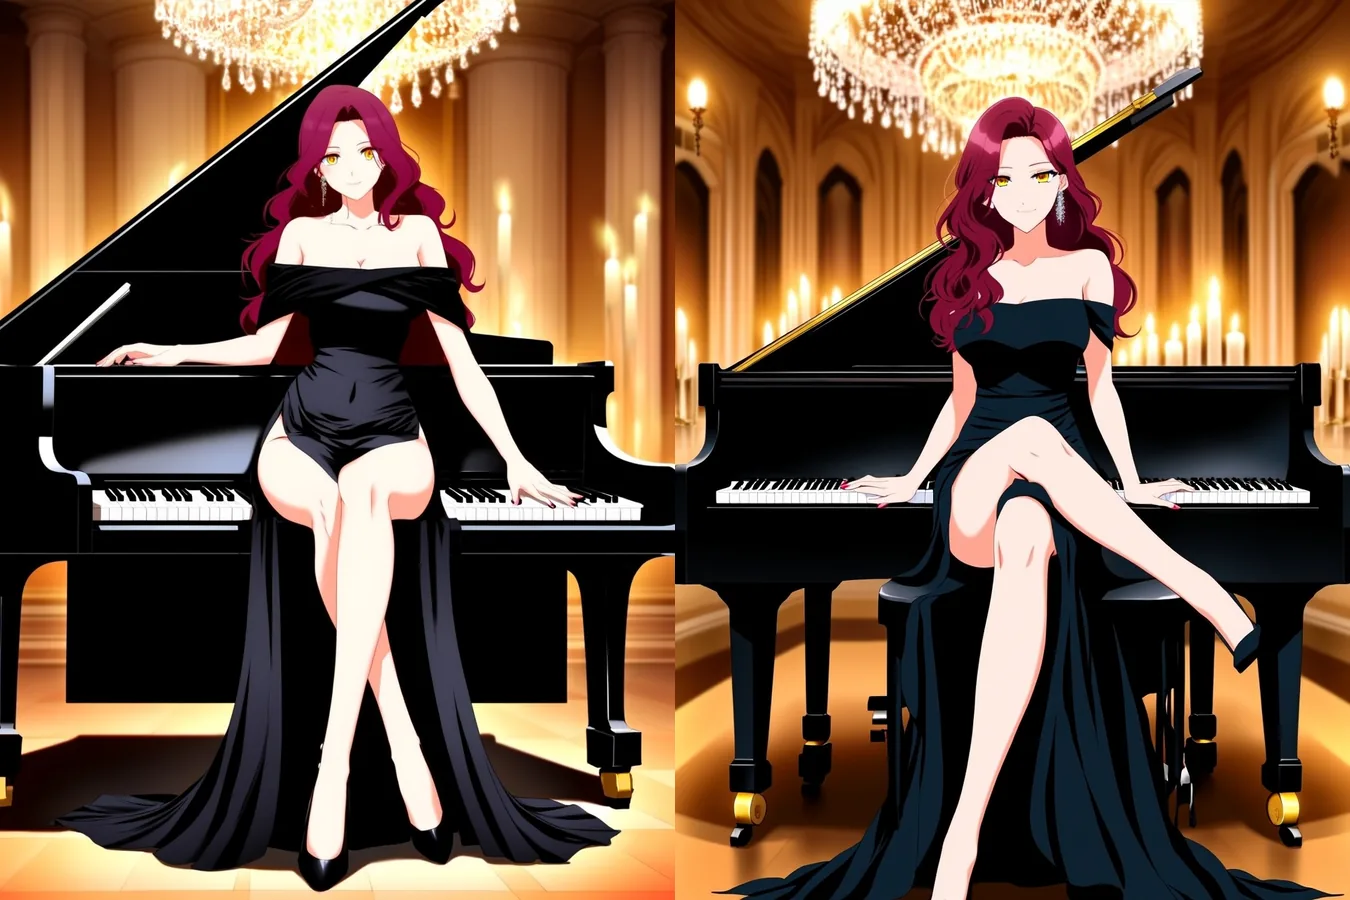
The pianist prompt, seeds 1 and 2, 3:4.
Limits
- Slow. 13 to 75 seconds per image, median 40.
- No negative prompt, steps, guidance or sampler. The public fields are
prompt,aspect_ratio,output_formatandseed. - Text to image only. There is no image input and no LoRA slot.
- One image per request.
- Occasional artefacts. The model sometimes adds a signature-like scribble or a pixelated patch learned from its training art. A new seed is the fix.
- Action poses need rerolls. Plan for two or three seeds.
Neta Lumina, Anima Turbo and Prefect Pony XL
All three are uncensored anime models on SpicyAPI. The rows below use only what we measured on 5 October 2026 for Neta Lumina and Anima Turbo, and what is published on the model pages for Prefect Pony XL, which we last tested in an earlier internal run on 18 September 2026.
| Neta Lumina | Anima Turbo | Prefect Pony XL | |
|---|---|---|---|
| What it is | Neta.art Lab fine-tune of Lumina-Image-2.0 | CircleStone Labs, 2B parameters, distilled Turbo build | Community anime checkpoint of the Pony XL lineage |
| Prompt style | Tags, sentences or both | Danbooru tags, also reads sentences | Pony-style tags |
| Aspect ratios | 9 at about one megapixel | 15, on 1k and 1.5k tiers | 7 native SDXL sizes |
| Speed in our tests | 13 to 75 s, median 40 | 2 to 16 s, 52 of 60 under 10 | Not measured in this round |
| Image-to-image | No | Yes, on its image-to-image endpoint | No |
| LoRAs | No | Not on the base family; its LoRA sibling takes up to three | No |
| Negative prompt | No | No | Not covered here |
| Content in our tests | All five levels delivered | Strongest content probe rendered as written on the first try | Three probe levels up to L4 rendered in the 18 September run |
| Output format | JPEG, PNG or WebP | JPEG | See the model page |
Pick Neta Lumina when you want an anime model that follows a long descriptive sentence and you can wait for it. Pick Anima Turbo for fast drafts, image-to-image or LoRAs. Pick Prefect Pony XL if your prompts already come from the Pony ecosystem. Our roundup of NSFW anime models covers the wider field.
Who should use it
Use Neta Lumina for key visuals, posters, character designs and storyboard frames where you will run a handful of seeds and keep the best. Skip it if you need speed, editing, a negative prompt or a style LoRA. Start at the text-to-image page.
FAQ
Is Neta Lumina uncensored?
Yes. The platform adds no content filter, and in our ladder of five levels, from L1 Suggestive to L5 Extreme, every level was delivered with no refusal and no substituted image. The model itself drew one small mosaic-style censor on the L5 restraint prompt, which it appears to have learned from its training art.
Does it use tags or sentences?
Both. Danbooru-style tags worked for the pianist and plain sentences worked for the neon-window man. Use tags for a precise look and a sentence for camera, light and mood.
Do I need the publisher's opening line?
No. With and without "You are an assistant designed to generate anime images based on textual prompts." gave nearly identical images on the same seed.
Why is it slower than other image models here?
We measured 13 to 75 seconds of model time over 31 runs, median 40, and image size did not explain the spread. Send variations in parallel and fix the seed while comparing.
What sizes does it support?
Nine aspect ratios at about one megapixel, from 1024 x 1024 at 1:1 to 1536 x 864 at 16:9 and 1536 x 656 at 21:9. Every output matched the requested size in our test.
Can I use LoRAs or a source image?
No. This endpoint is text to image only. For LoRAs or image-to-image on an anime model, look at Anima Turbo LoRA and the Anima Turbo image-to-image endpoint.
Is the same seed guaranteed to give the same image?
No. Seeds keep runs comparable, but treat a repeat as close rather than guaranteed.