Alibaba's Wan 2.7 text-to-image uses a reasoning pass to plan the composition before drawing. It returns one to four images per request at about 1 megapixel across seven aspect ratios, with a seed to steady comparisons.

Filtering differs by endpoint: Image editing — Uncensored, Text to image — Softened.

From $0.03/image

Workbench

Input

Text to image
502/5000
Describe the frame: subject, action, camera position, then light and lens. Wan 2.7 plans composition first, so one clear spatial relationship beats a pile of adjectives. at least 1 characters · at most 5000 characters
1:1, 4:3, 3:4, 16:9, 9:16, 3:2 or 2:3. Defaults to 1:1. The pixel budget is the same for all of them, so a wider ratio is wider, not larger.
Deep thinking
Lets the model reason about the prompt before it starts generating. Turning it off is noticeably faster and usually costs nothing in quality on detailed prompts.
1k or 2k; 1k by default. 2k carries four times the pixels of 1k, and the shape still follows aspect_ratio.
Color palette0/10
    Optional colour theme of 3 to 10 colours (8 is the recommended count). Enter each colour as a #RRGGBB hex code and, if you want, the share of the image it should cover in percent; rows left empty split whatever share is left, so leaving them all empty weights the colours equally. It steers the palette of the whole frame — set, wardrobe and light. No effect on price. at least 3 items · at most 10 items
    Seed
    0 to 2147483647. Hold it and change one clause at a time: the same seed keeps the draw steady, so the clause is what moved. It is a comparison tool, not a guarantee of an identical image. no lower than 0 · no higher than 2147483647
    Safety checkerOff

    SpicyAPI does not run a safety checker on this model. Your prompt and media go to the model as written, and the model itself decides what comes back.

    Checking your account before enabling submission and pricing.

    Output

    Ready for a new run
    wasteland-three-depthsExample result

    Related models and next tasks

    Missing the model you need?

    Tell us what to add and where you would use it. Requests go to the people who decide what gets onboarded next.

    Composition worked out before a pixel renders

    The Wan 2.7 text to image API turns a prompt into one to four images, and it runs an internal reasoning pass first, resolving layout, object relationships and lighting before anything renders. The payoff shows up on compound instructions: several subjects, a stated spatial relationship, a light source that has to read consistently across the frame. The canvas comes from seven aspect ratios and two resolution tiers, 1k or 2k.

    Open the playground
    Composition worked out before a pixel renders
    Canvas budget
    About 1 megapixel at 1k, about 4 at 2k, shared evenly across all seven ratios
    Aspect ratios
    1:1, 4:3, 3:4, 16:9, 9:16, 3:2, 2:3
    Prompt length
    Up to 5,000 characters, one pass over the whole scene
    Images per call
    1 to 4 via num_outputs, each billed as its own image
    Reasoning pass
    enable_thinking is on by default; turn it off for a faster render
    Seed
    0 to 2,147,483,647, or leave it out for a fresh draw
    Reasoning
    One prompt, not five short instructionsThe reasoning pass already resolves most ambiguity, so a single well-structured description outperforms several short clauses competing for the model's attention.
    Canvas
    Ratio and resolution decide the pixel budgetresolution picks the tier, about 1 megapixel at 1k or about 4 at 2k — and all seven ratios draw from it evenly, so a 9:16 portrait doesn't come out softer than a 1:1 square.
    Scale
    Wan 2.7 Pro is where the 4k tier lives2k already quadruples the pixels of 1k. Above that, Wan 2.7 Pro's text-to-image carries a resolution field of its own with a 4k option, which Alibaba's documentation limits to text-to-image; every editing endpoint in both families stops at 2k.

    What the Wan 2.7 API does well

    Compound instructions hold together

    Compound instructions hold together

    Multiple subjects, an explicit spatial relationship ('the cup left of the plate, in shadow'), or a light source shared across the frame tend to resolve correctly instead of drifting between clauses. The reasoning pass reads the whole prompt as one scene before it starts drawing, so a relationship stated in the first sentence still holds by the last.

    No falloff at extreme ratios

    No falloff at extreme ratios

    Each of the seven ratios gets its own pixel dimensions out of the same budget, so a wide 16:9 frame and a tall 9:16 frame carry comparable detail. A 16:9 request is wider than a 1:1 request but not larger, which means picking a ratio is a framing decision and has no bearing on how much detail lands in the file.

    • Controlled repeat runs

      Keep the seed and the full request so later variants can be compared against it; identical inputs still do not guarantee the same image. Change one field between calls, such as the ratio or a wardrobe clause, and the fixed seed keeps the rest of the composition close enough that the difference is the thing you changed.

    • One to four images, each priced as one

      num_outputs runs from 1 to 4 and is the only field that multiplies the bill — every image is charged separately. Prompt length, aspect ratio and resolution add nothing, and the estimate shown before you submit already covers the whole batch.

    • No quality preset to tune

      Six fields, and none of them is a quality dial: no sampler setting and no step count to get wrong. resolution sets the size, and enable_thinking, on by default, is the one switch that changes how the image is worked out. Turn it off for a faster draft; the edit endpoint has no such switch, because Alibaba's documentation limits that pass to prompts sent without an input image.

    Who Wan 2.7 is for

    • Scenes with more than one moving part

      Concept work

      Scenes with more than one moving part

      A character interacting with a specific prop, two subjects in a stated spatial arrangement, or a scene where the light source has to be consistent across several elements. These are the prompts that break down into keyword lists on faster models; writing them as one connected sentence gives the reasoning pass something to resolve.

    • Compositions that name a relationship between objects

      Product and editorial

      Compositions that name a relationship between objects

      Describe how objects sit relative to one another, since that relationship is what the reasoning pass resolves. For a product still life that means naming which item sits in front, which falls in another's shadow and where the reflection lands, then holding seed while the same arrangement is redrawn at 3:2 and at 9:16.

    • Build a set around one likeness

      Character sheets

      Build a set around one likeness

      Lock a seed once a likeness is settled, then vary wardrobe or setting clauses one at a time to build out a set. The fixed seed helps, but check each result, since the face can still drift.

    • Batches where composition accuracy matters more than print size

      High-volume concepting

      Batches where composition accuracy matters more than print size

      1k suits screen review and social-scale output, and enable_thinking set to false shortens each pass while compositions are still being sorted; switch to 2k for the frames that ship, and to Wan 2.7 Pro's text-to-image only when even that is too small.

    How to call the Wan 2.7 API

    1. Decide the ratio first

      aspect_ratio is the only field that changes the frame's shape, and the same description composes differently on a portrait canvas than a wide one. Picking it first avoids a mismatch between a composition written for a square frame and a canvas that ends up tall or wide instead.

    2. Write one prompt for the whole scene

      The reasoning step is already resolving ambiguity, so a single structured description beats several short, competing instructions. Cover subject, action, spatial relationships and light in the same paragraph; prompt accepts up to 5,000 characters, far more room than a compound scene needs.

    3. State relationships explicitly

      Name how elements relate ('behind', 'in shadow of', 'matching the color of') rather than listing them side by side. A flat list of objects gives the reasoning pass nothing to resolve; naming the relationship is what it actually reasons about.

    4. Explore without a seed, then lock it

      Leave seed unset while you're still finding the composition; once a result is close, fix that seed and change one field at a time. An unset seed gives a fresh draw on every call, useful for surveying options before committing to a direction to refine.

    5. Raise resolution before changing model

      If the result already reads correctly and only needs to be bigger, set resolution to 2k: same prompt, four times the pixels. Wan 2.7 Pro's text-to-image is the step after that, and a 4k tier is the only thing it adds to the size question.

    Wan 2.7 worked examples

    • A still life with an explicit spatial relationship

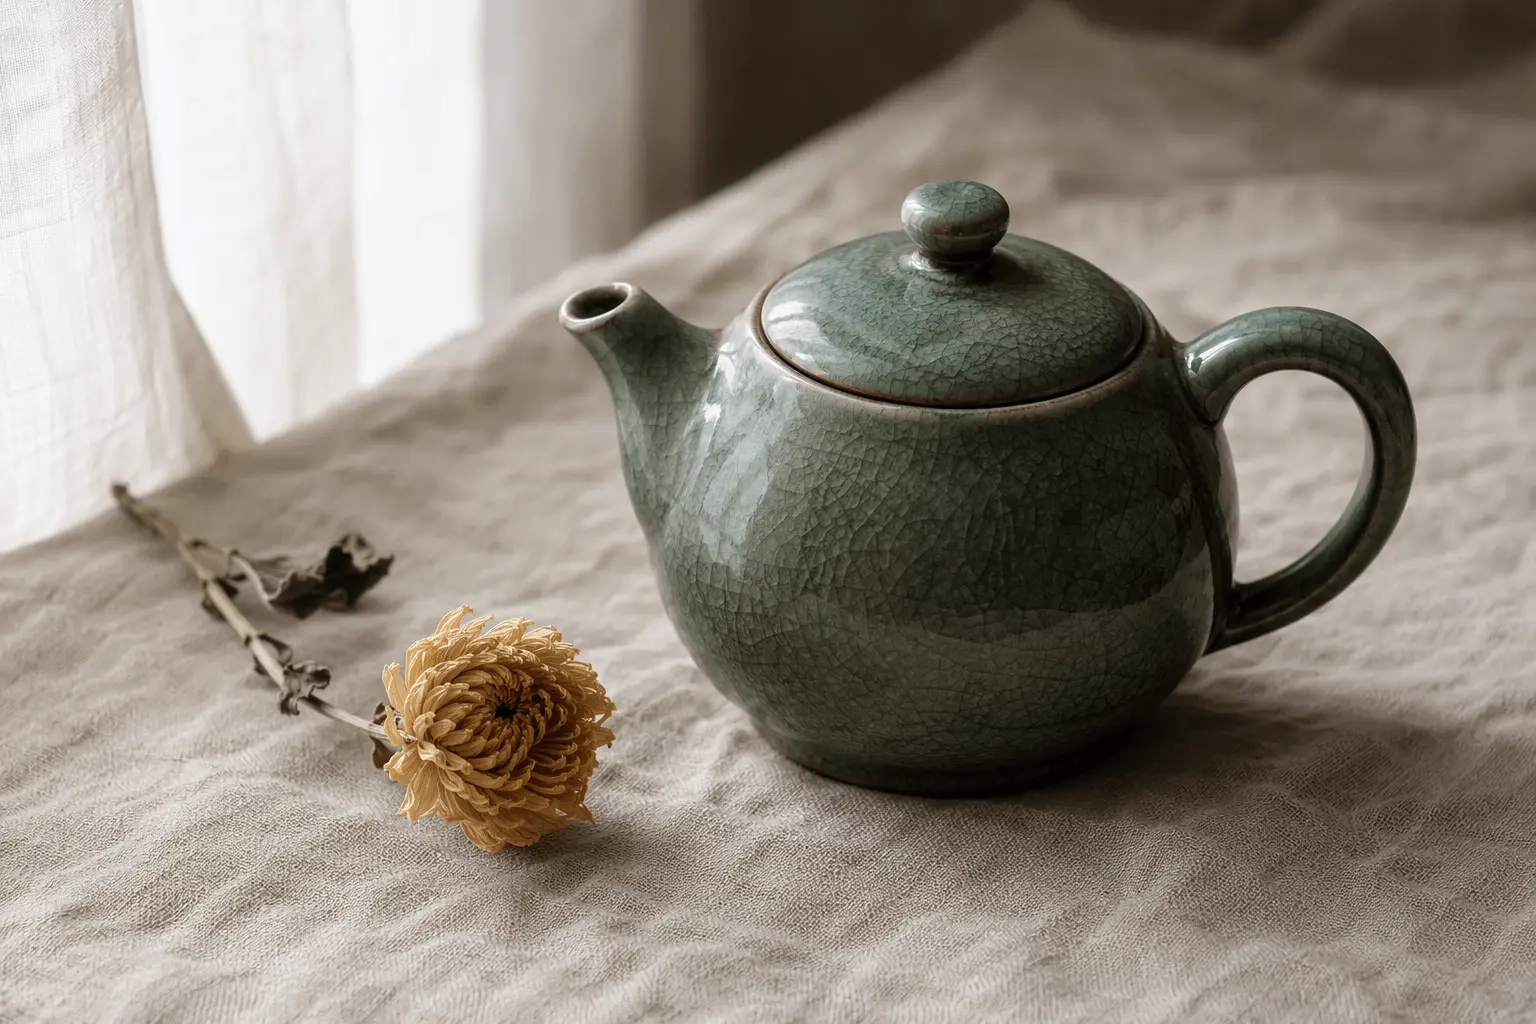
      Naming the relationship between the teapot, the cloth and the light keeps the composition from drifting into a generic product shot.

      A hand-thrown stoneware teapot glazed in deep celadon, resting on undyed linen beside a single dried chrysanthemum stem, soft window light from the left, fine crackle texture visible in the glaze
    • A portrait sheet around one identity

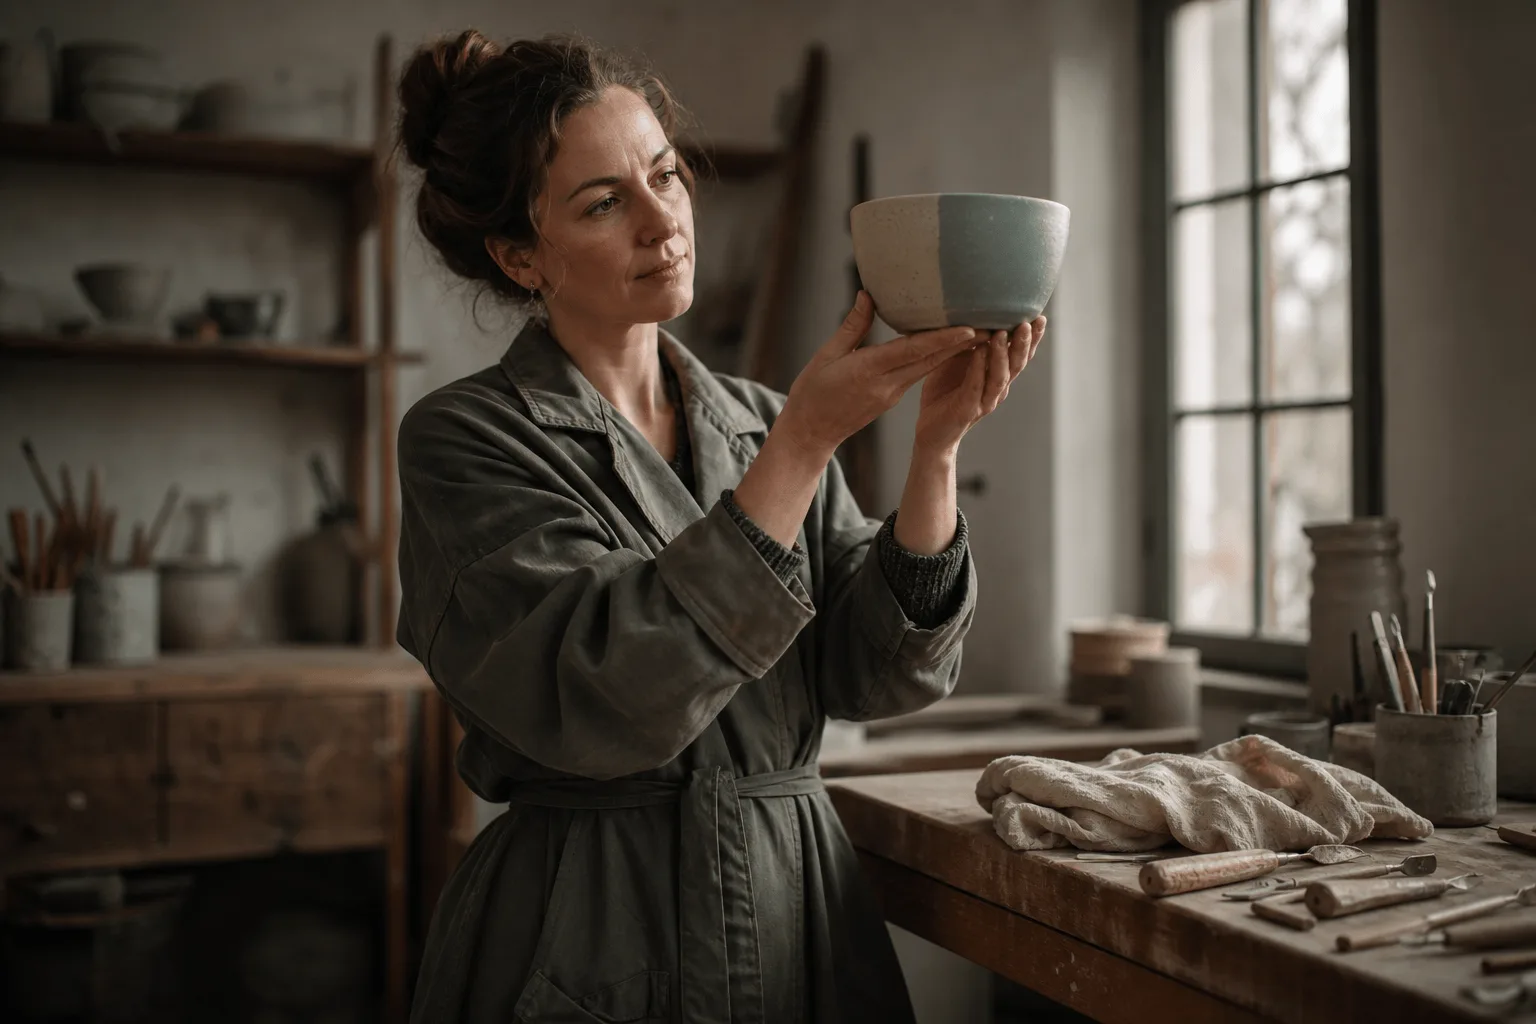
      Fix one seed as the identity anchor, then change only wardrobe and background across calls; the reasoning pass helps keep facial structure steady while those clauses change, though an exact match is not guaranteed.

      Portrait of a woman in her thirties, short dark hair, small scar above the left eyebrow, three-quarter view, overcast daylight, muted olive coat
    • One light source across a wide frame

      Naming a single light source and asking every object in the frame to answer to it is the kind of instruction the reasoning pass is built to resolve, and it holds across a wide 16:9 crop as readily as a square one.

      A row of five mismatched ceramic vases on a long wooden shelf, each holding a different dried flower, one warm lamp glowing from the left edge of the frame so every vase casts a soft shadow to the right, fine dust visible in the light

    Wan 2.7 API questions

    Write the whole scene in one structured paragraph: subject, what it is doing, where the camera sits, then the light. Put exclusions in that same paragraph, because there is no negative-prompt field to move them to. Settle the composition at 1k with seed left out, then fix that seed, raise resolution to 2k and change one clause per call, so every difference you see is the one you introduced.

    All Wan models22

    Video models18