bytedance/omnihuman-2.0/talking-avatarOmniHuman 2.0 talking avatar turns one portrait and an audio file into a 720p clip of that person speaking or singing it. The clip is as long as your audio, from 4 to 300 seconds.
Workbench
These examples were written for this endpoint. Replace the prompt and sample media URLs with your own accessible inputs, then check the current quote and model availability before submitting.
- Output6s
supper-club-singer 720p: `image_url` is a woman with dark pin curls and red lipstick in a black velvet gown at a vintage microphone in a blue-lit supper club; `audio_url` is a slow sung/spoken line of 5.2 seconds. The lips track the audio, a small head tilt and a smile land at the end as the prompt asks, and her hand stays on the microphone. The returned clip runs 6.0 seconds.
- Output6s
bar-counter-line 720p: `image_url` is a man in his forties with salt-and-pepper stubble and a dark linen shirt behind a dim bar; `audio_url` is a spoken line of 5.0 seconds. His eyes close and reopen, and the half smile and raised eyebrow follow the line while the bottles behind him stay stable. The returned clip runs 6.0 seconds.
- Output5s
seaside-terrace 720p: `image_url` is a woman with long dark hair in a cream satin trench on a stone terrace above the sea; `audio_url` is a spoken line of 4.55 seconds. In the final second her head turns toward the sea as the prompt asks, and her hair moves slightly. The returned clip runs 5.0 seconds.
- Output5s
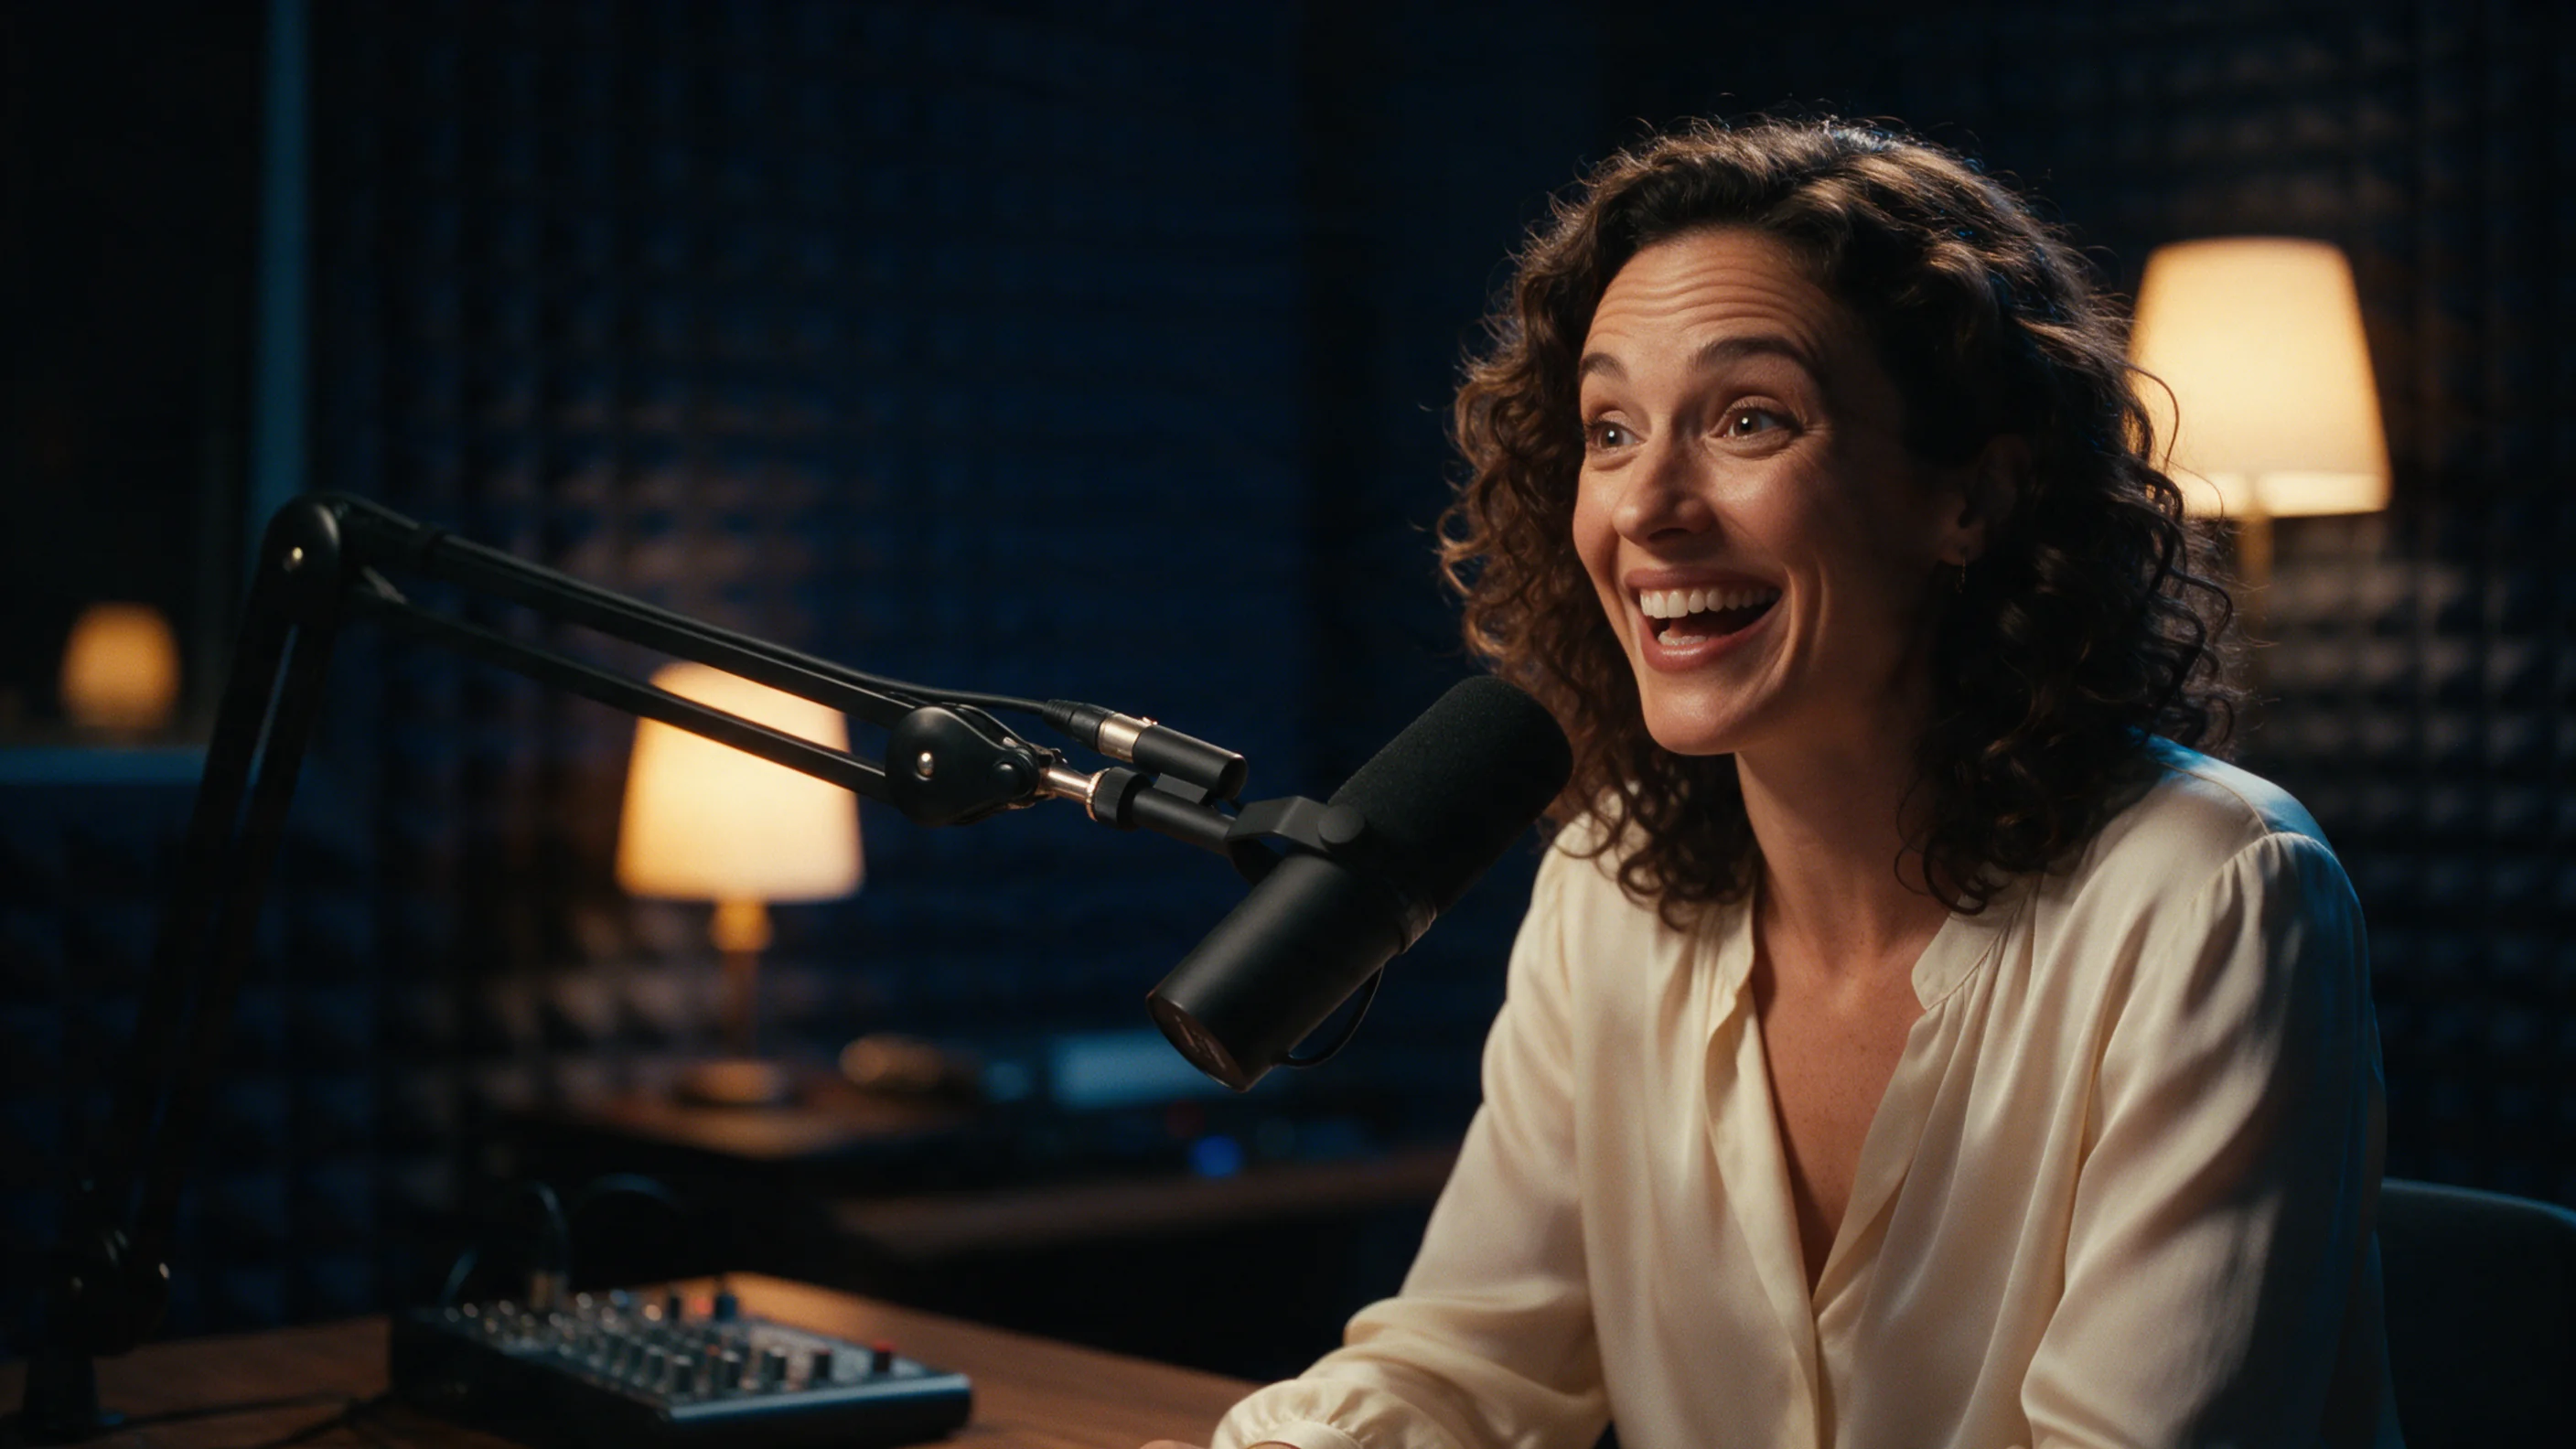
late-night-show-open 720p: `image_url` is a woman with natural curls in a cream blouse in a podcast studio with a boom microphone and lamps; `audio_url` is an upbeat spoken intro of 4.8 seconds. Wide open-mouth expressions, eyebrows and a laugh on the last word follow the prompt, but she does not visibly lean toward the microphone. The returned clip runs 5.0 seconds.
This example starts at $0.108 per output second. The Playground updates the estimate when you change the settings.