Introduction
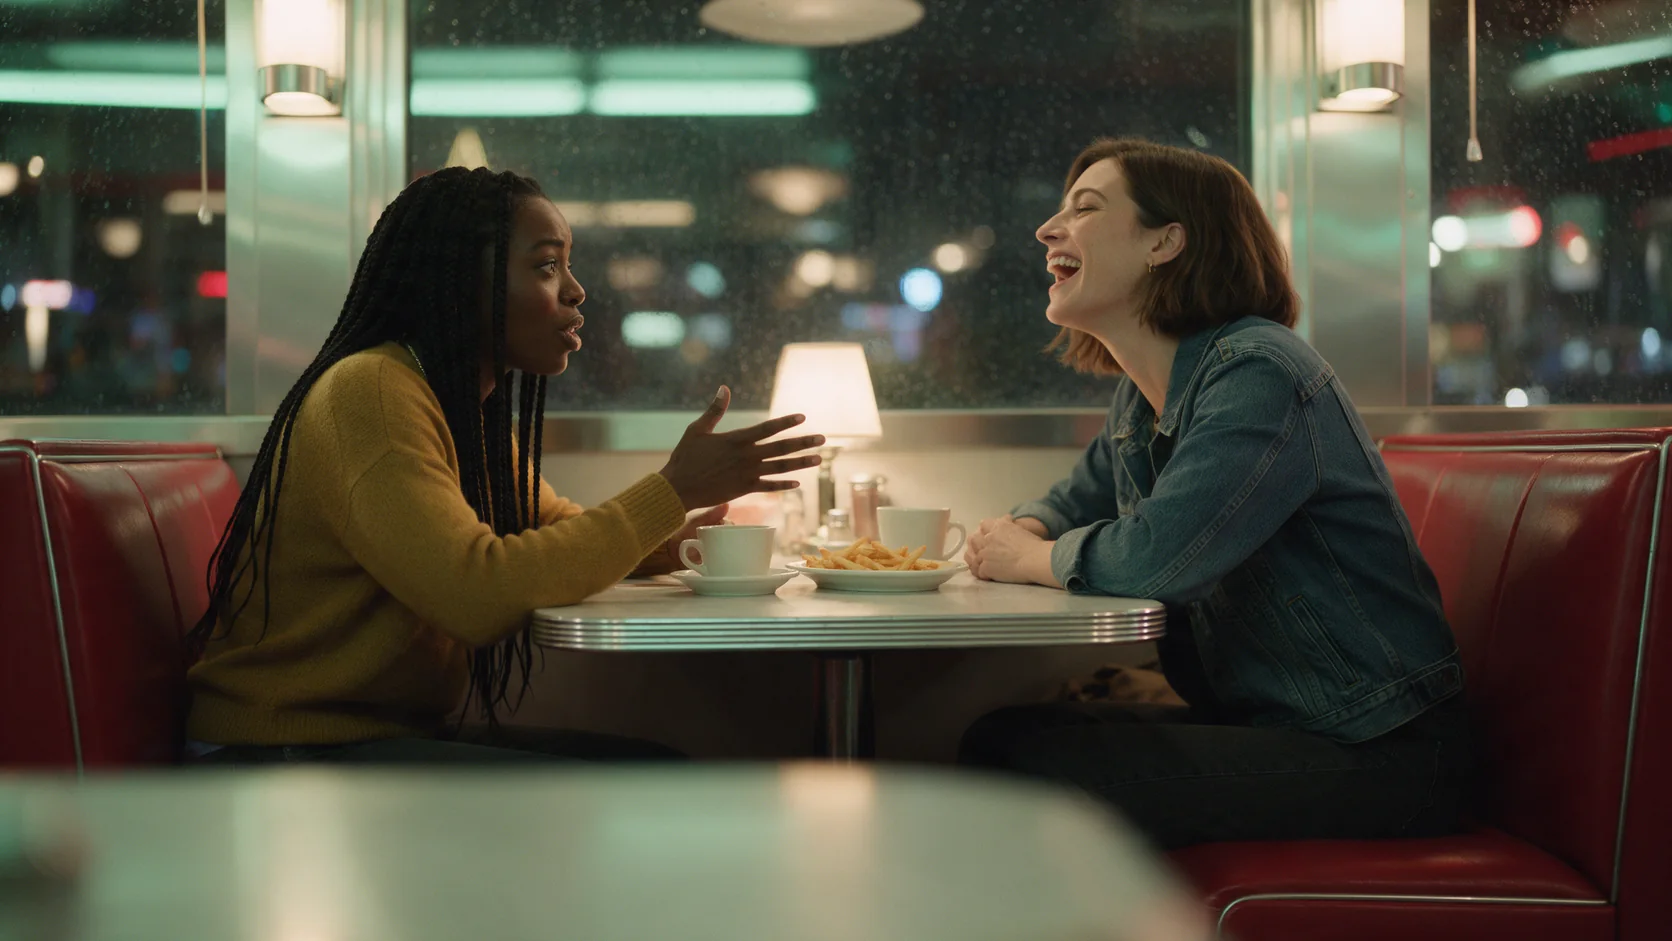
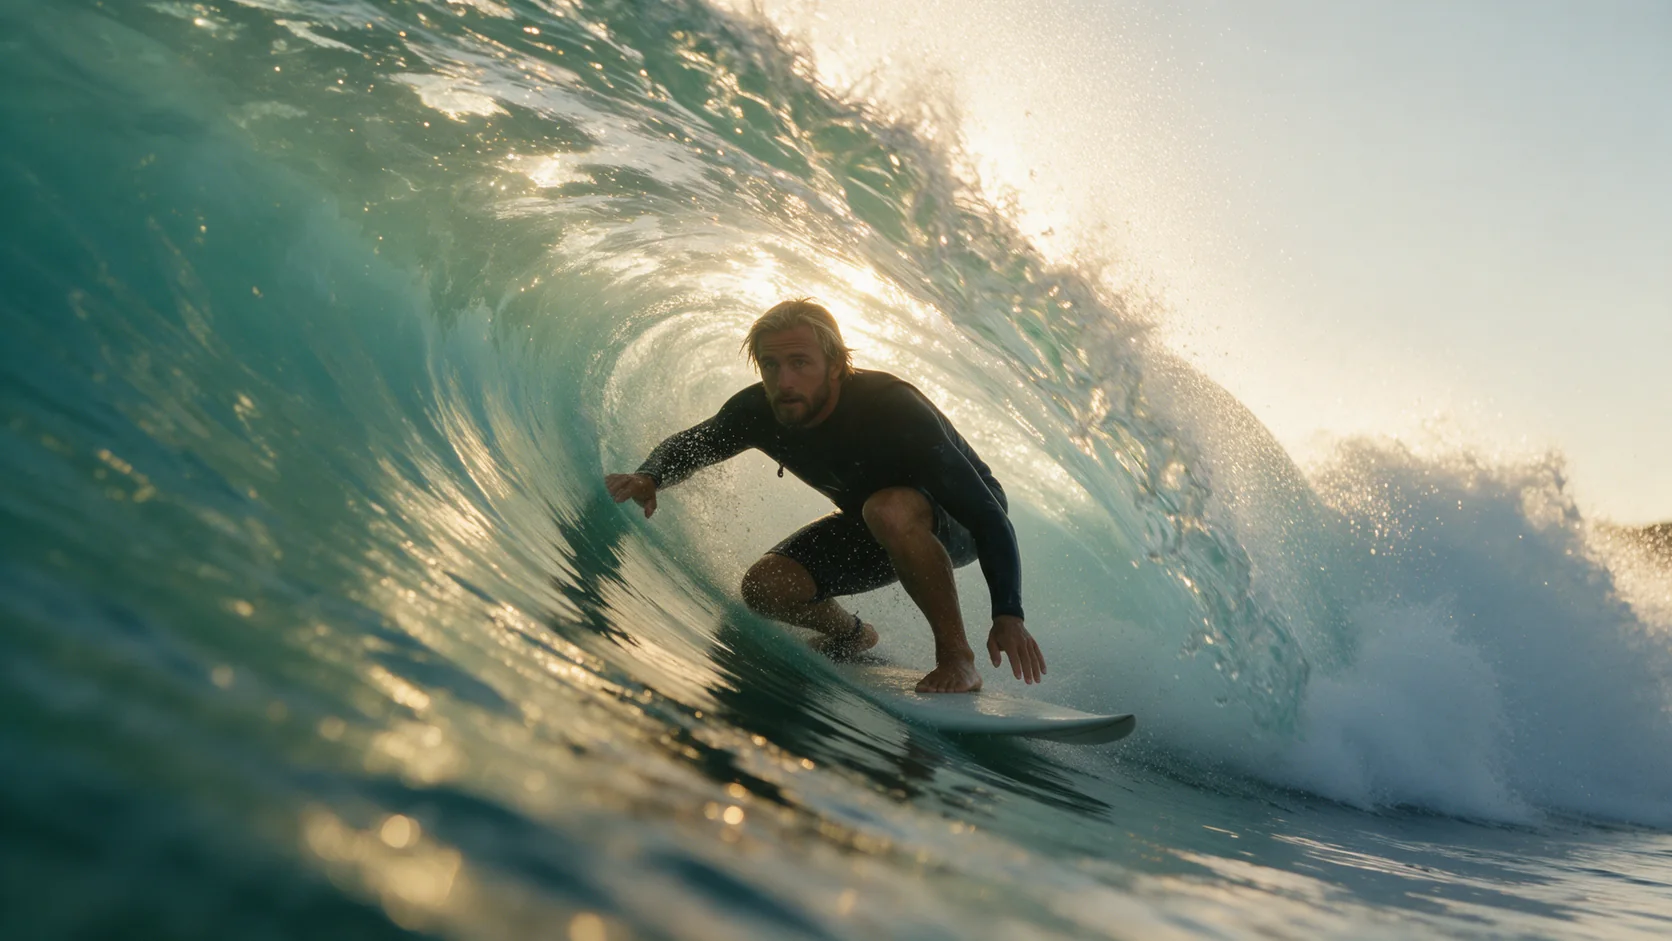
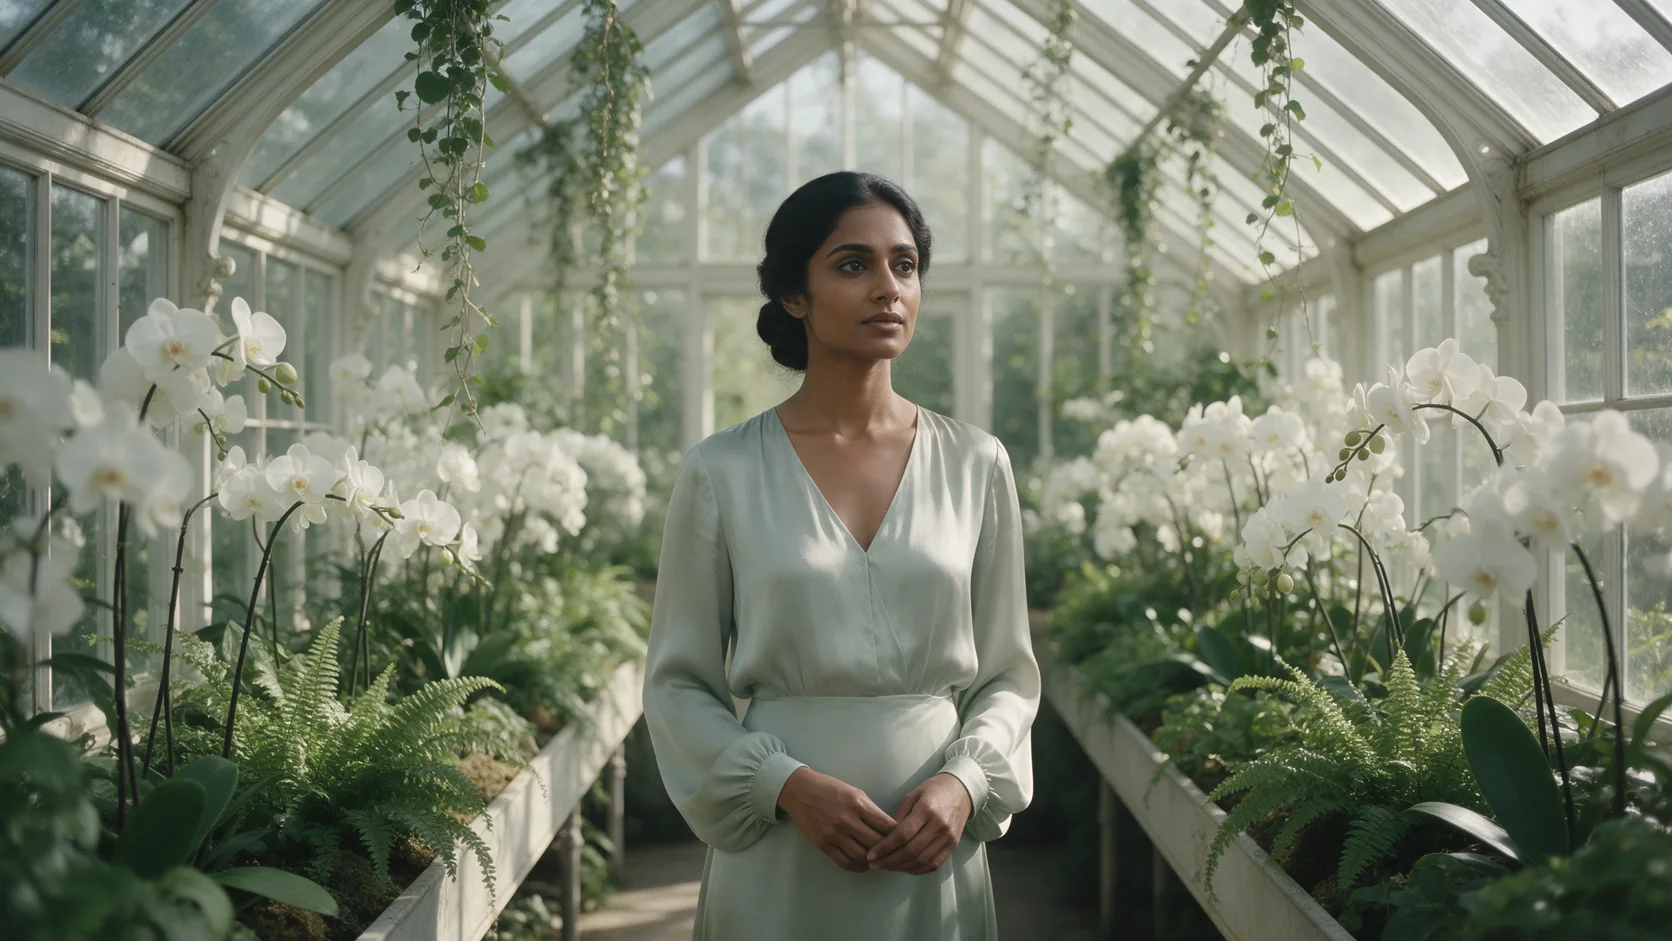
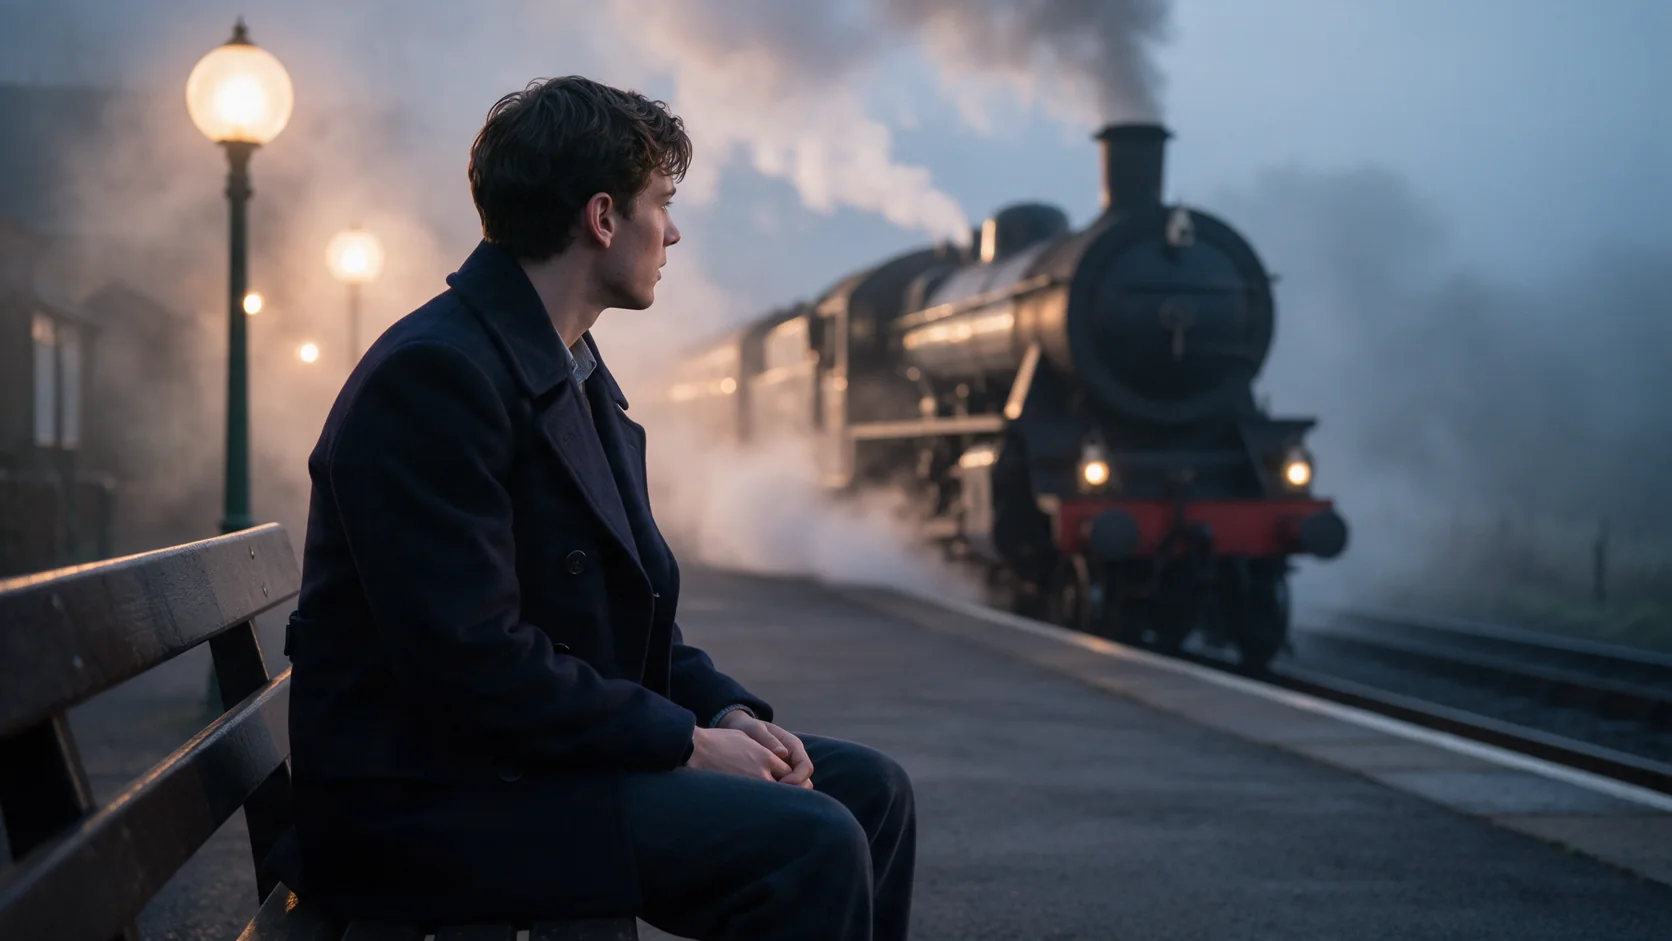
Kling 3.0 Text to video turns a written prompt into a clip with no image or driving video involved. Set a length from 3 to 15 whole seconds, a resolution of 720p, 1080p or 4K, and an aspect ratio of 16:9, 9:16 or 1:1. Turn generate_audio on to get dialogue, effects and ambience generated in the same pass, and choose shot_type to keep one continuous setup or let Kling cut its own multi-shot edit.
Choose a Kling 3.0 mode by starting material
| What you have at the start | Mode |
|---|---|
| a written scene or script | Kling 3.0 Text to video (you are here) |
| an opening frame, and optionally a closing one | Kling 3.0 Image to video |
| a character photo and a driving clip | Kling 3.0 Motion Control |
Key features & highlights
Dialogue and ambience in the same file
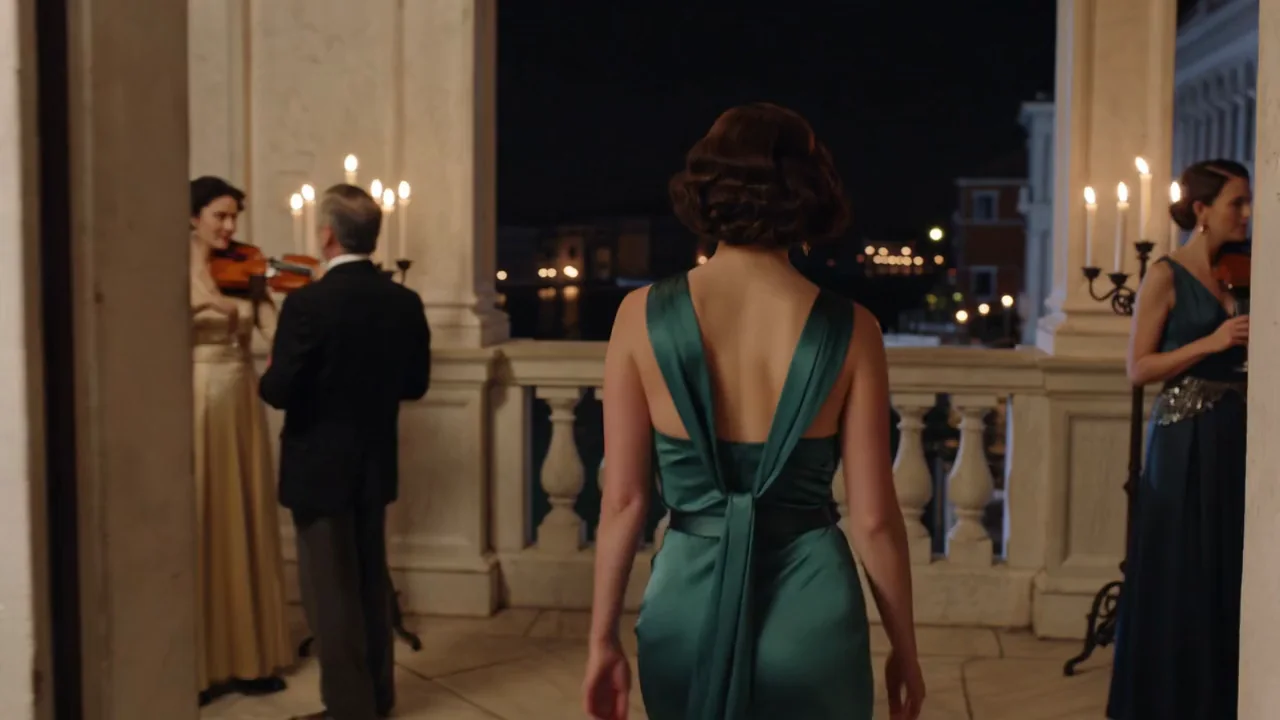
With generate_audio on, a spoken line written in quotes in the prompt comes back as audible dialogue, timed to the picture, alongside whatever ambient sound you describe. In our test the line "Don't wait up" came back spoken over a string quartet and the murmur of a gala, all from one paragraph.
Two ways to handle multiple shots
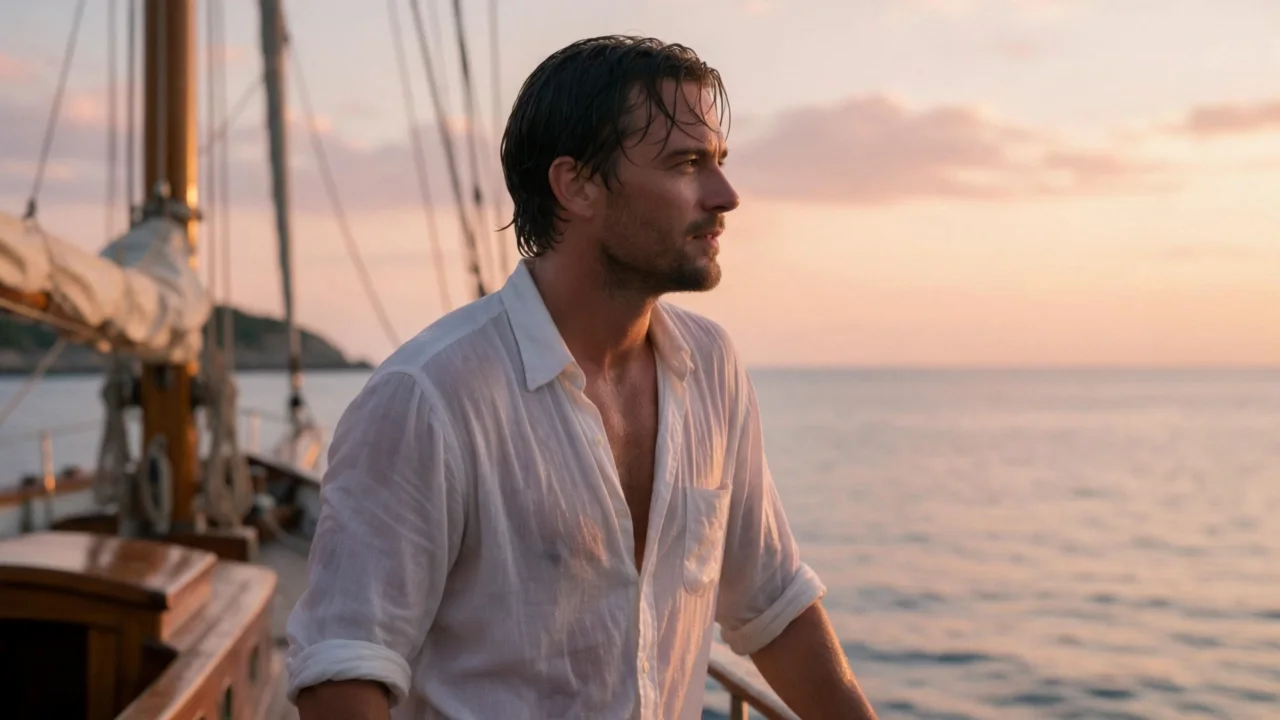
shot_type set to single keeps the camera on one setup for most of the run, though it can still cut on its own - in our tests two single-shot clips picked up an extra cut mid-run, once with the light changing across it. Adding "one continuous shot, no cuts" to the prompt held the shot together in our retest. Set shot_type to multi and Kling decides its own cuts instead.
720p, 1080p and 4K
All three resolutions and the audio toggle change the price. Draft the timing and framing at 720p, then run the take you like at 4K once it is worth the render.
Request parameters
| Parameter | Required | Description |
|---|---|---|
prompt | Yes | Describe the subject, the action, the camera and, with sound on, the dialogue and sound you want. at least 1 characters · at most 2500 characters |
negative_prompt | No | Things to keep out of the clip - objects, looks or motion you do not want - up to 2,500 characters. Optional; it does not change the price. at most 2500 characters |
aspect_ratio | No | 16:9, 9:16 or 1:1. Fixed for the whole clip - there is no source frame to follow instead. |
resolution | No | 720p, 1080p or 4K. Higher tiers cost more per second. |
generate_audio | No | Adds a generated soundtrack - dialogue in quotes, effects, ambience - to the same clip. Default: |
duration_seconds | No | Whole seconds, 3 to 15. Drives the price. |
shot_type | No | single keeps one setup for most of the run but can still cut on its own; multi lets Kling cut its own multi-shot edit. |
multi_prompt | No | The shot list for |
guidance_scale | No | How closely the clip follows the prompt, from 0 to 1 (default 0.5). Higher sticks to the wording more; lower leaves the model more freedom. |
Pricing
Billed per second of output. Resolution and the audio switch both change the rate.
| Resolution | Generate audio: No | Generate audio: Yes |
|---|---|---|
| $0.0672 / second | $0.1008 / second |
| $0.0896 / second | $0.1344 / second |
| $0.336 / second | $0.336 / second |
Use cases
Open a scene with real sound
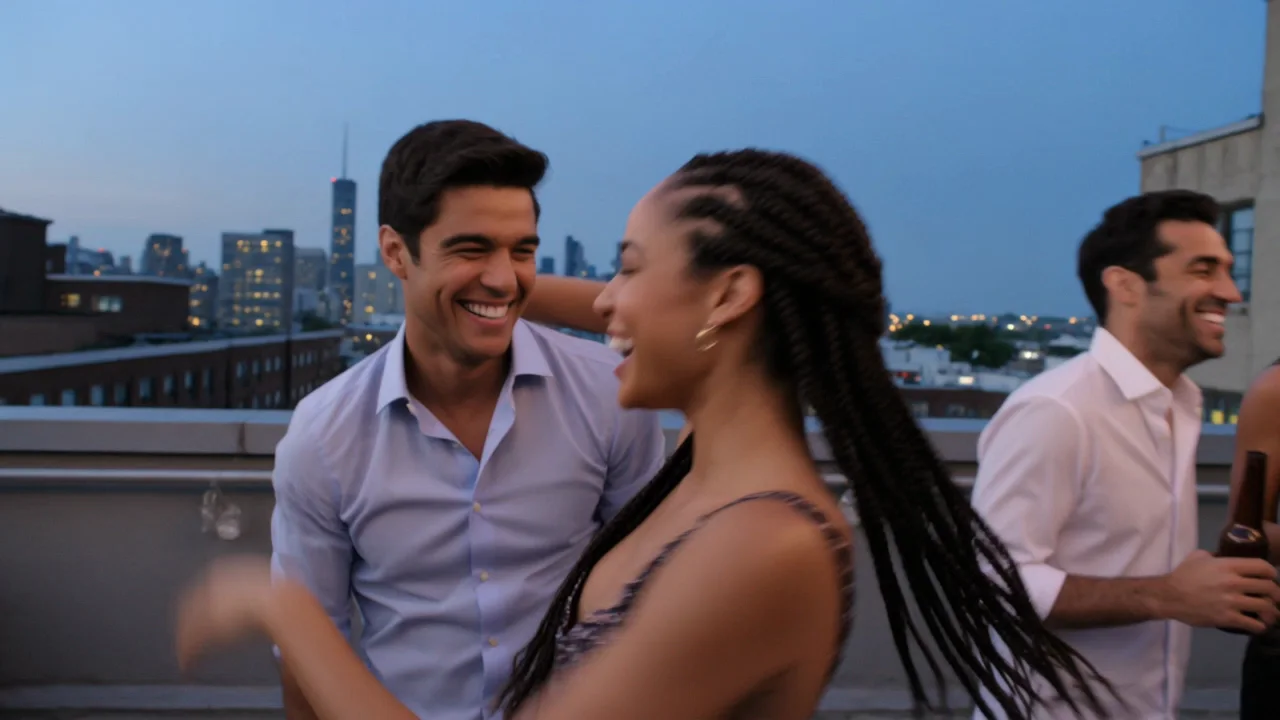
A toast, a confession, a goodbye - write the line and turn audio on, and the dialogue, the room tone and the picture arrive in one file. Our rooftop-party example ends on a whole group shouting one line together, timed against the clinking bottles and music underneath it.
Draft a look before committing to 4K
Text-to-video needs no source image, so it is the fastest way to test a lighting idea, a camera move or a piece of dialogue before spending a 4K render on it.
Hand off to image-to-video for continuity
Text-to-video decides wardrobe, face and framing fresh on every run. When a character has to look the same across several clips, generate the first shot here, then take its final frame into image-to-video as the opening frame of the next one.
Prompt guide & pro tips
Write it in the order it happens
Structure the prompt as subject and wardrobe, action, camera move, look, then sound. The palazzo-terrace-gown example follows that order: who she is and what she wears, what she does (walks, turns, speaks), the camera and light, then the ambient sound.
Give the whole group one line to land on
When several people are on screen, naming a single moment - one line, spoken together, at the very end of the brief - gives the model a clear beat to land the dialogue on instead of guessing when several voices should overlap.
Say "one continuous shot, no cuts" when it matters
shot_type: single is not a hard guarantee against cuts. If the take must hold one setup all the way through, add that instruction directly in the prompt; it held both the framing and the lighting steady in our retest of a shot that had cut and changed light on the first attempt.
API quick start
# Generate the idempotency key once; reuse it when retrying after a lost response.
export SPICY_IDEMPOTENCY_KEY="${SPICY_IDEMPOTENCY_KEY:-$(uuidgen)}"
curl -X POST https://api.spicyapi.ai/api/v1/jobs/createTask \
  -H "Authorization: Bearer $SPICY_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Idempotency-Key: $SPICY_IDEMPOTENCY_KEY" \
  -d '{
  "model": "kling/3.0/text-to-video",
  "input": {
    "prompt": "A slow aerial shot drifting over a misty pine forest at sunrise",
    "shot_type": "single",
    "resolution": "720p",
    "aspect_ratio": "16:9",
    "generate_audio": false,
    "duration_seconds": 5
  }
}'

# Copy data.taskId from the response into TASK_ID, then poll the status.
TASK_ID="TASK_ID_FROM_RESPONSE"
curl "https://api.spicyapi.ai/api/v1/jobs/recordInfo?taskId=$TASK_ID" \
  -H "Authorization: Bearer $SPICY_API_KEY"
See the API reference for authentication, the complete schema, polling, and error handling.