本文へスキップ

このレビューはまだ日本語版がないため、Englishの原文を表示しています。

フィルターあり — このモデルは、モデル自身の許容範囲を超える指示を明確に拒否します。実測済みの結果です。未計測のモデルには表示が付きません。

OmniHuman 2.0 Review: Talking Avatar From a Portrait and Audio

Pick OmniHuman 2.0 when you have a portrait and a recording and want the prompt to direct expression; expect about two minutes per short clip.

  • 軽め

  • 中程度

  • 強め

  • かなり強め

  • 最大

料金
—
所要時間の中央値
2.1 分
成功率
データ収集中

OmniHuman 2.0 is ByteDance's audio-driven avatar model, released on 15 October 2026. SpicyAPI serves it as one endpoint, omnihuman/2.0/talking-avatar. You send a portrait (image_url) and a recording of speech or singing (audio_url), and you get back a 720p video of that person performing the recording. The face, lips, head and upper body move with it. An optional prompt of up to 300 characters directs mood, gestures and where the eyes go. There is no duration, resolution or aspect-ratio field: the clip is as long as your audio, from 4 to 300 seconds.

The verdict

We ran four portraits on 25 October 2026, each with its own recording of 4.55 to 5.2 seconds. All four clips came back at 1280 x 720 and 24 fps with the audio track, after 110 to 133 seconds of processing. The lips followed the audio in every clip, the face stayed recognisably the same person, and most of the small gestures we asked for appeared. One did not: a lean toward the microphone never showed. A fifth portrait was declined by the publisher's content check before any video was made, and nothing was charged.

Pick it when the words are already recorded and you want a face to deliver them: a narrated intro, a testimonial, a character whose portrait is settled. Look elsewhere if you need the voice generated from text, a 1080p tier or a vertical format you can select.

How it scores. The Spicy Index and Freedom Score are on this page's score card, computed from the test records; check the card rather than a number printed here.

Try OmniHuman 2.0 →

Key facts

  • Inputs: one portrait and one recording, both required. Portrait: JPEG, PNG, WebP, BMP, TIFF, GIF, HEIC or HEIF, under 30 MB, 300 to 6000 px per side, width-to-height ratio 0.4 to 2.5. Audio: WAV or MP3, under 15 MB, 4 to 300 seconds.
  • Output: 720p. In our four runs the clip was 0.2 to 1 second longer than the audio and landed on a whole number of seconds (4.55 s of audio gave 5 s, 5.2 s gave 6 s).
  • Speed: 110 to 133 seconds from submit to finished file for clips of about five seconds. It is an asynchronous task, so you poll for the result or use a webhook. We have not timed longer audio.
  • Price: billed per second of the input audio, 4-second minimum and 300-second maximum. At the time of writing that is $0.1084 a second, about $0.54 for five seconds. The model page shows the live price.
  • Content limits: the publisher reviews every portrait; see "How far it goes". The page label is Filtered.

良かった点と足りなかった点

良かった点

  • Lips follow the line. In all four clips the lip movement tracked the recording, including a slow, low-register line at a vintage microphone.
  • The face stays the person. Comparing frames to the input portrait, the face was recognisably the same in all four clips.
  • Small, specific beats land. A smile and a small head tilt on the last word, a half smile with a raised eyebrow, a glance away in the final second and a quick laugh all arrived roughly where the prompt placed them.
  • The body moves, not just the mouth. The publisher describes head and upper-body movement following the audio, and the examples show it.
  • Phone photos go in as they are. WebP, HEIC and HEIF portraits are accepted, so there is no conversion step.
  • Long recordings are supported. Up to 300 seconds of audio in one request, which we did not push to the limit.

足りなかった点

  • It needs a recording. There is no text-to-speech path here. If you only have a script, you need a voice file first, or a model that generates the voice with the picture.
  • Body movement is less reliable than expression. "A lean toward the mic" did not visibly happen while the laugh and eyebrows beside it did. That is one run, so check a body movement before you build on it.
  • Slow for a short clip. About two minutes of processing for a clip of about five seconds.
  • Per-second price is higher than Kling Avatar 2.0. At the time of writing Kling Avatar 2.0 is $0.0512 a second at 720p, against $0.1084 here. Kling also has a 1080p tier; OmniHuman 2.0 is 720p only.
  • Every portrait goes through a content check. A declined portrait is not billed, but you only find out after submitting.
  • The output length is not exactly the audio length. Inspect the returned file if you are cutting to a precise timeline.

What the clips look like

The gallery holds four published examples from the OmniHuman 2.0 model page, all clothed and safe for work. Three of them use the same portraits and recordings as the Kling Avatar 2.0 page, trimmed to about five seconds, so the two pages can be compared side by side.

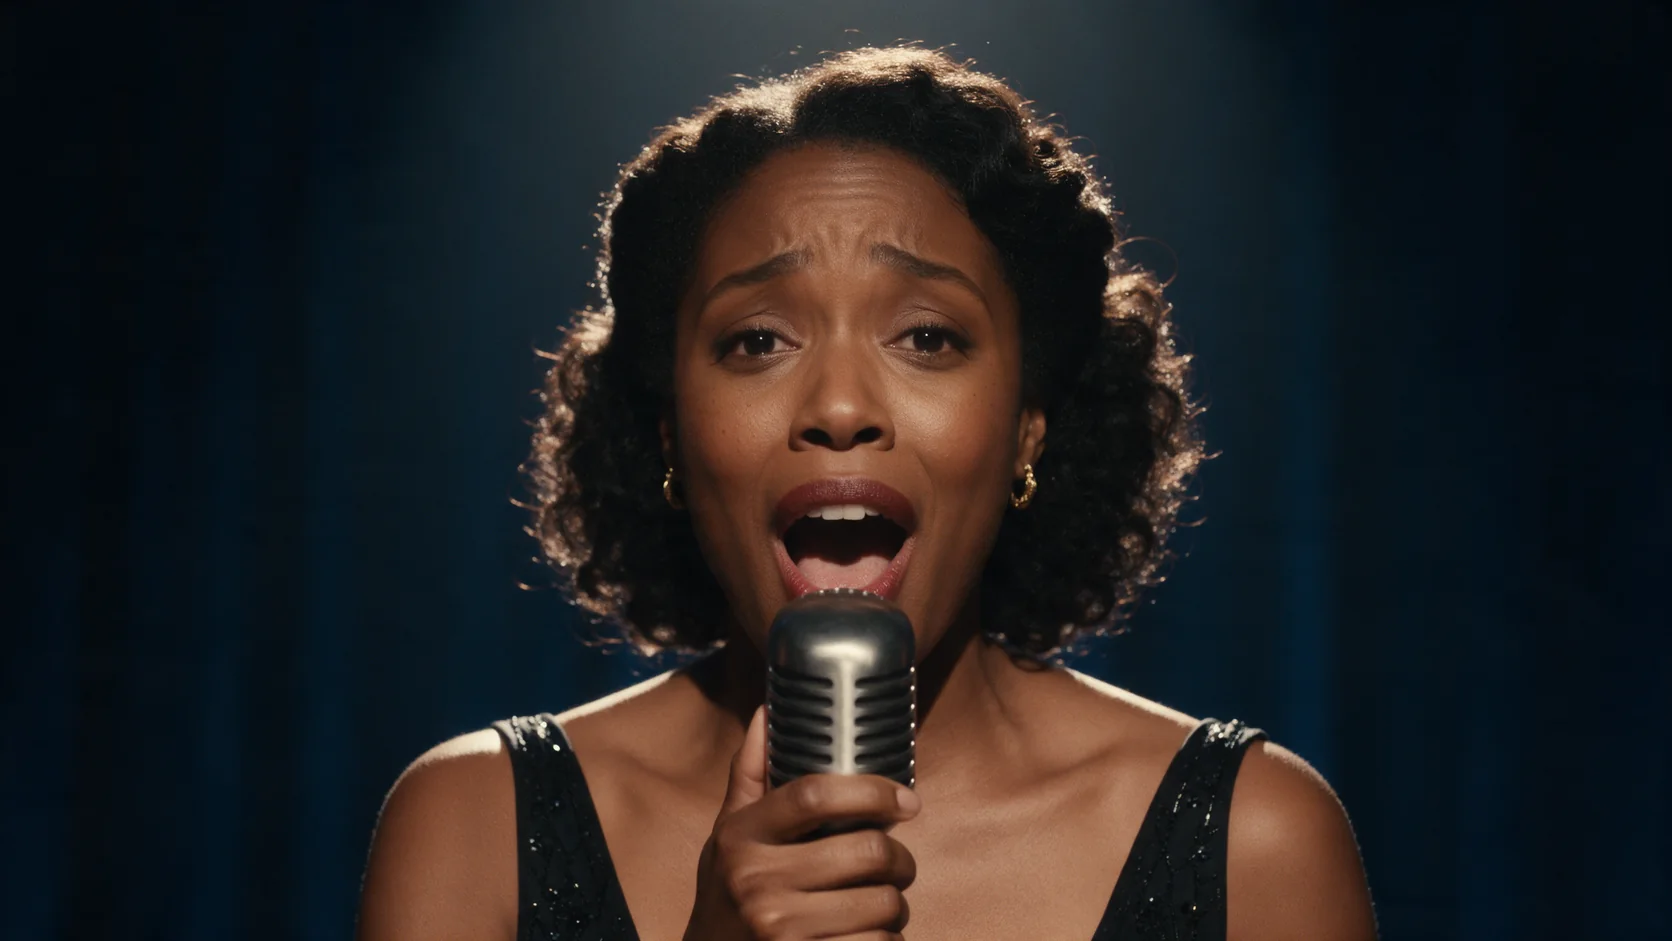
A slow line at a vintage microphone. A woman in a black velvet gown, 5.2 seconds of slow audio. The lips track the audio, a small head tilt and a smile land at the end as the prompt asked, and her hand stays on the microphone. The clip runs 6.0 seconds.

A low, teasing line behind a bar. A man behind a dim bar, a 5.0-second spoken line. His eyes close and reopen, the half smile and raised eyebrow follow the line, and the bottles behind him stay stable.

A glance away in the last second. A woman on a sunny stone terrace, 4.55 seconds of audio. Her head turns toward the sea in the final second and her hair moves slightly.

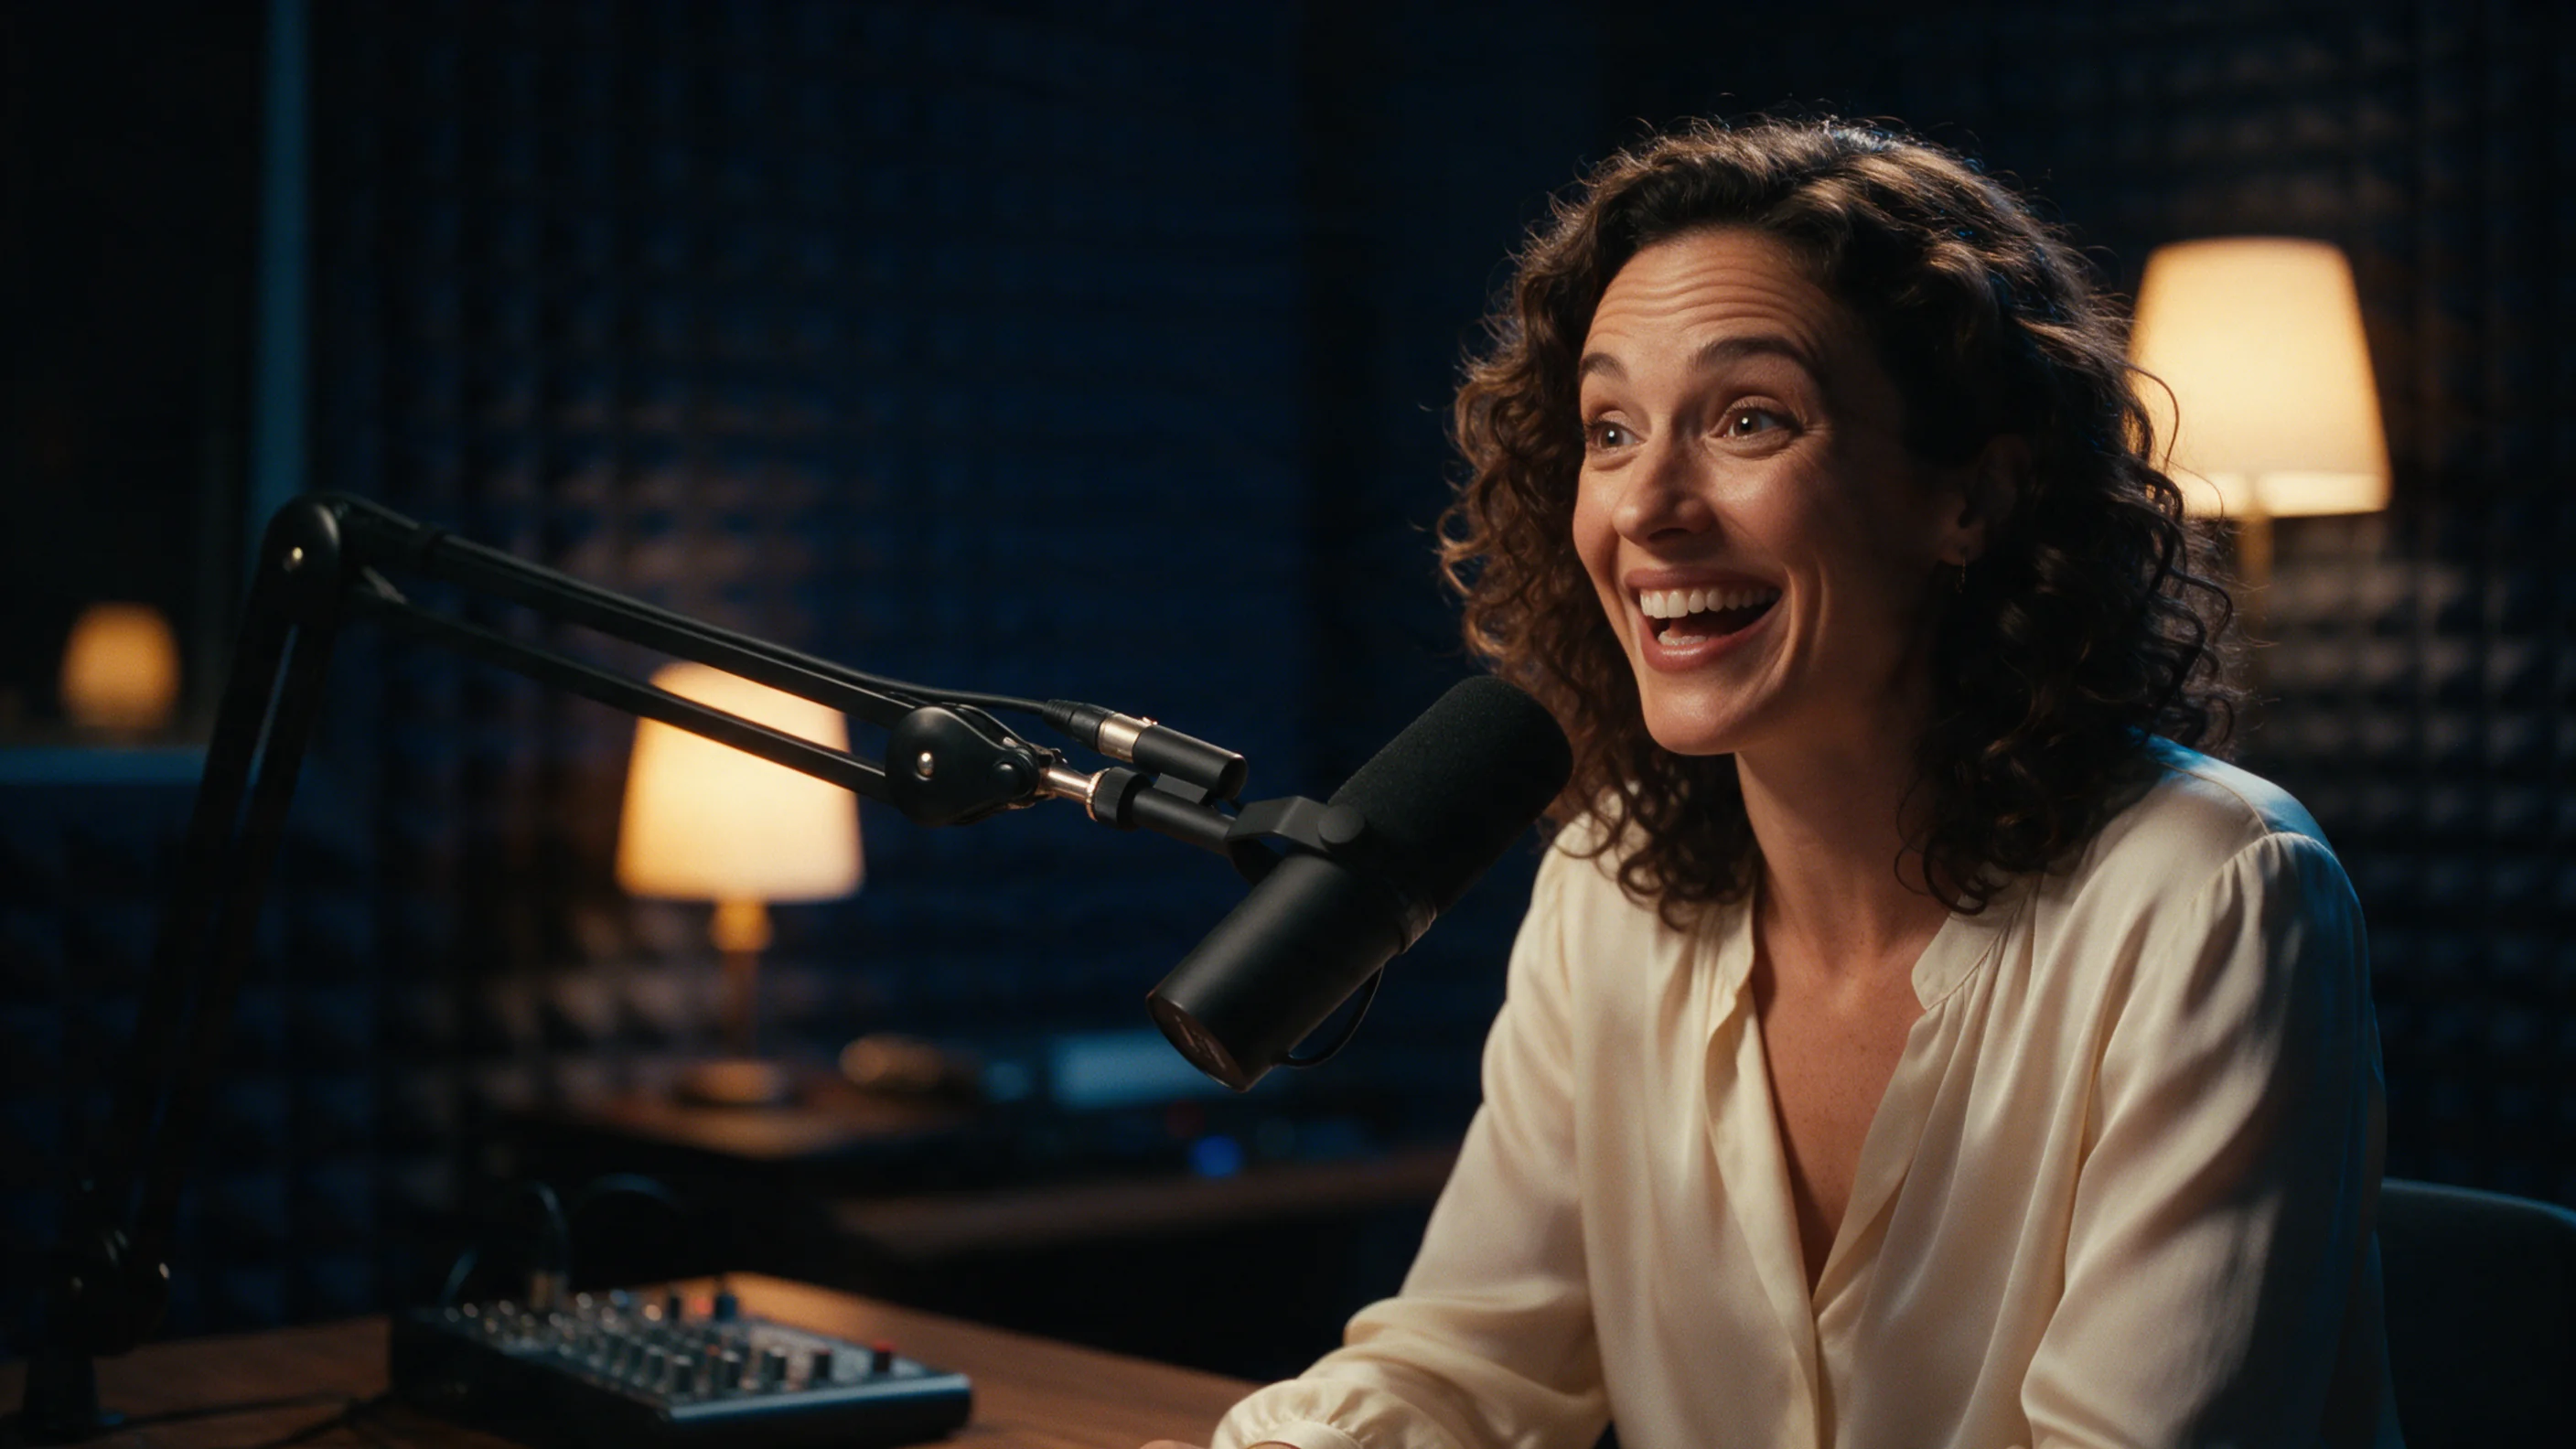
A late-night show opening. A woman in a podcast studio, an upbeat 4.8-second intro. Wide expressions, lively eyebrows and a laugh follow the prompt, but she does not visibly lean toward the microphone.
Prompts that worked

The prompt directs the performance. The portrait and the recording already decide who is on screen and what is said.

  • Tie a beat to a moment in the line. "Slow and languid, a lazy smile on the last word and a small tilt of the head, eyes on the lens." Both the smile and the tilt arrived at the end.
  • Pair a posture with an expression. "Leaning on the bar, he speaks low and teasing, a slow half smile and a raised eyebrow, warm amber light." The clip kept a consistent low register.
  • Give a gesture a moment to happen. "Relaxed on a sunny terrace, she murmurs the line with a knowing smile and glances away at the end." The head turn landed in the final second.
  • Keep to a few beats. Each of our prompts asked for a mood, one or two facial beats and sometimes a posture. That is enough to shape a five-second clip.
  • Trim the audio first. The clip runs as long as the file and billing follows the audio length, so cut the recording to the performance you want.

The publisher lists Chinese, English, Japanese, Korean, Spanish (Mexican) and Indonesian as prompt languages. Our prompts were in English, and we did not test camera-movement instructions.

How far it goes

SpicyAPI adds no filter of its own, but the publisher reviews every portrait before a clip is made. On 25 October 2026 we sent one portrait at the Moderate level of our five-level ladder (Mild, Moderate, Strong, Very strong, Maximum; test prompts not published). It was declined before any video was generated, in under half a minute, and nothing was charged. That is a refusal, not a toned-down result.

Not tested yet: Mild, Strong, Very strong and Maximum on this endpoint, so the score card has too few content levels for a full Freedom reading. We have no data on the other levels, so try your own portrait before you plan a project around it.

This endpoint makes a specific face say or sing specific words, which carries real personal risk if that face and voice are not yours to use. Send only a portrait and a recording that are your own, or that the person shown and heard has explicitly agreed to. Adults only, and never a real, identifiable person without consent.

Alternatives

OmniHuman 2.0 はどこまで描けるか

段階・タスク別の Freedom 点数
段階トーキングアバター
軽めテストの中で最も軽いプロンプト未テスト
中程度フィルターのあるモデルが断り始める地点
1 回中 0 回生成0.0 / 20 点
強め中間の段階。順位を付ける前に必ずテストします未テスト
かなり強め多くのモデルが手加減し始める地点未テスト
最大尺度の最上段。A 区分と B 区分の 2 つに分けて採点未テスト
タスクのスコア残りが通った場合の範囲:0.0~80.02026年10月25日 にテスト

2026年10月25日~2026年10月25日 にテスト

このサイトは職場でも安全に閲覧できる内容に保っています。結果は文章で伝え、表示する画像にはモザイクをかけ、テスト用プロンプトは決して公開しません。未成年に見える人物、実在の人物の容姿、同意のない状況は決してテストしません。

テスト記録をすべて見る →規制なしランキングを見る →

自分のプロンプトで、どこまで出るか試す

OmniHuman 2.0 の Spicy Index の内訳

公開リーダーボード 品質の 45%
未テスト

追跡している公開リーダーボードに、完全に一致するエントリーはまだありません。 仕組み

ブラインド出力テスト 品質の 35%
未テスト

当社のブラインド出力テストはまだ実施していません。 仕組み

アリーナの品質 品質の 20%
未テスト

ブラインド票が 100 票以上、95% 区間が 200 Elo 未満になると加わります。 仕組み

機能 重み 10.5%
未テスト

まだ採点していません。 仕組み

Freedom Score 重み 30%
未テスト

自由度が未測定、または証拠が不十分です。Index は元の品質・機能スコアを維持し、暫定表示で順位に含めます。証拠の欠如を 0 点とは扱いません。 仕組み

テストレポートをすべて見る →

SpicyAPI で OmniHuman 2.0 にできること

エンドポイント別の機能
機能トーキングアバター
ネイティブ音声なし
シード指定なし
ネガティブプロンプトなし
すべてのパラメーターとコード例を見る →

実際にかかる時間

過去 30 日の実際のジョブで、リクエストから完成までを計測しています。所要時間には当社自身のテスト実行も含みます。

所要時間の中央値
2.1 分
90 パーセンタイル
3.3 分
動画 1 秒あたりの待ち時間
データ収集中
成功率
データ収集中

完了したジョブが 10 件以上そろうと所要時間を表示します。成功率はお客様のジョブだけで数え、30 日分のトラフィックがそろうまで全モデルで非表示にしています。

OmniHuman 2.0 の代わりに検討できるモデル

あなたの意見は?

このレビューは役に立ちましたか?

投票するにはログインしてください。

コメント

コメントは自動チェックと当社チームによる確認を経ています。スパム、不適切な内容、個人攻撃、実在の人物の名前を同意なく挙げる投稿は削除します。コメントを報告いただければ、1 営業日以内に確認します。

このモデルを試しましたか?うまくいった方法を共有してください。スパムを防ぐため、コメントには無料アカウントが必要です。

OmniHuman 2.0 のよくある質問

OmniHuman 2.0 を自分で試す

プレイグラウンドで全パラメーターを設定し、実行前に正確な料金を確認できます。

ほかのレビュー

ランキングを見る →
  • A white cliff-top hotel lit gold at night above a dark sea, a glass rooftop pavilion, a lantern-lit pool terrace and a mahogany motor launch speeding away under the moon

    P-Video 2 Pro

    Pick P-Video 2 Pro for fast takes with built-in sound; for Maximum-level requests delivered as written, try another video model.

    Spicy Index
    63.7
    Freedom Score
    58.7

    2026年10月17日 にテスト

    レビューを読む
  • 深い青いベルベットの背景の前、1つのスポットライトの下でヴィンテージマイクに向かって歌う女性のクローズアップ

    Kling Avatar 2.0

    Kling Avatar 2.0 は 1 枚の肖像写真と 1 本の音声ファイルから、720p か 1080p で最長 5 分の発話・歌唱クリップを作ります。

    Spicy Index
    —

    2026年9月28日 にテスト

    レビューを読む
  • 夕暮れのガラスの温室で、大きな熱帯の葉に囲まれて立つエメラルドのシルクドレスの女性

    Wan 3.0

    テキスト・静止画・参照から、安く規制なしの音声付き 30 秒を撮るなら Wan 3.0。台本の終わりで場面を止めたいときは避けましょう。

    Spicy Index
    87.7
    Freedom Score
    96.0

    2026年9月24日 にテスト

    レビューを読む