Introduction
The style weights act on the image edit, with <Picture 1> identifying the source and later tokens identifying supporting images.
| Field | Value |
|---|---|
| Input | Image |
| Output | Image |
| Tasks | Text-to-image generation and image-to-image editing; still images |
| Model family | MiniMax H3-Image open weights with LoRA attachments |
| LoRA attachments | Up to 3 direct .safetensors file URLs |
| LoRA scale | 0–4 per file; default 1 |
| Prompt length | Required; up to 5,000 characters |
| Resolution menu | 1k, 1.5k, 2k, 3k, 4k; default 1k |
| Canvas choices | 15 aspect ratios; text generation defaults to 1:1 |
| Edit inputs | 1–9 pictures; editable source followed by up to 8 references |
| Reference notation | <Picture 1>, <Picture 2> and later numbers in upload order |
| Output encoding | jpeg by default; png and webp also available |
| Comparison control | Optional seed; helps compare one change without promising identical output |
| Tested output dimensions | 1.5k at 9:16: 1152 x 2048; 4k at 16:9: 5472 x 3072 |
Key features & highlights
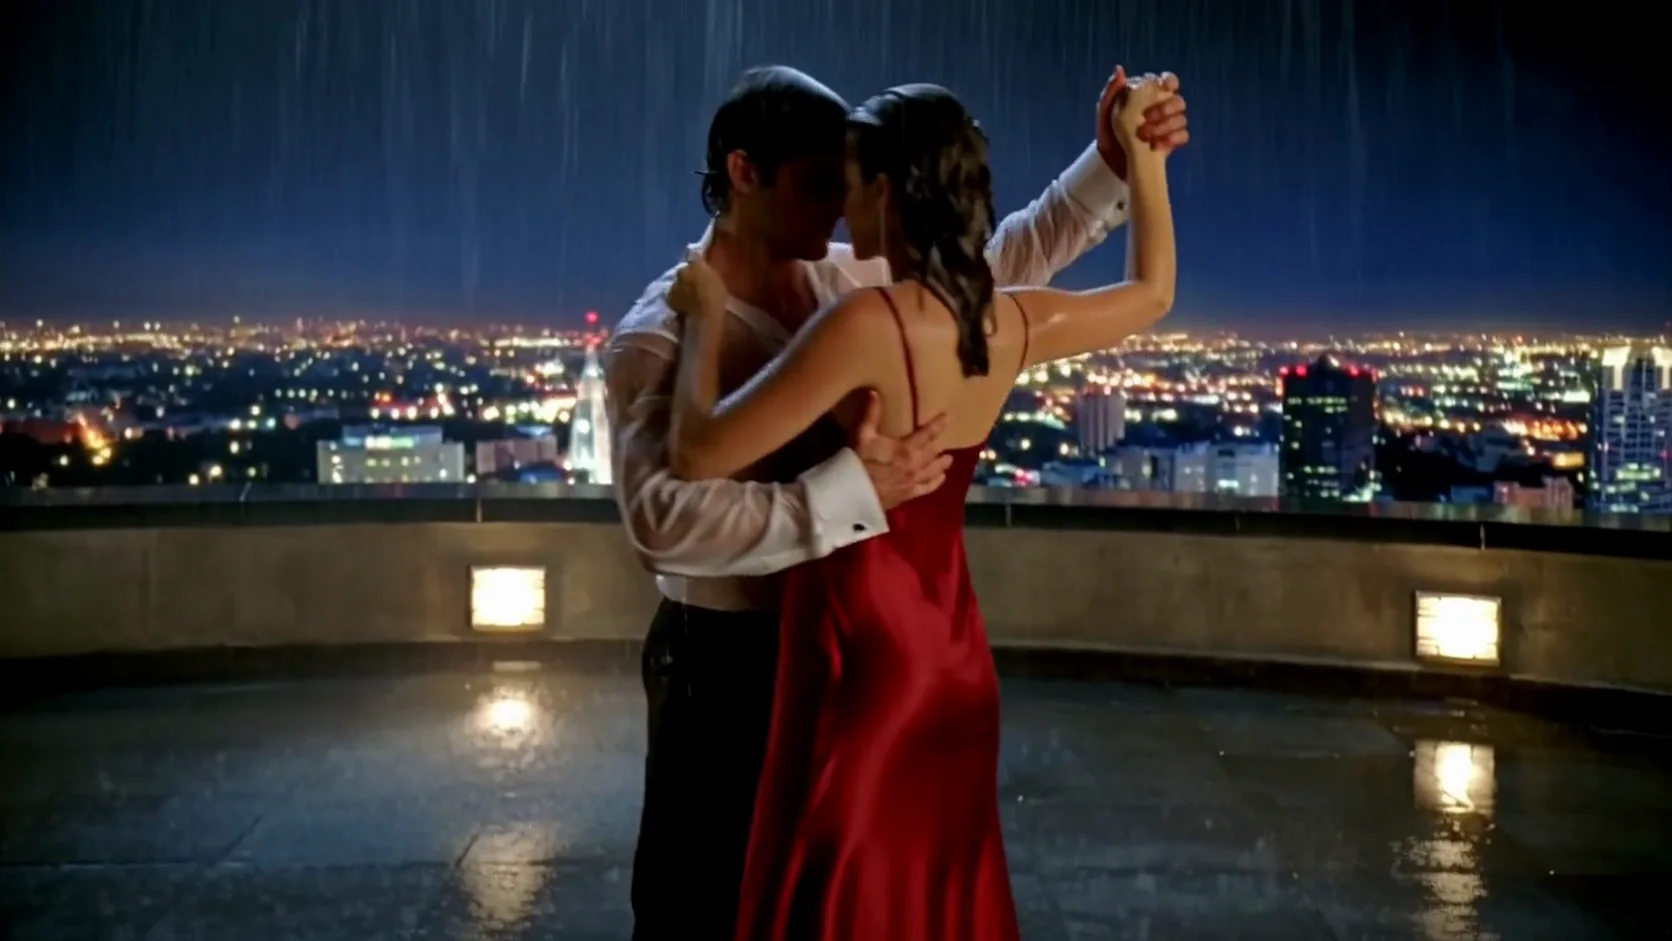
Neon light through a camcorder treatment
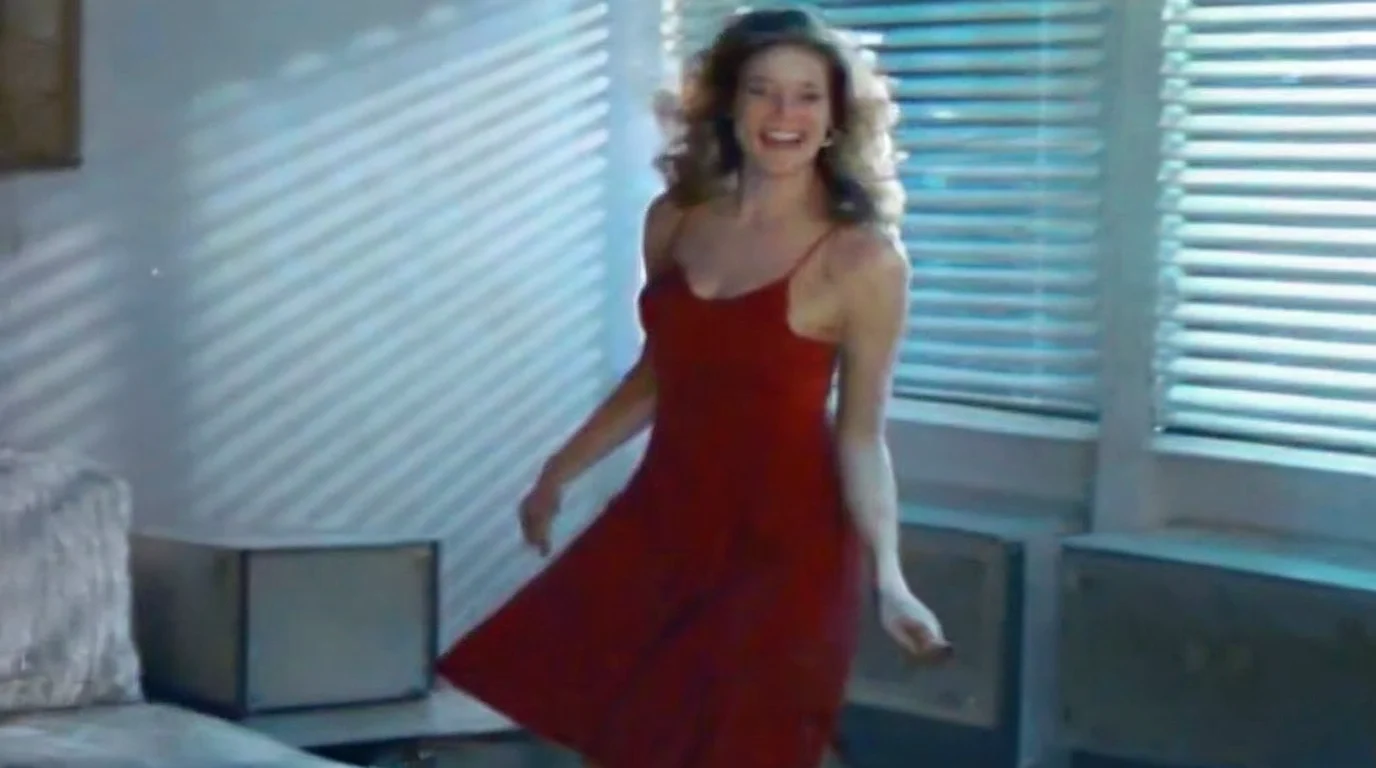
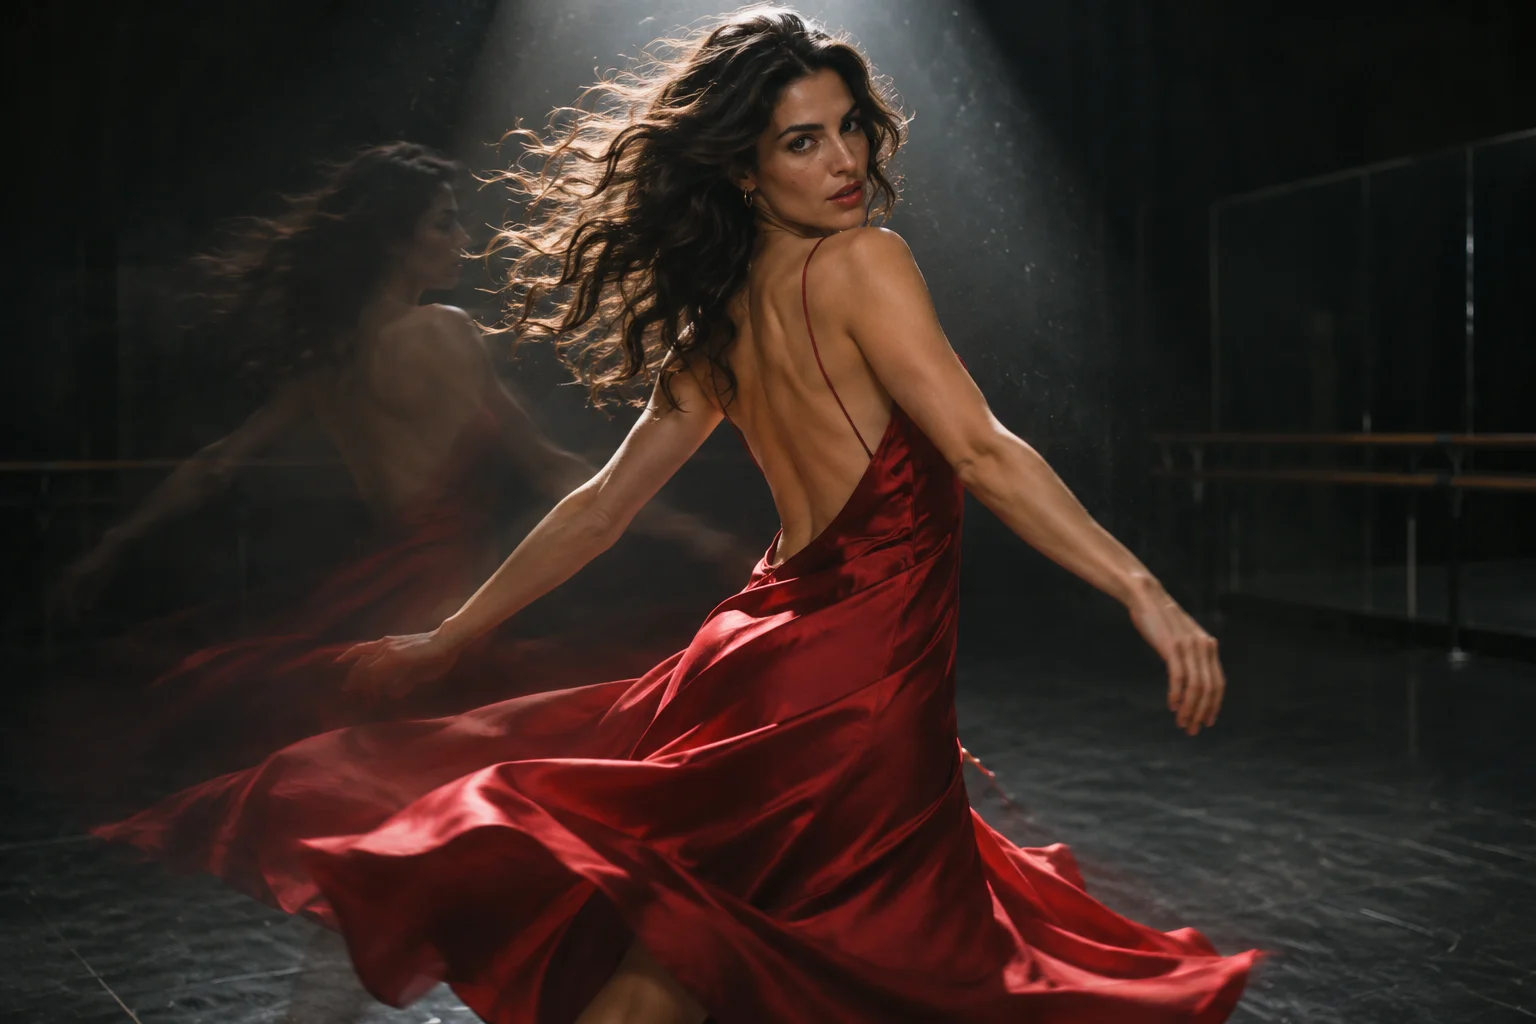
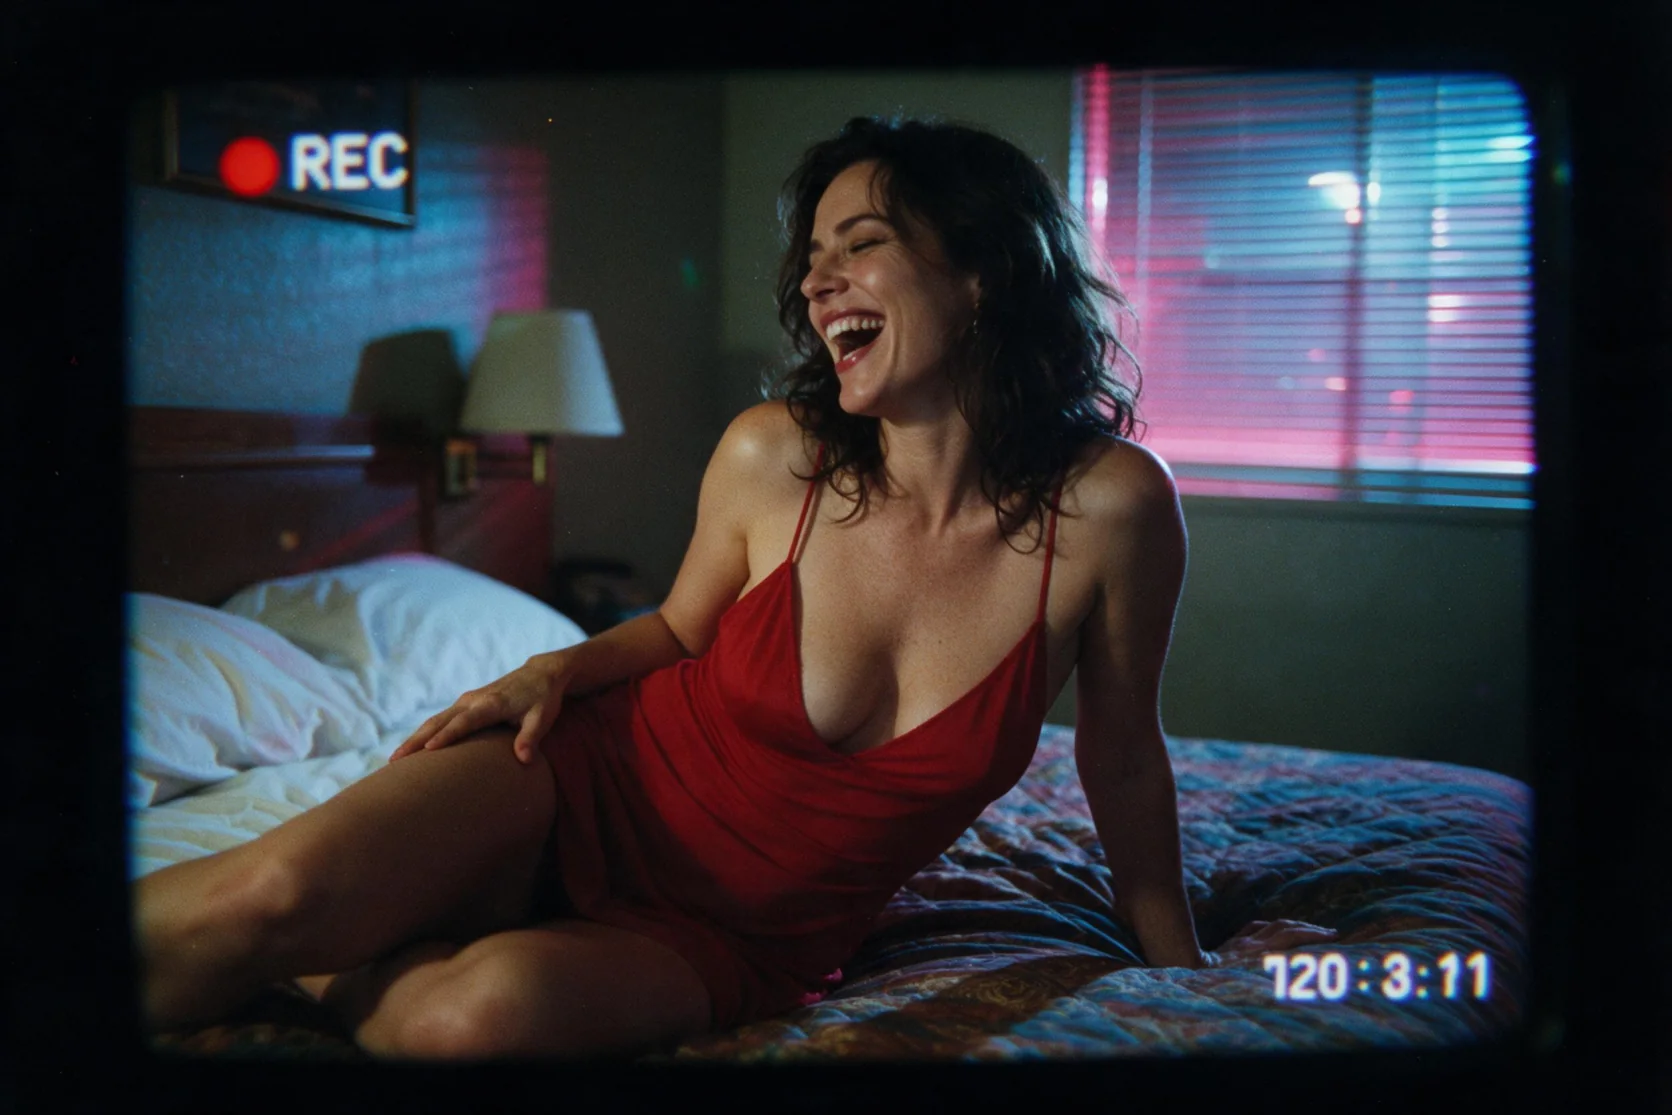
The new 1k, 16:9 sample shows a woman in a red slip dress dancing in a motel room. With vh5tape and scale 1, the VHS LoRA gave the whole frame a soft 1990s home-video look.
The tape look can bring its own lettering
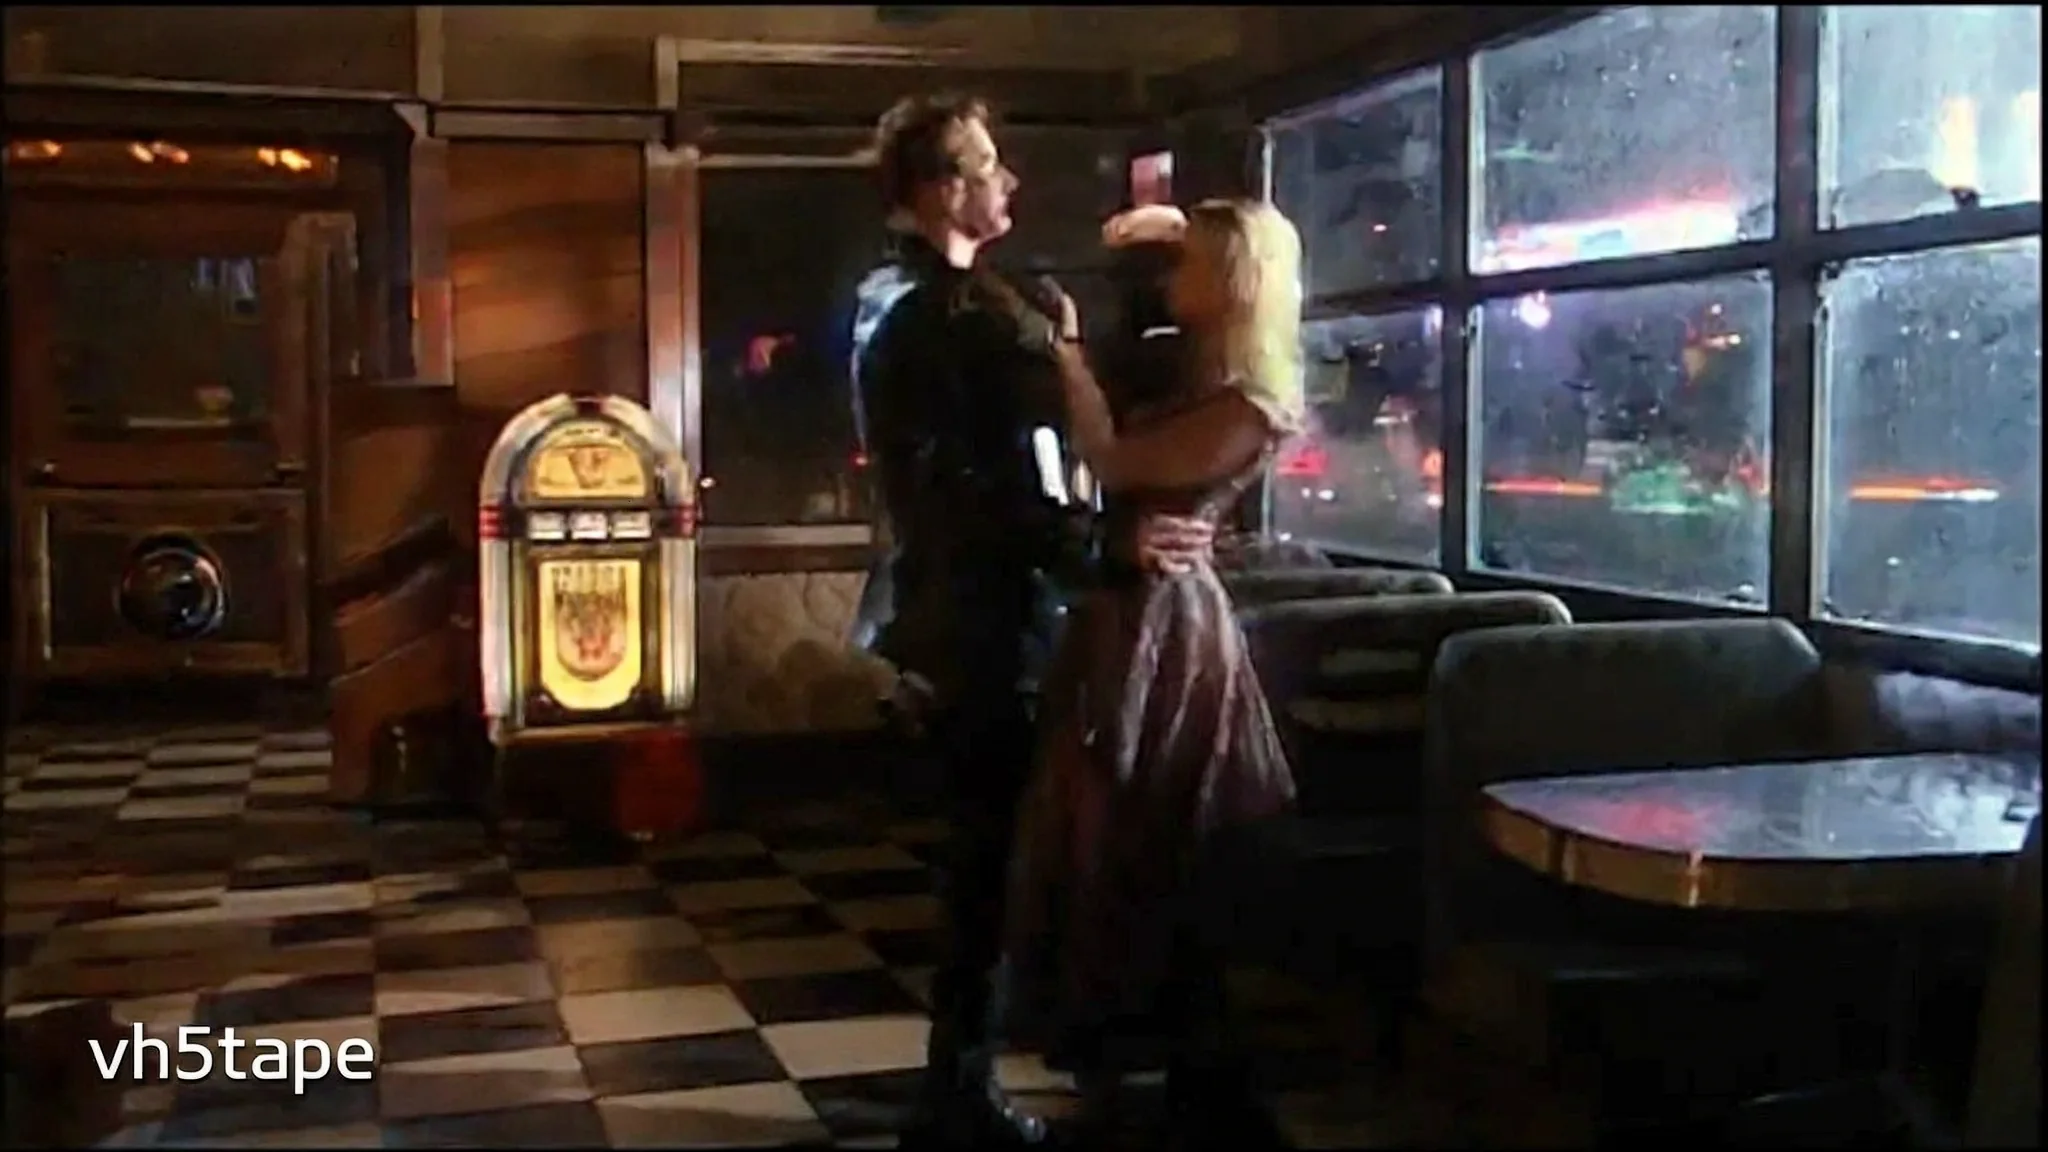
Our diner dance has recording grain and vh5tape lettering at lower left. That visible artifact is a reason to inspect text as well as the intended style before selecting an output.
A racing cabinet in a soft recording frame
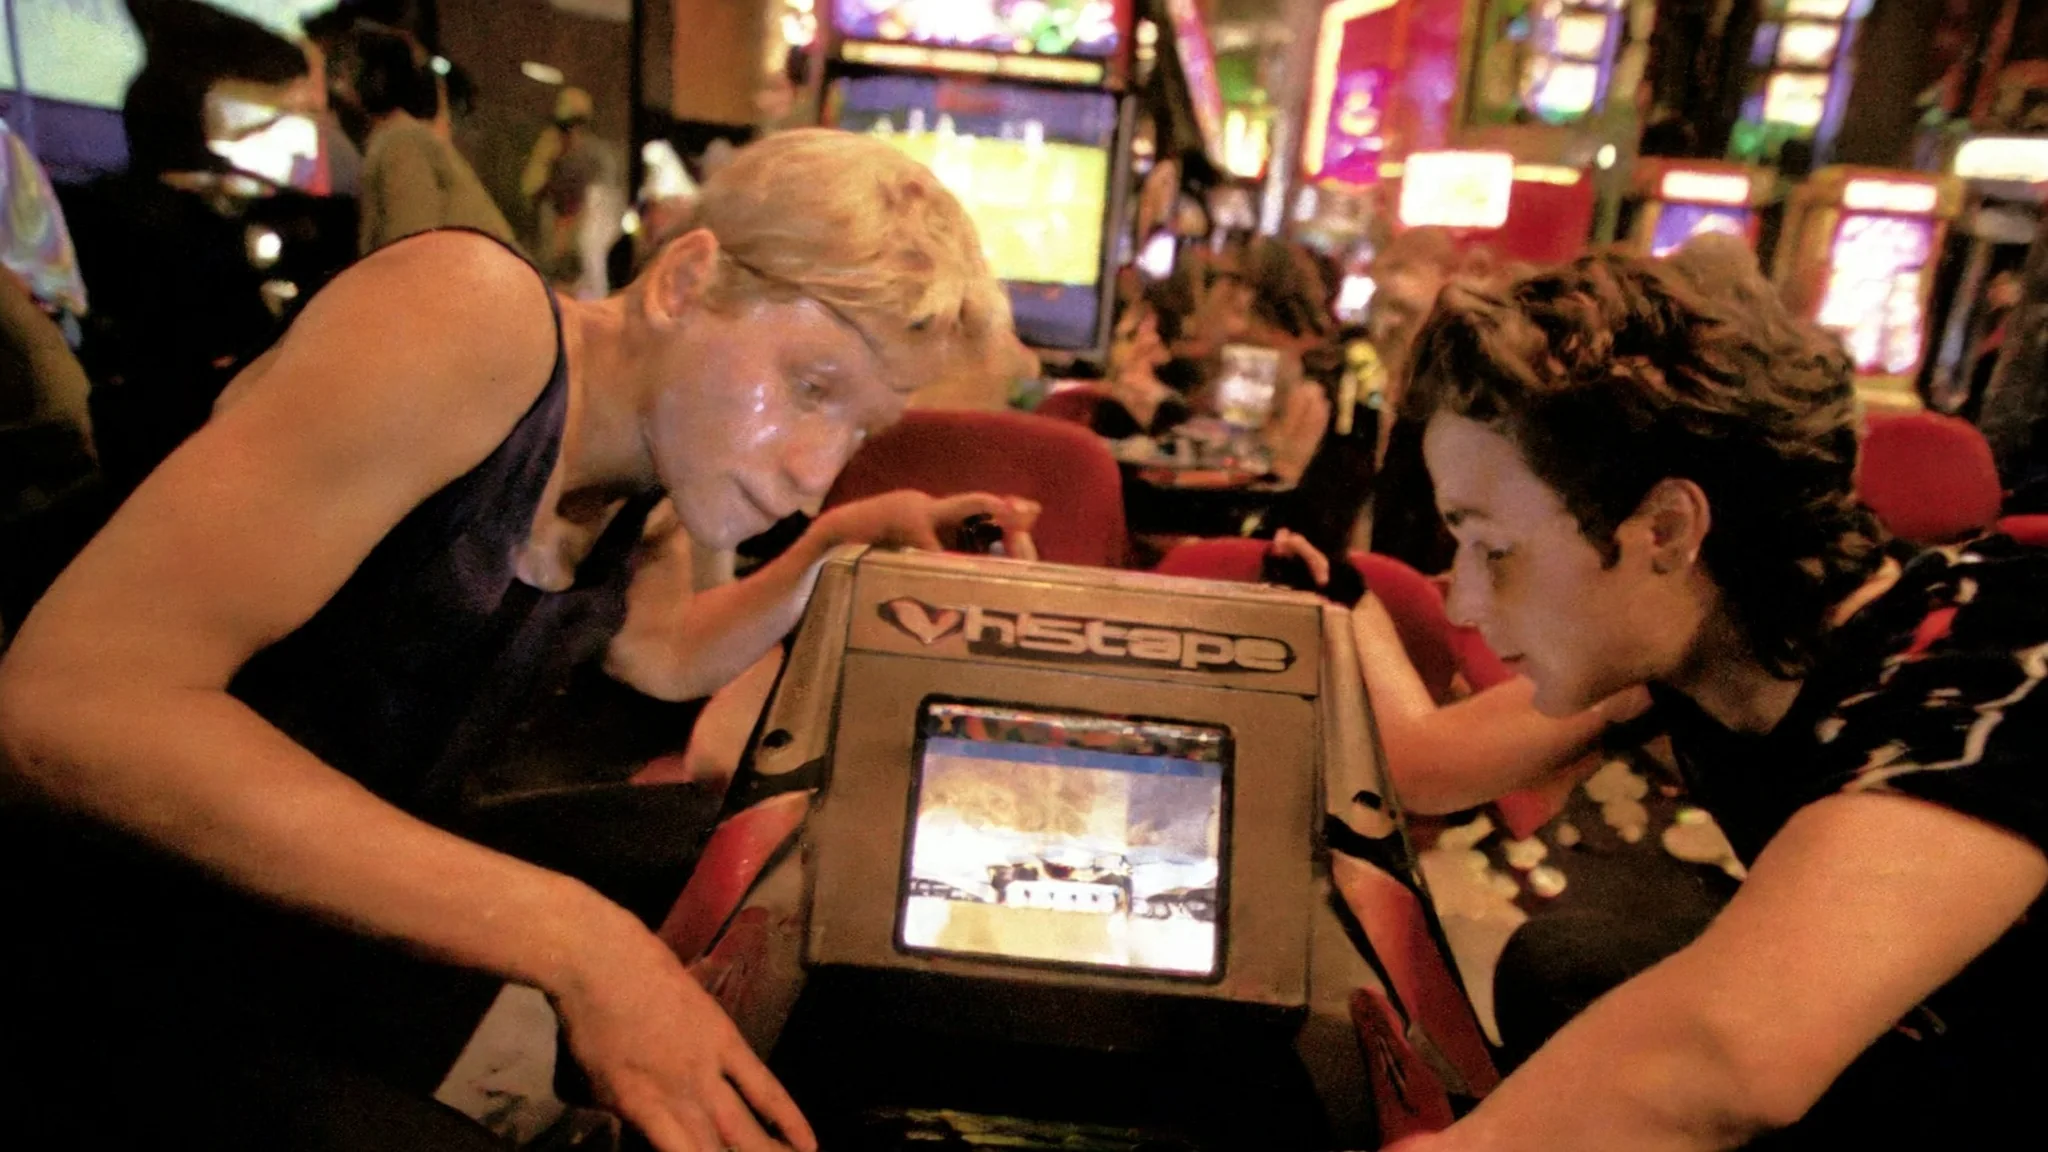
The arcade example applies the VHS treatment to two players amid neon lighting. It gives a second scene for judging how the adapter changes the appearance of people and surroundings.
A different drawing language for the harbor
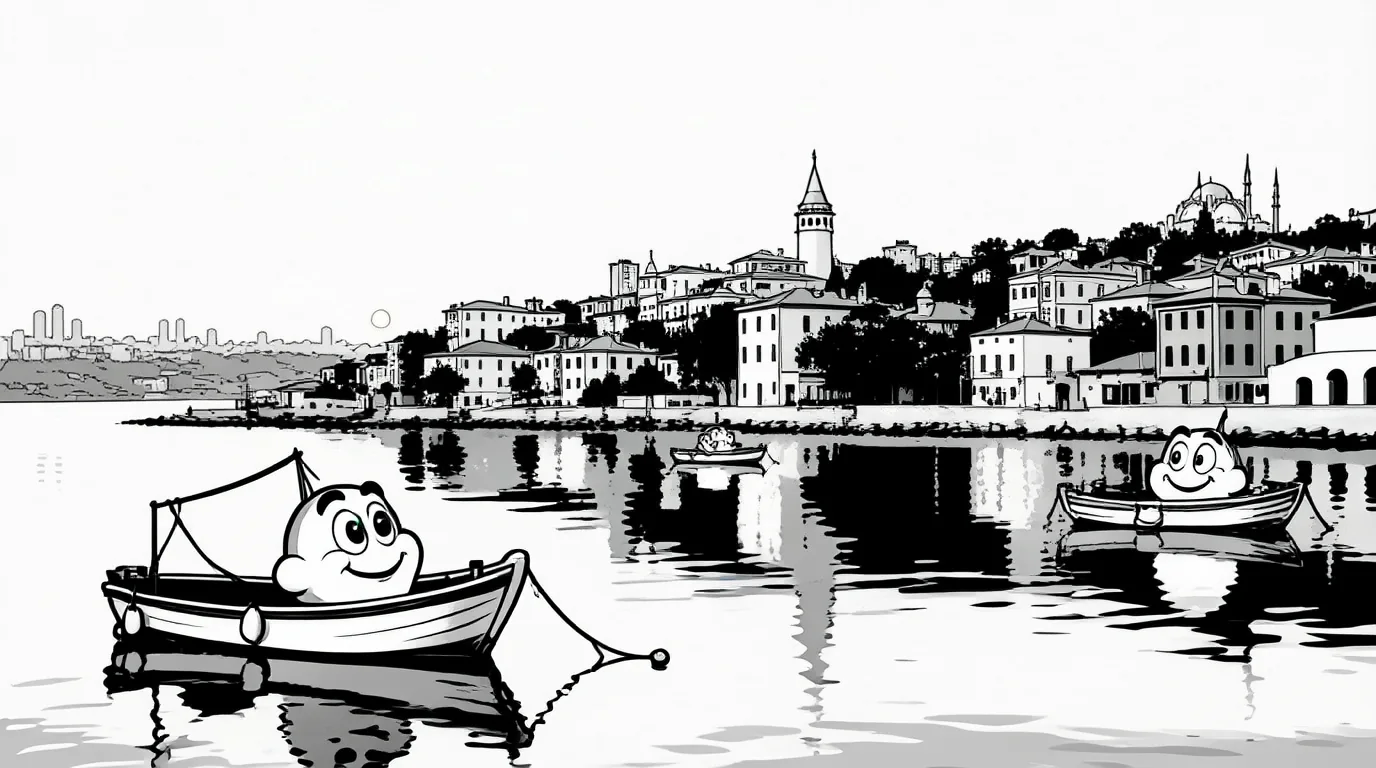
The Studio1939 style edit redrew the harbor in black and white with rubber-hose cartoon boats. The skyline arrangement remained recognizable in this sample.
Request parameters
| Parameter | Required | Description |
|---|---|---|
prompt | Yes | Write a required edit instruction of at most 5,000 characters, starting with the LoRA trigger and using for inputs. There is no preset prompt or text surcharge. at least 1 characters · at most 5000 characters |
image_urls | Yes | Include 1–9 picture URLs, starting with the required editable source; later inputs are references and each adds a small fee beyond the first-image edit rate. at least 1 items · at most 9 items |
aspect_ratio | No | Edit shapes are 1:1, 1:2, 2:1, 1:3, 3:1, 2:3, 3:2, 3:4, 4:3, 4:5, 5:4, 9:16, 16:9, 9:21, 21:9; leaving this unset follows the first picture. |
resolution | No | For a styled edit, choose 1k (default), 1.5k, 2k, 3k or 4k; the output tier becomes more expensive as size increases. |
loras | No | Provide at most three {path, scale} weight entries for the edit, using downloadable .safetensors URLs rather than repository pages. Scale runs from 0 to 4 and defaults to 1. Default: |
output_format | No | An edited result defaults to jpeg; png or webp may be requested for the same tier charge. |
seed | No | Optionally retain the random source when comparing edit treatments. No fixed default or numeric range is stated; it costs nothing extra and does not ensure identical results. |
Pricing
Styled edits have the open-weight size-tier rate plus a fixed per-image LoRA increment, unchanged for zero, one or three files. Every input after the first adds a fee; load errors and other failures are uncharged.
| Specification | Price |
|---|---|
| $0.042 / image |
| $0.06 / image |
| $0.078 / image |
| $0.15 / image |
| $0.222 / image |
Use cases
Neon motel scene studies
The red-dress motel example uses the VHS LoRA at scale 1 to turn a nighttime dance into a soft camcorder-style still. Use its whole-frame treatment as a reference for a tape-era mood board.
Restyle an existing photograph
Our 1930s cartoon LoRA changed a photograph into rubber-hose cartoon imagery while retaining the pose. The harbor example shows a related edit that preserves the skyline arrangement.
Compare an adapter before scaling up
Keep the seed and scene description steady while switching a LoRA on and off. Our VHS comparison changed the framing as well as the texture, so evaluate both before choosing a larger resolution tier.
Revisit a portrait setting
Single-picture wardrobe and setting edits retained the face in our tests. Add a LoRA treatment as a separate comparison so you can judge its effect on the person and surroundings.
Combine source and scene references
Two-picture composition succeeded in our tests. Put the editable source before the scene reference and name each picture in the instruction when planning a styled composite.
Prompt guide & pro tips
Choose generation or editing
Start from a written scene for generation, or supply the picture to revise before any supporting references. Editing accepts up to nine input pictures.
Attach a downloadable LoRA
Point path at the .safetensors file itself, using a Hugging Face /resolve/main/ link when appropriate. Start with scale 1; each file accepts 0–4 and the request can contain up to three files.
Describe the scene and treatment
Put the selected LoRA trigger ahead of a detailed English description of the wardrobe, action, light and surroundings. For an edit, map the source to <Picture 1> and assign later references their own numbers.
Compare and inspect the frame
Choose the ratio, resolution and format, then compare LoRA-on and LoRA-off requests with a fixed seed. Check style, composition and stray lettering; the seed does not promise an identical result.
Restyle a source picture with LoRA weights
Use this MiniMax H3-Image Open Weights LoRA endpoint when the starting point is a photograph or another existing picture. The request combines an editable source, optional supporting references, an instruction and up to three weight files. You can ask for a scene revision while applying a tested treatment such as the 1930s cartoon adapter.
The upload order matters: <Picture 1> is the picture being edited. Subsequent inputs are references that can supply a person, object or setting. Assign each one a role in the prompt so the requested changes and the details to retain are clear. For pictures of people, use photos you have the right to use, adults only, and no impersonation.
Editing parameters
| Parameter | Accepted values and role |
|---|---|
image_urls | One to nine pictures, starting with the source and followed by up to eight references |
prompt | Required instruction, up to 5,000 characters; name inputs with <Picture N> |
loras | Up to three {path, scale} entries, with a direct .safetensors URL for each file |
loras[].scale | Per-file value from 0 to 4; default 1 |
aspect_ratio | 1:1, 1:2, 2:1, 1:3, 3:1, 2:3, 3:2, 3:4, 4:3, 4:5, 5:4, 9:16, 16:9, 9:21 or 21:9; omission follows the source picture |
resolution | 1k, 1.5k, 2k, 3k or 4k; starts at 1k |
output_format | jpeg unless png or webp is selected |
seed | Optional random-source control for comparing an edit with one change |
The ratio setting and resolution tier serve different purposes. Leaving the ratio unset follows the source picture, while the tier sets the requested image size and price. For scale context, our open-weight 4k, 16:9 output measured 5472 x 3072 pixels; the tier label does not specify a universal width.
Build the instruction around source roles
Start with the adapter trigger, then identify what should be redrawn and what should survive the edit. A harbor study can read: "Studio1939 style, redraw <Picture 1> as a black-and-white rubber-hose cartoon harbor, with smiling boats and rounded outlines; retain the skyline arrangement." Supply the corresponding file in loras rather than relying on the phrase alone.
Adding a supporting picture
For a scene change, name both the source and the reference: "Use the woman in her forties from <Picture 1> in the lounge from <Picture 2>, wearing a navy dress beside the warm lamp; preserve her recognizable face." A VHS trigger can precede that instruction when the matching weight file is attached. This is a proposed brief, rather than a claim that the exact scene has been tested.
Keep requested changes separate from preservation goals:
- Specify which picture supplies the person or object.
- Describe the replacement clothing, surroundings and lighting.
- Identify the face, pose or layout that should remain recognizable.
- Review those details against the sources once the edit returns.
Evidence from our edits
The tested H3 video-model cartoon LoRA worked on this image checkpoint. A photograph took on a 1930s rubber-hose cartoon appearance while retaining its pose. In the harbor example, the skyline arrangement remained while the harbor and boats became a black-and-white cartoon.
Separate H3-Image editing tests retained a face through wardrobe and setting changes, and a two-picture composition placed a subject into another scene. Those results support trying reference edits; they do not prove that an attached adapter preserves every identity or layout. The VHS on/off comparison also changed composition, which is why a fixed seed is a comparison aid rather than a guarantee of an identical result.
Files, artifacts and troubleshooting
A Hugging Face /resolve/main/ URL should end at the .safetensors weight itself. Each entry has its own scale, with 1 as the starting value. Evaluate one file before judging a mixture, and keep the prompt, source order and seed steady while adjusting a scale.
Our broken-link request returned Failed to load LoRA, delivering no picture and no charge. Check that the URL downloads the intended file, then retry with the repaired link. A task failure does not silently substitute an untreated output. Also inspect for training-set lettering: the VHS diner generation carried vh5tape into a corner, so carried-over words are worth checking in styled edits too.
Charges and choosing another endpoint
A completed edit uses its resolution-tier rate plus the fixed LoRA increment. Additional references beyond the initial source add a fee. Attaching zero, one or three LoRAs leaves the increment unchanged, and choosing png or webp instead of jpeg has no pricing effect. The model page lists the current price; failed requests incur no charge.
Use Open Weights for an edit without adapter files while retaining seed control and the five tiers. If the brief needs ten to sixteen input pictures, MiniMax H3-Image accepts up to sixteen; its ratio behavior and three-tier menu differ, and it has no seed. Select text-to-image in this family when you have a written scene but no source. The older H3 Image LoRA uses the video model to create single frames and should be evaluated separately.
Content-test outcomes also have limits: our requests returned images without refusals, yet every Very strong edit in the standard test came back toned down. An image being delivered does not establish that it followed every instruction.
API quick start
# Generate the idempotency key once; reuse it when retrying after a lost response.
export SPICY_IDEMPOTENCY_KEY="${SPICY_IDEMPOTENCY_KEY:-$(uuidgen)}"
curl -X POST https://api.spicyapi.ai/api/v1/jobs/createTask \
  -H "Authorization: Bearer $SPICY_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Idempotency-Key: $SPICY_IDEMPOTENCY_KEY" \
  -d '{
  "model": "minimax/h3-image-open-lora/edit",
  "input": {
    "image_urls": [
      "https://example.com/reference.png"
    ],
    "output_format": "jpeg",
    "prompt": "A ceramic teapot on a linen cloth, soft window light, muted palette",
    "resolution": "1k"
  }
}'

# Copy data.taskId from the response into TASK_ID, then poll the status.
TASK_ID="TASK_ID_FROM_RESPONSE"
curl "https://api.spicyapi.ai/api/v1/jobs/recordInfo?taskId=$TASK_ID" \
  -H "Authorization: Bearer $SPICY_API_KEY"
See the API reference for authentication, the complete schema, polling, and error handling.